





Over the past two months, podcast creators have experienced a series of reliability issues on Spotify. This report covers the most significant of these, the June 24 publishing delay, in full detail and describes the broader reliability program now underway across our publishing pipeline.
When a podcast creator publishes a new episode, the audio and video content goes through a series of processing steps before it becomes available to Spotify users. These steps include transcoding (converting media into the formats our apps need) and content analysis.
On June 24, our video transcoding infrastructure reached maximum capacity. This created a backlog that delayed the publication of video podcast episodes for several hours. Creators reported that their episodes were not appearing on Spotify as expected. A queue built up and video podcast episodes that would normally be published within minutes were delayed for hours. Understandably, some creators re-uploaded episodes that had not appeared, which added further load. That is on us, not them: the system should have confirmed their upload was received and queued, and it did not.
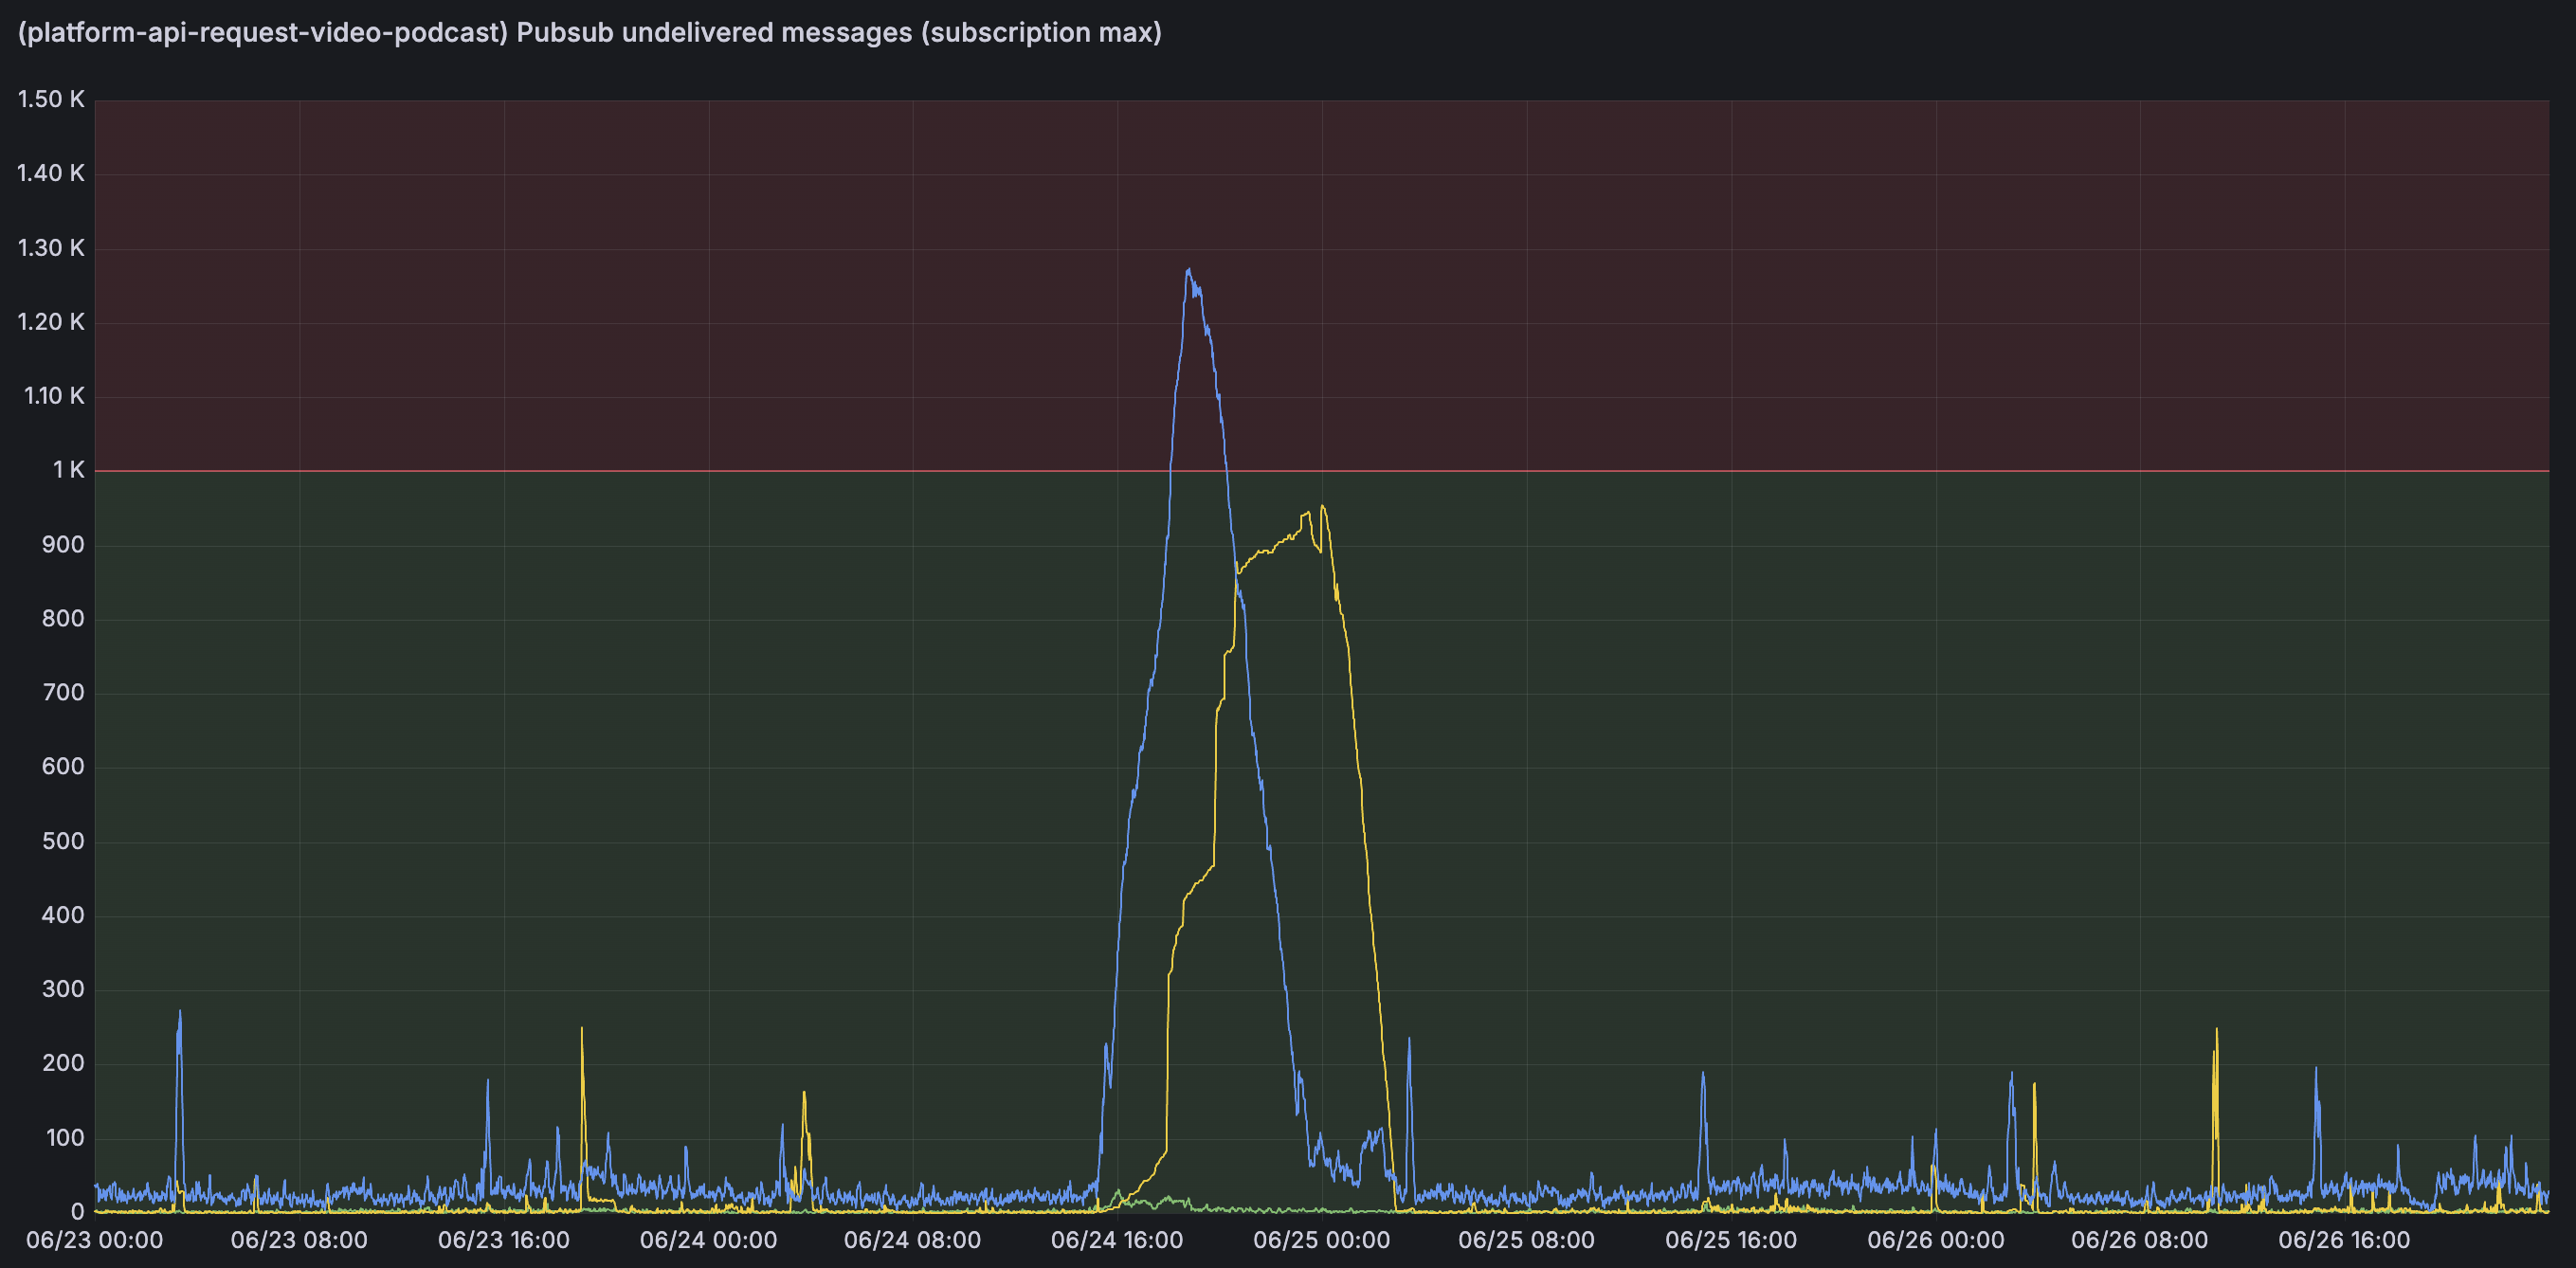
The image above shows the build-up and subsequent emptying of the medium-priority (used for new episodes - shown in blue) and low-priority (used for updates to older episodes - shown in yellow) queues.
Four factors converged to create this situation:
Our transcoding infrastructure was running with insufficient headroom to handle large spikes of content delivery. During typical periods of content submission our transcoding systems were able to scale and support both low-priority transcoding as well as the high-priority publication of new content. However, there wasn’t sufficient headroom to scale and support large spikes caused by the bulk delivery of new content.
A scheduled batch processing job was running. On occasion, we need to re-process existing episodes to be compatible with changes or additions to Spotify’s playback systems. During the June 24 disruption, a routine batch job processing existing content was consuming additional capacity alongside the regular processing for new episodes. While this job appeared fine earlier in the day, it became problematic when combined with increased content submissions.
Recent improvements increased per-item processing cost. We had recently changed our video transcoding to deliver better quality at lower bitrates. That change increased the time and processing power each episode requires, and we did not fully account for that added demand in our capacity planning.
A software bug was underutilizing available compute resources. Following a recent infrastructure migration to more powerful hardware, a bug in our resource scheduling caused our systems to underuse available processing capacity, reducing throughput by about 10%.
When we identified the issue, we stopped the batch job, deployed a fix for the resource scheduling bug, and added additional processing capacity overnight. By the following morning, all backlogs had cleared and publishing was operating normally. We subsequently added further capacity to provide the headroom that had been missing.
13:30 — Early alerts fire in our internal monitoring. Not immediately recognized as a broader capacity issue.
15:00 — Video podcast delivery spike pushes transcoding close to maximum capacity.
16:35 — Batch processing job stopped to free capacity.
17:34 — Automated alerts confirm queue backlog exceeding thresholds. Incident response begins.
19:00 — Creator reports of episodes not appearing on Spotify.
20:49 — Software fix deployed to improve resource utilization.
00:14 (Jun 25) — Additional processing cluster brought online.
01:02 — All queues cleared.
07:30 — Full confirmation: all publishing pipelines operating normally.
One thing this timeline makes plain: roughly four hours passed between the first alerts and formal incident response. We want to do better. Engineers investigating the early alerts stopped the batch job at 16:35, but we did not recognize the full scope of the capacity problem until queues breached thresholds at 17:34. The monitoring improvements described below exist to close exactly that gap.
We have already taken several steps to address this specific incident:
Increased our transcoding capacity by approximately 67%, providing significantly more headroom for traffic spikes and batch operations.
Fixed the resource scheduling bug that was leaving under-utilized compute capacity.
Improved our monitoring to alert earlier when capacity is approaching limits.
Beyond this specific incident, we are investing in broader improvements to the reliability of our podcast publishing pipeline. We've formed a dedicated cross-team effort focused on:
Building better capacity planning that accounts for not just steady-state traffic, but also burst capacity and incident recovery.
Improving prioritization across our publishing systems so that real-time content from creators is always processed ahead of background operations.
Extending rate limiting and backpressure mechanisms throughout the pipeline to handle unexpected load gracefully.
During this incident, many creators learned something was wrong from their audiences before they heard anything from us. We are improving our processes and technical capabilities so creators get notified as soon as possible when things aren’t working.
When a creator hits publish, their audience is waiting, and hours matter. We fell short repeatedly this summer, and we know a report like this only counts if the next incident is handled better than the last. The work above is how we intend to earn that trust back.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。