


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

U
Unit 42
Google DeepMind News
Stack Overflow Blog
Stack Overflow Blog
H
Help Net Security
MongoDB | Blog
MongoDB | Blog
I
InfoQ
N
Netflix TechBlog - Medium
T
Tailwind CSS Blog
量子位
博客园 - 叶小钗
月光博客
月光博客
IT之家
IT之家
G
Google Developers Blog
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
小众软件
小众软件
S
SegmentFault 最新的问题
Engineering at Meta
Engineering at Meta
奇客Solidot–传递最新科技情报
奇客Solidot–传递最新科技情报
aimingoo的专栏
aimingoo的专栏
云风的 BLOG
云风的 BLOG
Vercel News
Vercel News
爱范儿
爱范儿
让小产品的独立变现更简单 - ezindie.com
宝玉的分享
宝玉的分享

Hacker News - Newest: "AI"

AI can't read an investor deck AI as an attorney? Student uses ChatGPT, Gemini to sue UW over alleged racial discrimination Hacking MCP Servers in AI Systems – The Rug Pull: Tool Changes After Approval GitHub - MeepCastana/KubeezCut: Free Web based video editor Can AI judge journalism? A Thiel-backed startup says yes, even if it risks chilling whistleblowers Coming soon: 10 Things That Matter in AI Right Now DARPA built an AI to fact-check enemy weapons claims What explains heterogeneity in AI adoption? When AI Meets Muscle: Context-Aware Electrical Stimulation Promises a New Way to Guide Human Movements - Department of Computer Science AI Changed How We Build. It Did Not Change What Matters. Linux rules on using AI-generated code - Copilot is OK, but humans must take 'full responsibility for the… Meta spins up AI version of Mark Zuckerberg to engage with employees Code Mode: Let Your AI Write Programs, Not Just Call Tools | TanStack Blog GitHub - Delavalom/graft: Go framework for building AI agents. Type-safe tools, multi-provider (OpenAI, Anthropic, Gemini, Bedrock), zero vendor SDKs. India's TCS tops estimates, says new AI models did not dent services demand Gen Z's fading AI hype Strong feeling: we are in a folded AI reality GitHub - machinarii/total-recall-catalog: A reference catalog of latest knowledge retrieval, memory & RAG systems GitHub - mensfeld/code-on-incus: Give each AI agent its own isolated machine with root, Docker, and systemd. Active defense detects and stops threats automatically.. Quantization, LoRA, and the 8% Problem: Benchmarking Local LLMs for Production AI Iran war: We spoke to the man making Lego-style AI videos that experts say are powerful propaganda Powell, Bessent discussed Anthropic's Mythos AI cyber threat with major U.S. banks GitHub - immartian/bellamem: Persistent belief-graph memory for AI agents. Retrieves decisive context by importance — not recency, not RAG, not /compact. recursive-mode: The Repo-Native Operating System for AI Engineering After the attack on Sam Altman's home, will AI CEO's go on the offensive? The biggest advance in AI since the LLM Opus 4.6 vs GPT 5.4 One Prompt Unity World Generation Test “AI polls” are fake polls Client Challenge Can AI be a 'child of God'? Inside Anthropic's meeting with Christian leaders
Claude.AI Pro Plan quotas too small for deep research
datadrivenan · 2026-05-21 · via Hacker News - Newest: "AI"

Tags: AI, LLMs, Agents, Claude, Anthropic, Tokenomics
Published 2026-05-20

Usage limits reached!

Usage limits are too small for deep research

The $20/month Claude pro plan gives me at most 1 successful research mode question per session before I hit the usage limits, and I have twice seen a single research question fail to finish because it burns the entire session usage. Even when using Sonnet.

My suggestions if anyone at Anthropic sees this: Add some kind of hint to Claude to wrap things up as usage starts coming to an end, add some kind of UI hint to just use web search more often, and maybe allow soft overages for session usage?

The setup:

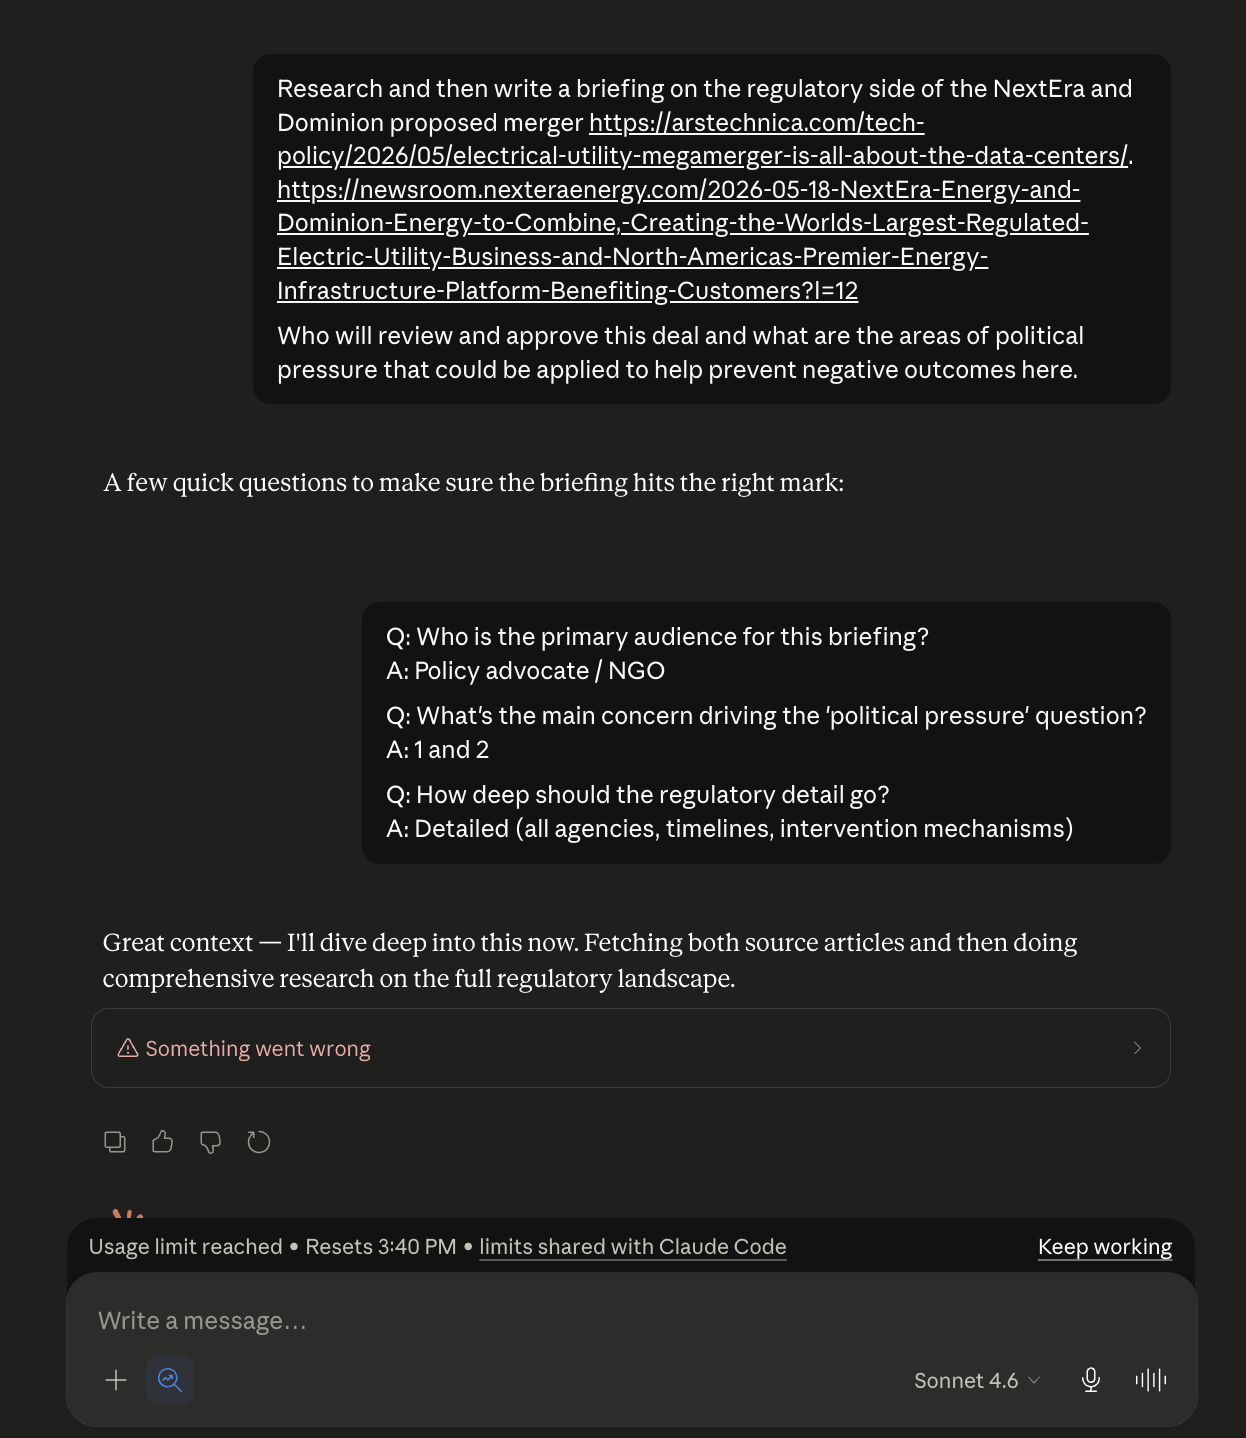
Dominion Energy and next era energy announced they plan on doing a merger and will form the largest energy company in the United States. Having written a book about energy technology and energy policy, I have some opinions on this space and wanted to learn a little bit more. So I asked Claude to do some research into this. I specifically chose the sonnet 4.6 model because I had previously seen research mode on opus fully burn all the usage in my $20 per month pro plan.

A few minutes into this it exploded!
Usage limits reached!

I had hit my limits before it could finish!

Well, 80% of my limits... Which is also weird because last time I checked even dumb local models will confirm that 80% is not 100%... There might be a bug?
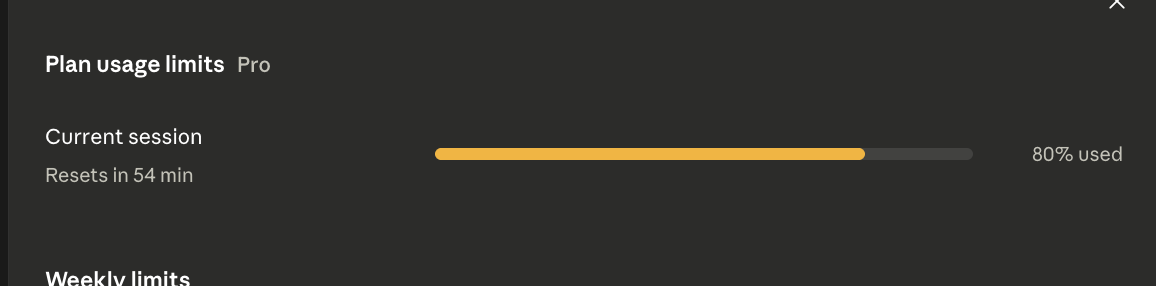
80% is 100%??

Take 2.

So I tried again a few hours later with the same prompt. No other connectors, no excessive MCP servers or customizations to burn context. No other usage in that session.
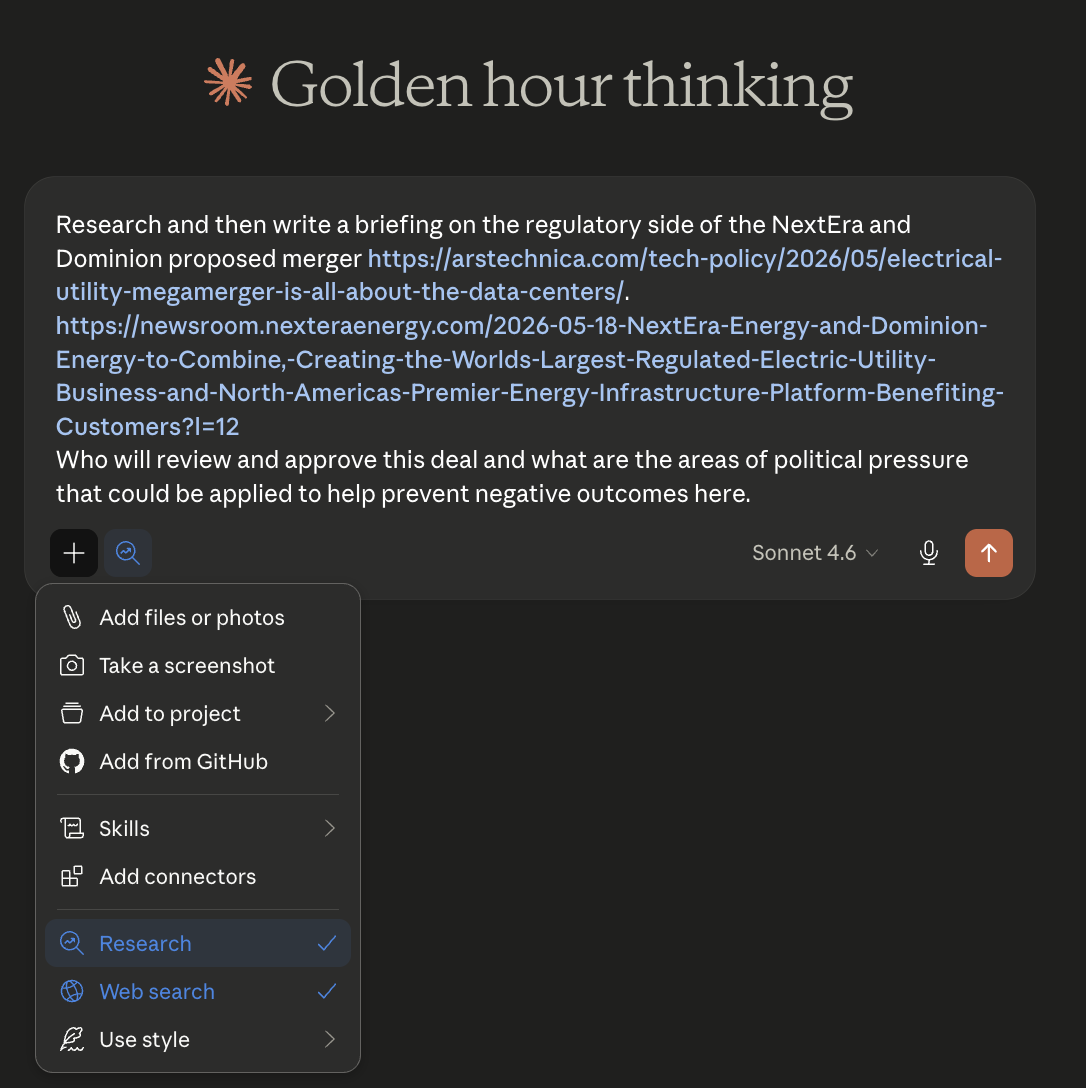
New research prompt

It worked this time, but used 56% of my usage.

Just 236 sources with lots of fact checking and cross referencing. The average of the internet averaging this section of the internet.

Claude.AI feels less quota efficient than Claude Code?

Last week I had a similar experience where resuming a short Claude web session and asking for a little bit of spreadsheet modeling work with Opus 4.7 consumed a whole session of usage quota and failed before finishing. I suspect that Claude Code would have used significantly less quota for the same amount of actual work. The moral of the story is never resume a session and manage context ruthlessly.

Maybe the real moral of the story is that most tasks don't need deep research, but it's still surprising to feel so constrained to only have at most one research mode question per ~6 hours.

Conclusions

I'm increasingly coming to believe that features failing outright is a very bad user experience.

Agentic workflows should either reject tasks up front due to lack of projected budget, or degrade gracefully within their budget. Otherwise people won't trust the feature itself, let alone trust it to use as many tokens as it can get.