

惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

Last Week in AI
Last Week in AI
F
Fortinet All Blogs
Blog — PlanetScale
Blog — PlanetScale
Engineering at Meta
Engineering at Meta
H
Hackread – Cybersecurity News, Data Breaches, AI and More
大猫的无限游戏
大猫的无限游戏
V
V2EX
Martin Fowler
Martin Fowler
让小产品的独立变现更简单 - ezindie.com
A
About on SuperTechFans
博客园 - 聂微东
博客园 - Franky
B
Blog RSS Feed
T
The Blog of Author Tim Ferriss
U
Unit 42
人人都是产品经理
人人都是产品经理
M
MIT News - Artificial intelligence
WordPress大学
WordPress大学
N
Netflix TechBlog - Medium
Apple Machine Learning Research
G
Google Developers Blog
P
Proofpoint News Feed
L
LangChain Blog
博客园 - 叶小钗

Hacker News - Newest: "AI"

AI can't read an investor deck AI as an attorney? Student uses ChatGPT, Gemini to sue UW over alleged racial discrimination Hacking MCP Servers in AI Systems – The Rug Pull: Tool Changes After Approval GitHub - MeepCastana/KubeezCut: Free Web based video editor Can AI judge journalism? A Thiel-backed startup says yes, even if it risks chilling whistleblowers Coming soon: 10 Things That Matter in AI Right Now DARPA built an AI to fact-check enemy weapons claims What explains heterogeneity in AI adoption? When AI Meets Muscle: Context-Aware Electrical Stimulation Promises a New Way to Guide Human Movements - Department of Computer Science AI Changed How We Build. It Did Not Change What Matters. Linux rules on using AI-generated code - Copilot is OK, but humans must take 'full responsibility for the… Meta spins up AI version of Mark Zuckerberg to engage with employees Code Mode: Let Your AI Write Programs, Not Just Call Tools | TanStack Blog GitHub - Delavalom/graft: Go framework for building AI agents. Type-safe tools, multi-provider (OpenAI, Anthropic, Gemini, Bedrock), zero vendor SDKs. India's TCS tops estimates, says new AI models did not dent services demand Gen Z's fading AI hype Strong feeling: we are in a folded AI reality GitHub - machinarii/total-recall-catalog: A reference catalog of latest knowledge retrieval, memory & RAG systems GitHub - mensfeld/code-on-incus: Give each AI agent its own isolated machine with root, Docker, and systemd. Active defense detects and stops threats automatically.. Quantization, LoRA, and the 8% Problem: Benchmarking Local LLMs for Production AI Iran war: We spoke to the man making Lego-style AI videos that experts say are powerful propaganda Powell, Bessent discussed Anthropic's Mythos AI cyber threat with major U.S. banks GitHub - immartian/bellamem: Persistent belief-graph memory for AI agents. Retrieves decisive context by importance — not recency, not RAG, not /compact. recursive-mode: The Repo-Native Operating System for AI Engineering After the attack on Sam Altman's home, will AI CEO's go on the offensive? The biggest advance in AI since the LLM Opus 4.6 vs GPT 5.4 One Prompt Unity World Generation Test “AI polls” are fake polls Client Challenge Can AI be a 'child of God'? Inside Anthropic's meeting with Christian leaders
The 100,000 whys of AI
lcamtuf · 2026-06-21 · via Hacker News - Newest: "AI"

One of the most painful arguments I keep having with fellow techies is the question of whether you can distinguish between human-written and AI-generated text.

Their skepticism is rooted in reason: at their core, LLMs are state-of-the-art statistical models of how humans talk. If so, the output from the model should be almost by definition indistinguishable from human language under any statistical test.

I don’t think this is always argued in good faith; at least some of the debates are started by folks who wish to maintain deniability for their own underhanded use of the tech. But if you sincerely hold this belief, I present you the following collage:
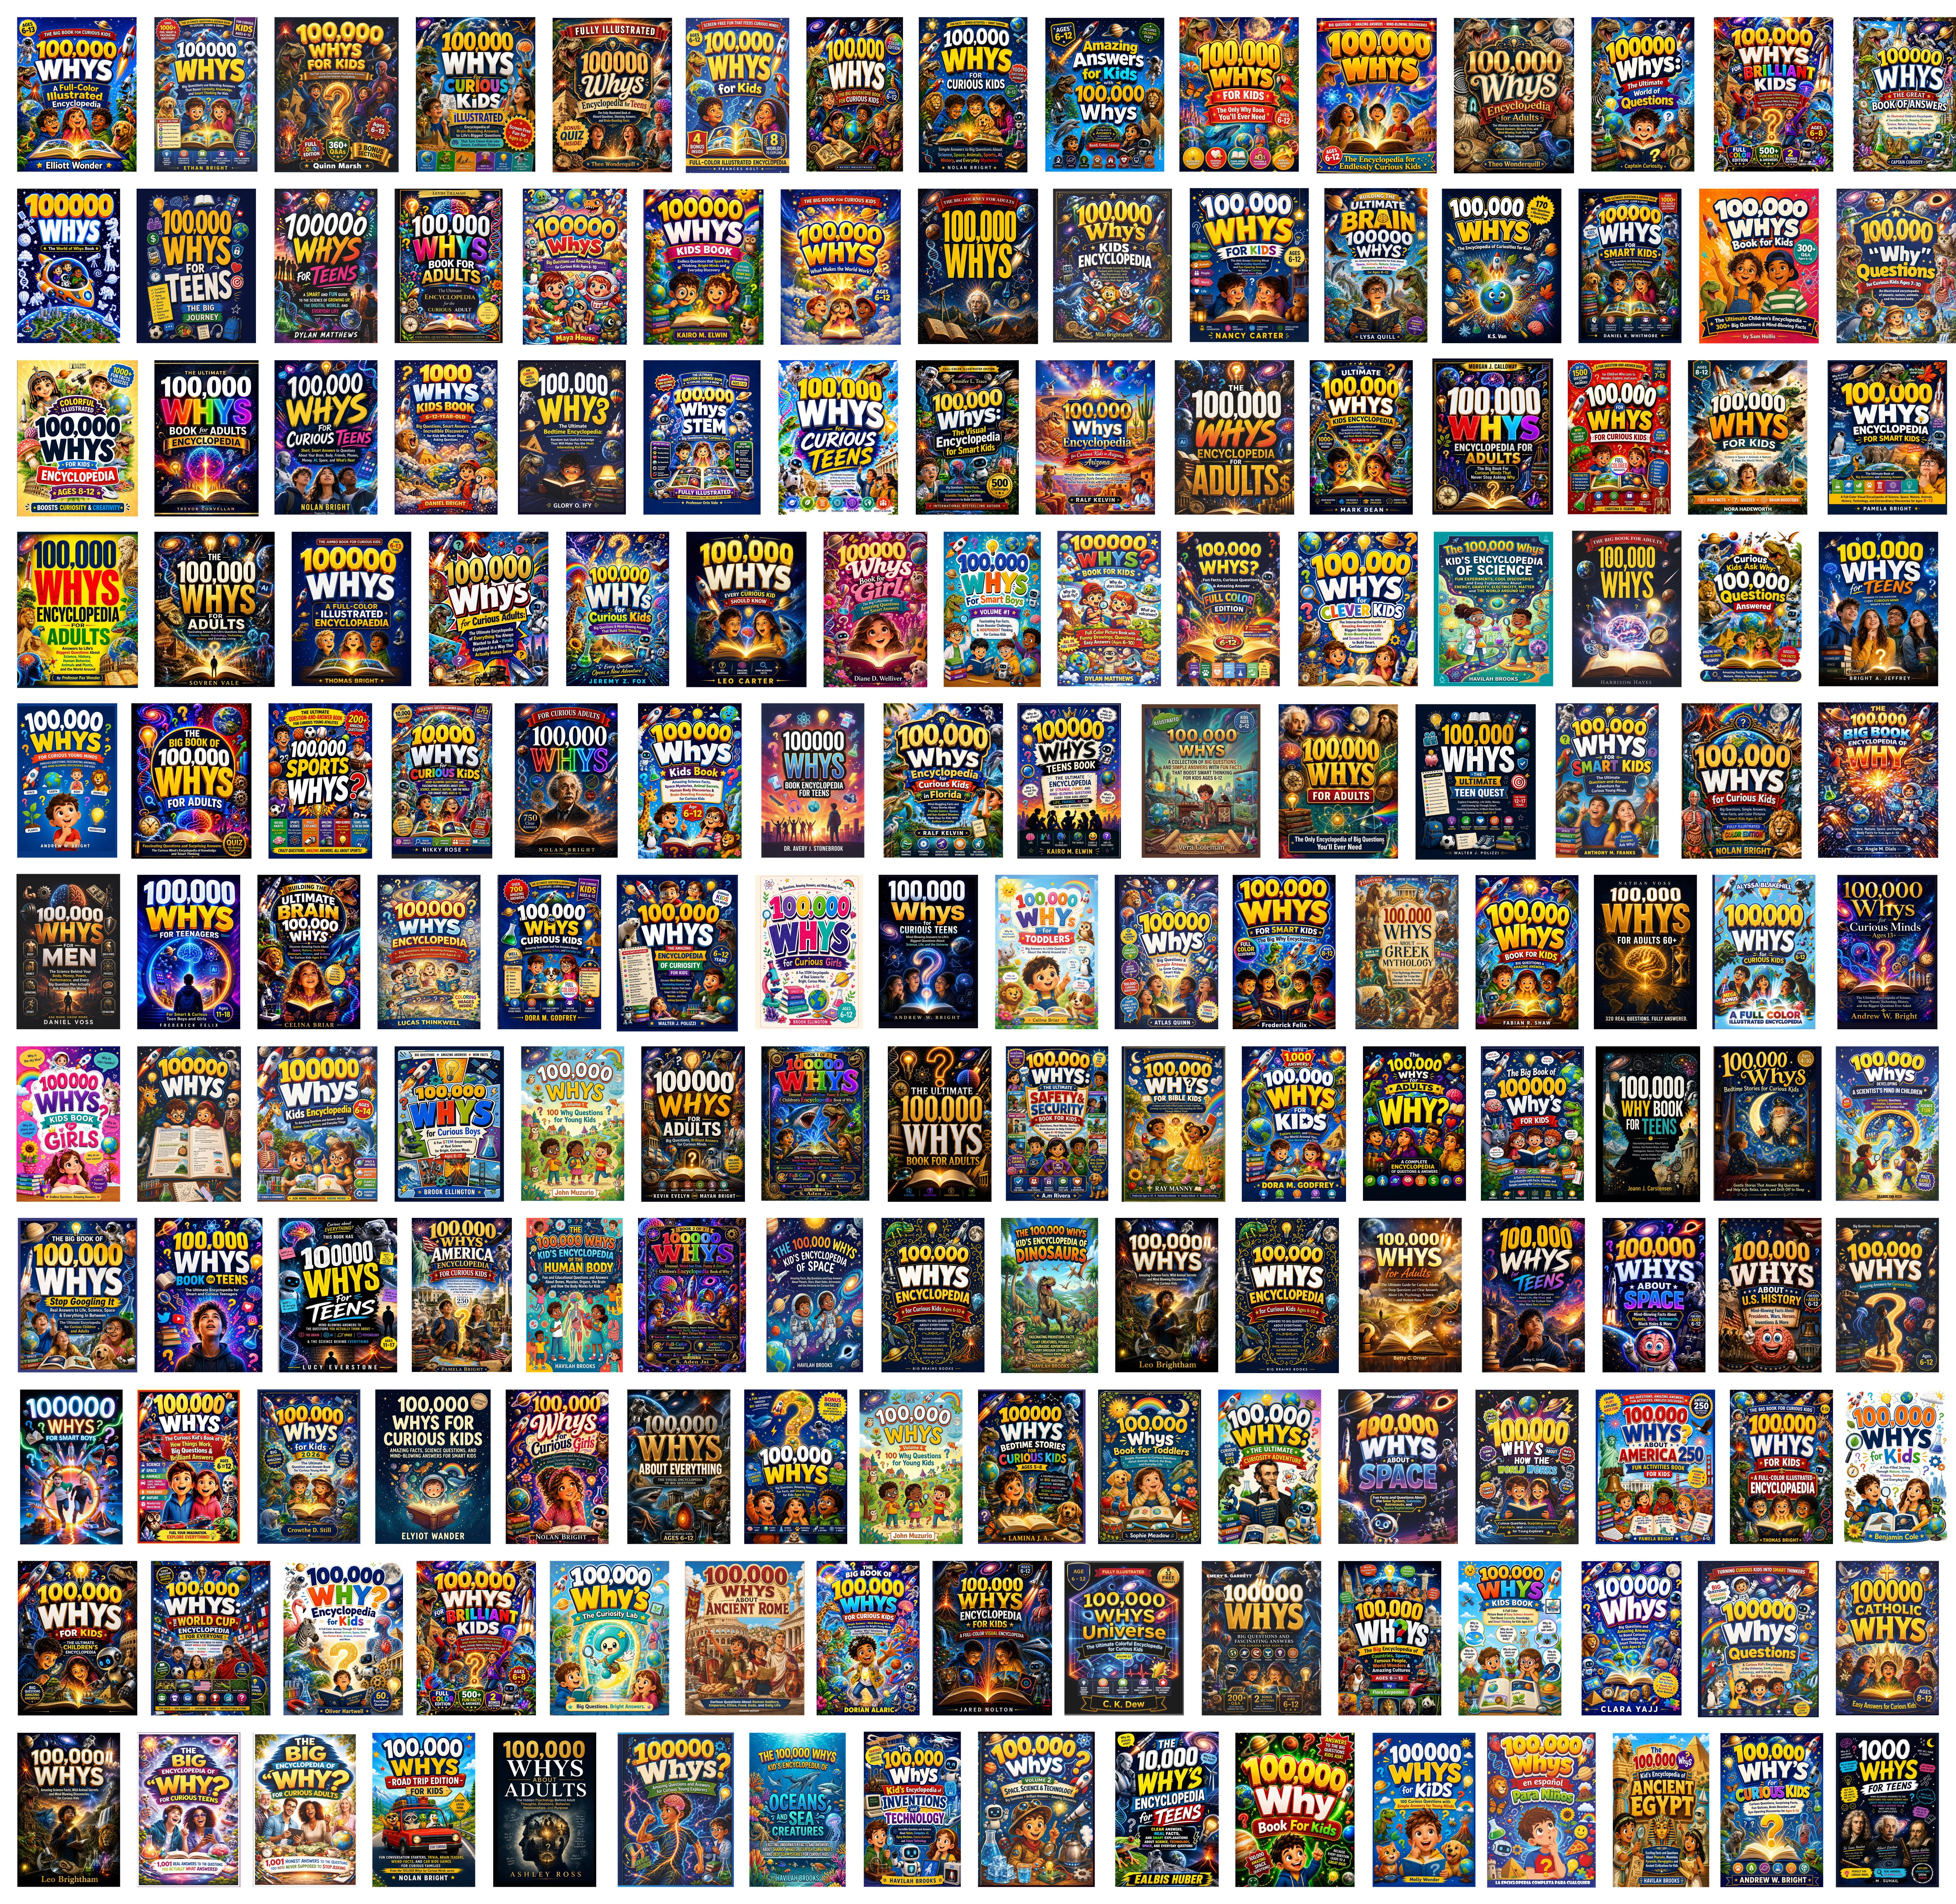
The image shows about 150 Amazon book covers that appear if you search the site for “100000 whys” (link). Some of these books are category bestsellers in children literature. You can view a zoomable, full-resolution version here.

There’s nothing inhuman about any of these titles or covers. At the same time, I probably don’t need to convince you that you’re staring at the purest form of AI slop that is now the scourge of many non-fiction book categories on Amazon. What we’re seeing here is the artifact of LLMs being quasi-deterministic: if you give them the same prompt — say, “generate a reference book for children” — they will produce functionally identical output perhaps 80% of the time.

The similarities in the collage go far beyond the choice of titles: for example, all the covers in the top row feature a roaring dinosaur in the top left corner of the design. There are many other clusters in the data, too. Look for a recurring red-and-white cartoon rocket, a golden retriever, a lion, and so forth.

This is precisely what makes LLM writing distinctive: it’s not that the models’ individual mannerisms are different from ours. It’s that they resort to the same, complex set of mannerisms in response to almost any normal prompt. This is a fuzzy signal, so you shouldn’t fire your intern when they say “it’s not this — it’s that”. But in more casual settings, it’s OK to trust your gut. In fact, these instincts are becoming increasingly important because traditional models of online interactions fall apart if it takes much less effort to produce content than to engage with it.

PS. If you’re using an LLM to automate blogging: yes, the tech is amazing, but chances are, your publication could be renamed to “100,000 Whys”.

Discussion about this post

Ready for more?