惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

Vercel News
Vercel News
N
Netflix TechBlog - Medium
C
Check Point Blog
MyScale Blog
MyScale Blog
The GitHub Blog
The GitHub Blog
Blog — PlanetScale
Blog — PlanetScale
B
Blog RSS Feed
Cyber Security Advisories - MS-ISAC
WordPress大学
WordPress大学
博客园 - Franky
MongoDB | Blog
MongoDB | Blog
I
InfoQ
Hugging Face - Blog
Hugging Face - Blog
Recent Announcements
人人都是产品经理
人人都是产品经理
腾讯CDC
V
Visual Studio Blog
Engineering at Meta
Engineering at Meta
T
The Blog of Author Tim Ferriss
V
V2EX
云风的 BLOG
云风的 BLOG
Microsoft Azure Blog
U
Unit 42
B
Blog

Amicoyuan

Greyson Chance 2023 Beijing 重启Life分类-Seasons SUMMA:Scalable Universal Matrix Multiplication Algorithm[未更新] 论文阅读:稀疏矩阵向量乘法在申威众核架构上的性能优化
论文阅读:Towards Efficient SpMV on Sunway Manycore Archi...
John Doe · 2023-07-11 · via Amicoyuan

文章链接:

Towards Efficient SpMV on Sunway Manycore Architectures | Proceedings of the 2018 International Conference on Supercomputing (acm.org)

文章总结

dual-side multi-level partitioning technique

三层分块:Block->Tile->Slice

其中在Tile这一层会有空Tile块,不需要计算

其中Slice这一层也会有空Slice切片,不需要计算

最底层Slice切片是我们的计算核心

多级队列:负载均衡—>The work sharing mechanism in the block and slice queuesguarantee the workload balance across fleets and cores.
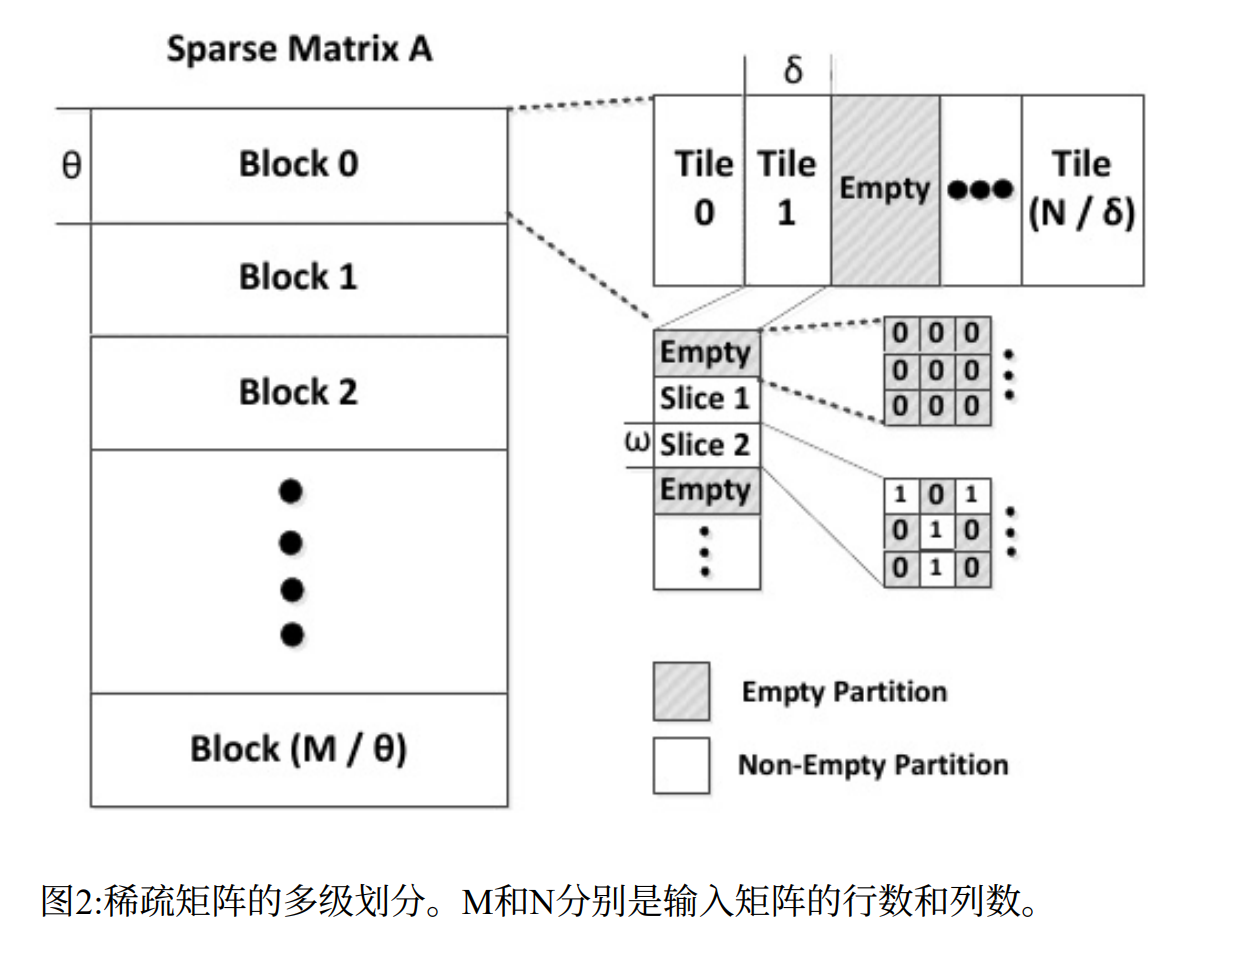
image-20230711215435026

映射细节:

image-20230711220304175

计算核心处理逻辑

一行8个核心:7个计算核心,1个I/O核心

计算核心负责SPMV计算

I/O核心负责将结果写回内存

多个slice组合—>batch,方便DMA,并进行数据预取(单位batch),注意计算核心slice依然没有改变

利用向量寄存器,巧妙搭载msg
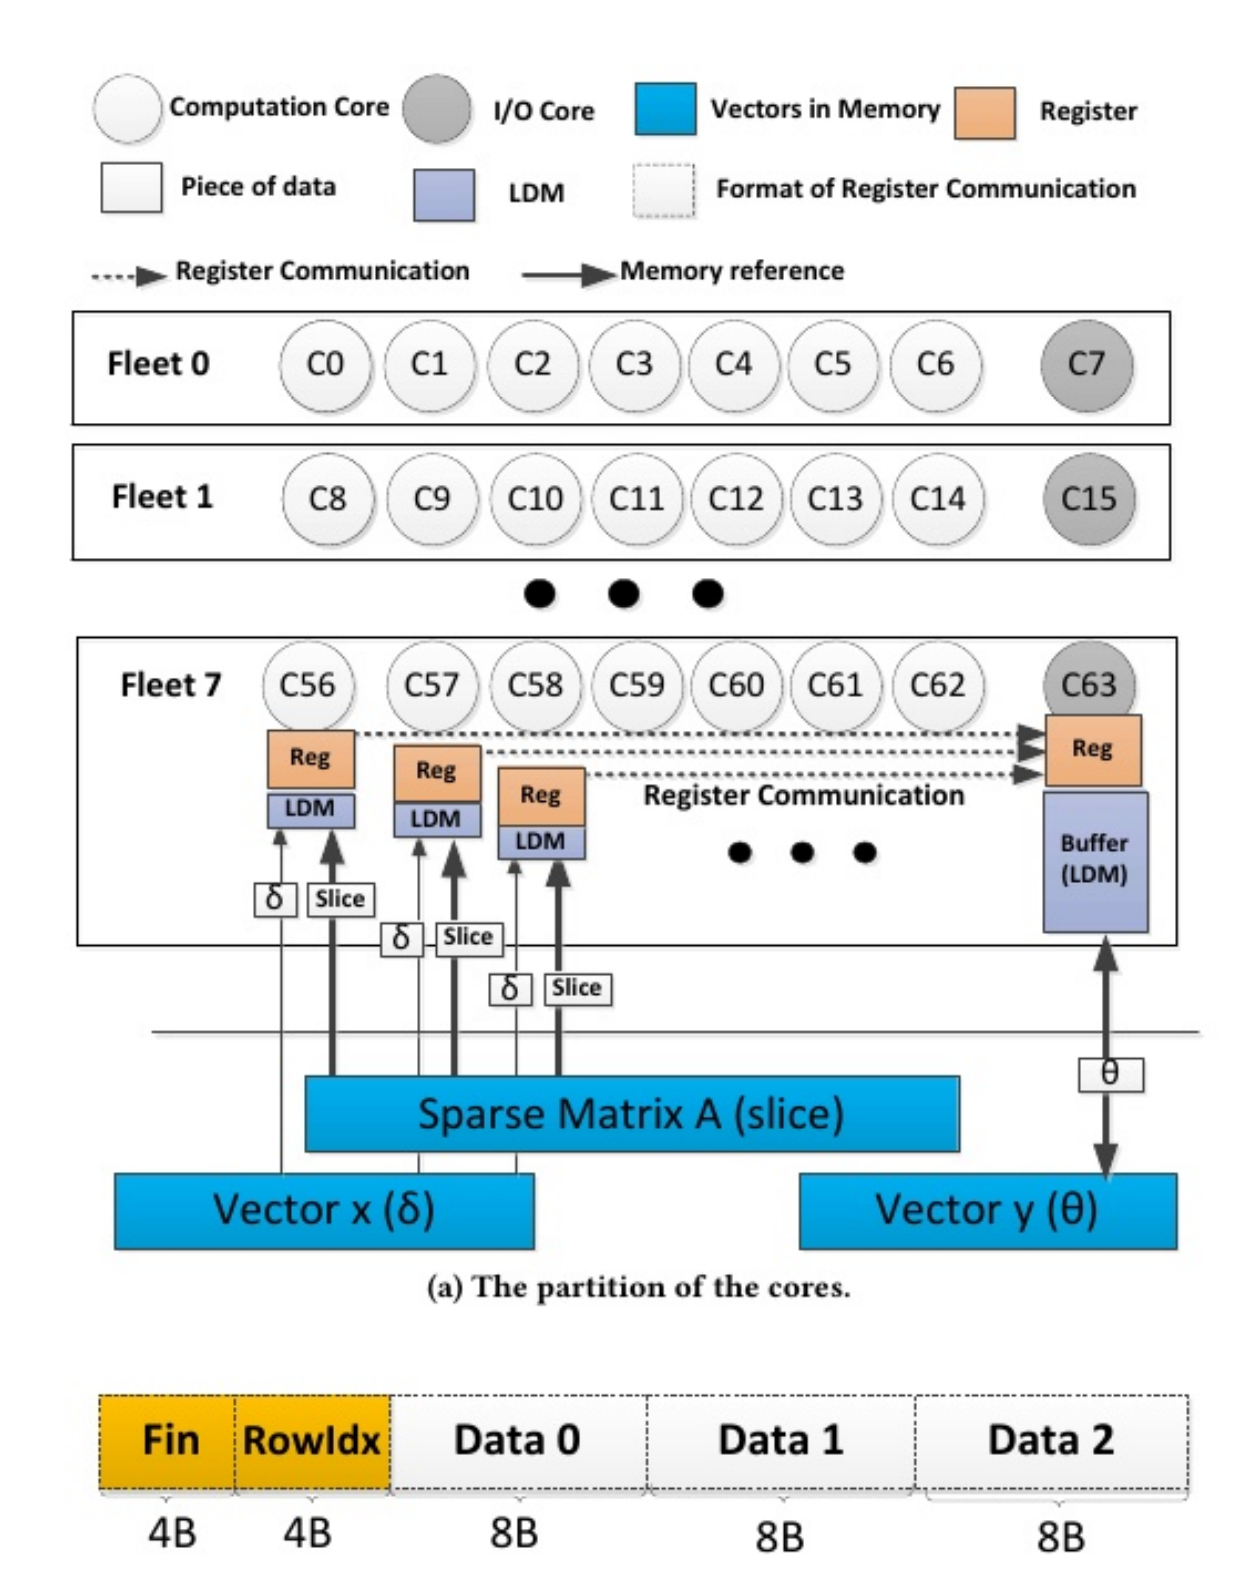
image-20230711221015472

I/O核心的处理逻辑

整个block计算完才写回,避免反复访存

向量计算器meg->reduce

利用神威RMA