





Saturday, 13th, 2026
I wrote this article yesterday. I decided to let it mature before publishing. This is what I woke up to this morning:
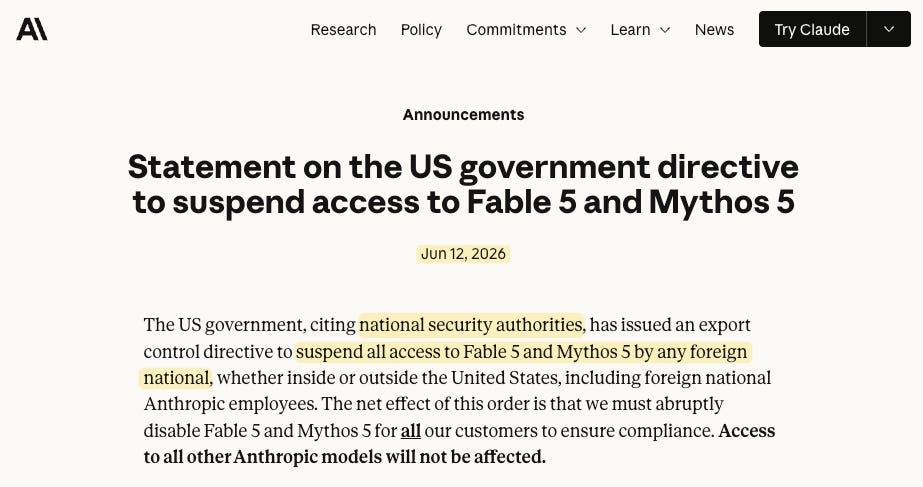
This is exactly what I mean when writing about the weaponization of AI and its use as a national security concern. I did not change a word of the article.
Screenshot from Anthropic’s website.
Friday, 12th, 2026.
I think it is. Not the AI one, though.
Apple announced a few days ago at WWDC something that goes way beyond Siri improvements; it is a signal of what the AI world looks like today, and where it is going.
Let me explain.
Apple believes that for most uses, we don’t need cloud-based LLMs. They have decided that Mac OS should be an AI-enabled system that processes workflows and tasks locally.
Cloud systems can be used when needed. It makes sense, users will not need to buy a monthly subscription if their Mac has the power to run AI automations and tasks natively.
What does that mean for you and me? Probably most of our automations and Claude skills will eventually run on our Macs. We will likely have to rebuild our apps.
So what happens to LLMs? They are already hinting at where they intend to go: advanced AI work: agents, harnesses, deep reasoning tasks. Specialist work, not default infrastructure.
LLMs are genuinely useful, but our hopes and imagination may have been playing a role in our misinterpretation of what they are really good at. LLMs have a limitation by design: they are probabilistic in nature.
Probabilistic systems interpret context; they do not execute with certainty. Asking an LLM to scan invoices and always update a database correctly is more hope than a solution. That use case pushes a probabilistic system to behave as a deterministic one. So why not use a deterministic system instead? Many experienced early adopters will disagree, but I would love to know how many credits their agentic systems cost per transaction, how much maintenance time they require, and how long they took to build. And then I would ask:
Why not use the LLM to build the deterministic tool instead?
A well-architected system can manage the probabilistic nature of an LLM through validation layers, confidence scoring, and human review queues. That is true. But those layers have a cost — in development time, in maintenance, in the human oversight required to catch what the model gets wrong. That cost rarely appears in the business case. It surfaces later, in the people doing the work that the automation was supposed to eliminate.
That brings me to what LLMs genuinely do well:
Democratizing software development — removing the technical barrier while the human still directs
Accelerating learning — removing the access barrier while the human still synthesizes
Interpretation aid — reducing cognitive load while the human still decides
Language and translation work — removing friction while the human still owns the meaning
Notice the pattern. In every case, the human remains essential. LLMs are amplification tools: they speed up and increase in size what we want to do, and also our mistakes.
The consumer marketing around AGI has gone quiet. The labs themselves are more AGI-focused than ever, as it is in their stated missions and research agendas. But the public narrative has shifted toward practical features and monthly subscriptions.
Apple’s decision to focus on local, practical AI for its users rather than chasing frontier model benchmarks is telling. It suggests that the race toward artificial general intelligence may be less central to real-world value than the industry was claiming.
This makes me suspect that OpenAI, Google, and Anthropic are working on very different models behind closed doors, experiments we do not know about yet, because the current LLM approach has a ceiling, and they know it.
I find it especially disturbing when I hear people framing AI as a national security issue. That framing does not produce wisdom; it produces escalation.
Every major technology of the last century that got absorbed into a power and dominance narrative ended up generating conflict rather than progress.
Other nations and blocs will not watch passively. They will build alternatives, restrict access, and retaliate through regulation and competing investment.
The arms-race framing fragments the technology rather than developing it. Apple, interestingly, offers a partial counterexample:
A commercial sovereignty play that does not require weaponizing the technology to capture its value.
I am not saying AI is over. I am saying LLMs are hitting a wall. The LLM business model is under pressure, not because the technology has stopped improving, but because the cost of accessing that improvement keeps rising while the sustainable use cases for most businesses and independent professionals remain narrower than advertised.
I do not want to be distracted by the barrage of new functionality announcements; they are good manipulation tactics. The truth reveals itself more clearly when you look at the subscription models and the escalating credit prices.
I am an AI early adopter myself, and I write Automato precisely because I want to connect with people interested in this space, sharing value and mutually benefiting from the opportunities this innovation might bring.
But my decades in the industry hint at the fact that our enthusiasm often hides the underlayers of what is really happening. So this article is also a warning to myself:
Remember to look deeper, get a better view, and decide in which direction to go. There might be gold somewhere else…
What is your take?
I wish you a very good day!
Jose from Automato
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。