











Most enterprises are experimenting with autonomous AI agents. Very few are deploying them safely at scale. According to McKinsey's "The State of AI in 2025" survey (November 2025), in no business function have more than ten percent of companies scaled AI agents into production. The failure is rarely a lack of ambition; it is a lack of visibility.
Unlike traditional software, autonomous agents generate their own logic on the fly. They bypass conventional security monitors, invoke tools and access data in ways that are difficult to audit after the fact, and operate across complex multi-agent workflows where a single misconfigured permission or policy gap can cascade into a significant security incident. What enterprises need is a new category of control infrastructure: one that operates at the moment a decision is being made, not after the damage is done.
That is the problem LangGuard was built to solve.
LangGuard acts as a runtime enforcement layer for agentic workflows, monitoring and enforcing policy across the end-to-end chain of actions, decisions, tools, credentials, and intent that spans every system an agent touches. Databricks provides unified governance through Unity Catalog and AI Gateway—the system of record for data, models, and access policies. As enterprises deploy agents into production, the workflow itself also needs a runtime enforcement layer that extends those platform-level controls into every step of agent execution. That is where LangGuard fits in. LangGuard's governance engine, the GRAIL™ (Governance AI Run-time Links) data fabric, captures every agent action as multidimensional trace data and constructs a live knowledge graph of workflow behavior and context. When an agent attempts to invoke a tool, access a dataset, or call a model, LangGuard evaluates that action against policy before it executes, across every system the workflow touches, regardless of where it runs.
The scale of a production enterprise agentic deployment makes this genuinely hard. A single workflow may involve tens of coordinated agents, hundreds of tool invocations, multiple foundation models, and policies managed across fifteen or more enterprise Systems of Record, including IT ticketing systems like ServiceNow, IAM and IDP platforms, CRM systems like Salesforce, HR platforms like Workday, cloud security platforms like Wiz and CrowdStrike, contact center platforms like TalkDesk, MCP Gateways, and API Gateways. Governing this in real time, without impacting agent performance, demands infrastructure purpose-built for the problem.
The LangGuard team spent years building IBM QRadar, a multiple-time Gartner Magic Quadrant leader and one of the world's most widely deployed enterprise SIEM platforms. QRadar ingests and correlates petabytes of security telemetry per day under strict latency and reliability requirements. That experience taught us a hard lesson: database architecture is destiny. When we designed LangGuard's workflow governance engine, we faced the same challenge we had solved before: operational security data that arrives in unpredictable, high-intensity bursts, where every millisecond of decision latency matters and idle infrastructure spend is unacceptable. Traditional databases that couple compute and storage force you to provision for peak load and pay for that capacity around the clock. Lakebase's serverless model, which fully decouples compute from storage and scales to zero between bursts, was the answer we had always needed but didn't have access to when we were building QRadar. It matched the problem exactly.
Lakebase is a new category of operational database architecture that disaggregates compute from storage, allowing compute to scale elastically with workload demand while durable state lives independently in a replicated storage layer. Built on the open foundation of PostgreSQL, the lakebase architecture preserves everything developers rely on in a proven relational database while eliminating the infrastructure constraints that make traditional, monolithic RDBMS the wrong choice for the speed and scale that modern apps, agents, and AI demand.
Agent behavior is notoriously bursty. An agent workflow might be completely dormant for hours and then suddenly generate hundreds of trace writes and enforcement reads in a matter of seconds. Lakebase dynamically provisions compute resources the exact moment those traces flood our system, and shuts down completely when activity stops. Because durable state lives in the storage layer, not in the compute node, spinning up a new compute instance requires no data movement. It simply attaches to the existing database history and begins serving queries immediately.
For a startup operating at enterprise scale, this is the difference between infrastructure that matches actual usage and infrastructure that penalizes you for having quiet periods. Our operational costs stay perfectly aligned with the workloads we are actually serving.
The natural concern with any disaggregated database is read latency. Lakebase addresses this through a caching layer between compute and storage that keeps hot data close to compute.
For LangGuard’s enforcement queries, tight indexed lookups against GRAIL™ context and policy tables, we expect the active working set to fit comfortably in compute-local memory. This architecture gives us the confidence that governance decisions can be enforced at workflow speed, without adding meaningful latency to agent execution.
Lakebase's instant database branching is one of its most operationally valuable capabilities for a governance product. When we create a branch, no data is physically copied. The branch diverges from the current database state using copy-on-write semantics, consuming storage only for new or modified data. Our developers can create an isolated, exact replica of our production trace data in seconds, test new governance policies against real-world agent behavior, and validate enforcement logic without risking the stability of the live environment.
Lakebase is built on PostgreSQL, the world's most advanced open-source relational database, with decades of production hardening across every industry. For LangGuard, this means full compatibility with the tools, libraries, and extensions our team already knows, with no proprietary query language or migration risk.
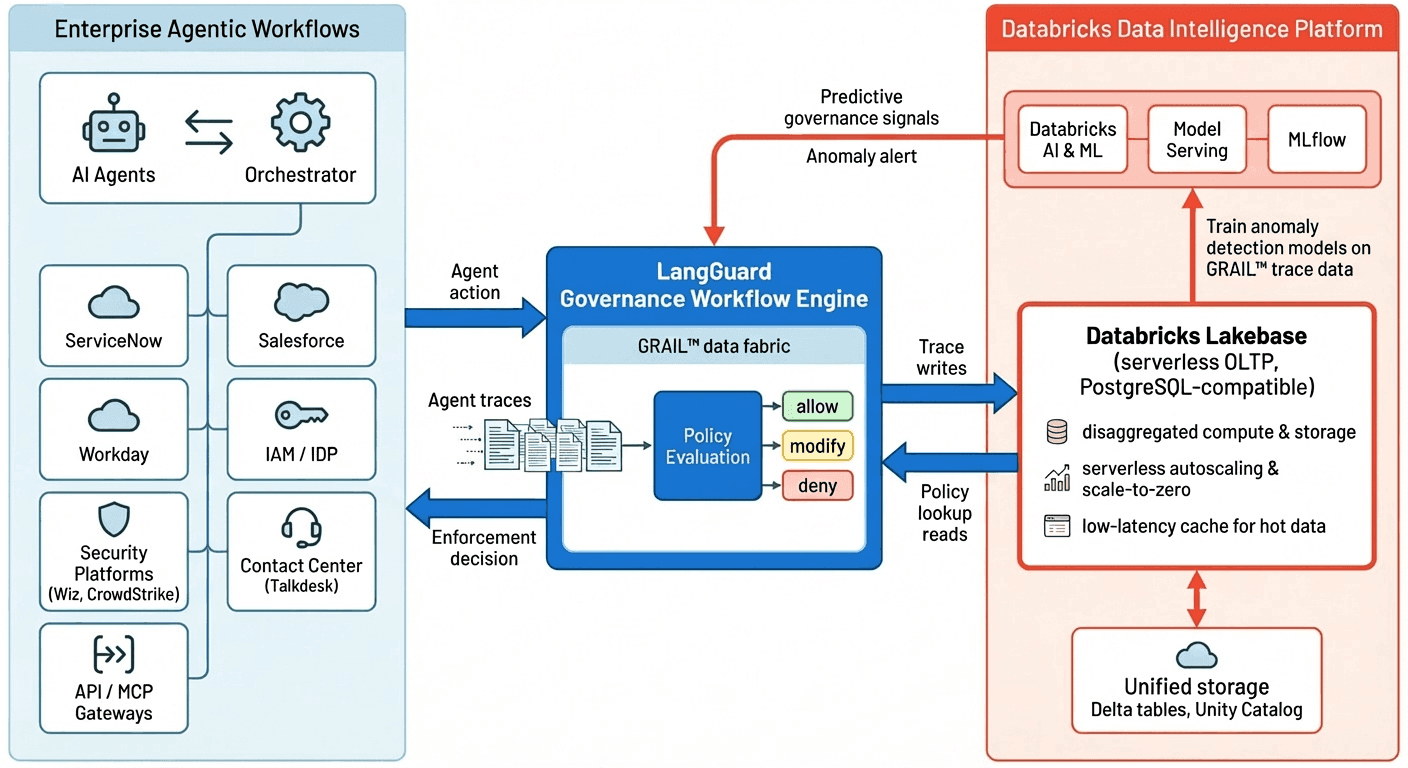
The joint LangGuard and Databricks architecture is designed to govern enterprise agentic workflows end-to-end while keeping all operational data on a single, trusted data and AI platform. On the left of the architecture are the enterprise agentic workflows themselves: AI agents and their orchestrators interacting with dozens of systems of record such as IT service management, CRM, HR, identity, security, contact center, and API/MCP gateways. Each agent action, tool invocation, and data access request generates rich trace events that flow into LangGuard in real time.
At the center of the diagram is the LangGuard Governance Workflow Engine, powered by the patent-pending GRAIL™ data fabric. GRAIL captures every agent action as multidimensional trace data and constructs a live knowledge graph of workflow behavior and context. When an agent attempts to call a tool, access a dataset, or invoke a model, LangGuard performs a policy evaluation against this live context and the relevant governance rules, returning an allow/deny/modify decision before the action executes. This gives enterprises a single control point for enforcing policy across every system the workflow touches, regardless of where the underlying agents are running.
On the right, Databricks Lakebase serves as the operational system of record for LangGuard’s trace and policy data. Lakebase’s serverless, PostgreSQL architecture disaggregates compute from storage, enabling elastic autoscaling and scale-to-zero between bursts of agent activity while keeping hot operational data in a low-latency cache near compute. LangGuard continuously writes trace events into Lakebase and performs low-latency reads for governance policy lookups and contextual queries, ensuring that enforcement decisions can be made at workflow speed without over-provisioning database capacity.
Because LangGuard’s operational data lives natively in Lakebase, it is immediately available to the broader Databricks Data Intelligence Platform for analytics and AI without additional ETL. Databricks AI, Model Serving, and MLflow can train and deploy anomaly detection models directly on GRAIL trace data to identify agents that deviate from their established behavioral baseline. These predictive signals feed back into the LangGuard Governance Engine, closing the loop between real-time enforcement and predictive monitoring and enabling enterprises to move from reactive controls to proactive, behavior-based AI governance on a single platform.
LangGuard's engine today enforces established policies at runtime across the full workflow. The next evolution is predictive: training behavioral models on historical GRAIL trace data to detect anomalous agent behavior before it manifests as a policy violation.
Because our operational trace data already lives within the Databricks ecosystem, as described above, we can move directly from enforcement to prediction without building separate ETL pipelines or standing up a second analytical platform.
If an agent starts acting erratically or deviating from its established baseline, those models will flag it as an anomaly before any damage is done. This convergence of real-time enforcement and predictive machine learning is the future of enterprise AI governance, and it is the architecture we are building today.
| KEY TAKEAWAY |
|---|
| LangGuard is one of the first startups building production infrastructure on Databricks Lakebase. The choice was driven by a specific set of non-negotiable requirements: low-latency enforcement, elastic burst handling, and governance policy testing against real data. Only a serverless OLTP database could satisfy them all. Lakebase is the first database to meet all of them. |
| For enterprises that need to govern agentic workflows end-to-end, across every agent, tool, credential, and system of record in the chain, this architecture means enforcement that operates at workflow speed, scales with deployment complexity, and evolves toward predictive behavioral security without requiring a separate data platform. |
Ready to govern your agentic workflows end-to-end? Visit langguard.ai to learn how LangGuard secures, controls, and operates enterprise agentic workflows with full policy compliance, or explore Databricks Lakebase to see how serverless OLTP infrastructure powers real-time AI governance at scale.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。