

惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

T
The Blog of Author Tim Ferriss
Hugging Face - Blog
Hugging Face - Blog
F
Fortinet All Blogs
B
Blog
Cyber Security Advisories - MS-ISAC
Microsoft Security Blog
Blog — PlanetScale
Blog — PlanetScale
月光博客
月光博客
腾讯CDC
小众软件
小众软件
G
Google Developers Blog
V
Visual Studio Blog
罗磊的独立博客
GbyAI
GbyAI
V
V2EX
大猫的无限游戏
大猫的无限游戏
H
Help Net Security
L
LangChain Blog
Engineering at Meta
Engineering at Meta
量子位
The GitHub Blog
The GitHub Blog
博客园 - 司徒正美
WordPress大学
WordPress大学
B
Blog RSS Feed

Databricks

How lakebase architecture delivers 5x faster Postgres writes Why Talent Transformation Is the Missing Focus of Enterprise AI Public Health Intelligence Shouldn't Require a Data Scientist Mean Time to Detect Is a Data Access Problem First-party audience data is the ad sales relationship now Rethinking Distributed Systems for Serverless Performance and Reliability The AI Scaling Gap Hiding in Digital Native Companies 10 trillion samples a day: Scaling beyond traditional monitoring infra at Databricks AI success starts with clean data, not just better models How nOps Rebuilt Their Cloud Optimization Platform on Databricks Lakebase, and Why Other ISVs Should Too Peril Predicts: Precision Payouts for a Volatile World The foundation of AI scalability: one team, one platform, one operating model The Federal Data Paradox: Rich in Data, Poor in Access Driving Budapest Forward: How BKK Uses Databricks to Transform City Mobility LLM Vs AI: A Practical Guide to Differences, Use Cases, and Tools Model Risk Governance Is Not the Same as Risk Intelligence Generative AI for Business: A Complete Strategy and Implementation Guide Data Science vs Data Engineering: Choosing Analysis or Infrastructure AI Applications: Tools, Use Cases, and Platforms MLOps vs DevOps: A Practical Guide for Data Scientists and IT Teams Top Data Warehouse Tools For Modern Data Analytics Unlocking SAP Business Context in Databricks with Semantic Metadata Delta Sharing The marketing activation gap has a fix: Databricks and Stitch partner to turn data infrastructure into marketing performance Alert Fatigue Is a Business Risk Backstage with Lakebase Shipping Faster isn’t Learning Faster Why Your OEE Dashboard Is Lying to You The Turbine That Tried to Tell You It Was Failing Predicting Readmissions Isn't Enough. Acting in Time Is. Clinical Trials Run Longer Than They Have To. That's a Patient Problem
Databricks partners with OpenAI on GPT-5.5
2026-04-24 · via Databricks

Databricks is excited to partner with OpenAI on GPT-5.5, their latest frontier model. GPT-5.5 is OpenAI's strongest frontier model for agentic work in enterprise, complex document reasoning, and long-horizon coding agents. GPT-5.5 also now powers Codex, OpenAI's coding agent.

GPT-5.5 Features and Benefits

GPT-5.5 is the smartest frontier model yet and the next step toward a new way of getting work done. It understands what you’re trying to do more quickly and can take on more of the work itself. Codex, OpenAI's coding agent, is now powered by GPT-5.5, with stronger reasoning and execution capabilities for developer workflows. 

The same strengths that make GPT-5.5 great at coding also make it powerful for everyday work on a computer. Because the model is better at understanding intent, it can move more naturally through the full loop of knowledge work: finding information, understanding what matters, using tools, checking the output, and turning raw material into something useful.

It can write and debug code, research online, analyze data, create documents and spreadsheets, operate software, and move across tools until a task is finished. Instead of carefully managing every step, you can give GPT-5.5 a messy, multi-part task and trust it to plan, use tools, check its work, recover from ambiguity, and keep going.

GPT-5.5 sets the state-of-the-art performance

To understand how these improvements translate into real enterprise workloads, we evaluated GPT-5.5 on OfficeQA, Databricks’ benchmark for document-heavy, multi-step analytical tasks customers perform every day. OfficeQA, built from 89,000 pages of U.S. Treasury Bulletins, measures a model’s ability to retrieve information across documents, interpret complex tables, and perform precise calculations grounded in real enterprise data.

When given the right documents (OfficeQA Pro LLM with Oracle PDF + Web Search), GPT-5.5 scored 64.66%, a decent jump from GPT-5.4's 57.14%, representing a ~13% improvement and a new state-of-the-art on this benchmark. This tests the ceiling of what the model can do when retrieval is already handled.
In a full-agent workflow eval (OfficeQA Pro Agent Harness), where the model must find the right documents, parse them, and compute answers on its own using the Codex agent harness, GPT-5.5 scored 52.63%, up from GPT-5.4's 36.10%. That's a 46% reduction in errors, showing that GPT-5.5's gains aren't just theoretical; they hold up in realistic, end-to-end enterprise workflows.
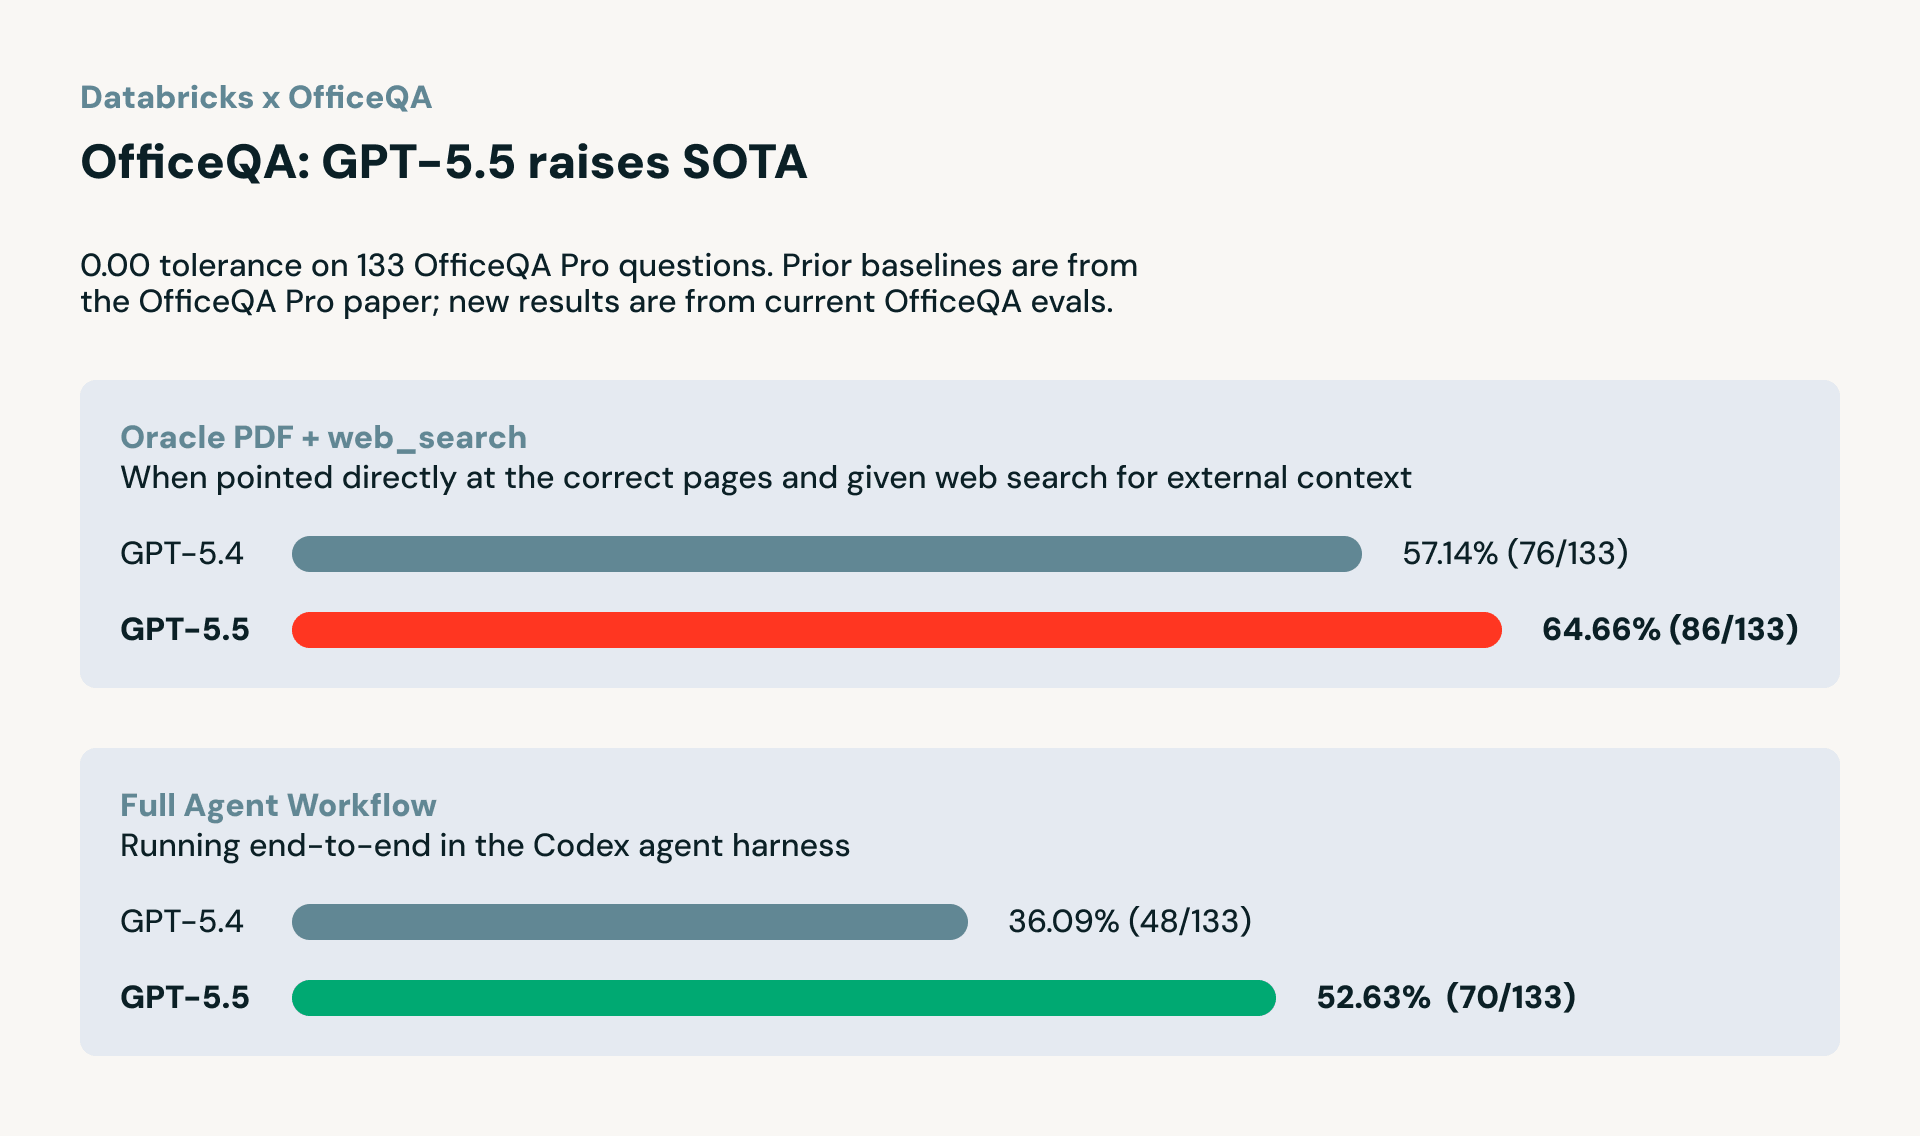
atabricks x OfficeQA benchmark chart showing GPT-5.5 outperforming GPT-5.4 on both Oracle PDF and Full Agent Workflow evaluations.

GPT-5.5 is coming soon to Databricks. Bring frontier reasoning to your enterprise data, securely, and at scale.