


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

Hugging Face - Blog
Hugging Face - Blog
腾讯CDC
阮一峰的网络日志
阮一峰的网络日志
博客园_首页
Last Week in AI
Last Week in AI
月光博客
月光博客
D
DataBreaches.Net
WordPress大学
WordPress大学
雷峰网
雷峰网
酷 壳 – CoolShell
酷 壳 – CoolShell
让小产品的独立变现更简单 - ezindie.com
博客园 - 叶小钗
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
U
Unit 42
Recent Announcements
宝玉的分享
宝玉的分享
MyScale Blog
MyScale Blog
C
Check Point Blog
F
Fortinet All Blogs
B
Blog
小众软件
小众软件
Vercel News
Vercel News
罗磊的独立博客
有赞技术团队
有赞技术团队

Databricks

Why Talent Transformation Is the Missing Focus of Enterprise AI Public Health Intelligence Shouldn't Require a Data Scientist Mean Time to Detect Is a Data Access Problem First-party audience data is the ad sales relationship now Rethinking Distributed Systems for Serverless Performance and Reliability The AI Scaling Gap Hiding in Digital Native Companies 10 trillion samples a day: Scaling beyond traditional monitoring infra at Databricks AI success starts with clean data, not just better models How nOps Rebuilt Their Cloud Optimization Platform on Databricks Lakebase, and Why Other ISVs Should Too Peril Predicts: Precision Payouts for a Volatile World The foundation of AI scalability: one team, one platform, one operating model The Federal Data Paradox: Rich in Data, Poor in Access Driving Budapest Forward: How BKK Uses Databricks to Transform City Mobility LLM Vs AI: A Practical Guide to Differences, Use Cases, and Tools Model Risk Governance Is Not the Same as Risk Intelligence Generative AI for Business: A Complete Strategy and Implementation Guide Data Science vs Data Engineering: Choosing Analysis or Infrastructure AI Applications: Tools, Use Cases, and Platforms MLOps vs DevOps: A Practical Guide for Data Scientists and IT Teams Top Data Warehouse Tools For Modern Data Analytics Unlocking SAP Business Context in Databricks with Semantic Metadata Delta Sharing The marketing activation gap has a fix: Databricks and Stitch partner to turn data infrastructure into marketing performance Alert Fatigue Is a Business Risk Backstage with Lakebase Shipping Faster isn’t Learning Faster Why Your OEE Dashboard Is Lying to You The Turbine That Tried to Tell You It Was Failing Predicting Readmissions Isn't Enough. Acting in Time Is. Clinical Trials Run Longer Than They Have To. That's a Patient Problem Network Quality Is a Revenue Problem, Not a Technical One
Accelerating LLM Inference with Prompt Caching for Open‑S...
Pei-Lun Liao, Asfandyar Qureshi, Roshan Regula, Bruce Fontaine, · 2026-05-23 · via Databricks

Why Prompt Caching Matters

Large language model (LLM) inference often involves repeated prompts—think of the same system or instruction prompt appearing in thousands of requests. Reprocessing that identical prefix for every call wastes compute cycles, inflates latency, and increases costs.

Prompt caching eliminates this redundancy, providing:

  • Lower latency – the prefill stage can be skipped when the cache is hit.
  • Higher throughput – more tokens are processed per model unit.

Prompt caching can be a powerful technique to raise a model’s quality in specific domains without compromising the model’s token throughput. Queries can share a large domain-specific system prompt, with the compute cost of that shared prompt amortized across all those queries. Frontier models, such as Claude, use system prompts that are many thousands of tokens long under the hood. Furthermore, in our recently published research we showed that automated prompt optimization allows open-source models to surpass frontier-model quality for enterprise tasks.

Feature availability

Databricks already provides built-in prompt caching for proprietary models (GPT, Gemini, Claude). We’ve now extended this capability to the open-weights models powering our Foundation Model APIs (FMAPIs) for batch inference, pay-per-token, and provisioned-throughput workloads. It also applies to any and all higher-level services powered by a foundation model, e.g., Agent Bricks, Genie, AI Functions.

Prompt caching is now supported for the following OSS models hosted on Databricks:

  • GPT‑OSS 20B and 120B
  • Gemma 3 12B
  • Fine-tuned Llama 3.1 8B (via PEFT serving)
  • Llama 3.1 8B and 3.3 70B

We will continue to roll out this feature across our other models. Security is a first‑class concern at Databricks. Prompt caches are isolated, only reside in volatile memory and are never persisted. Importantly, the caching is implicit: customers do not need to configure anything, our system has built to automatically run the prompt caching and reuse to improve throughput.

Real‑World Impact: batch inference on GPT OSS

We rolled out prompt caching to our GPT‑OSS models first and immediately saw measurable gains in one of the large-scale production batch‑inference pipelines:
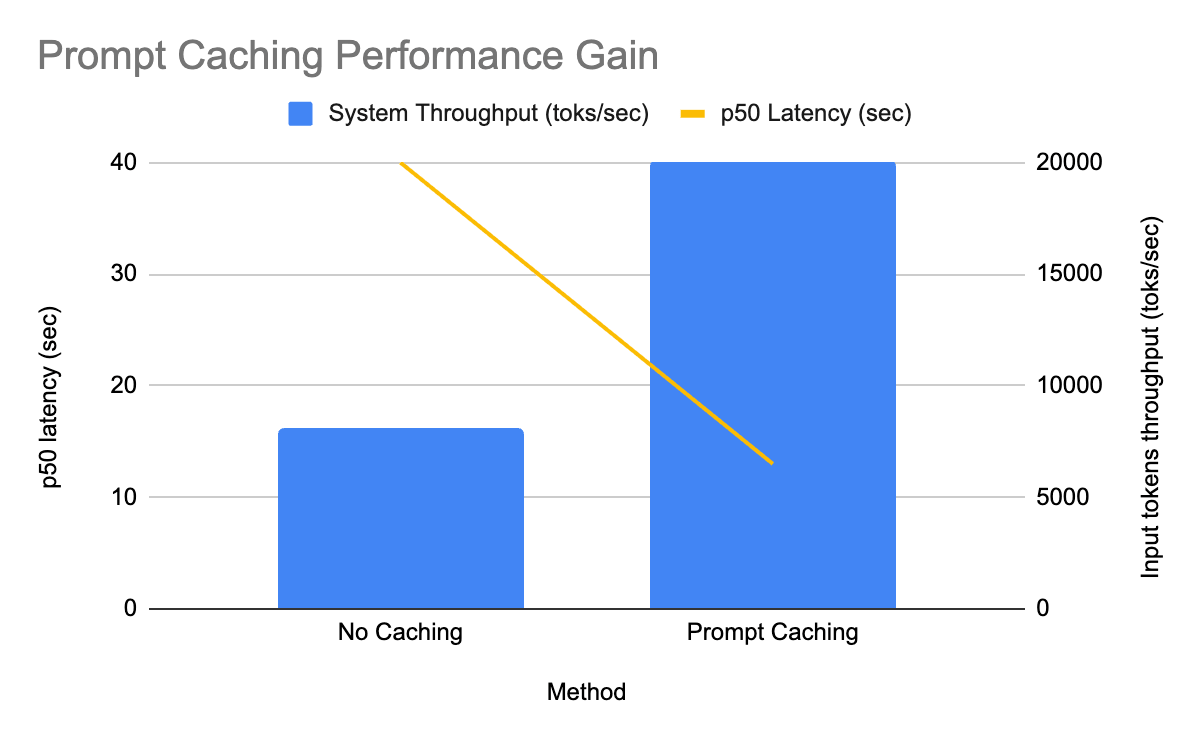
  • Per‑replica input‑token throughput increased by 2.5x
  • P50 latency reduced by 3x
  • All this with a relatively low cache hit ratio of 30%

Prompt Caching GPT‑OSS Models

Takeaway

By automatically reusing KV caches for identical prompts, Databricks enables you to run open-source LLMs faster, more cost-effectively, and with greater security—all without requiring any additional configuration. Whether you’re serving real‑time chat, batch‑processing large document collections, or building AI agents, prompt caching can turn a good inference pipeline into a great one. Give it a try on your next OSS‑model deployment and watch the performance metrics climb.