





线程块:
假如Dx = 6, Dy = 4, Dz = 2 ,如下是对应的线程id编号
第一层:
| 0 | 1 | 2 | 3 | 4 | 5 |
|---|---|---|---|---|---|
| 6 | 7 | 8 | 9 | 10 | 11 |
| 12 | 13 | 14 | 15 | 16 | 17 |
| 18 | 19 | 20 | 21 | 22 | 23 |
第二层
| 24 | 25 | 26 | 27 | 28 | 29 |
|---|---|---|---|---|---|
| 30 | 31 | 32 | 33 | 34 | 35 |
| 36 | 37 | 38 | 39 | 40 | 41 |
| 42 | 43 | 44 | 45 | 46 | 47 |
内存模型:
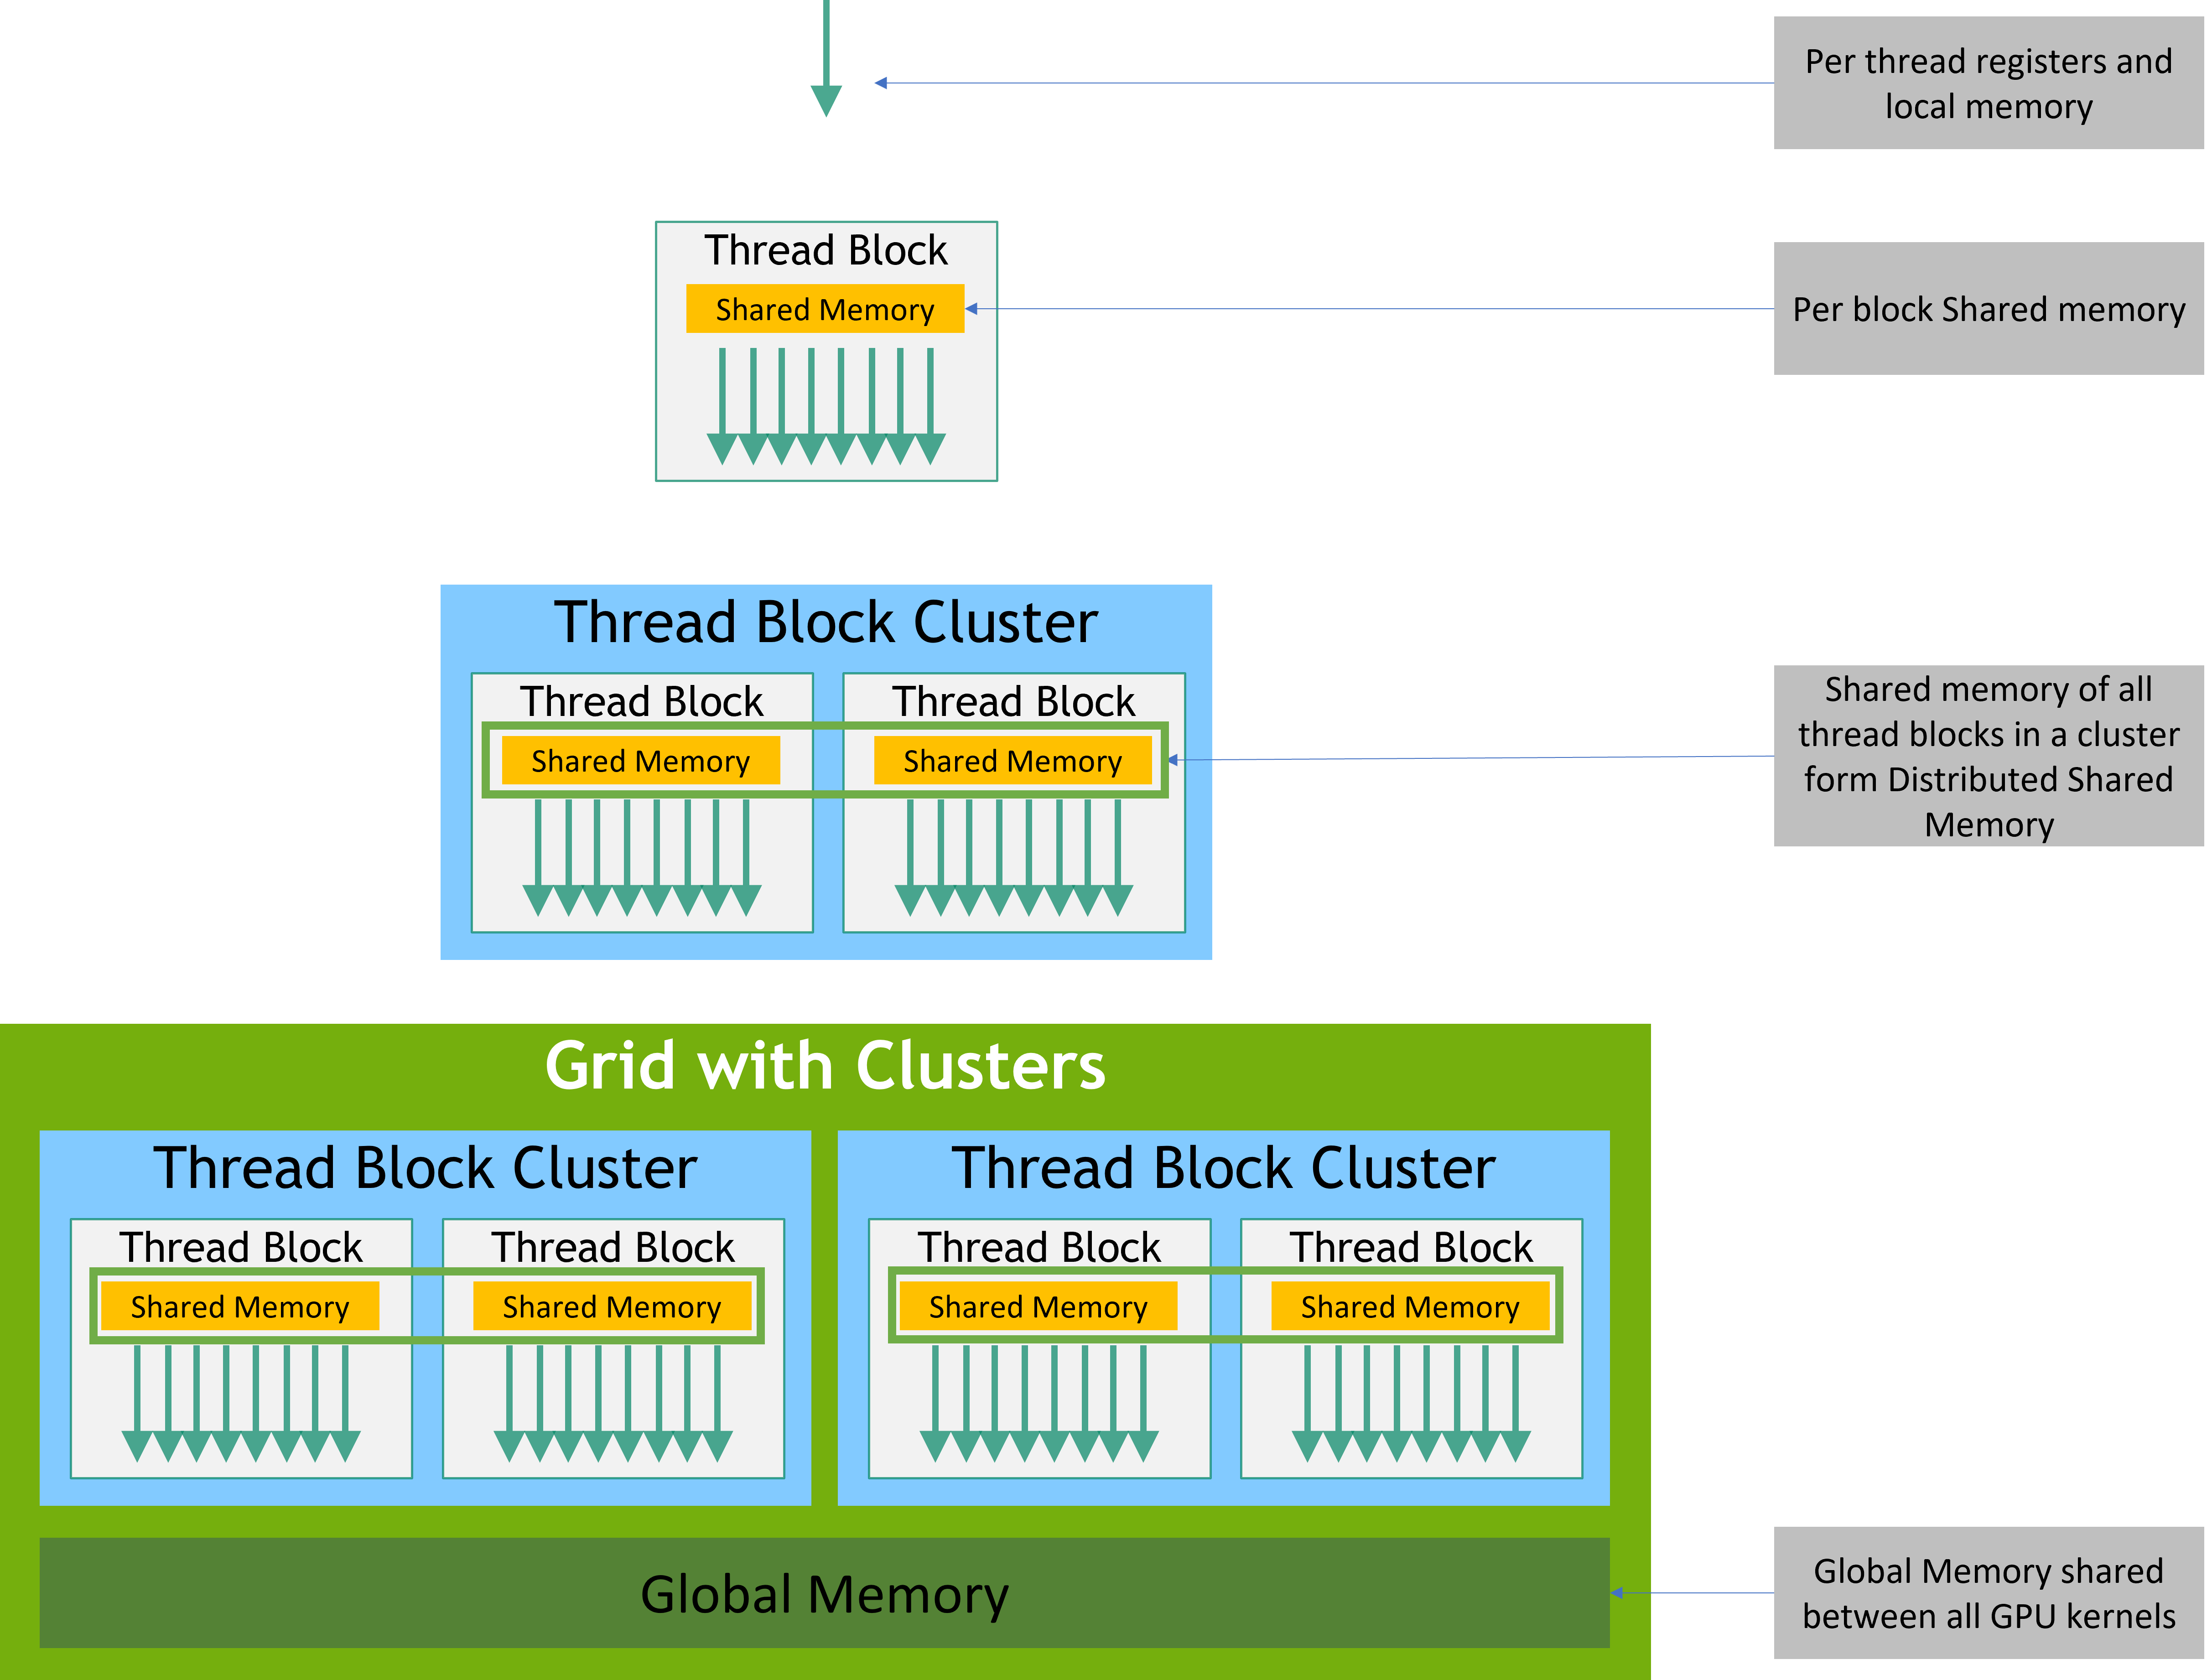
静态与动态内存的区别
| 特性 | 静态共享内存 | 动态共享内存 |
|---|---|---|
| 声明方式 | __shared__ float arr[size]; |
extern __shared__ float[]; |
| 大小确定时机 | 编译时 | 内核启动时 |
| 访问速度 | 略快(地址硬编码) | 略慢(运行时计算偏移) |
| 典型用途 | 固定大小的缓存 | 运行时决定大小的临时存储 |
| 作用域 | 整个集群内的所有线程块 + 非集群内的线程块 | 整个集群内的所有线程块 |
| 大小单位 | 以每个线程块为单位 | 以每个线程块为单位 |
异步内存拷贝(cuda::memcpy_async)
允许在GPU执行计算的同时,异步地从全局内存移动数据。
同步对象:cuda::barrier or a cuda::pipeline,
同步范围: cuda::thread_scope::thread_scope_thread, cuda::thread_scope::thread_scope_block,cuda::thread_scope::thread_scope_device,cuda::thread_scope::thread_scope_system
-code=sm_80 编译成针对计算能力8.0的二进制,-arch=compute_50 指定C++编译为PTX代码时采用的计算能力,要通过流实现内存拷贝间的重叠行为, 页锁是必须的:因为如果使用普通内存,则cudaMemcpyAsync会退化为同步操作, 因为要等待cpu固定页面,而页锁可以使GPU的直接访问内存(DMA)。
cudaStream_t stream[2];
for (int i = 0; i < 2; ++i)
    cudaStreamCreate(&stream[i]);
float* hostPtr;
cudaMallocHost(&hostPtr, 2 * size);

for (int i = 0; i < 2; ++i) {
    cudaMemcpyAsync(inputDevPtr + i * size, hostPtr + i * size,
                    size, cudaMemcpyHostToDevice, stream[i]);
    MyKernel <<<100, 512, 0, stream[i]>>>
          (outputDevPtr + i * size, inputDevPtr + i * size, size);
    cudaMemcpyAsync(hostPtr + i * size, outputDevPtr + i * size,
                    size, cudaMemcpyDeviceToHost, stream[i]);
}
如果GPU设备不支持并行的数据传输 , 其优化方案如下:
for (int i = 0; i < 2; ++i)
    cudaMemcpyAsync(inputDevPtr + i * size, hostPtr + i * size,
                    size, cudaMemcpyHostToDevice, stream[i]);
for (int i = 0; i < 2; ++i)
    MyKernel<<<100, 512, 0, stream[i]>>>
          (outputDevPtr + i * size, inputDevPtr + i * size, size);
for (int i = 0; i < 2; ++i)
    cudaMemcpyAsync(hostPtr + i * size, outputDevPtr + i * size,
                    size, cudaMemcpyDeviceToHost, stream[i]);
这样, 提交到流[1]的主机到设备内存拷贝操作,将与提交到流[0]的内核启动操作产生执行重叠。
void CUDART_CB MyCallback(void *data){
    printf("Inside callback %d\n", (size_t)data);
}
...
for (size_t i = 0; i < 2; ++i) {
    cudaMemcpyAsync(devPtrIn[i], hostPtr[i], size, cudaMemcpyHostToDevice, stream[i]);
    MyKernel<<<100, 512, 0, stream[i]>>>(devPtrOut[i], devPtrIn[i], size);
    cudaMemcpyAsync(hostPtr[i], devPtrOut[i], size, cudaMemcpyDeviceToHost, stream[i]);
    cudaLaunchHostFunc(stream[i], MyCallback, (void*)i);
}
// get the range of stream priorities for this device
int leastPriority, greatestPriority;
cudaDeviceGetStreamPriorityRange(&leastPriority, &greatestPriority);
// create streams with highest and lowest available priorities
cudaStream_t st_high, st_low;
cudaStreamCreateWithPriority(&st_high, cudaStreamNonBlocking, greatestPriority));
cudaStreamCreateWithPriority(&st_low, cudaStreamNonBlocking, leastPriority);

实现如下: 注意并发和死锁
__global__ void primary_kernel() {
   // Initial work that should finish before starting secondary kernel

   // Trigger the secondary kernel
   cudaTriggerProgrammaticLaunchCompletion();

   // Work that can coincide with the secondary kernel
}

__global__ void secondary_kernel()
{
   // Independent work

   // Will block until all primary kernels the secondary kernel is dependent on have completed and flushed results to global memory
   cudaGridDependencySynchronize();

   // Dependent work
}

cudaLaunchAttribute attribute[1];
attribute[0].id = cudaLaunchAttributeProgrammaticStreamSerialization;
attribute[0].val.programmaticStreamSerializationAllowed = 1;
configSecondary.attrs = attribute;
configSecondary.numAttrs = 1;

primary_kernel<<<grid_dim, block_dim, 0, stream>>>();
cudaLaunchKernelEx(&configSecondary, secondary_kernel);
也可以使用cuda 图的方式,待研究...
*cuda图: 可以通过api创建, 也可以通过流捕获,cudaStreamBeginCapture() 会将流置于捕获模式。当流处于捕获状态时,提交到该流的工作不会立即排队执行,而是逐步追加到一个正在构建的内部图中
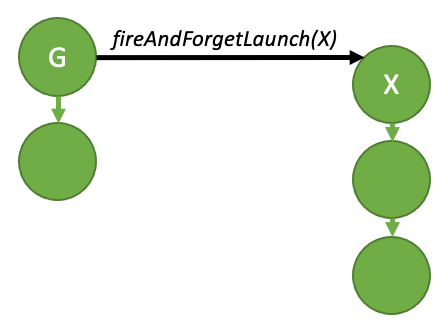
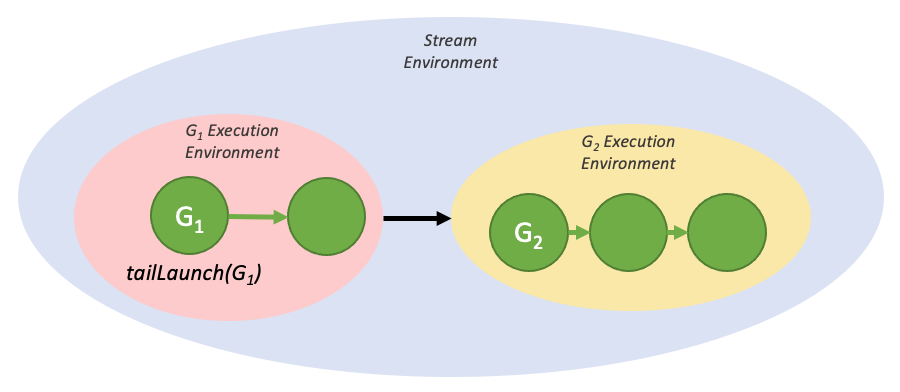
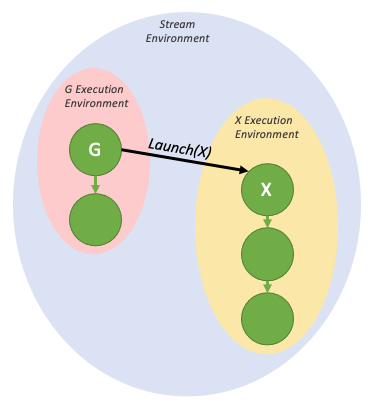
cudaEventRecord(event2, stream2);cudaStreamWaitEvent(stream1, event2);| 即发即弃启动模式 | cudaStreamGraphFireAndForget |
|---|---|
| 尾部启动模式 | cudaStreamGraphTailLaunch |
| 同级启动模式 | cudaStreamGraphFireAndForgetAsSibling |
即发即弃启动:
尾部启动:
同级启动:
对等拷贝:
cudaSetDevice(0);                   // Set device 0 as current
float* p0;
size_t size = 1024 * sizeof(float);
cudaMalloc(&p0, size);              // Allocate memory on device 0
cudaSetDevice(1);                   // Set device 1 as current
float* p1;
cudaMalloc(&p1, size);              // Allocate memory on device 1
cudaSetDevice(0);                   // Set device 0 as current
MyKernel<<<1000, 128>>>(p0);        // Launch kernel on device 0
cudaSetDevice(1);                   // Set device 1 as current
cudaMemcpyPeer(p1, 1, p0, 0, size); // Copy p0 to p1
MyKernel<<<1000, 128>>>(p1);        // Launch kernel on device 1
当应用程序以64位进程运行时,主机与所有计算能力2.0及以上的设备将共享统一的虚拟地址空间,
cudaPointerAttributes attributes;
cudaPointerGetAttributes(&attributes, ptr);  // 可确定指针位于主机/设备内存
cudaMemcpy(dest, src, size, cudaMemcpyDefault); // 自动识别指针位置
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。