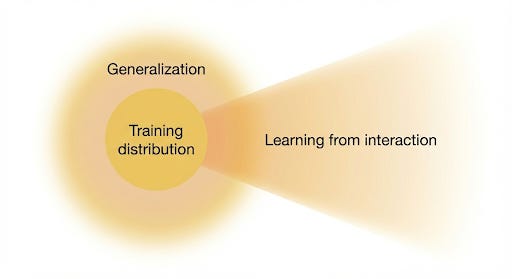
Every time people talk about “generalization” in LLMs, they mean something different. This often leads to subsequent debate. Why?
The problem with generalization is that the word doesnt generalize.
We've long been beyond the traditional statistical understanding, of generalizing to new samples from the "same distribution". Today, you can come up with a completely novel phrasing, or misspelling of the query, and LLMs will still respond correctly
This means, for a benchmark, it's no longer enough to prevent contamination of the exact input/output pair.
In fact, with better representations, RL, and some human ingenuity in deploying capital to create targeted data, it's now enough to know a description of the distribution to optimize. We can even get pretty far with LLMs combining and transforming existing data into the target distribution.
This is what people observe as "benchmaxxing". The issue is, even the set of describable distributions explodes combinatorially. Everyone wants something slightly different, our wants keep evolving, and to this the models don't necessarily generalize. This is probably what Ilya meant when he said "models still can't generalize" on Dwarkesh’s podcast.
It is why, I think, static benchmarks, ironically even “live” ones, are dead. Unless the distribution keeps drifting over time, unpredictably, any benchmark can now be hillclimbed with relative ease.
Yet, this is not enough for AGI. Why? Because the world keeps changing. In fact, everytime a model becomes capable on a new distribution, we want to use it for a new set of problems, which exposes new holes. Progress in AI capabilities will continue to extend our imagination, and this is a testament to human ingenuity.
So, what should we evaluate in 2026? For one, we need new ways to measure sample efficient adaptation by learning from interactions, what some put under the general umbrella of "continual learning". We want models to perform well on the "novel" situations we find ourselves in, which may be off the training distribution in subtle ways.
The promising sign is, for a lot of user queries off the training distribution, such as in coding, models do generalize, especially if they are a combination of seen distributions. Here's the crux:
We need to stop viewing generalization, or "out of distribution" as a discrete, static concept. Otherwise the words will keep changing meaning based on context.
Generalization is a continuous spectrum: how far you can you correctly extrapolate given what you've seen.
Humans do it to differing extents, depending on how much time evolution spent optimizing on the environment. We generalize extremely well in changes to our physical environment. Novel math, the environment of abstract symbols, has long been considered the pinnacle of human intelligence. Generalization is a function of optimization in an environment.
The optimization could even be at “test time”. If you are capable of self-verification, or in other words, have a good “world model” or “value function”, “thinking” is also optimization. We discover, simpler, more general principles the more we think about a problem.
Similarly, for models, they generalize to different extents based on what you ask, how far it is from what the model has seen in training, and how much the model was optimized for nearby distributions. For the rest, one day, they will be able to learn fast from interactions. That, would be true general intelligence, and fill the “jagged frontier”. They don't have to make discoveries in “quantum gravity” to get there. Neither have you.