

惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

Stack Overflow Blog
Stack Overflow Blog
S
SegmentFault 最新的问题
大猫的无限游戏
大猫的无限游戏
The GitHub Blog
The GitHub Blog
M
MIT News - Artificial intelligence
T
Tailwind CSS Blog
aimingoo的专栏
aimingoo的专栏
Last Week in AI
Last Week in AI
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
让小产品的独立变现更简单 - ezindie.com
罗磊的独立博客
H
Help Net Security
Engineering at Meta
Engineering at Meta
Microsoft Security Blog
阮一峰的网络日志
阮一峰的网络日志
J
Java Code Geeks
T
The Blog of Author Tim Ferriss
Hugging Face - Blog
Hugging Face - Blog
C
Check Point Blog
F
Fortinet All Blogs
腾讯CDC
博客园 - Franky
WordPress大学
WordPress大学
U
Unit 42

Google Developers Blog

Build zero-trust AI agents that judge intent, not just syntax- Google Developers Blog Autonomous LLM post-training with Tunix on TPUs- Google Developers Blog The Anatomy of Harness Engineering: How to Evaluate, Iterate, and Guard AI Coding Agents- Google Developers Blog Announcing ADK for Kotlin 1.0: Building Production-Ready AI Agents in Kotlin, Android, and Beyond- Google Developers Blog Driving Developer Excellence: Inside the Program Sprints- Google Developers Blog 4 engineering patterns behind the strongest AI Agents Challenge submissions- Google Developers Blog Decoding cosmic signals with deep learning and Keras- Google Developers Blog Enterprise-Grade Precision for Long-Context Multimodal Embedding Inference on Cloud TPU- Google Developers Blog How to Evaluate Live & Voice Agents in ADK- Google Developers Blog Build zero-trust AI agents with Google's Agent Development Kit- Google Developers Blog Introducing Credentio: Open Source C++ Library for C2PA Content Credentials from Google- Google Developers Blog HeyGen x Google Cloud: Bringing Avatar IV to TPUs- Google Developers Blog Why Go is an Ideal Language for AI-Assisted Software Engineering- Google Developers Blog Mastering Edge AI on Raspberry Pi with LiteRT and Gemma- Google Developers Blog Agent Plugins package your skills, tools, and more- Google Developers Blog Scaling AI Agent Infrastructure with the MCP Stateless updates- Google Developers Blog A unified API for AI model routing- Google Developers Blog Scaling real-time AI agents with session-aware load balancing- Google Developers Blog Agent and Model Evaluations in Gemini Enterprise Agent Platform are now GA- Google Developers Blog Enable on-demand expertise with Agent Skills in Genkit Go- Google Developers Blog How to use Google microbenchmarks for evaluating TPU performance- Google Developers Blog Run Ray on TPU, Part 2: Ray AI libraries- Google Developers Blog Scaling Agentic RL: High-Throughput Agentic Training with Tunix- Google Developers Blog Run Ray on TPU, Part 1: The foundations- Google Developers Blog Expanding Choice in Gemini Enterprise Agent Platform: Introducing Grounding with Parallel Web Search- Google Developers Blog Building scalable AI agents with modular prompt transpilation- Google Developers Blog Evolving Spec-Driven Development: Conductor Now Supports Antigravity- Google Developers Blog Systems Engineering Playbook: Optimizing Qwen 3.5-397B MoE on Ironwood (TPU7x)- Google Developers Blog Unlocking the Next Era of On-Device AI with Google Tensor and Pixel- Google Developers Blog LiteRT.js, Google's high performance Web AI Inference- Google Developers Blog
Gemma 4 12B: The Developer Guide
André Susano Pinto, Andreas Steiner, Karolis Misiunas, Karsten R · 2026-06-03 · via Google Developers Blog

Following the announcement in our launch blog, we are releasing Gemma 4 12B, a dense multimodal model with a unified, encoder-free architecture.

Gemma 4 12B introduces several milestones for local AI:

  1. A multimodal encoder-free architecture: Bypassing heavy multi-stage vision and audio encoders entirely, multimodal data is fed straight into the LLM backbone, reducing multimodal latency.
  2. Our first medium-sized model with audio input: In the Gemma family, audio inputs were restricted to small, lightweight edge architectures (e.g. E4B). Gemma 4 12B is the first medium-sized model capable of natively ingesting audio.
  3. Developer-friendly size: Small enough to run locally on dedicated GPU laptops with 16GB VRAM or unified memory. To maximize local inference speeds, we are additionally releasing a dedicated multi-token prediction (MTP) model.
  4. New MacOS desktop experience: For the first time, we are releasing downloadable macOS desktop applications, letting developers experience fully local spoken and visual interaction directly on consumer-grade devices.

The Architecture

Traditional multimodal models rely on frozen, separate vision encoders (e.g., Gemma 4 uses a 150M parameter vision model for edge sizes and 550M for medium-sized models) and audio encoders (300M parameters for Gemma 4 E2B and E4B). Processing multimodal inputs with multiple separate encoders before feeding them to the LLM leads to increased latency and fragmented memory footprints.

Gemma 4 12B solves these issues by utilizing a single decoder-only transformer containing the same advanced decoder structure as the Gemma 4 31B Dense model.
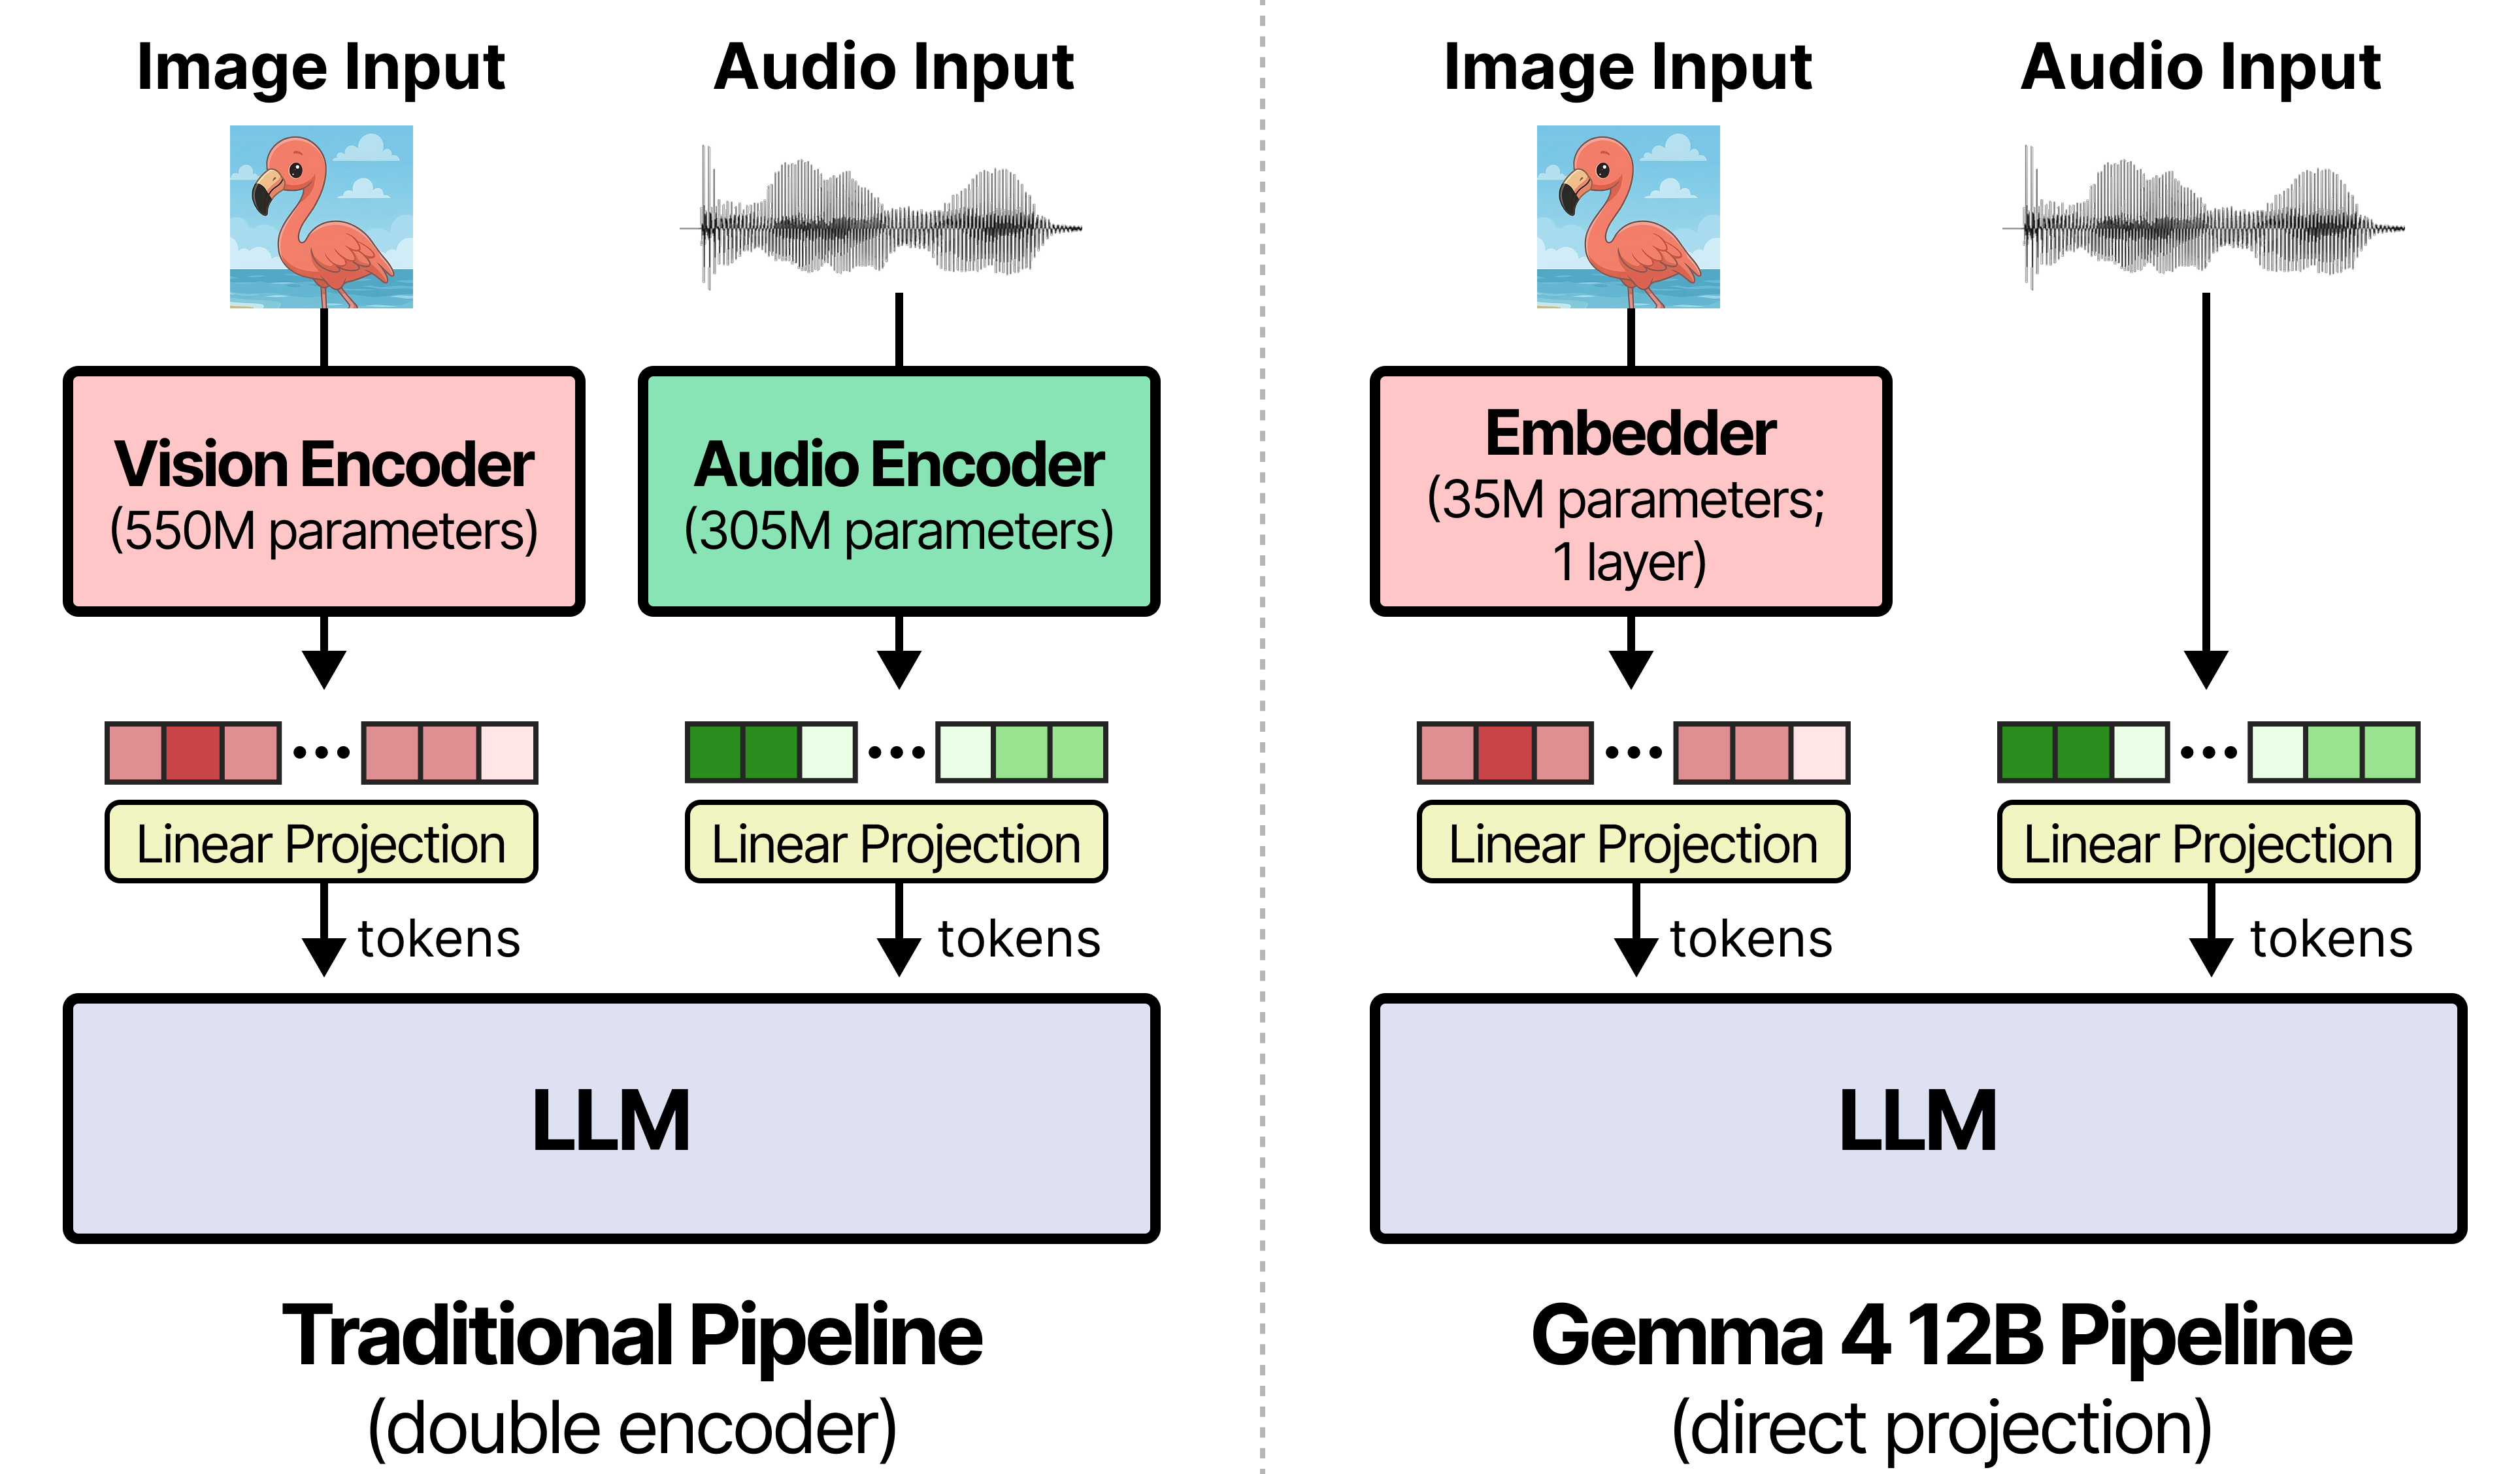
overview

  • Vision embedder (35M parameters): Replaces the 27 vision transformer layers of the other medium-sized Gemma 4 models. Raw 48x48 pixel patches are projected to the LLM hidden dimension with a single matmul. A factorized coordinate lookup (X and Y matrices) attaches spatial location information directly to the input.
  • Audio wave projection: Eliminates the separate audio encoder (skipping the 12 conformer layers used in Gemma 4 E2B and E4B). Raw 16 kHz audio signals are sliced into 40ms frames (640 floats each) and projected linearly to the LLM input space.
  • Unified fine-tuning advantage: Because vision, audio, and text inputs share the exact same weights, you no longer have to co-tune separate frozen encoders. Downstream adapter (e.g. LoRA) or full tuning naturally update the entire multimodal token loop in a single pass (via Hugging Face or Unsloth).

For a more in-depth overview of how this encoder-free architecture works, check out A Visual Guide to Gemma 4 12B.

Capabilities

Gemma 4 12B achieves outstanding performance, with capabilities such as automatic speech recognition, agentic reasoning, diarization, video understanding, coding, and more.

See below examples for a demonstration of the model's agentic and multimodal capabilities:

Example 1: Gemma 4 12B creates a local image processing app that uses Gemma 4 12B

Thanks to its agentic and multimodal understanding capabilities, Gemma 4 12B can be easily used with existing agent harnesses like OpenCode. In this example, we served it locally using llama.cpp using the gemma-skills to code a Gradio app that helped the user process images. This app was powered by the same Gemma 4 12B model that built it!

Example 2: Processing 5 minutes of Video at 1 FPS with audio

We used Gemma 4 12B to analyse a part from the Google IO Keynote moment from May 19, specifically the 5 minutes between 00:15:32 and 00:20:45. To do that, we extracted all the frames of that segment (at 1 FPS), plus the prompt and the audio from the video:

Prompt:

  1. 313 frames (at 1FPS, images resized to visual token budget 70)
  2. "what happens when the man takes a selfie?"
  3. the Video's audio + the prompt below
When the man takes a "selfie" or is shown holding a smartphone in front of his face in these demonstration videos, it is a clever way to visually represent how the AI models can take existing media—like a personal photo or a video clip—and "reimagine" it. In these specific clips, the model is taking a selfie and using it as a base to generate various scenarios (like a person in a space station, or walking through a forest).

Essentially, the man is not actually taking a selfie; rather, he is **acting out a visual metaphor for the AI's capability to take one specific input (a "selfie") and generate a whole world of new content based on it.** This is part of the "Swap" and "Build worlds" demonstrations of the Gemini Omni model, showing its ability to perform complex, multi-modal reasoning and creative generation.

On-Device & Desktop Serving: Powered by LiteRT-LM

In tandem with the Gemma 4 12B launch, we are officially introducing powerful on-device developer integrations powered by LiteRT-LM, bringing zero-latency local AI execution natively to standard desktop environments:

1.Native MacOS Apps: The mobile Google AI Edge Gallery is officially expanding to desktop platforms, running Gemma 4 12B offline, natively on Apple Silicon GPUs. It comes with a secure sandboxed Python execution loop to write, execute, and plot scientific charts inside the chat bubble. In parallel, the Google AI Edge Eloquent app on Mac launches support for Gemma 12B to power Voice Edit conversational inputs.

2. Drop-in Local API Servers (litert-lm serve): Run Gemma 4 12B as a local, OpenAI-compatible API server using the new litert-lm serve CLI command. Seamlessly connect standard integrations (e.g., Continue, Aider, OpenClaw, Hermes or OpenCode), leveraging stateless prefix caching in memory to match context history and instantly bypass prefill latency.

litert-lm import --from-huggingface-repo=litert-community/gemma-4-12B-it-litert-lm  gemma-4-12B-it.litertlm gemma4-12b

# Start the OpenAI-compatible server
litert-lm serve

Shell

Copied

Find a deep dive about it on the Google AI Edge Gallery blog.

Getting Started Today

Ready to build local multimodal agents with the first encoder-free architecture of the Gemma family? Here is how you can jump in today