








This article is also available in Chinese 简体中文.
Recently, Argilla and Hugging Face launched Data is Better Together, an experiment to collectively build a preference dataset of prompt rankings. In a few days, we had:
See the progress dashboard for the latest stats!
This resulted in the release of 10k_prompts_ranked, a dataset consisting of 10,000 prompts with user ratings for the quality of the prompt. We want to enable many more projects like this!
In this post, we’ll discuss why we think it’s essential for the community to collaborate on building datasets and share an invitation to join the first cohort of communities Argilla and Hugging Face will support to develop better datasets together!
Data continues to be essential for better models: We see continued evidence from published research, open-source experiments, and from the open-source community that better data can lead to better models.
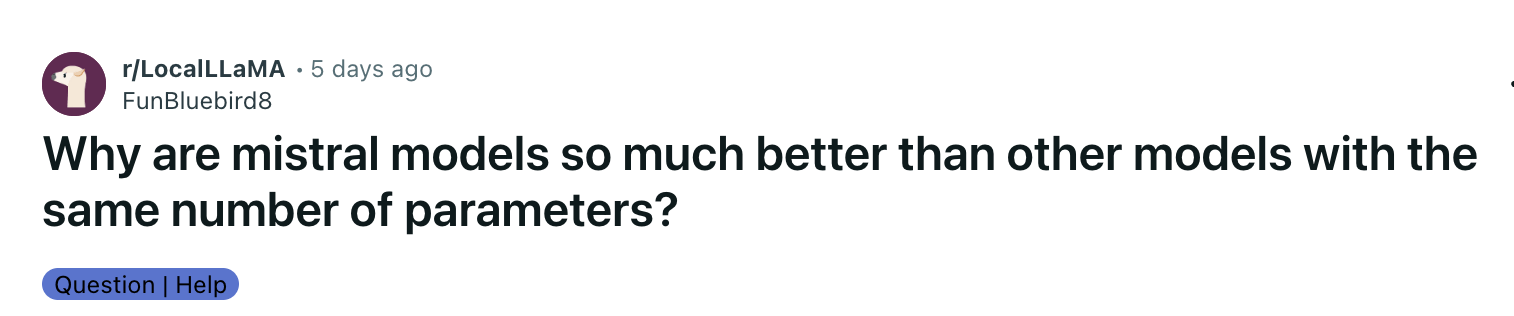
The question.
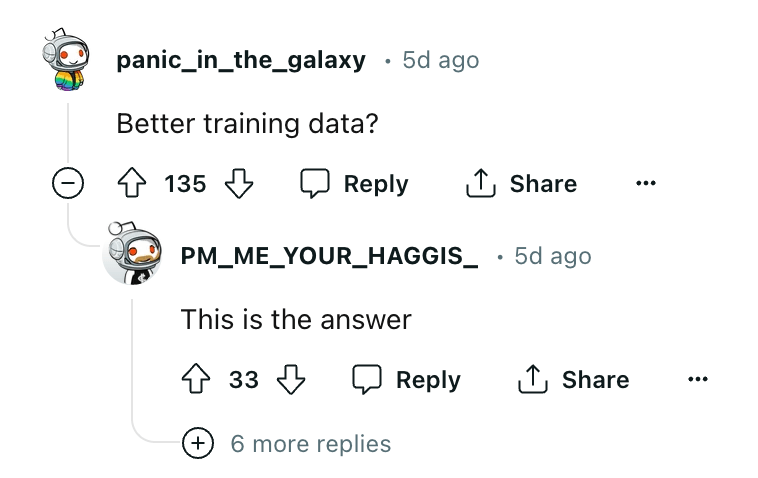
A frequent answer.
Data is vital for machine learning, but many languages, domains, and tasks still lack high-quality datasets for training, evaluating, and benchmarking — the community already shares thousands of models, datasets, and demos daily via the Hugging Face Hub. As a result of collaboration, the open-access AI community has created amazing things. Enabling the community to build datasets collectively will unlock unique opportunities for building the next generation of datasets to build the next generation of models.
Empowering the community to build and improve datasets collectively will allow people to:
Importantly we believe that building datasets collectively will allow the community to build better datasets abd allow people who don't know how to code to contribute to the development of AI.
One of the challenges to many previous efforts to build AI datasets collectively was setting up an efficient annotation task. Argilla is an open-source tool that can help create datasets for LLMs and smaller specialised task-specific models. Hugging Face Spaces is a platform for building and hosting machine learning demos and applications. Recently, Argilla added support for authentication via a Hugging Face account for Argilla instances hosted on Spaces. This means it now takes seconds for users to start contributing to an annotation task.
Now that we have stress-tested this new workflow when creating the 10k_prompts_ranked, dataset, we want to support the community in launching new collective dataset efforts.
We’re very excited about the possibilities unlocked by this new, simple flow for hosting annotation tasks. To support the community in building better datasets, Hugging Face and Argilla invite interested people and communities to join our initial cohort of community dataset builders.
People joining this cohort will:
Our goal is to support the community in building better datasets together. We are open to many ideas and want to support the community as far as possible in building better datasets together.
We are open to supporting many types of projects, especially those of existing open-source communities. We are particularly interested in projects focusing on building datasets for languages, domains, and tasks that are currently underrepresented in the open-source community. Our only current limitation is that we're primarily focused on text-based datasets. If you have a very cool idea for multimodal datasets, we'd love to hear from you, but we may not be able to support you in this first cohort.
Tasks can either be fully open or open to members of a particular Hugging Face Hub organization.
If you want to be part of the first cohort, please join us in the #data-is-better-together channel in the Hugging Face Discord and let us know what you want to build together!
We are looking forward to building better datasets together with you!
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。