


All hype aside, it's hard to deny the profound impact that AI is having on society and businesses. From startups to enterprises to the public sector, every customer we talk to is busy experimenting with large language models and generative AI, identifying the most promising use cases, and gradually bringing them to production.
The #1 comment we get from customers is that no single model will rule them all. They understand the value of building the best model for each use case to maximize its relevance on company data while optimizing the compute budget. Of course, privacy and intellectual property are also top concerns, and customers want to ensure they maintain complete control.
As AI finds its way into every department and business unit, customers also realize the need to train and deploy many different models. In a large multinational organization, this could mean running hundreds, even thousands, of models at any time. Given the pace of AI innovation, newer and higher-performance model architectures will also lead customers to replace their models quicker than expected, reinforcing the need to train and deploy new models in production quickly and seamlessly.
All of this will only happen with standardization and automation. Organizations can't afford to build models, tools, and infrastructure from scratch for new projects. Fortunately, the last few years have seen some very positive developments:
In addition, our cloud partnerships let customers use Hugging Face models and libraries at any scale without worrying about provisioning infrastructure and building technical environments. This makes it much easier to get high-quality models out the door at a rapid pace without having to reinvent the wheel.
Following up on our collaboration with AWS on Amazon SageMaker and Microsoft on Azure Machine Learning, we're thrilled to work with none other than IBM on their new AI studio, watsonx.ai. watsonx.ai is the next-generation enterprise studio for AI builders to train, validate, tune, and deploy both traditional ML and new generative AI capabilities, powered by foundation models.
IBM decided that open source should be at the core of watsonx.ai. We couldn't agree more! Built on RedHat OpenShift, watsonx.ai will be available in the cloud and on-premise. This is excellent news for customers who cannot use the cloud because of strict compliance rules or are more comfortable working with their confidential data on their infrastructure. Until now, these customers often had to build their in-house ML platform. They now have an open-source off-the-shelf alternative deployed and managed using standard DevOps tools.
Under the hood, watsonx.ai also integrates many Hugging Face open-source libraries, such as transformers (100k+ GitHub stars!), accelerate, peft and our Text Generation Inference server, to name a few. We're happy to partner with IBM and to collaborate on the watsonx AI and data platform so that Hugging Face customers can work natively with their Hugging Face models and datasets to multiply the impact of AI across businesses.
In addition, IBM has also developed its own collection of Large Language Models, and we will work with their team to open-source them and make them easily available in the Hugging Face Hub.
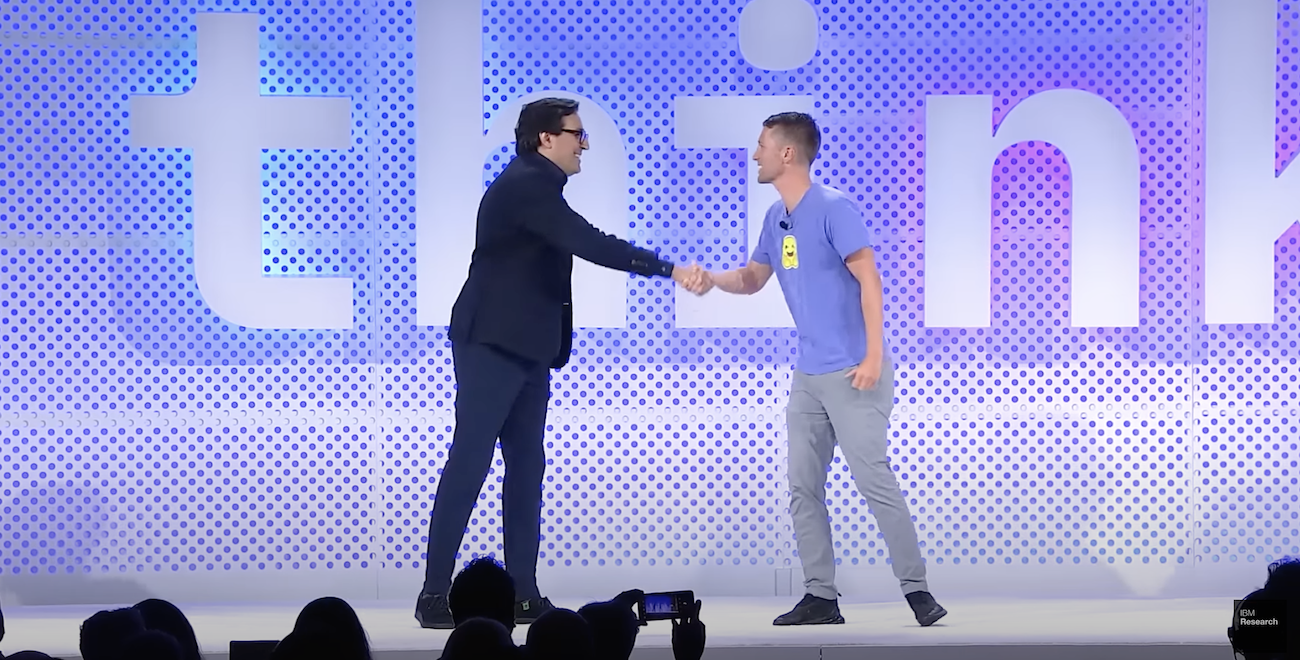
To learn more, watch Dr. Darío Gil, SVP and Director of IBM Research, and our CEO Clem Delangue, announce our collaboration, walk through the watsonx platform, and present IBM’s suite of Large Language Models in an IBM THINK 2023 keynote.
Our joint team is hard at work at the moment. We can't wait to show you what we've been up to! The most iconic of technology companies joining forces with an up-and-coming startup to tackle AI in the Enterprise... who would have thought?
Fascinating times. Stay tuned!
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。