





The rise of Generative AI and LLMs like ChatGPT has increased the interest and importance of embedding models for a variety of tasks especially for retrievel augemented generation, like search or chat with your data. Embeddings are helpful since they represent sentences, images, words, etc. as numeric vector representations, which allows us to map semantically related items and retrieve helpful information. This helps us to provide relevant context for our prompt to improve the quality and specificity of generation.
Compared to LLMs are Embedding Models smaller in size and faster for inference. That is very important since you need to recreate your embeddings after you changed your model or improved your model fine-tuning. Additionally, is it important that the whole retrieval augmentation process is as fast as possible to provide a good user experience.
In this blog post, we will show you how to deploy open-source Embedding Models to Hugging Face Inference Endpoints using Text Embedding Inference, our managed SaaS solution that makes it easy to deploy models. Additionally, we will teach you how to run large scale batch requests.
Before we start, let's refresh our knowledge about Inference Endpoints.
Hugging Face Inference Endpoints offers an easy and secure way to deploy Machine Learning models for use in production. Inference Endpoints empower developers and data scientists to create Generative AI applications without managing infrastructure: simplifying the deployment process to a few clicks, including handling large volumes of requests with autoscaling, reducing infrastructure costs with scale-to-zero, and offering advanced security.
Here are some of the most important features:
You can get started with Inference Endpoints at: https://ui.endpoints.huggingface.co/
Text Embeddings Inference (TEI) is a purpose built solution for deploying and serving open source text embeddings models. TEI is build for high-performance extraction supporting the most popular models. TEI supports all top 10 models of the Massive Text Embedding Benchmark (MTEB) Leaderboard, including FlagEmbedding, Ember, GTE and E5. TEI currently implements the following performance optimizing features:
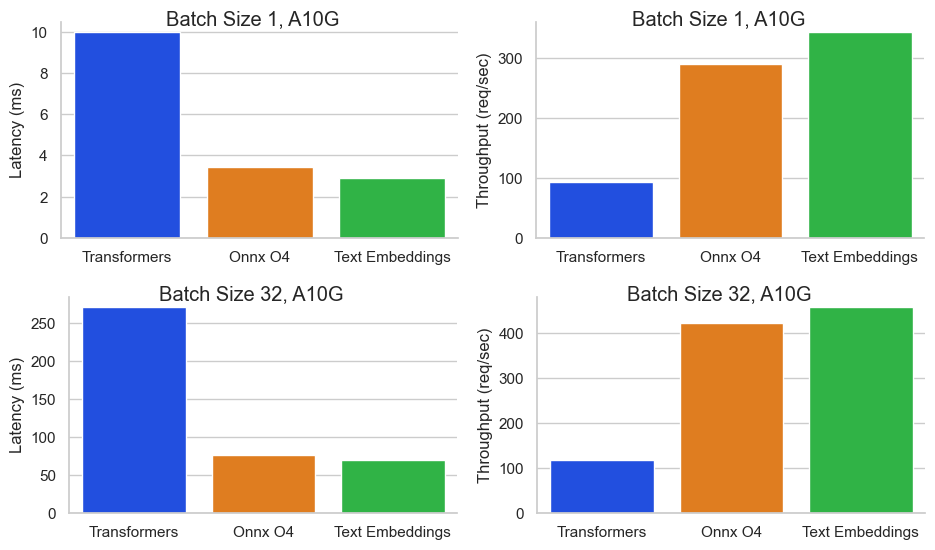
Those feature enabled industry-leading performance on throughput and cost. In a benchmark for BAAI/bge-base-en-v1.5 on an Nvidia A10G Inference Endpoint with a sequence length of 512 tokens and a batch size of 32, we achieved a throughput of 450+ req/sec resulting into a cost of 0.00156$ / 1M tokens or 0.00000156$ / 1k tokens. That is 64x cheaper than OpenAI Embeddings ($0.0001 / 1K tokens).
To get started, you need to be logged in with a User or Organization account with a payment method on file (you can add one here), then access Inference Endpoints at https://ui.endpoints.huggingface.co
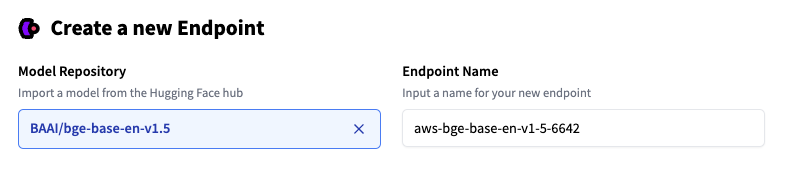
Then, click on “New endpoint”. Select the repository, the cloud, and the region, adjust the instance and security settings, and deploy in our case BAAI/bge-base-en-v1.5.
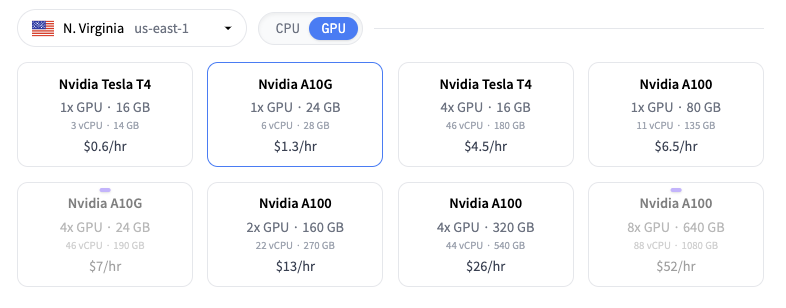
Inference Endpoints suggest an instance type based on the model size, which should be big enough to run the model. Here Intel Ice Lake 2 vCPU. To get the performance for the benchmark we ran you, change the instance to 1x Nvidia A10G.
Note: If the instance type cannot be selected, you need to contact us and request an instance quota.
You can then deploy your model with a click on “Create Endpoint”. After 1-3 minutes, the Endpoint should be online and available to serve requests.
The Endpoint overview provides access to the Inference Widget, which can be used to manually send requests. This allows you to quickly test your Endpoint with different inputs and share it with team members.
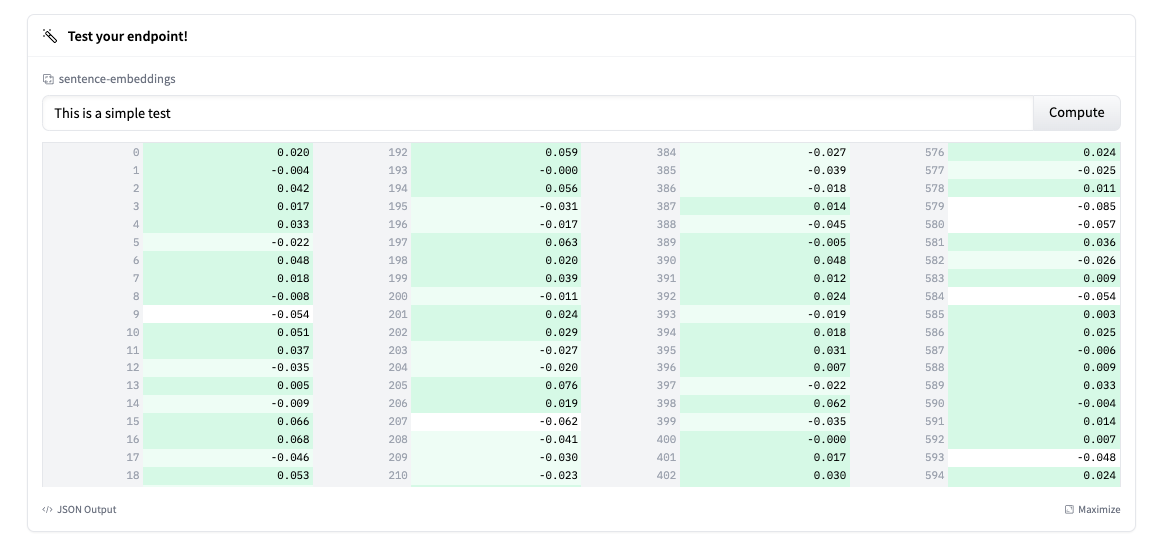
Note: TEI is currently is not automatically truncating the input. You can enable this by setting truncate: true in your request.
In addition to the widget the overview provides an code snippet for cURL, Python and Javascript, which you can use to send request to the model. The code snippet shows you how to send a single request, but TEI also supports batch requests, which allows you to send multiple document at the same to increase utilization of your endpoint. Below is an example on how to send a batch request with truncation set to true.
import requests

API_URL = "https://l2skjfwp9punv393.us-east-1.aws.endpoints.huggingface.cloud"
headers = {
    "Authorization": "Bearer YOUR TOKEN",
    "Content-Type": "application/json"
}

def query(payload):
    response = requests.post(API_URL, headers=headers, json=payload)
    return response.json()

output = query({
"inputs": ["sentence 1", "sentence 2", "sentence 3"],
"truncate": True
})

# output [[0.334, ...], [-0.234, ...]]
TEI on Hugging Face Inference Endpoints enables blazing fast and ultra cost-efficient deployment of state-of-the-art embeddings models. With industry-leading throughput of 450+ requests per second and costs as low as $0.00000156 / 1k tokens, Inference Endpoints delivers 64x cost savings compared to OpenAI Embeddings.
For developers and companies leveraging text embeddings to enable semantic search, chatbots, recommendations, and more, Hugging Face Inference Endpoints eliminates infrastructure overhead and delivers high throughput at lowest cost streamlining the process from research to production.
Thanks for reading! If you have any questions, feel free to contact me on Twitter or LinkedIn.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。