








Foundation models like CLIP are fantastic tools for classification applications, but they sometimes focus on the wrong features due to biases in their training data. To overcome this limitation, my colleagues and I developed ROBOSHOT.
The ROBOSHOT method improves the robustness of pre-trained model embeddings in a fully zero-shot fashion, without any additional fine-tuning required.
My PhD advisor, Fred Sala, included a note about ROBOSHOT in his presentation about Skill-It! at Snorkel AI’s Enterprise LLM Summit in January, but I recently had the privilege to present and discuss my work on ROBOSHOT in greater depth with Snorkel’s researchers.
You can watch a recording of the presentation (embedded below), but I have also summarized the main points here.
Our work with ROBOSHOT began with understanding how embedding-based foundation models like CLIP make predictions. We start with a sample image and a list of possible labels. The model gets the image embedding and the labels’ embedding, then makes a classification by taking a dot product between the image embedding and all the label embeddings. The model predicts the label based on which has the highest cosine similarity with the image.
These off-the-shelf models can achieve respectable accuracy, but they sometimes rely on spurious correlations in the training data. For example, in classifying water birds versus land birds, if the pre-training dataset often shows water birds in front of water and land birds on land, the model may mistakenly use the background as the basis for its prediction.
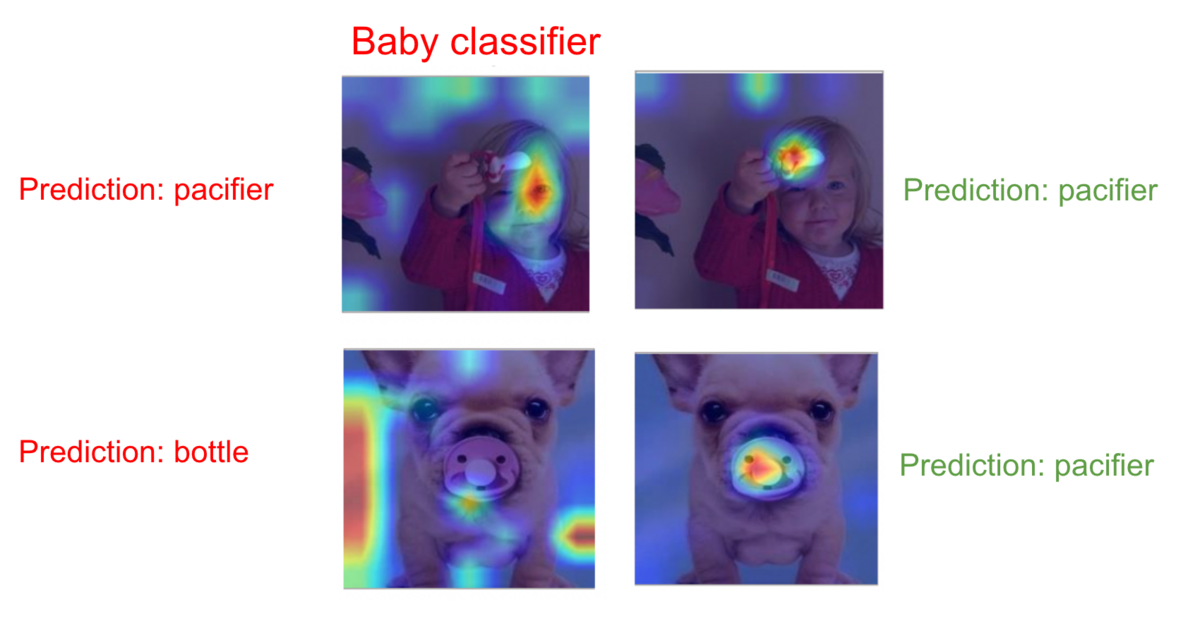
To address this, we can use a large language model (LLM) like GPT-4 to identify likely spurious correlations and useful features. We then use techniques from the literature on embedding debiasing to modify the model’s behavior in the embedding space.
Our experiments show that using embeddings to reject spurious features tends to reduce variance along one vector. Amplifying the importance of our predicted helpful features enlarges the variance in orthogonal directions.
We experimented with only-rejection approaches and only-projection approaches. We’ve seen that reducing spurious correlations and increasing useful features together yields the best results.
We applied ROBOSHOT to various tasks and datasets and have seen promising results—including on the waterbirds and land birds data set mentioned above. As mentioned, standard pre-trained models struggle with this task because they rely on the bird’s immediate environment to make its prediction. ROBOSHOT redirected the model to focus more on features of the bird itself, such as the shape of its beak.
Our results showed not only an improvement in the average accuracy but also a notable increase in the worst-group accuracy, which improved by almost 30%.
We also applied ROBOSHOT to textual tasks using models like BERT and ADA (OpenAI’s embedding model). In a sentiment classification task, we observed positive results, indicating that ROBOSHOT’s approach to identifying and reducing spurious correlations can be successfully extended to textual data.
These preliminary results are encouraging and underscore the potential of ROBOSHOT in improving the robustness of pre-trained models, even in a fully zero-shot setting.
While ROBOSHOT is unable to handle more complex models like transformers or LLMs, where each token has one embedding per layer. Secondly, it’s currently focused on classification tasks where the features can be easily described with language.
In cases where we can’t find a textual description to differentiate features, ROBOSHOT’s abilities are limited. For example, a human can look at an LLM output and declare whether they think it is harmful, but they may struggle to put into words why they think it’s harmful.
We’re actively working to overcome these limitations.
As we look forward to the future of ROBOSHOT, we hope that it could help build more cost-effective and efficient alternatives to the current LLM alignment methods. The current process, known as reinforcement learning from human feedback (RLHF), involves a complex and often time-consuming procedure.
In RLHF, data scientists collect human preference data and use it to retrain the base language model using a reinforcement learning objective function. This process, while effective, requires substantial human and computational resources.
Our ongoing research explores the possibility of modifying language models in the embedding or activation space during inference. In essence, the future directions for ROBOSHOT revolve around making the process of aligning machine learning models with human preferences more efficient, cost-effective, and widely applicable.
Our work on ROBOSHOT has shown promising results in improving the robustness of pre-trained model embeddings in a zero-shot fashion. We’re excited about the potential impact of this method in the field of machine learning, particularly in settings where access to labeled data is limited.
We look forward to continuing our research and finding ways to overcome the current limitations. Thank you for your time and interest in our work.
Snorkel has more live online events coming. Look at our events page to sign up for research webinars, product overviews, and case studies.
If you're looking for more content immediately, check out our YouTube channel, where we keep recordings of our past webinars and online conferences.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。