

惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

Martin Fowler
Martin Fowler
Cyber Security Advisories - MS-ISAC
雷峰网
雷峰网
J
Java Code Geeks
G
Google Developers Blog
博客园 - 司徒正美
The GitHub Blog
The GitHub Blog
L
LangChain Blog
人人都是产品经理
人人都是产品经理
GbyAI
GbyAI
Vercel News
Vercel News
S
SegmentFault 最新的问题
Engineering at Meta
Engineering at Meta
H
Hackread – Cybersecurity News, Data Breaches, AI and More
云风的 BLOG
云风的 BLOG
F
Fortinet All Blogs
Y
Y Combinator Blog
博客园_首页
Last Week in AI
Last Week in AI
让小产品的独立变现更简单 - ezindie.com
罗磊的独立博客
A
About on SuperTechFans
B
Blog
Microsoft Security Blog

Snorkel AI

Building AI-Native Systems for Federal Infrastructure: A Conversation with Rezaur Rahman Code World Models and AutoHarness for LLM Agents Benchtalks #1: Alex Shaw (Terminal-Bench, Harbor) – Building the Benchmark Factory Building FinQA: An Open RL Environment for Financial Reasoning Agents How Tool Discipline Let a 4B Model Outsmart a 235B Giant on Financial Tasks Coding agents don’t need to be perfect, they need to recover Closing the Evaluation Gap in Agentic AI SlopCodeBench: Measuring Code Erosion as Agents Iterate Introducing the Snorkel Agentic Coding Benchmark 2026: The year of environments Part V: Future Direction and Emerging Trends in Rubric-Based AI Evaluation The self-critique paradox: Why AI verification fails where it’s needed most Chat With the Terminal-Bench Team | Snorkel AI Intelligence per watt: A new metric for AI’s future Terminal-Bench 2.0: Raising the bar for AI agent evaluation Snorkeling in RL environments Introducing SnorkelSpatial: A Benchmark for LLM Spatial Reasoning Scaling Trust: Rubrics in Snorkel's Quality Process Evaluating Multi-Agent Systems in Enterprise Tool Use Evaluating Coding Agents with Terminal-Bench 2.0 Parsing isn’t neutral: why evaluation choices matter The science of rubric design The right tool for the job: An A-Z of rubrics Data quality and rubrics: how to build trust in your models Building the benchmark: inside our agentic insurance underwriting dataset Evaluating AI agents for insurance underwriting LLM observability: key practices, tools, and challenges Anthropic Claude + AWS: revolutionizing pharma data analytics with Snorkel AI Data-centric development of an enterprise AI agent with Snorkel Building the data development platform for specialized AI
The Art and Science of Building AI Benchmarks That Shape ...
Alexis Sobel · 2026-06-16 · via Snorkel AI

Vincent Sunn Chen spoke at AI Engineer London about what it actually takes to build AI benchmarks that move the field forward, not just measure it.

The throughline is an asymmetry that keeps showing up across deployments and the 150+ proposals reviewed for the Open Benchmarks Grants: agent capabilities are climbing fast, but the ability to measure those agents with rigorous AI benchmarks in realistic, high-stakes settings has lagged behind. Closing that evaluation gap is one of the most important problems in AI right now — and open benchmarks are one of the most powerful levers available to address it.

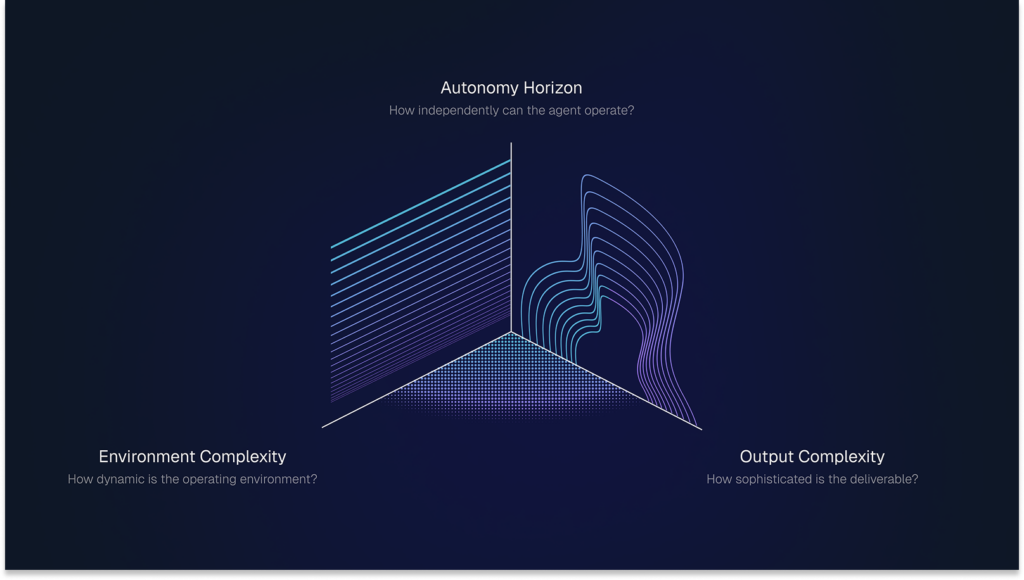
In the talk, Vincent breaks the problem into two halves. The first is the science of an effective measuring stick — rigorous task quality, deliberate distributional diversity, real model headroom, and a robust evaluation methodology — illustrated with benchmarks like GPQA, MMLU, ARC-AGI, and τ-bench. The second is the art that separates benchmarks that merely measure from the ones that reshape the field: a clear thesis on where things are going, a roadmap others can build on, and first-class researcher UX — think Terminal-Bench, SWE-bench, and HELM. The talk closes with a look at where the next great benchmarks may emerge: environment complexity, autonomy horizon, and output complexity.
If you want to go deeper than the talk, the two pieces below are the fuller written versions:


And if any of this maps to what you’re building, the Open Benchmarks Grants are open: a $3M commitment to fund open benchmarks, datasets, and evaluation artifacts for frontier agents. Share a proposal or reach out at benchmarks.snorkel.ai.