








As AI shifts from chatbots to autonomous agents, open models are serving market demands for full control over where AI runs and how it’s deployed and evolves.
Today, NVIDIA is expanding its Nemotron 3 model family with Nemotron 3.5 Lightning, the highest-efficiency model in its class for long-running agentic AI workloads. This release follows Nemotron 3 Nano and reflects NVIDIA’s commitment to continually improving open models for greater accuracy and speed.
Built for specialized tasks within larger multi-agent systems, Nemotron 3.5 Lightning, a 30-billion-parameter mixture-of-experts model, helps create smarter and more efficient agentic applications.
Also, NVIDIA is releasing NeMo Switchyard, an open source library for smart routing inside popular agent tools. Enterprises can use it to build a router based on their specific needs. When deployed, NeMo Switchyard can intelligently direct each request to the most capable and suitable model for the job without requiring developers to rewrite their applications.
Together, Nemotron 3.5 Lightning and NeMo Switchyard deliver greater control over how AI is deployed, where it runs and how efficiently it operates — across PCs, workstations, data centers and the cloud.
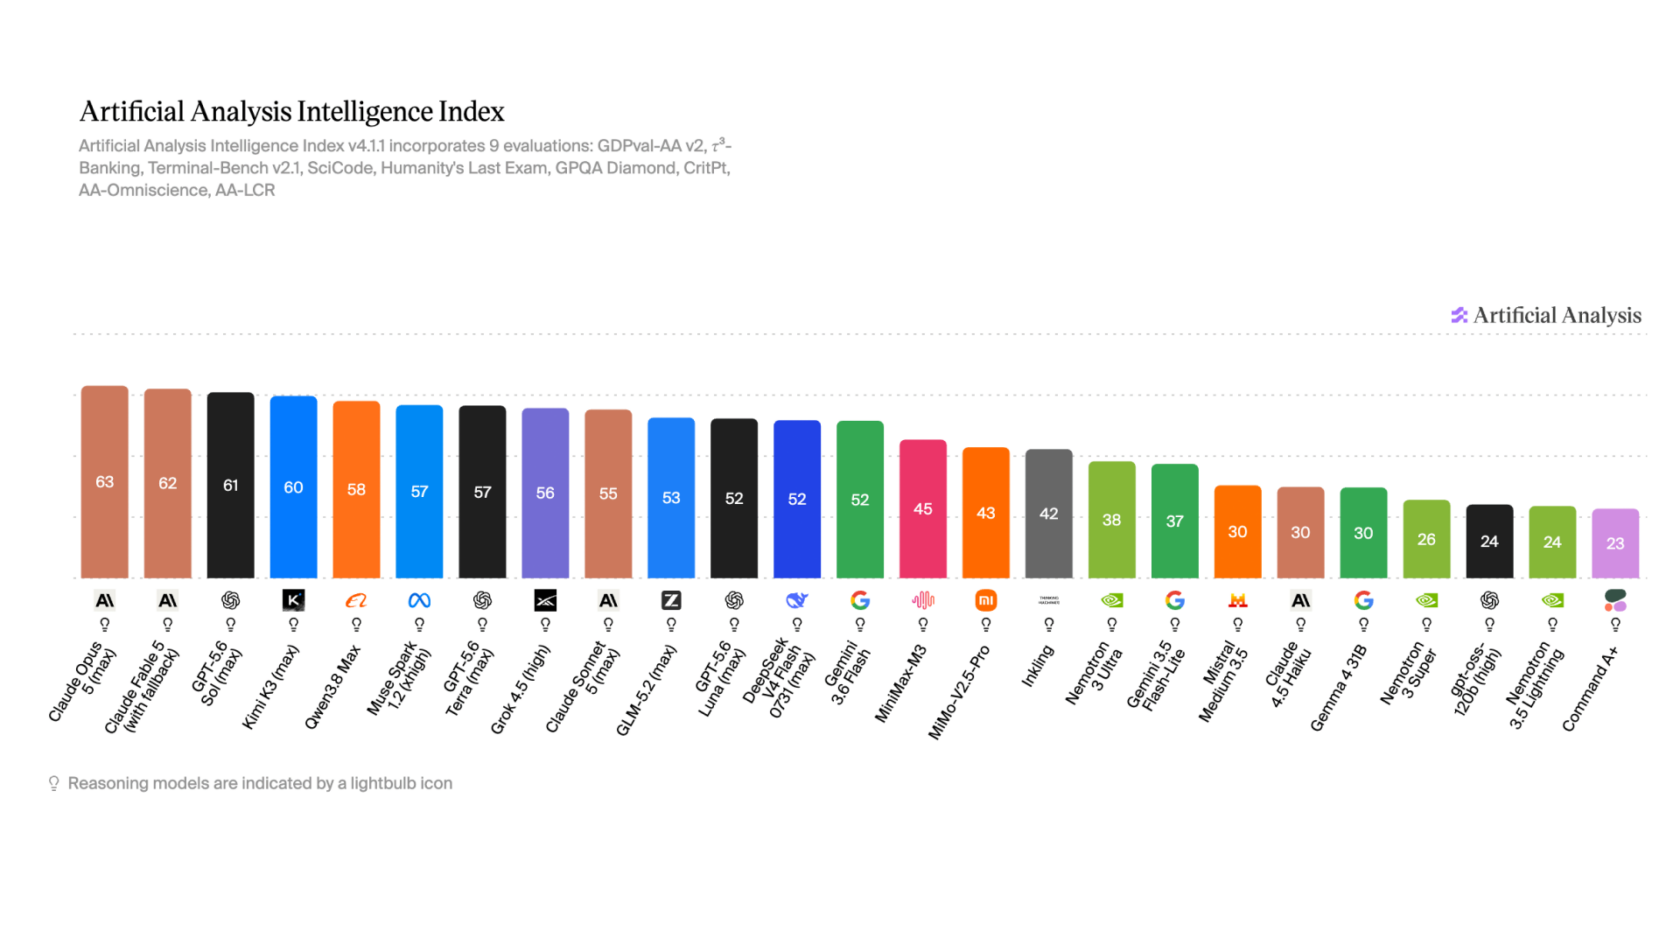
Modern agentic systems — always-on agents — increasingly operate as systems of models, or model ensembles, with different models specialized for different tasks.
NVIDIA Nemotron open models are designed for this architecture. A frontier reasoning model such as Nemotron 3 Ultra or GPT-5.6 may plan and orchestrate a workflow, while smaller specialized models like Nemotron 3.5 Lightning can perform targeted tasks such as code review, tool use, security alert monitoring and answering billing questions.
NVIDIA Nemotron 3.5 Lightning is a fully customizable open model built for high-volume tasks powering always-on agents. It was developed with contributions from the Nemotron Coalition, whose members provided evaluation methodologies, inference software and datasets to help advance the model.
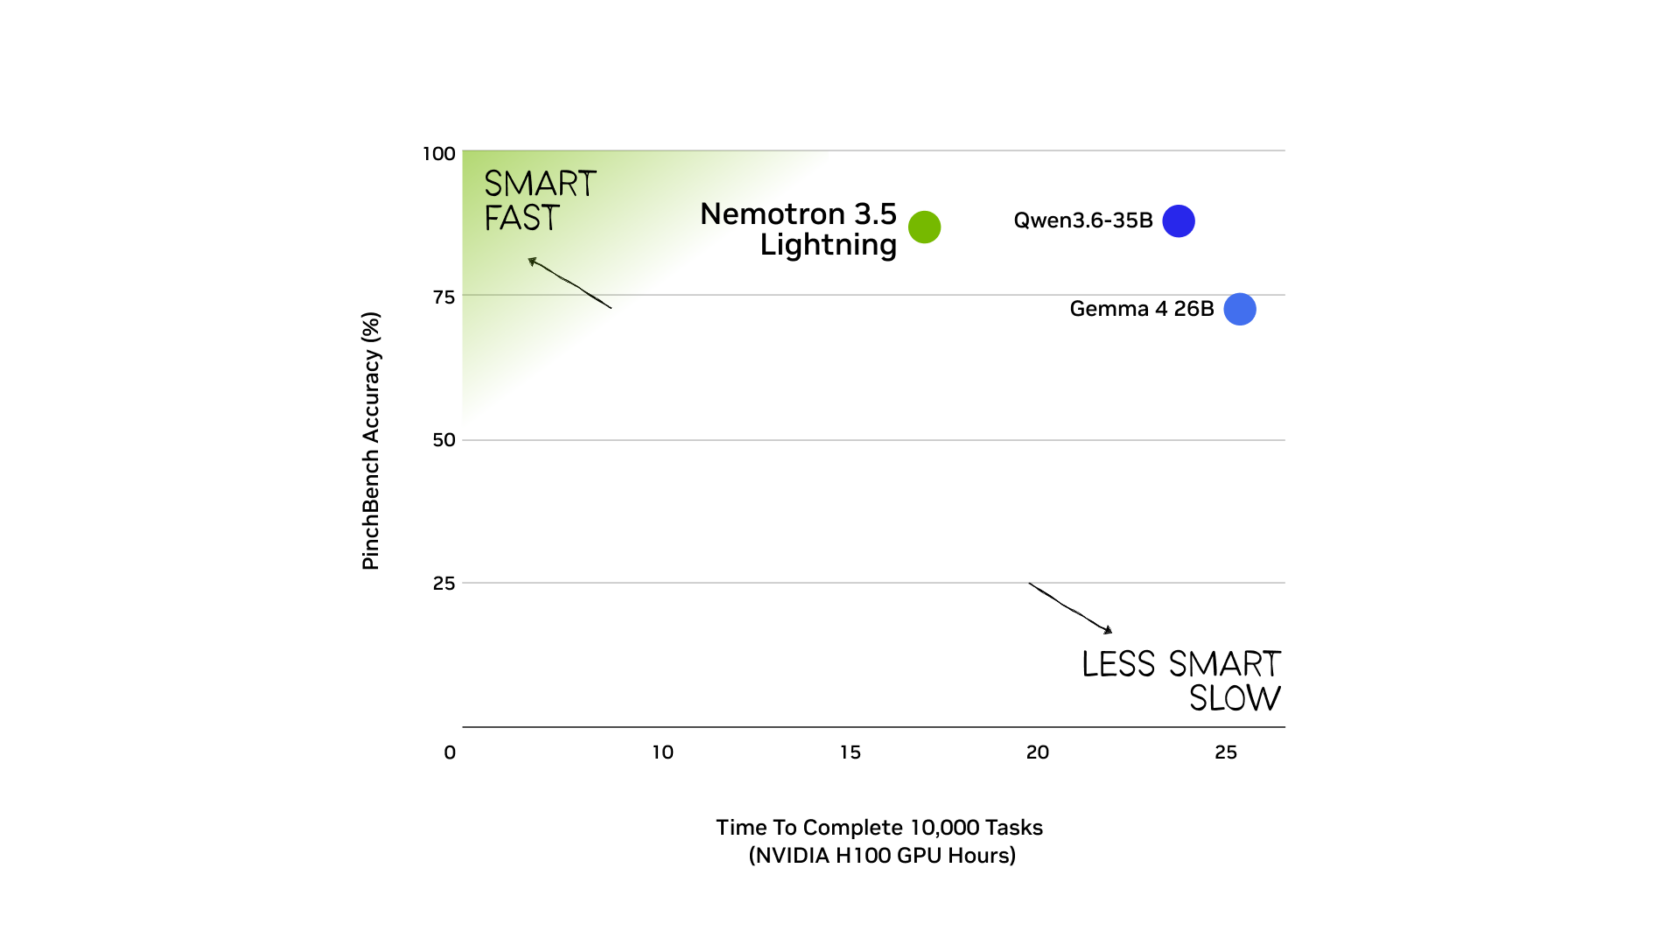
The model delivers up to 4x faster output speed, leading to 30% faster agentic task completion compared with other models in its class. And because it’s open and customizable, Nemotron 3.5 Lightning can be easily post-trained with NVIDIA NeMo on an organization’s own domain data, tools and workflows to improve accuracy for specialized tasks.
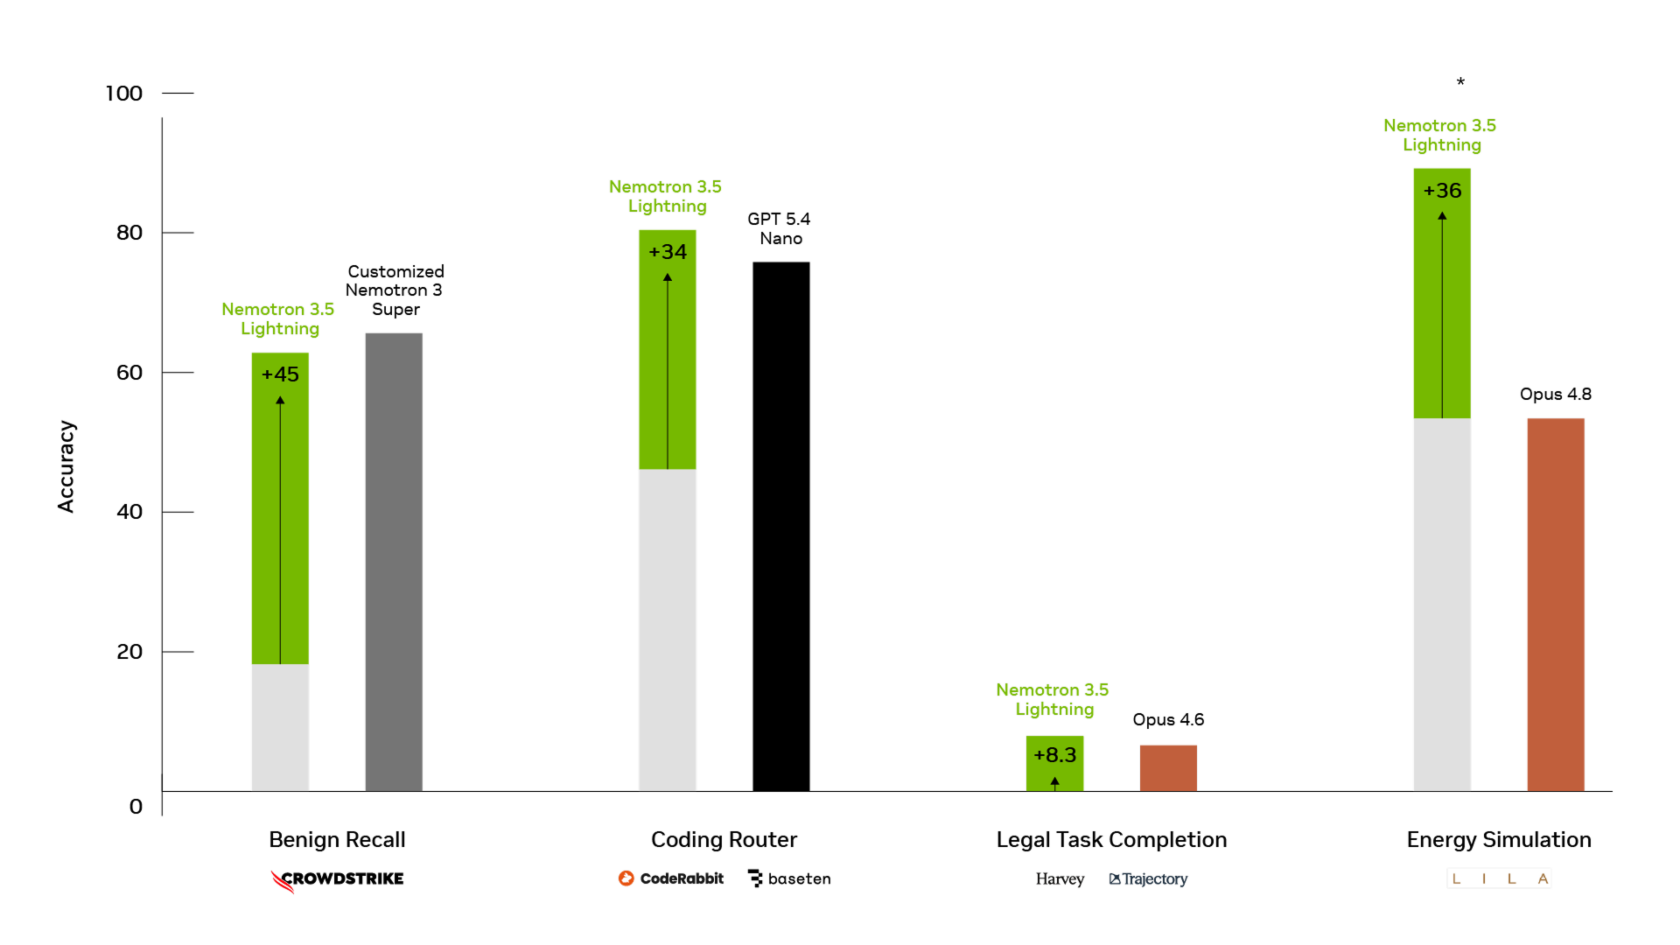
AI leaders across industries are customizing Nemotron 3.5 Lightning for their workloads, including CrowdStrike for cybersecurity, Harvey with Trajectory for legal services and CodeRabbit with Baseten for code review, helping improve accuracy for domain-specific agentic tasks. Additionally, Lila Sciences is helping to improve reasoning capabilities for agentic tasks across physical and life sciences, and Fastino Labs customized the model and is seeing leading accuracies for software development, finance and healthcare workloads.
Nemotron 3.5 Lightning also gives organizations control over privacy and deployment. It can run on local AI systems — including NVIDIA RTX PCs, NVIDIA DGX Spark, NVIDIA DGX Station and NVIDIA Jetson — to help users maximize existing infrastructure investments, or scale across edge AI devices, NVIDIA RTX PRO workstations, data centers and cloud environments for enterprise use cases. And Nemotron 3.5 Lightning can run locally or on premises for high-volume, specialized tasks that require fast responses.
Also, as with every Nemotron launch, NVIDIA publishes as much of the training data and techniques as licensing permits, which allows for traceability, auditing and training of other models. Alongside Lightning, NVIDIA is releasing Nemotron-RL-Agentic-Terminal-Pivot, an agentic reinforcement learning dataset used to post-train it for coding agent capabilities.
Some models are better for coding, some for reasoning, some for lightweight tasks and some are optimized to run locally for greater privacy and efficiency. If customers rely on one default model, they might either overspend or lose quality; if they manage routing manually, it becomes integration work that can slow down a deployment.
NVIDIA NeMo Switchyard is an open source model routing library for AI agents. The technology routes prompts to the most capable and efficient model for each step of an agent workflow automatically, based on specific needs. Agent application developers can tune or modify the router with different routing algorithms to match their priorities, such as quality, latency and cost requirements. In a system of models, enterprises can create powerful AI agents with improved tokenomics.
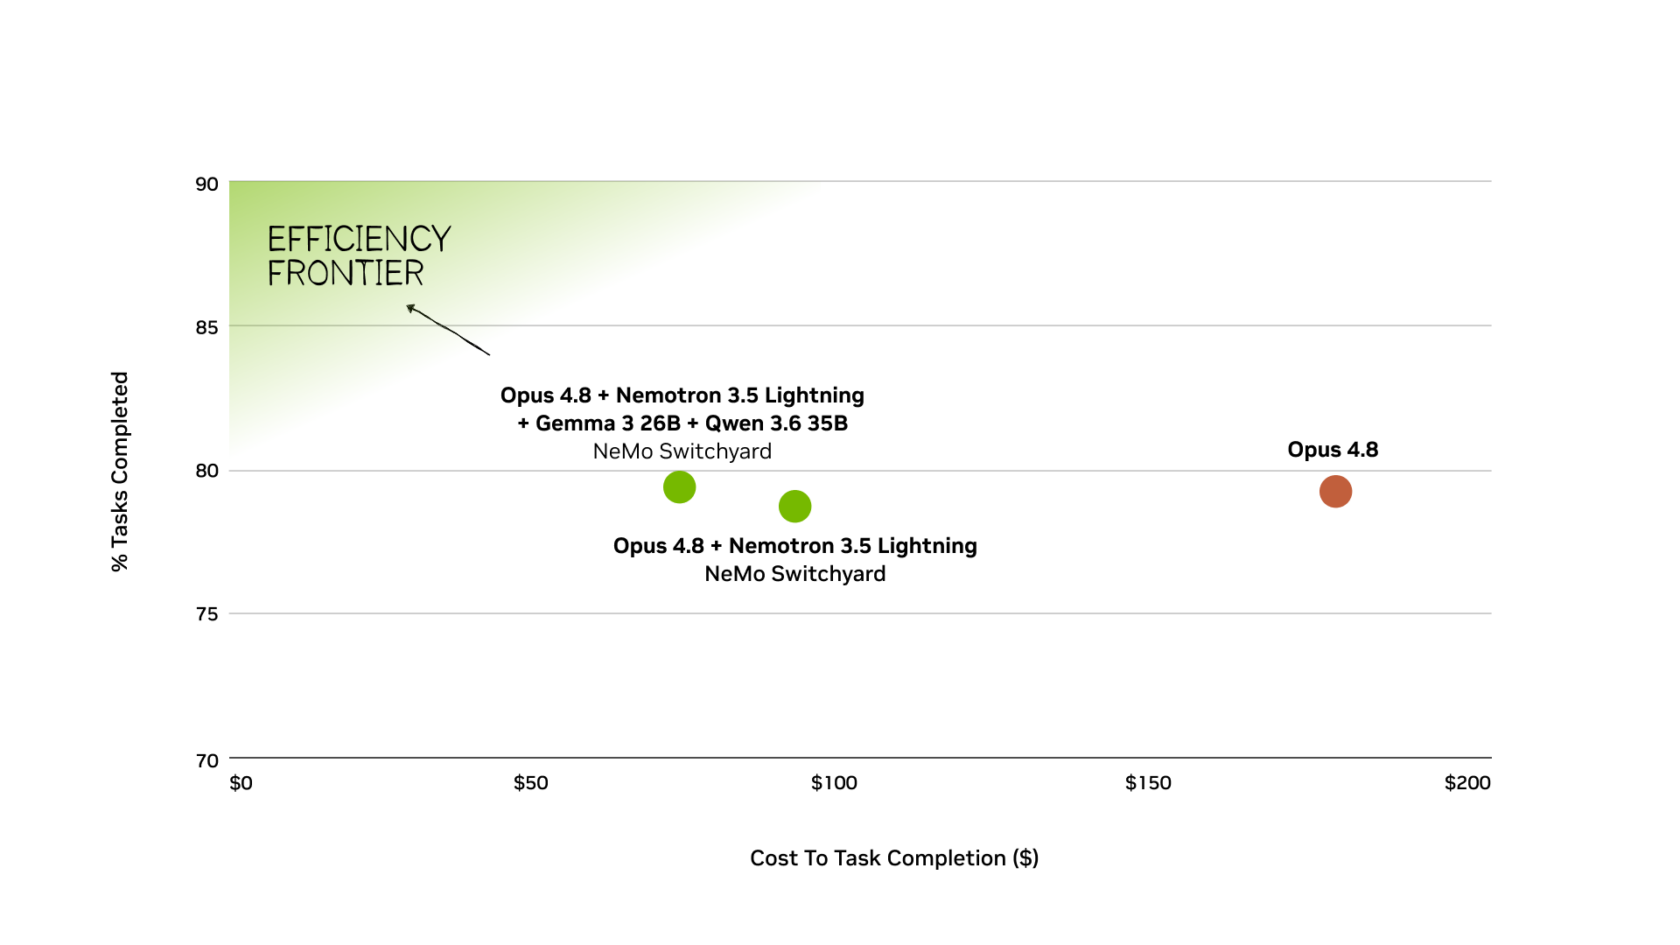
Internal benchmarks show that NeMo Switchyard maintains frontier-level accuracy while reducing task completion cost to nearly one-third of Opus 4.8 alone.
NVIDIA is working with partners across the AI ecosystem to bring intelligent model routing into the tools and platforms developers already use.
Nemotron 3.5 Lightning is available on Hugging Face, ModelScope, OpenRouter and build.nvidia.com as an NVIDIA NIM microservice as well as through a broad ecosystem of NVIDIA Cloud Partners, post-training platforms, inference platforms and cloud service providers. NeMo Switchyard is available on GitHub and coming to partner platforms soon.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。