








Frontier intelligence is going local. At IFA 2026, NVIDIA, Microsoft and its partners are teaming up to provide faster inference and new tools that make agents easier to set up and run locally on NVIDIA hardware. New compact NVIDIA RTX Spark Windows PCs are also coming in October to give AI enthusiasts, developers and creators more ways to run capable agents locally and securely.
Today’s announcements include:
Also, August was a busy month for local AI:
Getting a local agent up and running with local models required some effort — choosing a model, finding a compatible inference server, dialing in quantization settings and keeping everything updated. That friction is disappearing on RTX and DGX systems.
Three of the most widely used agent apps will offer simplified local model setup on Windows, each built on llama.cpp and incorporating NVIDIA’s latest inference optimizations. The new setup experiences are designed to reduce manual configuration and make it easier to get local agents up and running.
Last month, Perplexity introduced its Portable Computer agent, giving users a simple way to run Perplexity locally on Linux systems like NVIDIA DGX Spark with the models, orchestration and tools packaged into a single app experience.
Perplexity Portable Computer is available on NVIDIA RTX GPUs with at least 24GB VRAM running on Linux, with support on Windows coming soon, bringing that same streamlined setup to a broader group of PC users. Users can run complete workflows locally without consuming credits, while selectively escalating parts of a task to one of 15+ frontier models in the cloud when additional research or reasoning is needed. Portable Computer asks for permission before sending content to the cloud, helping users keep sensitive information on their device. Here’s some example use-cases:
Try Portable Computer today.
Hermes Agent — developed by Nous Research — is a general-purpose agent used by millions that excels at reliability and self-improvement. Model- and provider-agnostic, Hermes is built to run all day on local systems, making RTX PCs, RTX PRO workstations and DGX Spark a natural fit.
Configuring a local model in Hermes will provide users with one-click setup across RTX and DGX systems on Windows. The agent will automatically detect the NVIDIA GPU, select an appropriate model and configuration, and run it through integrated llama.cpp with NVIDIA inference optimizations already in place, eliminating manual model downloads and tuning. Support for Linux is coming soon.
Once it is running, Hermes works the way it does anywhere else. It uses tools, maintains context across tasks, remembers information between sessions and creates reusable skills over time, allowing the agent to become more capable with continued use. Running the model locally on a GPU keeps performance fast while keeping data on the system.
One-click local model setup is available now on Windows, with support coming soon to Linux. Learn more about Hermes Agent.
OpenClaw has become one of the defining projects of the open-agent movement — the largest AI project on GitHub, with more than 380K stars and a fast-growing community that’s building tools and skills across research, engineering, project management and everyday productivity.
NVIDIA, Microsoft and OpenClaw have been working together to make that experience easier to set up on Windows PCs. To reduce onboarding friction, the OpenClaw Windows App simplifies the process of setting up an optimized local model on any RTX GPU with at least 24GB of VRAM.
Learn more in the OpenClaw blog.
Inference performance is critical to keeping local agents responsive. NVIDIA is continuing to collaborate with the open-source llama.cpp and vLLM communities to accelerate agentic workloads across local NVIDIA platforms.
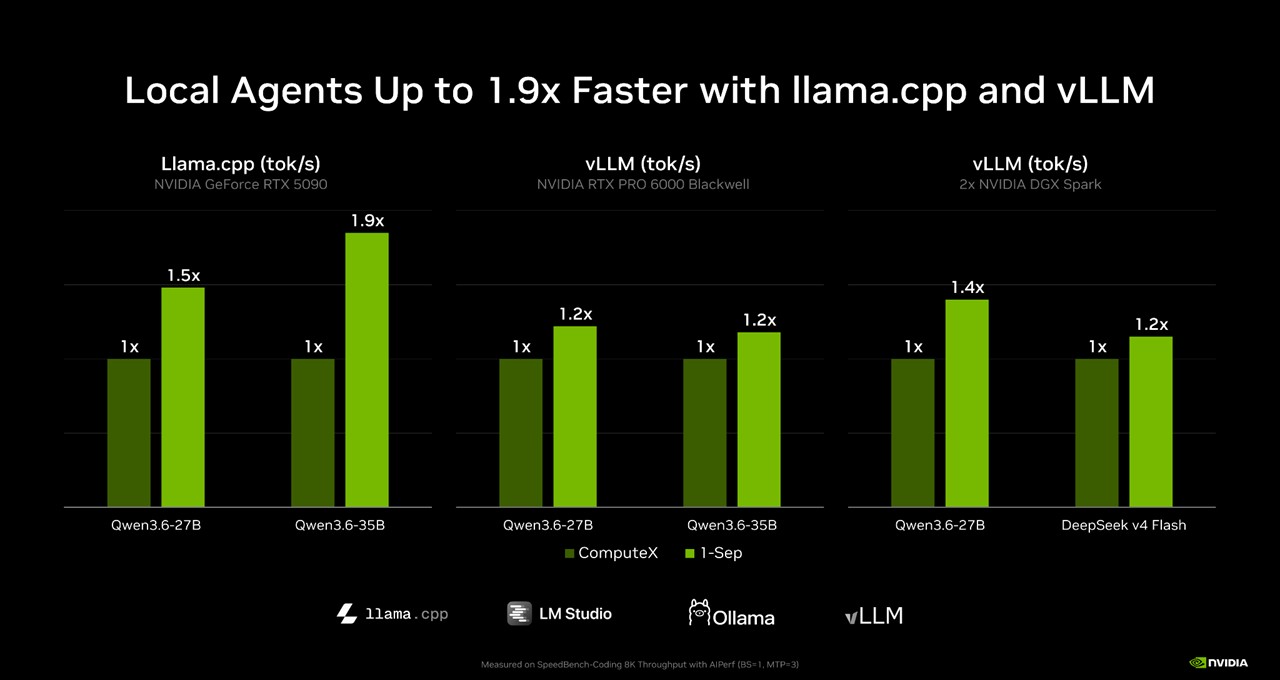
llama.cpp delivers up to 1.9x higher throughput through kernel optimizations on a GeForce RTX 5090, enhanced speculative decoding techniques and faster prefill.
vLLM delivers 1.2x on RTX PRO 6000 Blackwell Workstation Edition and up to 1.4x on two DGX Spark clusters. New XQA attention kernels in FlashInfer and backend optimizations help to accelerate inference across both platforms.
These gains are available on the llama.cpp and vLLM inferencing backends.
Users can also experience these via the LM Studio and Ollama applications.
More than half of U.S. households have two or more PCs, and much of that computing power sits idle throughout the day. NVIDIA Personal AI Router (PAIR) is a free, open source software tool that puts those systems to work together for local AI.
Agentic workflows often break complex tasks into smaller jobs that can run in parallel, but performance can slow when every request is competing for the same GPU. PAIR automatically discovers compatible PCs on a local network and routes independent inference requests to whichever system has capacity. It works with Ollama and LM Studio and can adapt as devices join or leave the network.
For example, a user could ask Hermes to create a “Sunday Reset” plan by sorting through a cluttered inbox and prioritizing what needs attention now, what can wait and what can be skipped. Hermes can split that work across multiple subagents, while PAIR distributes those jobs across available PCs instead of having them all wait on a single GPU.
The result is more compute for local agents, with more tasks running in parallel and the flexibility to move AI workloads to another PC while the main system is being used for gaming, creating or other work.
The NVIDIA PAIR beta is available for Windows, macOS and Linux through both graphical and terminal interfaces, supporting NVIDIA GeForce RTX 20 Series GPUs and newer, NVIDIA RTX PRO workstation GPUs (Turing architecture and newer), NVIDIA DGX Spark and Apple M4 or newer silicon.
Check out the NVIDIA tech blog to get started with NVIDIA PAIR.
Open image and video models enable artists to experiment with Creative AI models on PCs. This enables artists to iterate and explore concepts and ideas, without the dreaded token anxiety and keep more of their creative work private and on-device.
CyberLink’s new PhotoDirector AI PC Mode is one of the first applications to integrate these diffusion models directly into a creative software, and turn them into a creative tool at the finger tips of the artists. Coming to PhotoDirector 365 and optimized for NVIDIA RTX Spark when it launches, AI PC Mode users are getting AI-powered editing tools for generative editing, image enhancement, object and distraction removal, background removal and replacement, portrait refinement and the creation of entirely new visuals — with the flexibility to choose between local or cloud processing, depending on the task.
On NVIDIA GPUs, PhotoDirector uses TensorRT-RTX and FP8 to accelerate local AI.
Start using Cyberlink’s PhotoDirector 365 photo editing software and learn more about PhotoDirector AI PC Mode, launching with RTX Spark in October.
NVIDIA RTX Spark is coming this October— and at IFA 2026, partners are showing off their hardware. At IFA, newly announced designs join the existing six OEMs shipping in October. Acer showed its compact desktop RTX Spark concept, and Lenovo announced its Yoga Pro 9n and Yoga 9n 2-in-1.
RTX Spark is a new beginning for Windows PCs. One PC built for creators, gamers and AI agents. With a powerful 1 Petaflop RTX Blackwell GPU, up to 128GB of unified memory and a highly efficient 20-core Grace CPU, RTX Spark delivers incredible performance and efficiency. This superchip enables high performance thin laptops with all day battery life and compact desktops to power always-on agents. Paired with the new Windows Agent framework, it enables agents that run safely in the background under OS level control.
Last week at Gamescom, Electronic Arts, Embark and Ubisoft were among the latest game publishers and developers bringing their blockbuster titles to NVIDIA RTX Spark Windows PCs. They join the publishers that announced RTX Spark support at COMPUTEX in May, including KRAFTON, NetEase, Riot Games and XBOX. Read more.
Sign up to be notified when RTX Spark laptops and desktops are available.
🎮 NVIDIA Brings New RTX Tech and Games to Gamescom — NVIDIA released DLSS 4.5 Ray Reconstruction, featuring a new second-generation transformer model for improved image quality in ray-traced and path-traced games. Gamescom also brought new RTX announcements for titles including 007 First Light, CONTROL Resonant and Gears of War: E-Day, plus expanded game support for the upcoming NVIDIA RTX Spark.
🐋Introducing DeepSeek Harness — DeepSeek’s new open source harness pairs with DeepSeek-V4-Flash to power local agentic coding workflows on NVIDIA DGX Station and multi-DGX Spark setups.
📊MLPerf Client v2.0 Expands AI PC Benchmarking — MLCommons released MLPerf Client v2.0, developed in collaboration with NVIDIA and other industry leaders. The update adds new benchmarks for agentic AI and image generation, alongside expanded LLM testing for real-world local AI workloads.
Follow NVIDIA RTX Spark on X, Instagram, TikTok and Facebook — and stay informed by subscribing to the NVIDIA Local AI newsletter. Follow NVIDIA Workstation on LinkedIn and X.
See notice regarding software product information.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。