


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

WordPress大学
WordPress大学
L
LangChain Blog
酷 壳 – CoolShell
酷 壳 – CoolShell
罗磊的独立博客
J
Java Code Geeks
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
博客园 - 叶小钗
小众软件
小众软件
博客园 - Franky
D
Docker
Google DeepMind News
Microsoft Azure Blog
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
U
Unit 42
宝玉的分享
宝玉的分享
C
Check Point Blog
B
Blog
V
V2EX
博客园 - 三生石上(FineUI控件)
MyScale Blog
MyScale Blog
The Cloudflare Blog
博客园 - 聂微东
博客园_首页
Engineering at Meta
Engineering at Meta

Redis

Real-Time Fraud Detection: Latency, Features & Scale Context window in AI: why every token is a budget decision Connecting to Redis Cloud with AWS PrivateLink vs. VPC peering | Redis Redis Data Integration in Redis Cloud is now GA in AWS | Redis Why AI Misses Business Context & How Teams Fix It AI Reasoning Explained: Why Context Matters Semantic Layer vs Context Layer: Key Differences Redis array data type: How it works and when to use it Context Graphs vs. Vector Search: When RAG Falls Short What’s new in two – May 2026 edition Redis 8.8 performance improvements: Faster string, hash, streams, SCAN & more Redis 8.8: New array data structure & open source features How Conflict-free Replicated Data Types power active-active database replication Context Orchestration: What It Is & How It Works Context Compaction for AI Agents: A Complete Guide Prompt Bloat: Causes, Costs & Fixes for LLM Apps Agentic Retrieval Techniques: A Complete Guide Single-shot reliable consumers with XREADGROUP CLAIM in Redis 8.4 | Redis Long-Horizon AI Agents: Memory & State Infrastructure What is a context engine? What Is a Context Layer? AI Agent Infrastructure Context Retrieval for AI Agents: What It Is & Why It Matters Context Poisoning: How Bad Data Breaks Agent Reasoning Context Engineering for AI: What It Is & How to Build It Dynamic endpoints: Migrate databases without changing your endpoint | Redis AI Shopping Assistants: How They Work & What to Build Endless Aisle Retail: Infrastructure & Real-Time Data LLM Speed Benchmarks: Metrics & Infrastructure Guide Context Pruning: Cut LLM Tokens Without Losing Quality What’s new in two – April 2026 edition
Context is all you need: Introducing Redis Iris | Redis
Redis · 2026-05-16 · via Redis

Agents don’t have an intelligence problem. They have a context problem. They fail because their context layer is scattered, stale, slow, or hard to use.

That’s why we’re introducing Redis Iris, our new context and memory solution that turns fragmented enterprise data into live, agent-ready context. Redis Iris is a context engine, an important layer in an AI stack that sits between an agent and the data it needs to act, feeding the right context, in the right form, at the right time.

Iris is composed of five tools, Redis Context Retriever, Redis Agent Memory, Redis Data Integration, Redis LangCache, and Redis Search. Two of these are brand new to Redis. Context Retriever makes external data sources navigable by agents. Agent Memory preserves short- and long-term context across tasks and agents.

It’s all built on top of Redis, storing and serving the underlying vector, structured, unstructured, and real-time data that scales alongside your agent fleets.

Why a context engine?

For customer support bot, the answer to “Why is my order late?” may be spread across a customer database, an order system, a shipping provider, a ticketing tool, and a policy document. Without a context engine, the bot either gives a generic answer or relies on brittle, one-off integrations that expose a lot of low-level complexity.

A context engine creates a governed, agent-readable view of the data it needs to answer that question. In this example, it would define business entities like customers, orders, shipments, tickets, and policies, as well as the relationships and access rules between them. The bot can then retrieve the right customer, order, shipment status, policy, and prior interaction in one flow. The result is an agent that answers using the customer’s actual situation, not just static documentation.

The hardest problems in production AI are no longer solved by model choice. They show up at runtime: stale state, slow retrieval, fragmented memory, disconnected tools, and sessions that fail to compound. A context engine gives agents fast, reliable access to the operational data and memory they need while they’re working.

For agents to function at scale, a context engine has to meet four requirements:

  • Context that is navigable by agents. Agents need a way to traverse relationships, understand entities, discover relevant context, and access it through consistent interfaces. They should be able to move from an account to its opportunities, from a support interaction to the underlying customer state, and from a document to the systems and workflows it references. That’s the difference between raw retrieval and agent-native context.
  • Context that is retrievable quickly. Production systems can’t tolerate slow retrieval. Latency hits UX, workflow completion time, throughput, and cost. Even the best context model is useless if agents can’t access it at production speed. Fast retrieval is what makes the rest of the system work.
  • Context that is always up to date. A business’s context is always changing. CRM records update, warehouse tables refresh, new files land in object storage, transactions arrive, and app state evolves in real time. A context engine has to reflect those changes continuously—not through brittle batch-only workflows. Agents need to trust that the context they’re using reflects the current state of the business.
  • Context that gets better over time. Context should not just be current. It should compound. As the system is used, it should become more personalized, more relevant, and more informed by prior interactions and durable state. That means the context layer must support memory, learning, and accumulation over time. That’s how a retrieval layer becomes a context layer that keeps improving.

Redis Iris, an end-to-end context engine

Redis is already in the agent runtime, used by 43% of enterprise AI agent stacks to serve the hot operational state agents need. We combine sub-millisecond performance, memory, and retrieval in one package so agents can meet real production demands like voice turn-taking, fraud scoring, and customer experiences that carry across sessions.

Because Redis is multi-cloud, BYOC, and works across any agent platforms, teams get the context layer they need without turning their AI strategy into a hyperscaler lock-in decision.

Redis Iris combines five tools, rolled up into a single runtime that makes context navigable, current, fast, and better over time.
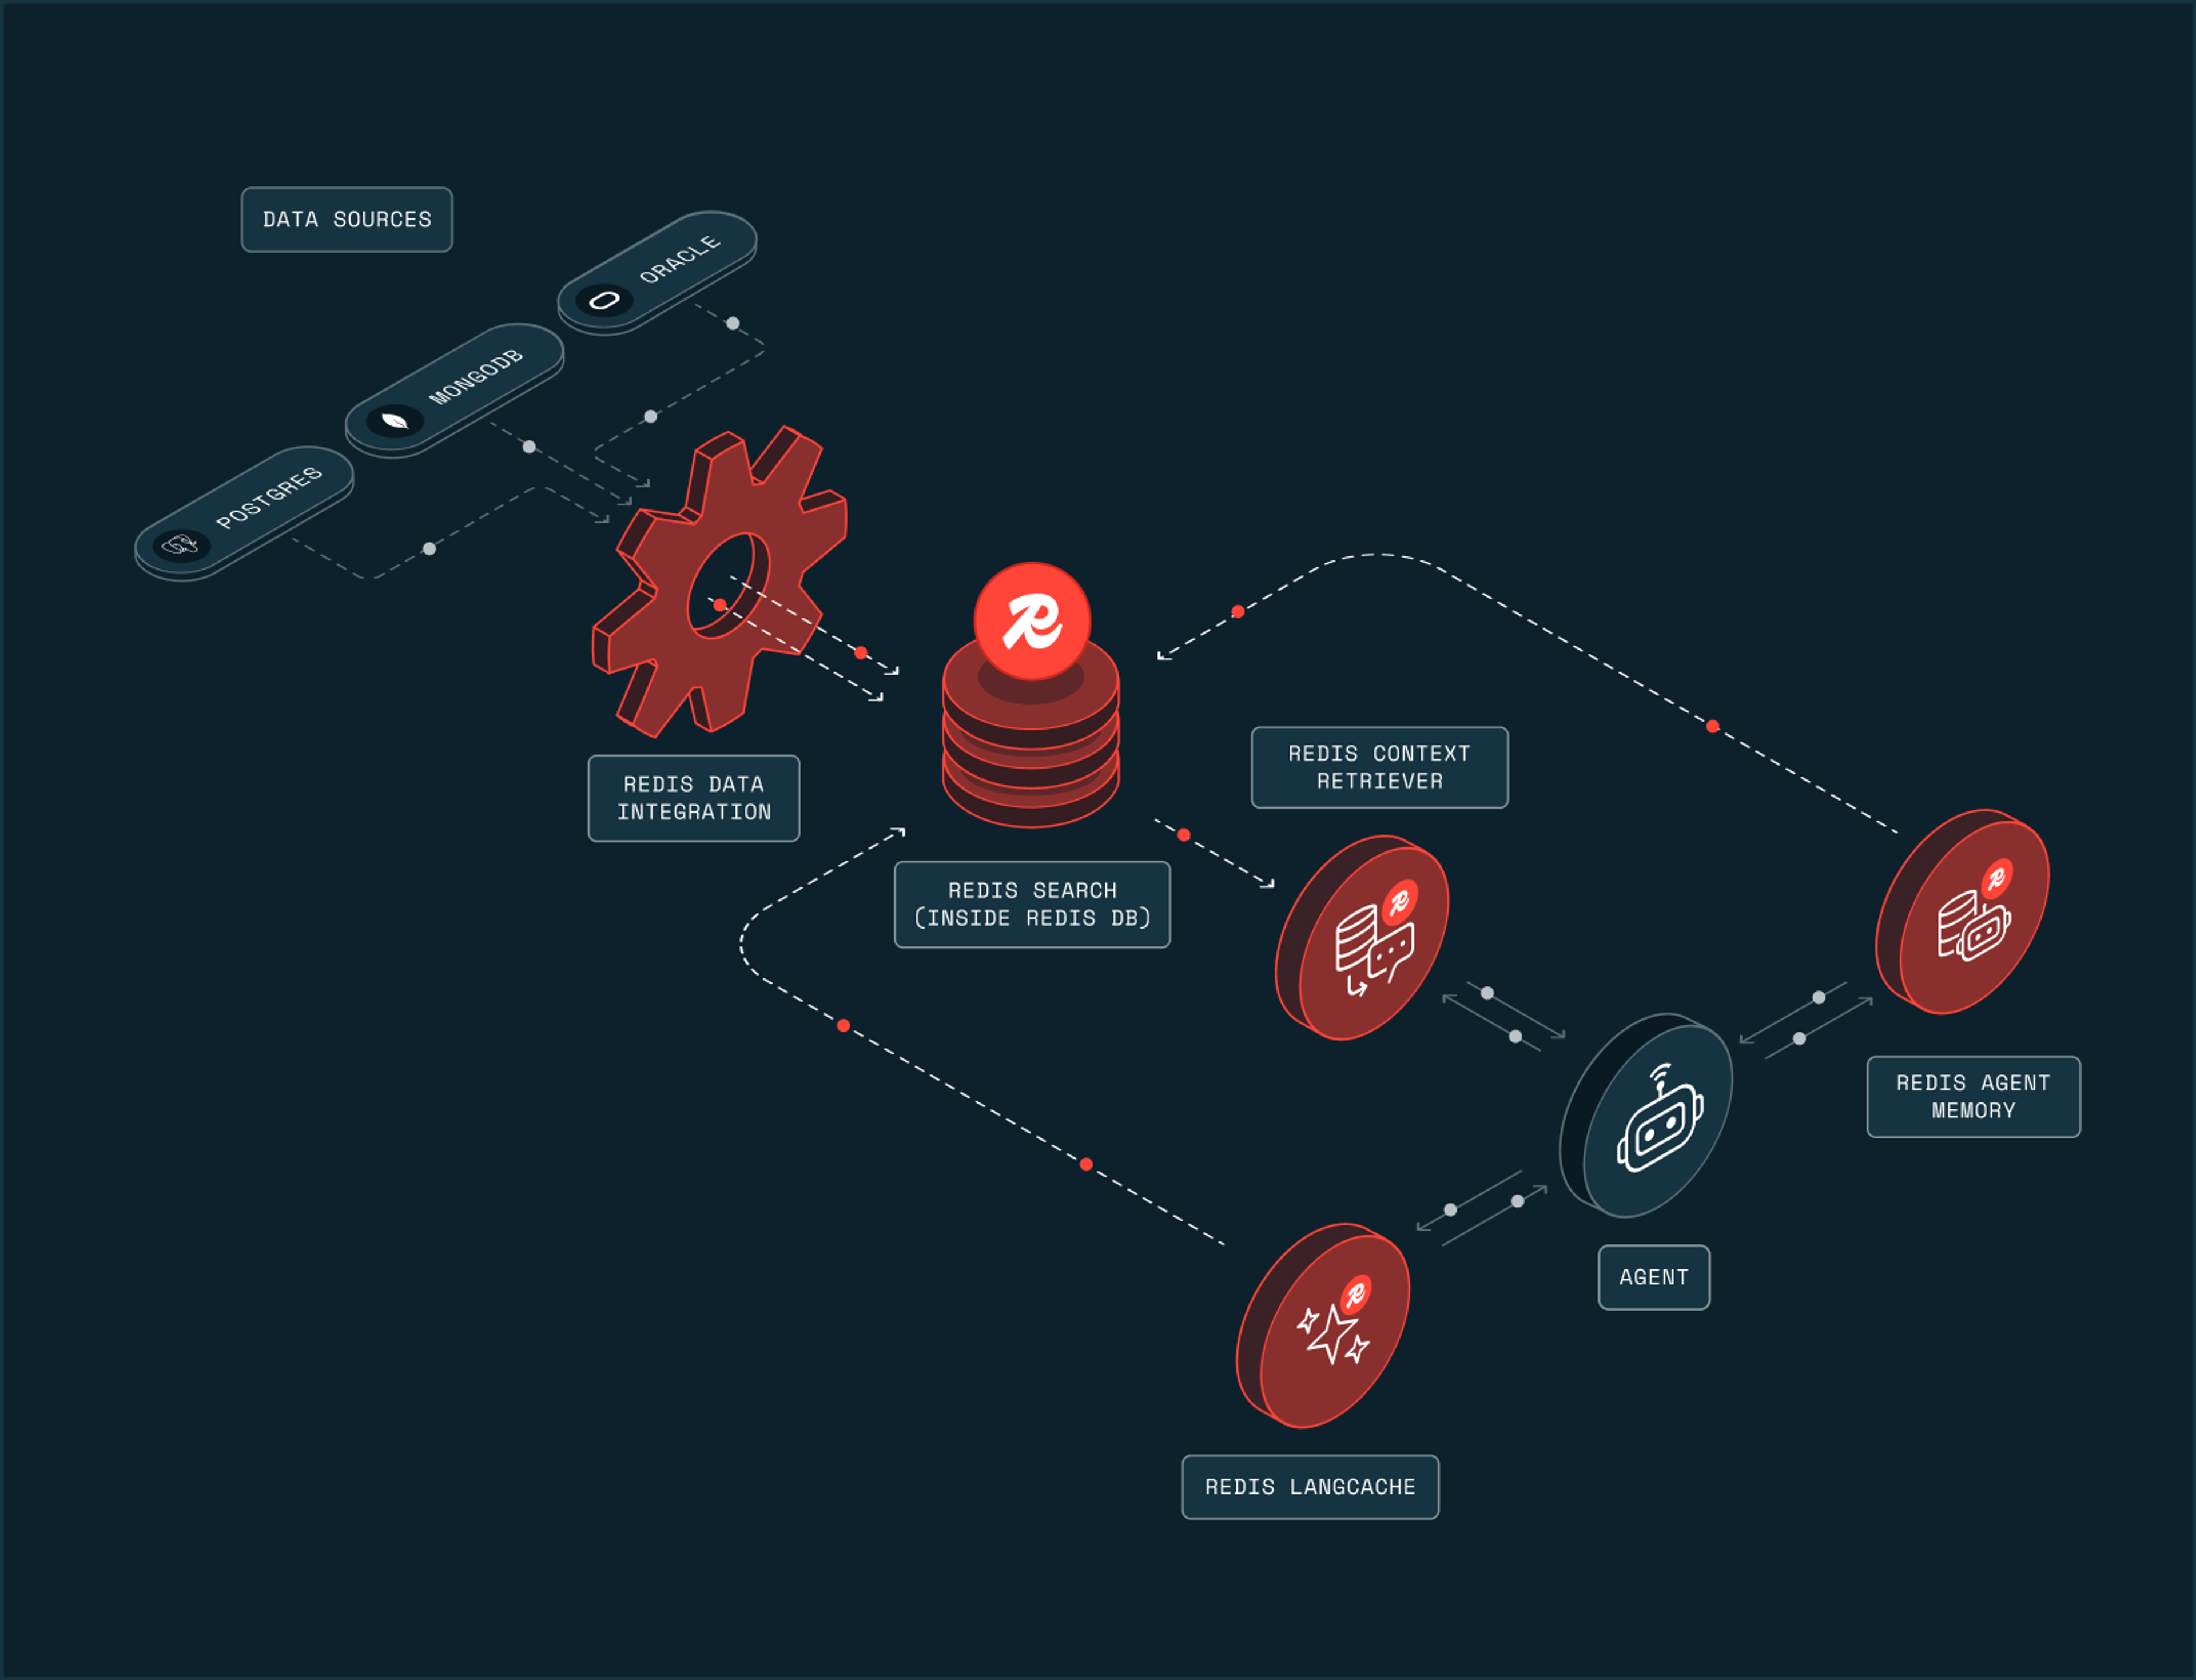
  • Context Retriever lets devs define a semantic model for business data—entities, fields, relationships, and access rules—and then auto-generates MCP tools agents can use instead of querying databases directly. At runtime, agents authenticate with scoped keys, discover only the tools they’re allowed to use, and execute indexed lookups through Redis and Redis Search, with row-level filters enforced server-side. It gives agents a controlled retrieval layer over structured business data, instead of relying on text-to-SQL or custom integrations for every workflow. Now available in preview.
  • Agent Memory manages short-term conversational state and longer-term durable memory for agent apps. It stores, updates, and retrieves context like recent interaction history, user preferences, and other persisted attributes in Redis so agents can maintain state across turns and sessions without reloading or re-deriving that information every time. Now available in preview.
  • Redis Data Integration ingests and synchronizes data from source systems like relational databases, data warehouses, and document stores into Redis. That data is stored in Redis in formats optimized for agent access, creating a continuously updated operational data plane that separates systems of record from agent-facing retrieval and serves context in real time.
  • LangCache provides low-latency semantic caching to shorten response time, and save up to 90 percent on token costs.
  • Redis Search the fast layer underneath the context engine that retrieves a company’s vector, structured, unstructured, and real-time data

Redis Iris

Try Redis Iris today

If you’re already building real-time agents, you don’t need another vendor in your stack. You need a better runtime layer for the one you already have.

Redis Iris extends the Redis infrastructure teams already know and trust, bringing navigable retrieval, fresh operational state, compounding memory, and fast semantic search into one engine instead of spreading them across a tool zoo of vector databases, memory services, streaming pipelines, caches, and custom glue.

That means agents can work with the context they need while they’re actually running. They can navigate business entities through a schema instead of gambling on text-to-SQL. They can retrieve fresh state without forcing teams to own another ETL pipeline. They can carry memory across sessions and channels. And they can stay inside the latency budgets that matter for voice, fraud, personalization, and customer experience.

The payoff: simpler agent architecture, fewer seams to debug, and agents that get faster, more reliable, and more useful in production.

The easiest way to see the difference is to try it. Use your existing Redis Cloud account to start adding context capabilities to your agent stack, or create a new Redis Cloud account for free.

Start with the Redis you already know, now built to scale with your agents.