

惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

云风的 BLOG
云风的 BLOG
V
Visual Studio Blog
人人都是产品经理
人人都是产品经理
The GitHub Blog
The GitHub Blog
月光博客
月光博客
T
Tailwind CSS Blog
小众软件
小众软件
Y
Y Combinator Blog
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
P
Proofpoint News Feed
B
Blog RSS Feed
博客园 - 司徒正美
A
About on SuperTechFans
Cyber Security Advisories - MS-ISAC
博客园 - 聂微东
Microsoft Security Blog
Recent Announcements
博客园 - Franky
U
Unit 42
奇客Solidot–传递最新科技情报
奇客Solidot–传递最新科技情报
Microsoft Azure Blog
T
The Blog of Author Tim Ferriss
GbyAI
GbyAI
Apple Machine Learning Research

Runpod Blog.

New Runpod datacenter now live: AP-IN-1 Track GPU spend across your team with Cost Centers The GPU supply supercycle is here. Here’s what AI builders need to know. Community Spotlight: One-click AI image and video generation on Runpod with SwarmUI | Runpod Blog Community Spotlight: LoRA Pilot Data Prep to Inference Introducing the Runpod Assistant: Manage Your Cloud GPU Resources with Natural Language OpenAI's Parameter Golf: Train the Best Language Model That Fits in 16MB on Runpod LLM inference optimization: techniques that actually reduce latency and cost Pruna P-Video and Vidu Q3 public endpoints now available on Runpod Runpod brand spelling guide Quickstart - Runpod Documentation The AI market looks nothing like the narrative Training StyleGAN3 with Vision-Aided GAN on Runpod KoboldAI – The Other Roleplay Front End, And Why You May Want to Use It How to Connect Cursor to LLM Pods on Runpod for Seamless AI Dev Community Spotlight: How AnonAI Scaled Its Private Chatbot Platform with Runpod Prompt Scheduling with Disco Diffusion on Runpod Runpod's Latest Innovation: Dockerless CLI for Streamlined AI Development Run Your Own AI from Your iPhone Using Runpod Introducing Flash: Run GPU workloads on Runpod Serverless: No Docker required Use Claude Code with your own model on Runpod: No Anthropic account required Avoid Errors by Selecting the Proper Resources for Your Pod What hackers built on Runpod at TreeHacks 2026 Easily Back Up and Restore Your Pod with Cloud Sync + Backblaze B2 The Complete Guide to GPU Requirements for LLM Fine-Tuning AI Guides, Tutorials & GPU Infrastructure Insights | Runpod Your first Claude Code project within Runpod: a complete setup guide 10 billion Serverless requests and counting Building for resilience: Runpod’s response to the AWS us-east-1 outage How to Connect Google Colab to Runpod
What’s New for Serverless LLM Usage in Runpod (2025 Update)
Brendan McKeag · 2025-01-10 · via Runpod Blog.

Out of all of the use cases that our serverless architecture has, LLMs are one of the best examples of it. Because so much of LLM use is dependent on the human using it to process, digest, and type a response, you save so much on GPU spend by ensuring that you only pay for the inference time rather than an entire pod – why continue to spend for GPU time when it's just going to sit idle? Not only that, but serverless allows you to scale seamlessly up to spikes in demand with a minimum of fuss. We are leaning hard into serverless and want to share what we've created with you.

Newly Released Features

We've cooked up a bunch of improvements designed to reduce friction and make the platform easier to use. Here's a roundup of what's come out over the last few months:

Increased 80GB GPUs per Worker to 4

Without support involvement, you can now create workers with up to four GPUs for 80GB and 80GB Pro specs, up from two. This will give you up to 320GB to play with, which should be enough for most LLM use cases, except for Deepseek v3 and some higher bit quantizations of other large models. If you require more than 320GB, feel free to contact our friendly support team for an increase so you can get up to eight 80GB GPUs in your endpoint.

You can make the edits under the Edit Endpoint screen under GPU Count:
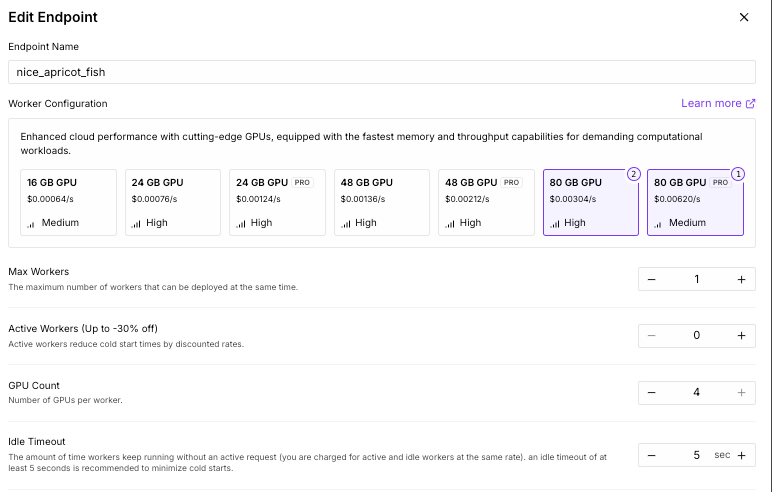
Runpod Edit Endpoint form with GPU memory tiers, per-second pricing, max workers, GPU count, and idle timeout

Serverless SGLang Quick Deploy Endpoint

The Quick Deploy for VLLM doesn't look quite so lonely anymore with an SGLang option next to it.
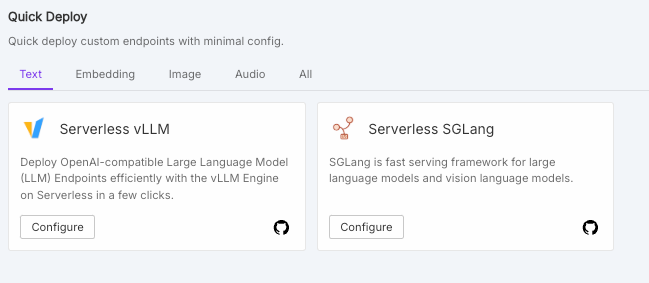
Runpod Quick Deploy page with Serverless vLLM and Serverless SGLang options

SGLang is a specialized framework focused on structured generation and control flow, with features like:

  • Built-in support for complex prompting patterns and structured outputs
  • Python-native control flow integration
  • Optimization for instruction-following and function calling scenarios
  • Generally simpler to get started with for Python developers

vLLM emphasizes high-performance inference with features like:

  • PagedAttention memory management for efficient batch processing
  • Strong support for continuous batching
  • KV cache management optimizations
  • Better suited for high-throughput production deployment scenarios
  • More mature ecosystem integration with popular serving frameworks

The choice between them often depends on your specific needs. If you're primarily doing structured generation with complex control flows in Python, SGLang's native integration might be more convenient. If you're optimizing for maximum throughput in production, vLLM's performance optimizations could be more valuable.

We've written about SGLang and vLLM in the past if you've like to read more.

Improved Model Selection Screen

When deploying an endpoint, you can select a model from a list to pull straight from Huggingface, or enter the path for your preferred model to have it pulled instead - no more fiddling with environment variables if you'd rather not.
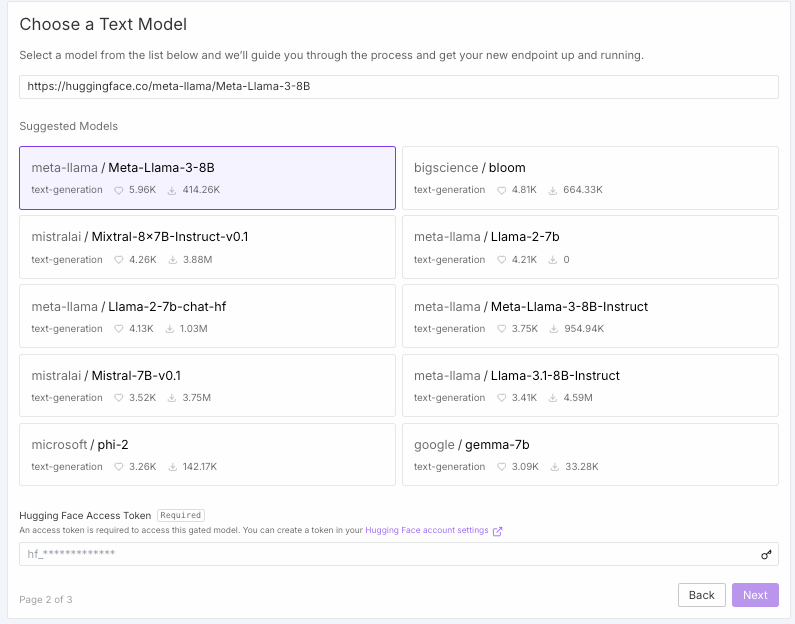
Choose a Text Model screen listing Hugging Face models with Meta-Llama-3-8B selected and an access token field

Deploy Repos Straight to Runpod with GitHub Integration

Want to bring your own inference engine instead? If it's in a GitHub repo, you can just bring it straight in with our new integration. Docker deploy isn't going anywhere, of course, but deploying straight from GitHub could save an enormous amount of middleman effort from having to bake and upload your own image.
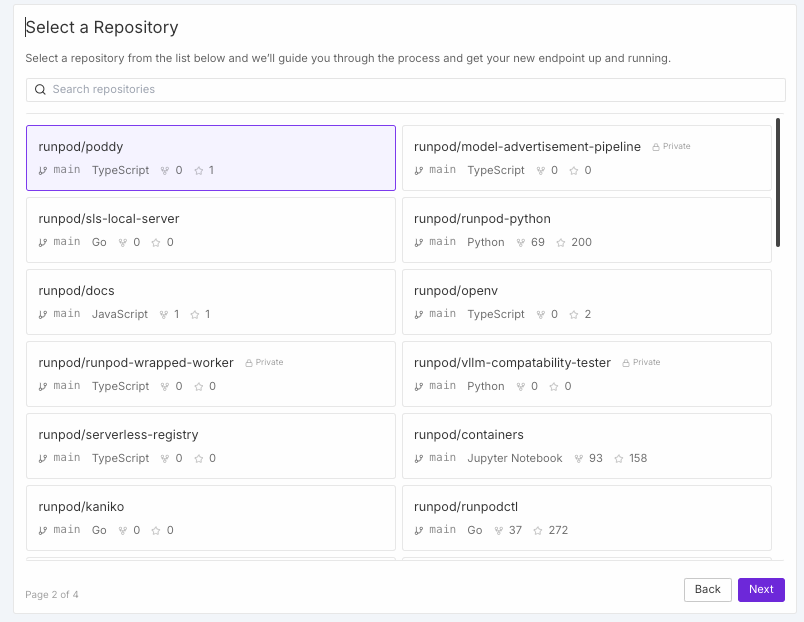
Select a Repository screen listing Runpod GitHub repos such as Runpod-python and Runpodctl

Create a Serverless Endpoint Today

On the Horizon

We're not done yet - we've got several more features working its way through the pipeline to make deploying serverless endpoints faster and easier to help support your team. Have any questions on how to use any of these features? Check out our Discord or drop us a line!

Author profile: Brendan McKeag