


by Florian Pellet on Nov 18, 2025.
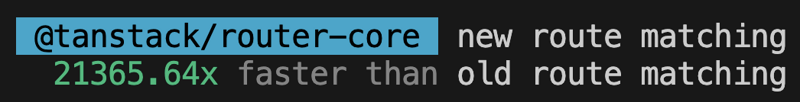
We achieved a 20,000× performance improvement in route matching in TanStack Router. Let's be honest, this is definitely cherry-picked, but the number is real and comes from a real production application. More importantly, it shows that matching a pathname to a route is no longer bottlenecked by the number of routes in your application.
One big responsibility of a router is to match a given URL pathname (e.g., /users/123) to a route definition (e.g., /users/$userId). This is deceptively complex when you consider all the different types of route segments (static, dynamic, optional, wildcard) and the priority rules that govern which route should match first.
Our previous route matching algorithm was based on a sorted flat list of all routes, iterating through each to find a match. As we added more features like optional segments and wildcards, the algorithm became increasingly complex and slow, and we started receiving reports of incorrect matches. Our sorting did not adhere to a strict weak ordering, the sorting logic was not well-defined and even behaved differently between Chrome and Firefox.
We opted for a complete rewrite.
We now parse the route tree into a segment trie, and matching is done by traversing this trie. This makes it much simpler to implement exact matching rules while ensuring high performance.
A trie (wikipedia) is a tree structure where each node corresponds to the common string prefix shared by all of the node's children. The concept maps very well to a representation of the routes in an app, where each node is a URL pathname segment.
Given a single route /users/$id, our segment trie would look like this:
Adding more routes gives a more complete picture:
This yields the following tree:
To match /users/123, we:
The reason we can get such a massive performance boost is because we changed which variable drives the complexity of the algorithm. The bigger the route tree, the bigger the performance gain.
(This is simplified, in practice it's more like O(N * M) vs. O(M * log(N)) in the average case, but the point is that we changed which variable dominates the complexity.)
Using this new tree structure, each check eliminates a large number of possible routes, allowing us to quickly zero in on the correct match.
For example, imagine we have a route tree with 450 routes (fairly large app) and the tree can only eliminate 50% of routes at each segment check (this is unusually low, it's often much higher). With this bad setup, we have found a match in 9 checks (2**9 > 450). By contrast, the old approach could have found the match on the first check, but in the worst case it would have had to check all 450 routes, which yields an average of 225 checks. Even in this simplified case, we are looking at a 25× performance improvement.
This is what makes tree structures so powerful.
In practice, we have observed:
These are lower than 20,000×, but they are still insane numbers.
Beyond choosing the right data structures, working on performance is usually about avoiding death by a thousand cuts: avoiding memory allocations, skipping work, … Here are some of the fun implementation details that helped us get to these numbers.
We use a stack to manage our traversal of the tree, because the presence of dynamic segments (/$required, /{-$optional}, /$ wildcards) means we may have multiple possible paths to explore at each segment.
The ideal algorithm would be depth-first search (DFS) in order of highest priority, so that we can return as soon as we find a match. In practice, we have very few possibilities of early exit; but a fully static path should still be able to return immediately.
To accomplish this, we use an array as the stack. We know that .push() and .pop() at the end of an array are O(1) operations, while .shift() and .unshift() from the start are O(N), and we want to avoid the latter entirely. At each segment, we iterate candidates in reverse order of priority, pushing them onto the stack. This way, when we pop from the stack, we get the highest priority candidates first.
Optional segments introduce additional complexity, as they can be present or absent in the URL. While walking the tree, we need to track which optional segments were skipped (i.e. we need an array of booleans).
Every time we push onto the stack, we need to store the "state at which to pick up from" including which optional segments were skipped. But we don't want to have to [...copy] an array of booleans every time we push onto the stack as it would create many short-lived allocations.
To avoid this overhead, we use bitmasking to represent skipped optional segments.
For example, consider a route with two optional segments: /{-$users}/{-$id}. We can represent the presence of these segments with a bitmask:
To write to the bitmask, we use bitwise operators:
And to read from the bitmask:
The downside is that this limits us to 32 segments, because in JavaScript bitwise operations cast a number into a 32-bit integer. Optional segments beyond that point will never be considered skipped. We could switch to a BigInt if needed, but for now, this feels reasonable.
When building the segment trie, we need to parse each route (e.g., /users/$userId/{-$maybe}) into its constituent segments (e.g. static:users, dynamic:userId, optional:maybe). Doing this is basically running the same parsing algorithms hundreds of times, every time extracting the same structured data (i.e. segment type, value, prefix, suffix, where the next segment starts, etc).
Instead of re-creating a new object every time, we can reuse the same object across all parsing operations to avoid allocations in the hot path.
Technically, we can push this even further by using a Uint16Array to store the data, which is more memory efficient and faster to access than object properties. And TypeScript handles this very well, so we don't need to type the buffer or even initialize it.
Because the route tree is static after initialization, a URL pathname will always yield the same match result. This makes this an ideal candidate for caching.
With a cache, we only need to do the expensive matching operation once per unique pathname. Subsequent requests for the same pathname will be served from the cache, which is O(1).
However, as we have seen before, some apps can have a very large number of unique routes, which means even more unique pathnames (e.g., route /user/$id is matched by /user/1, /user/2, etc). To prevent unbounded memory growth, we implement a Least Recently Used (LRU) cache. When the cache reaches a certain size, it automatically evicts the least recently used entries.
This data structure performs about half as well as a regular Object for writes, and on par with an Object for reads. This is a trade-off we are willing to make to avoid unbounded memory growth.

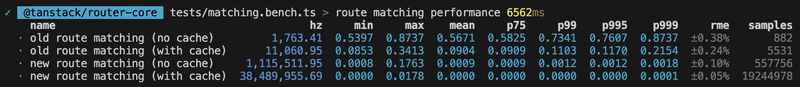
The numbers we have presented so far are impressive. They are also cherry-picked from the biggest apps we tested, which is biased in favor of the new algorithm. And they are comparisons against the old, uncached algorithm. In reality, we added caching a while ago. We can see the full progression over the last 4 months:
And besides that, they also focus on a small part of the router's performance profile. Matching a pathname to a route is only one part of the job. If we look at a more "complete" operation, for example buildLocation, which involves matching, building the location object, interpolating the path, passing the validation functions, running the middlewares, etc, we see a more modest but still significant improvement:
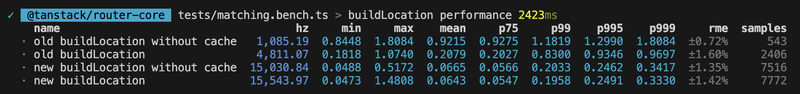
Even the smallest apps see some improvement here, but it might not feel as dramatic. We will continue to optimize the other parts of the router to make it feel as snappy as we can. The good news is route matching is no longer a bottleneck.
While we are very happy with these results (and are probably done optimizing route matching for now), there are still some avenues we could explore to push this even further:
sub-segment nodes: currently, each node in the trie represents a full URL segment (between slashes). We could further break down segments into sub-segments (e.g., prefix, dynamic part, suffix) to allow for much better branch elimination. This is what find-my-way does (the router behind Fastify), and it yields impressive results.
branch compression: we could also expand in the other direction, and have tree nodes that represent multiple segments at once, when there is no branching (usually, for a series of static segments). This would reduce the depth of the tree and the number of stack frames we need to process.
This wasn't a "let's make it faster" project, it was a "let's make it correct" project that happened to yield massive performance improvements as a side effect. We rarely see numbers this large in real benchmarks, so we hope you’ll forgive a bit of cherry-picking in this post.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。