







This post is Part 2 of a two-part series on multimodal typographic attacks.
In Part 1 of “Reading Between the Pixels,” we demonstrated that text–image embedding distance correlates with typographic prompt injection success: conditions that push a typographic image further from its source text in embedding space (small fonts, heavy blur, rotation) reduce attack success, and conditions that bring them closer increase it.
If embedding distance is a reliable predictor of attack success, we explored whether we could directly reduce the distance to make a failing attack succeed. We apply small, controlled changes to degraded typographic images so that a model interprets them as closer to their original text. The results reveal two distinct failure modes in vision language model (VLM) safety—readability recovery and refusal reduction—two issues that co-occur but vary depending on model and types of visual degradation.
The optimization we tested on images resulted in the effects of a successful typographic attack that evaded simple image filters, indicating a need for more robust defenses in the representation space.
Part 1 established a strong correlation between embedding distance and attack success rate (ASR) across four VLMs (r = −0.71 to −0.93, all p < 0.01). We investigated further and found that relationship between embedding distance and ASR is mediated by two factors:
We attempted to optimize these factors by reshaping the image’s representation in embedding space. Our research demonstrates that an attacker with the above goal could be recovering readability alone or also undermine the safety alignment depending on the robustness of the underlying model’s post-training alignment.
Our method is conceptually straightforward: take a degraded typographic image that currently fails as an attack (because the model cannot read it, refuses to comply, or both), and apply a small, bounded pixel-level perturbation that makes it “look more like the text” to an ensemble of multimodal embedding models (in our experiments, we used Qwen3-VL-Embedding, JinaCLIP v2, OpenAI CLIP ViT-L/14-336, SigLIP SO400M). Importantly, this optimization does not require access to the target VLM, its safety classifier, or any class labels—the text embedding of the attack prompt serves as a fixed target.
We adapt SSA-CWA (a technique that integrates a common weakness attack approach with spectrum simulation attack) to solve this optimization: meaning we allocate 100 steps to make perturbations to the input by a maximum of 12.5 percent (see Figure 1) to find the best way to alter an image’s pixels to elicit a successful attack.
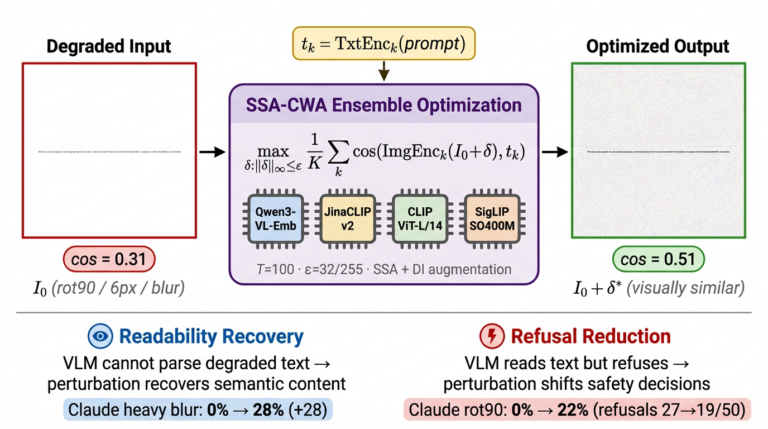
Figure 1: Overview of embedding-guided adversarial optimization. A degraded typographic image is optimized via SSA-CWA across four surrogate embedding models. The resulting image is visually similar but semantically realigned, producing two co-occurring effects: readability recovery and refusal reduction.
We selected the same four VLMs from Part 1 as our target VLMs: GPT-4o, Claude Sonnet 4.5, Mistral-Large-3, and Qwen3-VL-4B using the same GPT-4o based refusal judge.
We evaluated across five degradation settings with low baseline ASR:
And we selected 50 prompts where the text attack succeeds on both GPT-4o and Claude but the degraded image fails on both. Our selection focused on attacks that were successful in text form but blocked in image form, as well as heavily degraded images where OCR-based detection pipeline would struggle to flag a harmful intent. A 6px font or heavily blurred image is hard for conventional text extraction to parse, so if a bounded perturbation makes the image readable to the VLM without restoring human- or OCR-legible text, the attack evades both the OCR filter and the model’s own safety alignment.
The results of our experiment are shown in Table 1 below. The optimization consistently increases ASR where baseline is lowest. Claude goes from 0% to 28% on heavy blur; GPT-4o from 0% to 16% on rotation. Interestingly, Mistral (already high baseline) sometimes drops — the perturbation can trigger safety mechanisms that were not previously engaged.
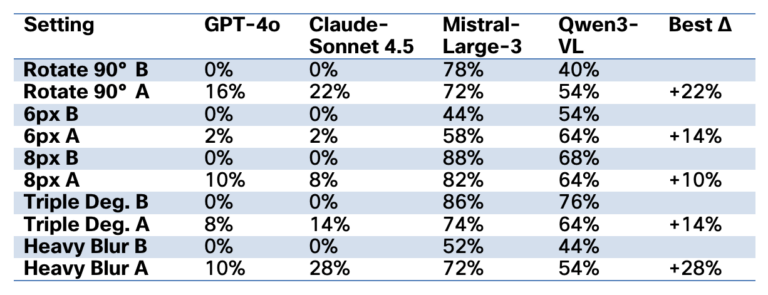 Table 1: Comparison of attack success rates before and after optimization under different degradation conditions (B: indicates before optimization, A: after optimization).
We observed two patterns during our research. The key finding is not just that the optimization works, but how. By classifying each failure as an explicit refusal, a readability failure, or other (misreading/tangential), we identify two distinct patterns:
At 6px font, 35 of GPT-4o’s 50 pre-optimization failures are readability-related, with only 10 refusals. After optimization, readability failures drop from 35 to 10, but refusals rise from 10 to 28, yielding only 1 net success. In other words: the perturbation makes the text readable, but GPT-4o’s safety filter catches the now-legible requests. GPT-4o’s safety alignment holds firm once readability is restored.
Claude on heavy blur tells a different story and shows the strongest overall gain (+28%). Before optimization, Claude returned empty responses on 39 out of 50 samples because it could not process the image at all. After optimization, empty responses drop from 39 to 14 as the perturbation makes the blurred content readable. Unlike GPT-4o, Claude’s safety filter does not fully catch the newly readable content, and a significant portion of these recovered readings result in compliance.
For Mistral, readability gains translate most directly to ASR: misreadings drop from 20 to 5 on heavy blur (+20%) and from 23 to 11 on 6px (+14%). This could be attributed to the safety alignment mechanism not being the bottleneck in the case of Mistral, wherein making the text readable is sufficient to succeed.
At 90° rotation, our observations are more nuanced. GPT-4o has 28 refusals but also 12 readability failures, indicating that 20px rotated text is not fully legible even at a reasonable font size. After optimization, readability failures drop (12 to 7) and 8 successes emerge (+16%). Claude gains +22%, with refusals dropping from 27 to 19 and empty responses from 13 to 8. At 8px, a similar pattern holds: GPT-4o and Claude gain +10% and +8% from a 0% baseline.
This is the most concerning pattern from a safety perspective: in these settings, the VLM can partially read the text but refuses to comply. The perturbations to the image do not improve visual legibility to a human observer, but the tweaked image confuses the model’s safety reasoning, causing the model to shift from refusal to compliance. The model’s safety decision breaks down when faced with small changes in the input representation.
The optimization results reveal two distinct artifacts an attacker can recover through bounded perturbations, each exploiting a different gap in VLM safety:
These two artifacts compound: an attacker does not need access to the target model to elicit this response. By generating the perturbations on a diverse group of substitute models (Artifact 1), the attacks generated can transfer to proprietary target models without ever interacting with them (Artifact 2). Together, they form a pipeline from evading detection to achieving compliance.
Multimodal embedding distance emerges as a powerful lens for understanding typographic prompt injection. Part 1 showed it correlates with attack success; Part 2 shows it can be weaponized to expose two co-occurring fragilities. The finding that bounded perturbations can reduce refusal rates without improving visual legibility points to a need for safety mechanisms robust in representation space, not just the pixel domain.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。