Alibaba’s Tongyi Lab Releases VimRAG: a Multimodal RAG Fr...
2026-04-10·via MarkTechPost
Retrieval-Augmented Generation (RAG) has become a standard technique for grounding large language models in external knowledge — but the moment you move beyond plain text and start mixing in images and videos, the whole approach starts to buckle. Visual data is token-heavy, semantically sparse relative to a specific query, and grows unwieldy fast during multi-step reasoning. Researchers at Tongyi Lab, Alibaba Group introduced ‘VimRAG’, a framework built specifically to address that breakdown.
The problem: linear history and compressed memory both fail with visual data
Most RAG agents today follow a Thought-Action-Observation loop — sometimes called ReAct — where the agent appends its full interaction history into a single growing context. Formally, at step t the history is Ht = [q, τ1, a1, o1, …, τt-1, at-1, ot-1]. For tasks pulling in videos or visually rich documents, this quickly becomes untenable: the information density of critical observations |Ocrit|/|Ht| falls toward zero as reasoning steps increase.
The natural response is memory-based compression, where the agent iteratively summarizes past observations into a compact state mt. This keeps density stable at |Ocrit|/|mt| ≈ C, but introduces Markovian blindness — the agent loses track of what it has already queried, leading to repetitive searches in multi-hop scenarios. In a pilot study comparing ReAct, iterative summarization, and graph-based memory using Qwen3VL-30B-A3B-Instruct on a video corpus, summarization-based agents suffered from state blindness just as much as ReAct, while graph-based memory significantly reduced redundant search actions.
A second pilot study tested four cross-modality memory strategies. Pre-captioning (text → text) uses only 0.9k tokens but reaches just 14.5% on image tasks and 17.2% on video tasks. Storing raw visual tokens uses 15.8k tokens and achieves 45.6% and 30.4% — noise overwhelms signal. Context-aware captioning compresses to text and improves to 52.8% and 39.5%, but loses fine-grained detail needed for verification. Selectively retaining only relevant vision tokens — Semantically-Related Visual Memory — uses 2.7k tokens and reaches 58.2% and 43.7%, the best trade-off. A third pilot study on credit assignment found that in positive trajectories (reward = 1), roughly 80% of steps contain noise that would incorrectly receive positive gradient signal under standard outcome-based RL, and that removing redundant steps from negative trajectories recovered performance entirely. These three findings directly motivate VimRAG’s three core components.
https://arxiv.org/pdf/2602.12735v1
VimRAG’s three-part architecture
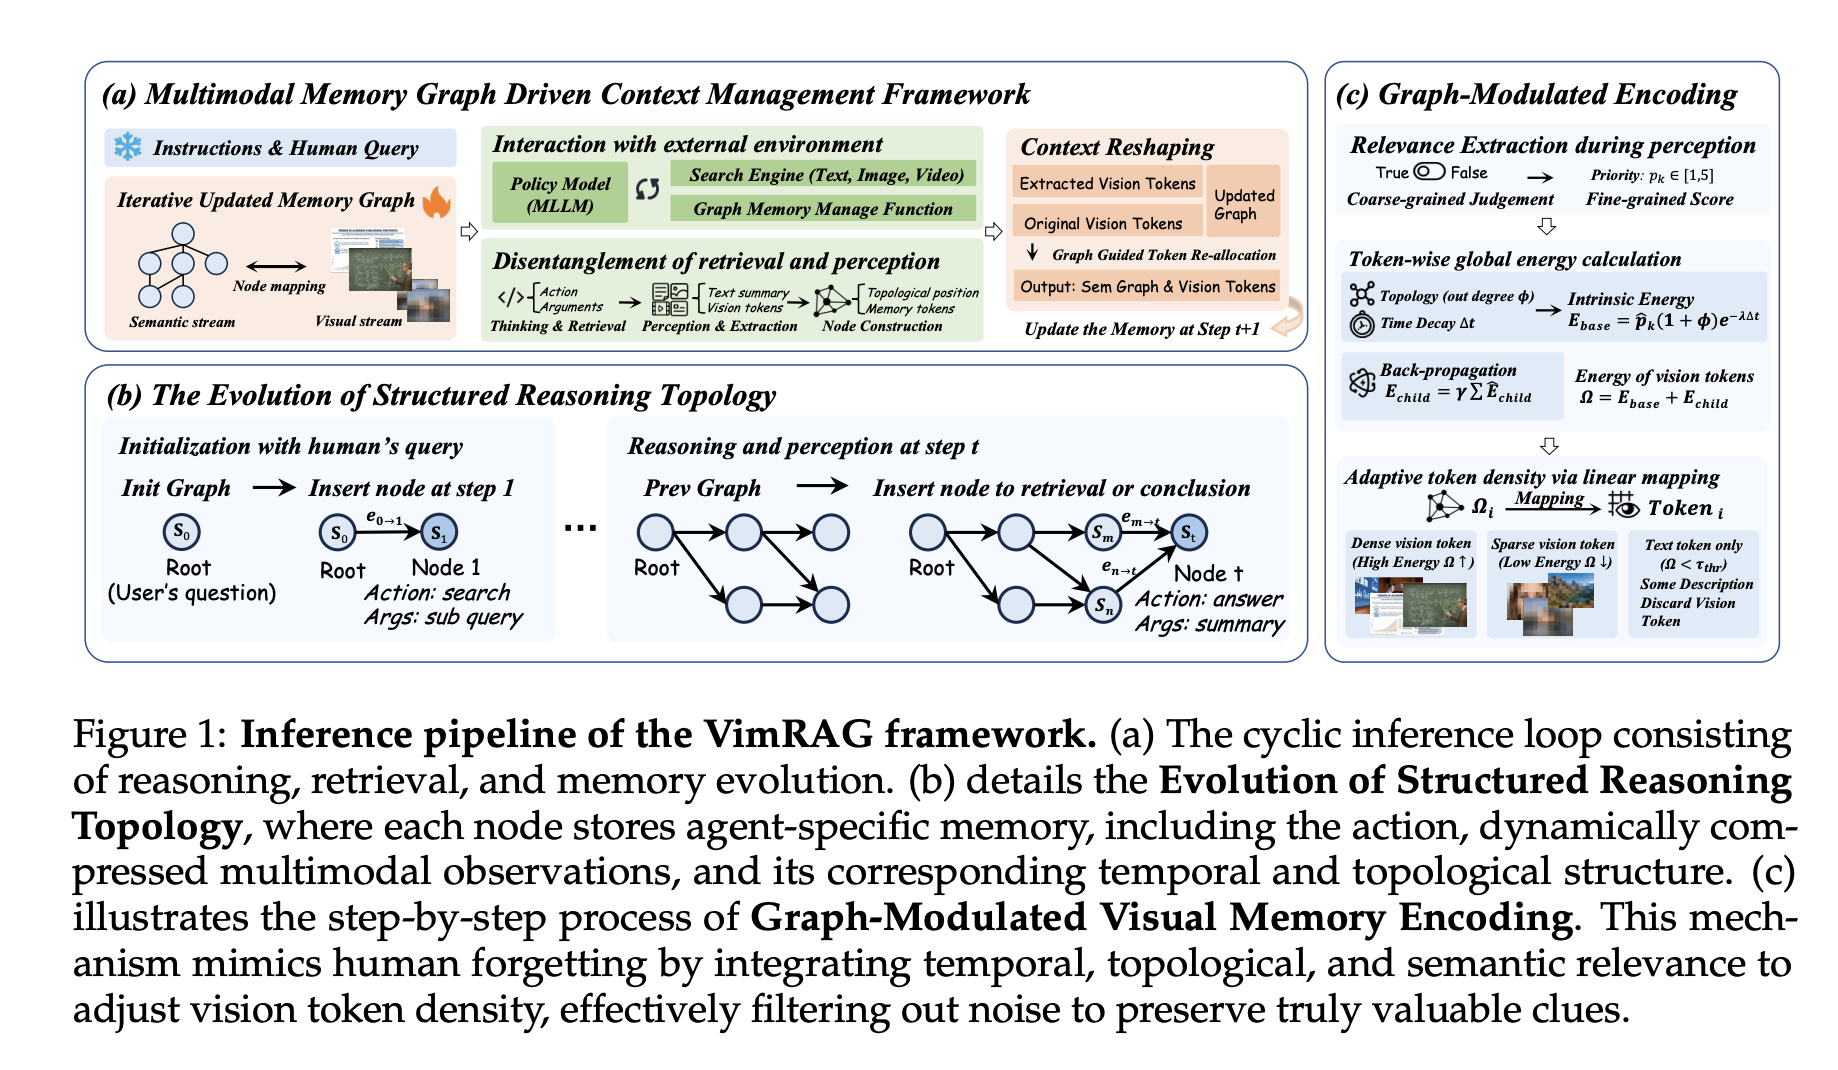
The first component is the Multimodal Memory Graph. Rather than a flat history or compressed summary, the reasoning process is modeled as a dynamic directed acyclic graph Gt(Vt, Et) Each node vi encodes a tuple (pi, qi, si, mi): parent node indices encoding local dependency structure, a decomposed sub-query associated with the search action, a concise textual summary, and a multimodal episodic memory bank of visual tokens from retrieved documents or frames. At each step the policy samples from three action types: aret (exploratory retrieval, spawning a new node and executing a sub-query), amem (multimodal perception and memory population, distilling raw observations into a summary st and visual tokens mt using a coarse-to-fine binary saliency mask u ∈ {0,1} and a fine-grained semantic score p ∈ [1,5]), and aans (terminal projection, executed when the graph contains sufficient evidence). For video observations, amem leverages the temporal grounding capability of Qwen3-VL to extract keyframes aligned with timestamps before populating the node.
The second component is Graph-Modulated Visual Memory Encoding, which treats token assignment as a constrained resource allocation problem. For each visual item mi,k, intrinsic energy is computed as Eint(mi,k) = p̂i,k · (1 + deg+G(vi)) · exp(−λ(T − ti)), combining semantic priority, node out-degree for structural relevance, and temporal decay to discount older evidence. Final energy adds recursive reinforcement from successor nodes: , preserving foundational early nodes that support high-value downstream reasoning. Token budgets are allocated proportionally to energy scores across a global top-K selection, with a total resource budget of Stotal = 5 × 256 × 32 × 32. Dynamic allocation is enabled only during inference; training averages pixel values in the memory bank.
The third component is Graph-Guided Policy Optimization (GGPO). For positive samples (reward = 1), gradient masks are applied to dead-end nodes not on the critical path from root to answer node, preventing positive reinforcement of redundant retrieval. For negative samples (reward = 0), steps where retrieval results contain relevant information are excluded from the negative policy gradient update. The binary pruning mask is defined as . Ablation confirms this produces faster convergence and more stable reward curves than baseline GSPO without pruning.
Results and availability
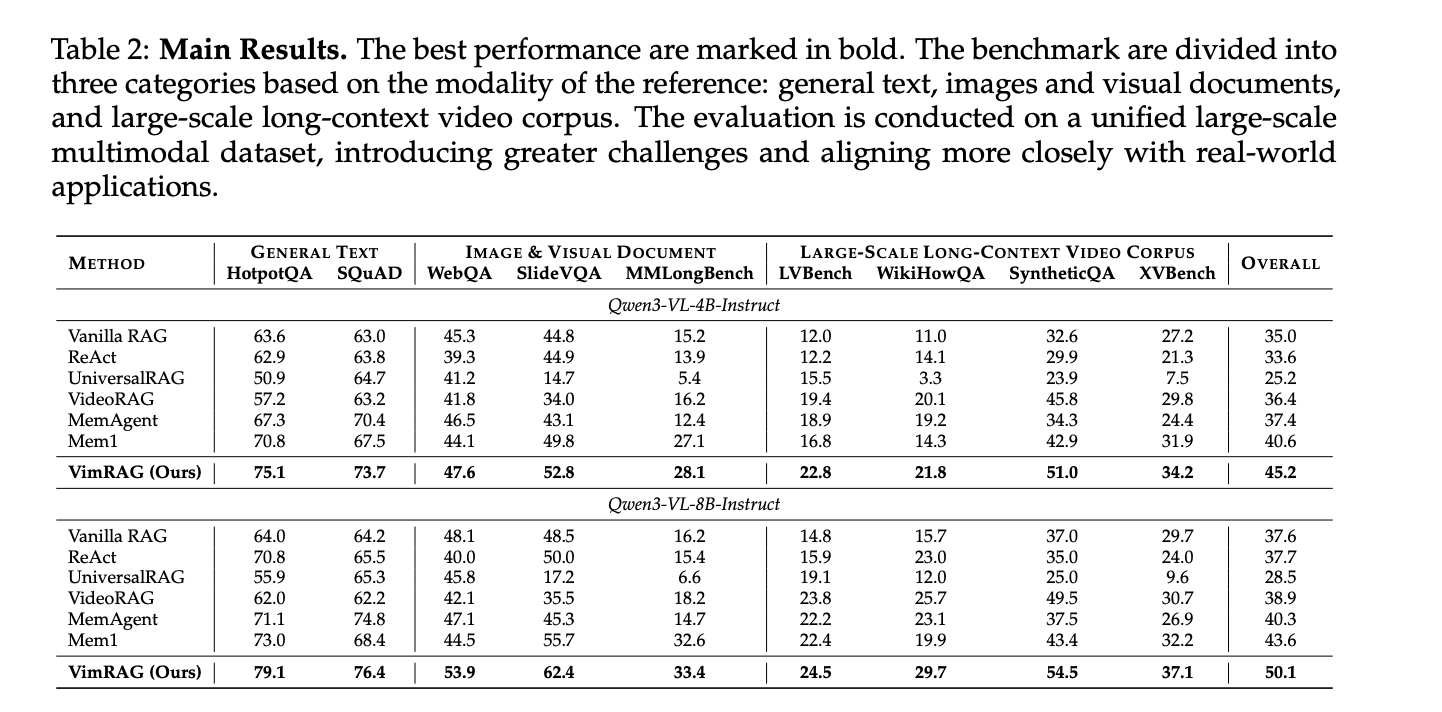
VimRAG was evaluated across nine benchmarks — HotpotQA, SQuAD, WebQA, SlideVQA, MMLongBench, LVBench, WikiHowQA, SyntheticQA, and XVBench, a new cross-video benchmark the research team constructed from HowTo100M to address the lack of evaluation standards for cross-video understanding. All nine datasets were merged into a single unified corpus of approximately 200k interleaved multimodal items, making the evaluation harder and more representative of real-world conditions. GVE-7B served as the embedding model supporting text-to-text, image, and video retrieval.
On Qwen3-VL-8B-Instruct, VimRAG achieves an overall score of 50.1 versus 43.6 for Mem1, the prior best baseline. On Qwen3-VL-4B-Instruct, VimRAG scores 45.2 against Mem1’s 40.6. On SlideVQA with the 8B backbone, VimRAG reaches 62.4 versus 55.7; on SyntheticQA, 54.5 versus 43.4. Despite introducing a dedicated perception step, VimRAG also reduces total trajectory length compared to ReAct and Mem1, because structured memory prevents the repetitive re-reading and invalid searches that cause linear methods to accumulate a heavy tail of token usage.
https://arxiv.org/pdf/2602.12735v1
Key Takeaways
VimRAG replaces linear interaction history with a dynamic directed acyclic graph (Multimodal Memory Graph) that tracks the agent’s reasoning state across steps, preventing the repetitive queries and state blindness that plague standard ReAct and summarization-based RAG agents when handling large volumes of visual data.
Graph-Modulated Visual Memory Encoding solves the visual token budget problem by dynamically allocating high-resolution tokens to the most important retrieved evidence based on semantic relevance, topological position in the graph, and temporal decay — rather than treating all retrieved images and video frames at uniform resolution.
Graph-Guided Policy Optimization (GGPO) fixes a fundamental flaw in how agentic RAG models are trained — standard outcome-based rewards incorrectly penalize good retrieval steps in failed trajectories and incorrectly reward redundant steps in successful ones. GGPO uses the graph structure to mask those misleading gradients at the step level.
A pilot study using four cross-modality memory strategies showed that selectively retaining relevant vision tokens (Semantically-Related Visual Memory) achieves the best accuracy-efficiency trade-off, reaching 58.2% on image tasks and 43.7% on video tasks with only 2.7k average tokens — outperforming both raw visual storage and text-only compression approaches.
VimRAG outperforms all baselines across nine benchmarks on a unified corpus of approximately 200k interleaved text, image, and video items, scoring 50.1 overall on Qwen3-VL-8B-Instruct versus 43.6 for the prior best baseline Mem1, while also reducing total inference trajectory length despite adding a dedicated multimodal perception step.
Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.