


This article is also available in Chinese 简体中文.
If you're working on data-intensive research or machine learning projects, you need a reliable way to share and host your datasets. Public datasets such as Common Crawl, ImageNet, Common Voice and more are critical to the open ML ecosystem, yet they can be challenging to host and share.
Hugging Face Hub makes it seamless to host and share datasets, trusted by many leading research institutions, companies, and government agencies, including Nvidia, Google, Stanford, NASA, THUDM and Barcelona Supercomputing Center.
By hosting a dataset on the Hugging Face Hub, you get instant access to features that can maximize your work's impact:
The Hub can host terabyte-scale datasets, with high per-file and per-repository limits. If you have data to share, the Hugging Face datasets team can help suggest the best format for uploading your data for community usage. The 🤗 Datasets library makes it easy to upload and download your files, or even create a dataset from scratch. 🤗 Datasets also enables dataset streaming , making it possible to work with large datasets without needing to download the entire thing. This can be invaluable to allow researchers with less computational resources to work with your datasets, or to select small portions of a huge dataset for testing, development or prototyping.
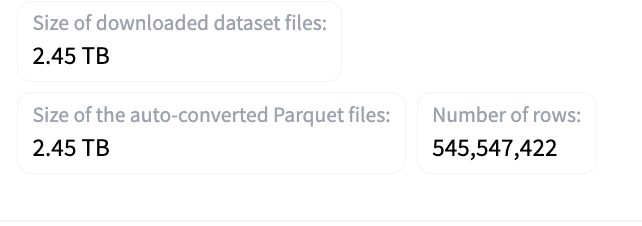
The Hugging Face Hub can host the large datasets often created for machine learning research.
Note: The Xet team is currently working on a backend update that will increase per-file limits from the current 50 GB to 500 GB while also improving storage and transfer efficiency.
Beyond just hosting your data, the Hub provides powerful tools for exploration. With the Datasets Viewer, users can explore and interact with datasets hosted on the Hub directly in their browser. This provides an easy way for others to view and explore your data without downloading it first.
Hugging Face datasets supports many different modalities (audio, images, video, etc.) and file formats (CSV, JSON, Parquet, etc.), and compression formats (Gzip, Zip, etc.). Check out the Datasets File Formats page for more details.

The Dataset Viewer for the Infinity-Instruct dataset.
The Datasets Viewer also includes a few features which make it easier to explore a dataset.
Built-in Full Text Search is one of the most powerful features of the Datasets Viewer. Any text columns in a dataset immediately become searchable.
The Arxiver dataset contains 63.4k rows of arXiv research papers converted to Markdown. By using Full Text Search, it's easy to find the papers containing a specific author such as Ilya Sutskever below.
The Datasets Viewer allows you to sort the dataset by clicking on the column headers. This makes it easy to find the most relevant examples in a dataset.
Below is an example of a dataset sorted by the helpfulness column in descending order for the HelpSteer2 dataset.
Hugging Face is fortunate to have third party integrations with the leading open source data tools. By hosting a dataset on the Hub, it instantly makes the dataset compatible with the tools users are most familiar with.
Here are some of the libraries Hugging Face supports out of the box:
| Library | Description | Monthly PyPi Downloads (2024) |
|---|---|---|
| Pandas | Python data analysis toolkit. | 258M |
| Spark | Real-time, large-scale data processing tool in a distributed environment. | 29M |
| Datasets | 🤗 Datasets is a library for accessing and sharing datasets for Audio, Computer Vision, and Natural Language Processing (NLP). | 17M |
| Dask | Parallel and distributed computing library that scales the existing Python and PyData ecosystem. | 12M |
| Polars | A DataFrame library on top of an OLAP query engine. | 8.5M |
| DuckDB | In-process SQL OLAP database management system. | 6M |
| WebDataset | Library to write I/O pipelines for large datasets. | 871K |
| Argilla | Collaboration tool for AI engineers and domain experts that value high quality data. | 400k |
Most of these libraries enable you to load or stream a dataset in 1 single line of code.
Here are some examples with Pandas, Polars and DuckDB:
# Pandas example
import pandas as pd
df = pd.read_parquet("hf://datasets/neuralwork/arxiver/data/train.parquet")

# Polars example
import polars as pl
df = pl.read_parquet("hf://datasets/neuralwork/arxiver/data/train.parquet")

# DuckDB example - SQL queries
import duckdb
duckdb.sql("SELECT * FROM 'hf://datasets/neuralwork/arxiver/data/train.parquet' LIMIT 10")
You can find more information about integrated libraries in the Datasets documentation. Along with the libraries listed above, there are many more community supported tools which support the Hugging Face Hub such as Lilac and Spotlight.
The SQL Console provides an interactive SQL editor that runs entirely in your browser, enabling instant data exploration without any setup. Key features include:
On every public dataset you should see a new SQL Console badge. With just one click you can open a SQL Console to query that dataset.
While making datasets accessible is important, protecting sensitive data is equally crucial. The Hugging Face Hub provides robust security features to help you maintain control over your data while sharing it with the right audiences.
The Hugging Face Hub supports unique access control options for who has access to the dataset.
For more details about gated datasets, see the gated datasets documentation. For more fine-grained controls, there are Enterprise plan features where organizations can create resource security groups, use SSO, and more.
Along with access controls, the Hugging Face Hub offers several security scanners:
| Feature | Description |
|---|---|
| Malware Scanning | Scans files for malware and suspicious content at each commit and visit |
| Secrets Scanning | Blocks datasets with hardcoded secrets and environment variables |
| Pickle Scanning | Scans pickle files and shows vetted imports for PyTorch weights |
| ProtectAI | Uses Guardian tech to block datasets with pickle, Keras and other exploits |

Having a secure platform with powerful features is valuable, but the true impact of research comes from reaching the right audience. Reach and visibility are crucial for researchers sharing datasets - it helps maximize research impact, enables reproducibility, facilitates collaboration, and ensures valuable data can benefit the broader scientific community.
With over 5M builders actively using the platform, the Hugging Face Hub provides researchers with powerful tools for community engagement and visibility. Here's what you can expect:
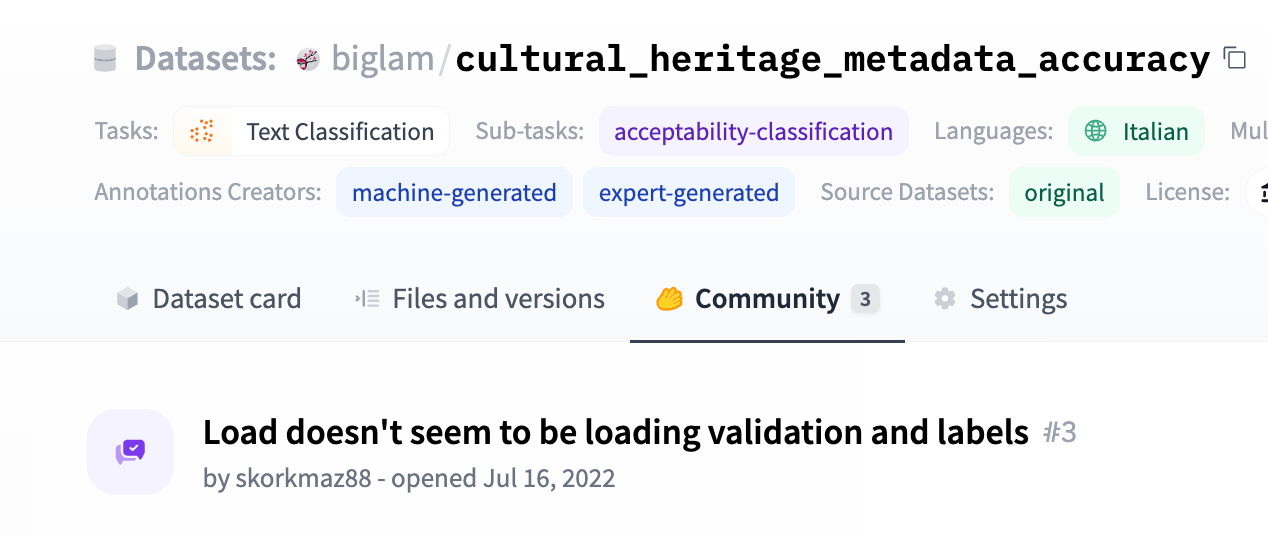
The Hub makes it easy to ask questions and discuss datasets.
Now that you understand the benefits of hosting your dataset on the Hub, you might be wondering how to get started. Here are some comprehensive resources to guide you through the process:
The following pages will be useful if you want to share large datasets:
If you want any further help uploading a dataset to the Hub or want to upload a particularly large dataset, please contact datasets@huggingface.co.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。