


Consolidation has been one of the paths that many astute observers predicted for the near-future of labs training models. It was labelled as inevitable, as training costs are increasing by orders of magnitude every year. Yet, as someone who in 2024 would’ve predicted consolidation really picking up come 2026 or 2027, where are we? We’re at a place where more companies are training strong models — easily investing hundreds of millions to billions of dollars in the total effort still — and an increasing number of organizations are releasing these models openly.
The demand for tokens is incredibly high, and likely to increase as models get more efficient and unlock more possible use cases. All of these labs we thought would need to consolidate are realizing that building token machines is a likely path to value, and more companies will identify that source of value over time.
The prime example is Thinking Machines — when they announced their company in February 2025, very few people would’ve put them in the bucket of an open models company, myself included. Now their open model finetuning service is making hundreds of millions in revenue per year and they’re releasing the best open-weight models built in the U.S.A. — ahead of the early leaders in NVIDIA with Nemotron and Arcee’s Trilogy.
On the other side of the ecosystem is the sustained pace from the Chinese labs, with newer entrants like Xiaomi still accumulating mindshare in the broader AI economy. Having predicted consolidation for a long time, it now seems like a safer bet is to predict continued adoption, and try to imagine the role that open models play there. How much can revenue-share licenses like Kimi K3 stick? How much market share can open models take? We’re entering the decisive era.
This is one of the most packed recaps of open models we’ve ever had, we’re excited!
Inkling by thinkingmachines: The first model from Thinking Machines is a 975B-A41B multimodal MoE that supports text, images, and audio as inputs and produces text as output. While it is not the strongest model among peers (in China) in its size class, it is positioned to be a great base for fine-tuning, e.g., through their commercial offering, Tinker. They also release a smaller version (276B-A12B), which is really competitive for its size.
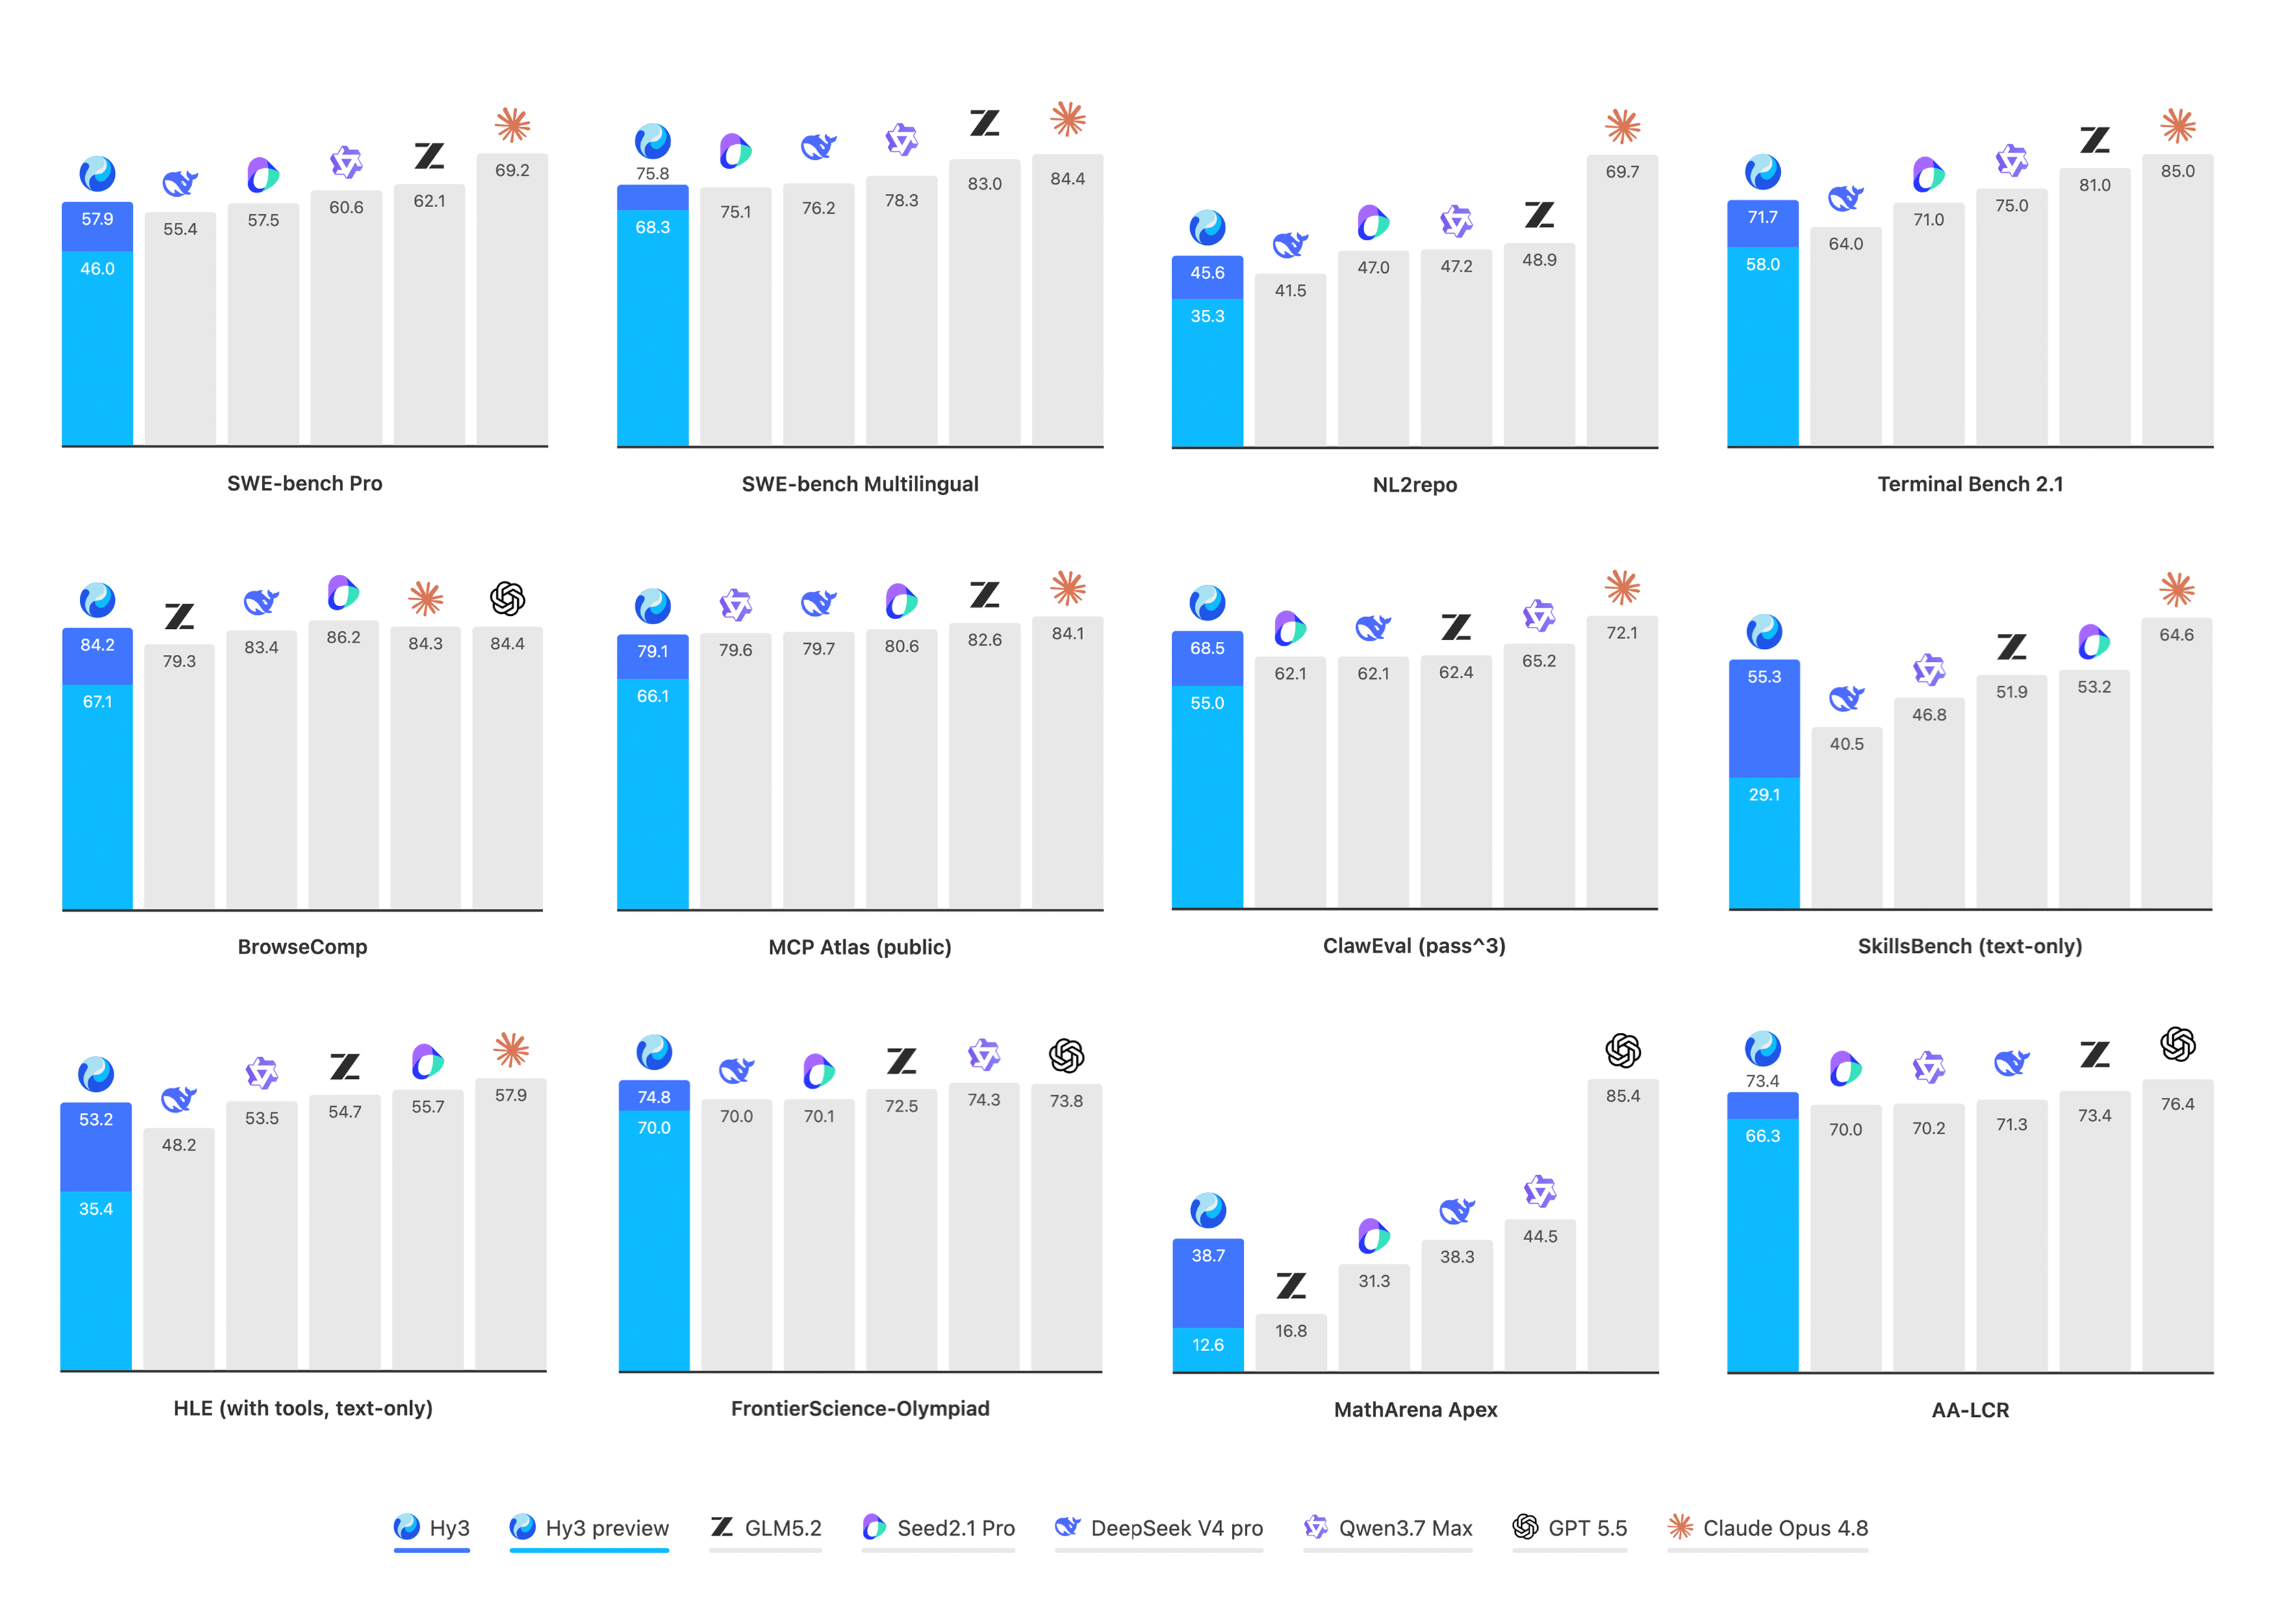
Hy3 by tencent: A 295B-A21B MoE from Tencent. It improves over its predecessor across all metrics. Most notable, however, is the license change: While the previous version (covered in Artifacts 21) used a custom and rather restrictive license, Tencent switched to Apache 2 for this release. The model was also able to proof a 50 year old math problem (with a dedicated harness and Sol as a judge, although it is unclear how important the latter really is).
Laguna-S-2.1 by poolside: Poolside quickly rose out of nowhere to become a frequent guest at Artifacts, marking its third appearance in three consecutive months. S2.1 is a newly pre- and post-trained version of the 118B-A8B MoE that fits on a DGX Spark, which brought it a lot of attention. Poolside also adopted the OpenMDW license, which is an Apache 2.0-like free license but has better legal backing for AI models specifically. The company also goes into more detail in its blog, which includes all the evaluation trajectories. This is a lot of transparency for an open model release!
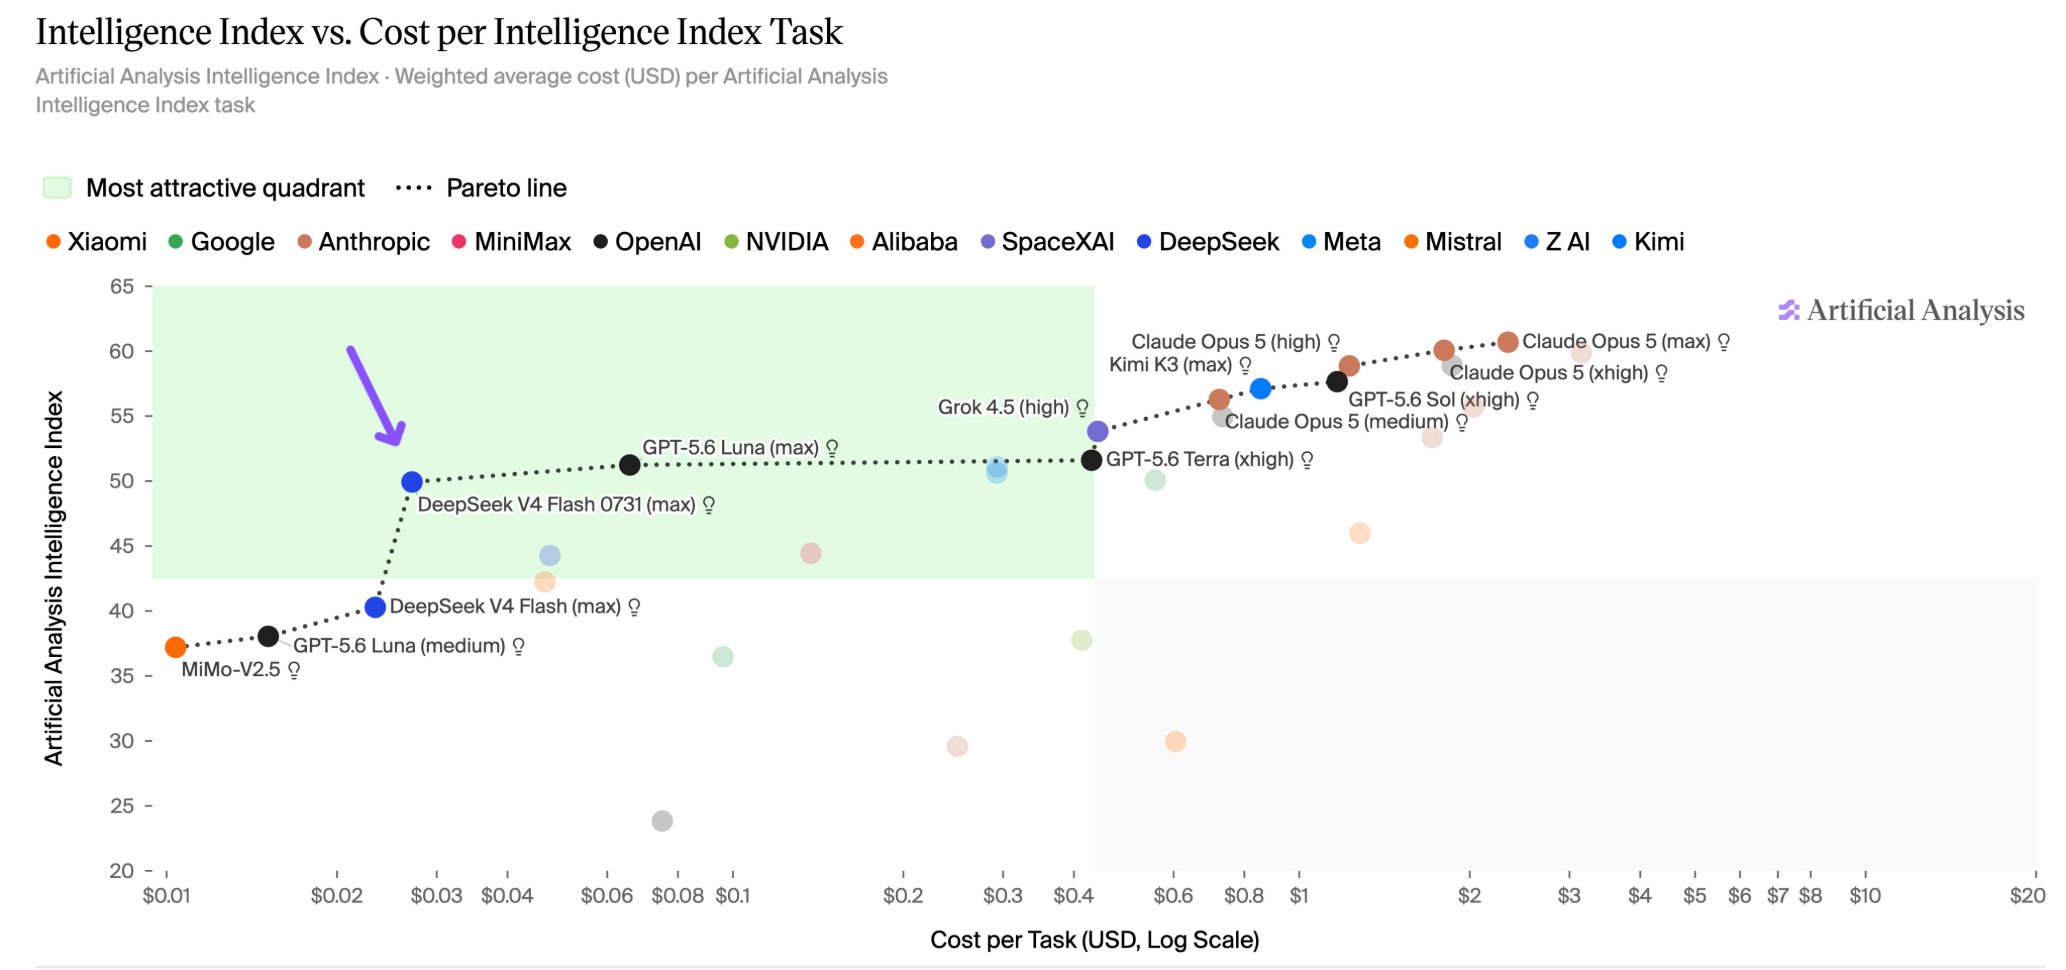
DeepSeek-V4-Flash-0731 by deepseek-ai: Just one day after OpenAI has dropped the prices of their smallest model by 80%, the whale dropped an update to their V4 Flash model, beating Luna at the pareto frontier. The bigger model is not updated yet, so it remains to be seen where it will land in terms of performance. For the initial V4 releases, the Flash version was the star of the show in terms of performance per parameter, while Pro was rather underwhelming.
Kimi-K3 by moonshotai: This is the biggest open model release in some time, and we covered it in a separate post and a podcast episode. It was released under a noncommercial license, requiring inference and fine-tuning providers to enter into a commercial agreement. Kevin Xu and Graham Webster argue in a post that these licenses enable potential future government action against US entities doing business with Chinese AI companies:
But if a US company needs a contract with Moonshot to provide the inference tokens that Kimi K3 generates, the picture looks different. Some of the policy tools US officials and others have debated as potential levers to restrict Chinese open model use would more clearly apply.
LongCat-2.0 by meituan-longcat: The Chinese DoorDash is back again. This time, the company released another big MoE with 1.6T parameters. While the model itself is not the most capable for its size beyond benchmarks, it was trained entirely on Ascend 910s, making it the first non-Huawei, non-toy model trained entirely on Chinese accelerators. Other Chinese chips are mostly used for inference (if at all).
Laguna-XS-2.1 by poolside: An update to the small (33B-A3B) MoE from Poolside.
Motif-3-Beta by Motif-Technologies: A preview of a 314B-A13B MoE by the Korean Motif. This is by far the company’s most ambitious model, as it is considerably larger and introduces some architectural innovations like GDLA and mHC.
Apertus-v1.5-70B by swiss-ai: A continued pre-train of the fully open-source Apertus 1.0, using 2T more tokens.
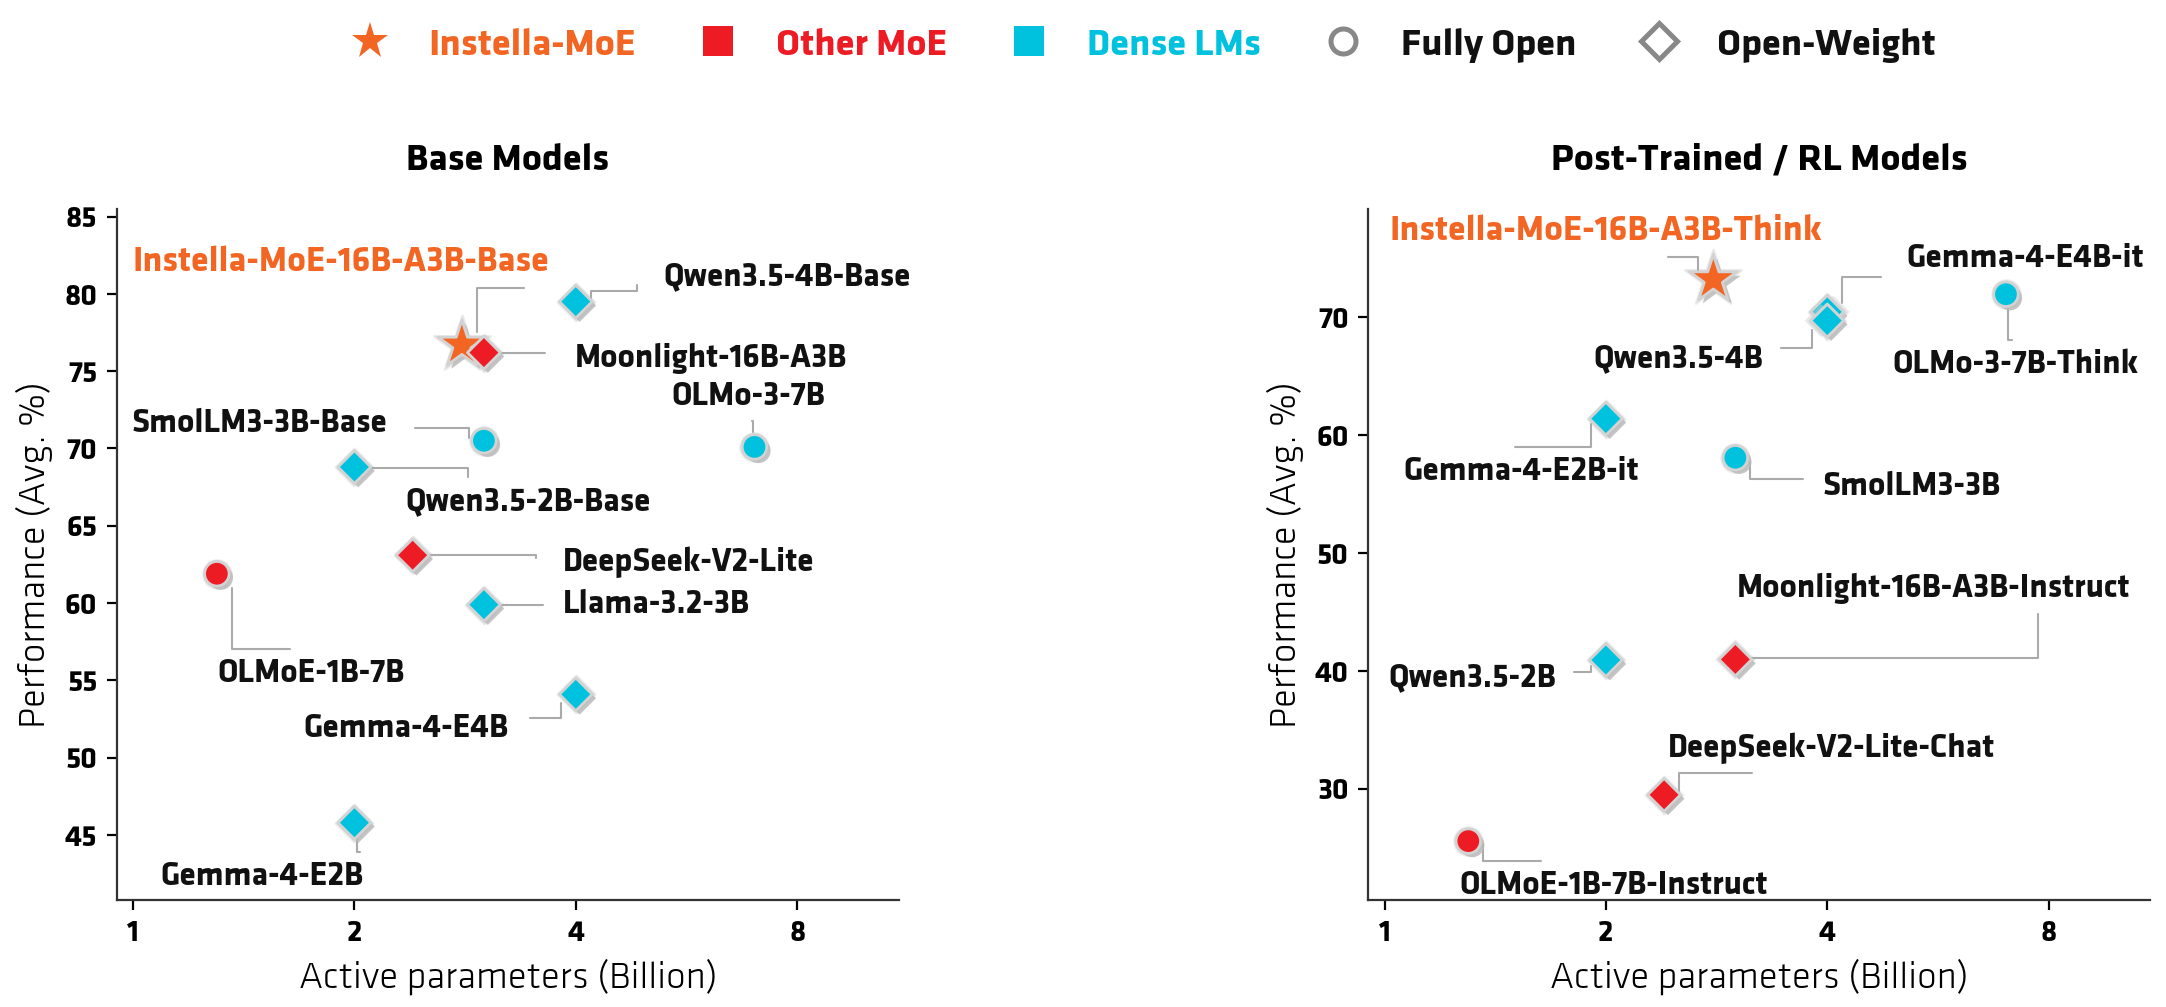
Instella-MoE-16B-A3B-Think by amd: A 16B-A3B MoE trained by AMD on Instinct cards. AMD also provides all the different stages, from the base to the SFT checkpoints, as well as MidTrain and DPO.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。