


I built Tallei because I was tired of repeating myself to AI.
My workflow was already spread across multiple tools. I would:
- Brainstorm in Claude
- Generate images and graphs on ChatGPT
- Gather & analyze in Perplexity
- Argue with the content on Gemini 😅
Every switch came with a cost -> lost context & time wasted.
I had to re-explain the project.
Re-state my preferences.
Re-summarize decisions that had already been made.
Re-upload documents or re-copy the important parts.
The assistants were getting better. The workflow between them was getting worse.
So I built Tallei — a cross-AI memory layer that sits underneath the tools I already use and helps them work from the same context. Not another chat app. Not a replacement for ChatGPT or Claude. A shared memory system that makes those tools feel less disconnected.
The problem was not intelligence. It was continuity.
A lot of people talk about which model is smarter.
That was not the pain I felt.
The real pain was continuity.
I could have a great working session in one assistant and then lose the thread completely when I moved to another. What mattered was not just text. It was the state of the work:
what I was trying to do
what had already been decided
what documents mattered
what constraints were important
what kind of responses I preferred
That state kept dying at the border between tools.
Tallei started from a simple idea: your context should not disappear just because you switched AI assistants.
How Tallei can help you
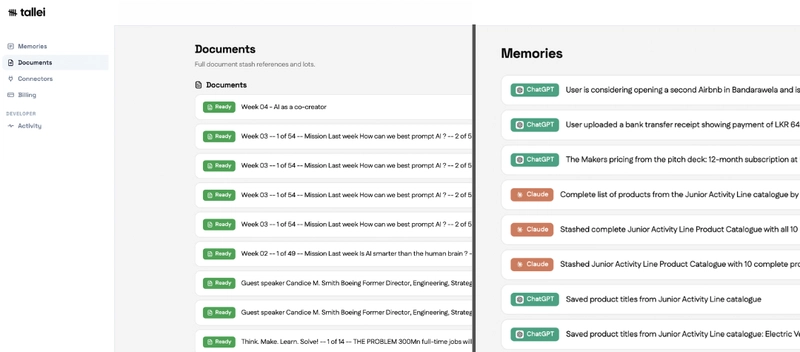
Tallei is designed to store and retrieve the parts of context that are worth carrying forward across tools.
That includes things like:
- preferences
- facts
- decisions
- recent notes
- document-related context
The goal is simple:
reduce re-explaining
keep projects coherent across assistants
make handoffs between tools smoother
let documents stay useful after the first chat window is closed
If you only use one assistant, native memory may be enough.
But if your work spans multiple tools, you start to feel this gap very quickly.
The first version worked, but barely
The first version of Tallei proved the idea, but the experience was rough.
I had the basics in place:
- a backend
- authentication
- memory save and recall
- an MCP server
- a dashboard
- integrations for multiple assistants
Technically, it worked.
But when I tested recall properly, it took over **30 seconds** in the early version.
That is unusable for a product like this.
Memory cannot feel like a background report. It has to feel immediate. If recalling context takes that long, the user would rather just manually explain things again.
That was the first big product lesson: this could not just be “smart.” It had to be fast enough to disappear into the workflow.
1. My first big mistake: I optimized for speed and made it worse
When I started fixing latency, I made a mistake that taught me a lot about memory products.
I got recall much faster.
But I also made it less trustworthy.
The faster version sometimes returned the wrong memory first, especially on new or slightly different queries. The system looked impressive on latency, but it was no longer reliable. And for a memory system, that is deadly.
A fast wrong answer is worse than a slower correct one.
Because once the user stops trusting recall, the whole product starts falling apart. They hesitate. They second-guess what is injected. They stop depending on the system.
That was the moment I stopped thinking only about speed and started thinking more clearly about trust.
The recall system that actually worked
The version that finally felt right was simpler.
Instead of trying to be overly clever, I rebuilt recall around a few practical buckets of context:
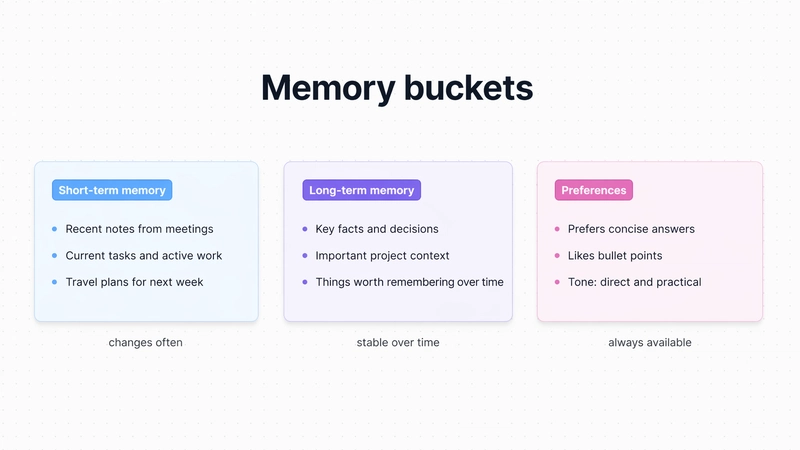
preferences
long-term memory like facts and decisions
short-term memory like recent notes and events
That structure worked better because it reflected how context is actually in our brains.
Some things should almost always be available, like preferences.
Some things matter over time, like key decisions.
Some things are recent and situational, like what happened in the last few days or weeks.
The goal was not to create the most complicated retrieval system possible. The goal was to reliably bring the right categories of context into the conversation without flooding it.
That made Tallei feel much more stable.
It also led to a much better outcome on performance, while keeping accuracy intact. The “dump-all when it fits, retrieve selectively when it does not” model ended up being much more practical than forcing heavy retrieval logic on every request.
Documents were one of the hardest parts
One of the biggest things I realized while building Tallei was that memory is not just about facts like “I prefer concise answers.”
Documents matter a lot more than that.
People want assistants to remember:
- the PDF they uploaded
- the contract they reviewed
- the research they already summarized
- the notes from a brainstorm
- the key takeaways from a long session
That is where a lot of the handoff pain really lives.
So Tallei handles documents in two ways:
01. Document notes
These are lighter-weight summaries, key points, or takeaways.
They are useful when you want the important context from a document without dragging the whole document into every conversation.
02. Document blobs
These are for the full source material when you need more complete archival context.
On top of that, each document gets a @doc: reference, and documents can be grouped into lots with @lot: references. That makes it easier to organize related material and carry it forward in a structured way instead of treating every file like an isolated upload.
03. Document lots
These are multiple documents referenced and usually used together. This was really useful since people usually reference an average 2 documents per AI query, and running and finding 2 are costly and takes up memory. We need to make sure to not overbloat the context.
This was important for the product because real work is rarely just one memory at a time. It is often a set of connected documents, notes, and decisions.
2. Another mistake: I built things because they sounded smart
At one point, I built a graph layer to map entities and relationships across memories.
It sounded like exactly the kind of thing a memory product should have.
In practice, it added complexity without enough value.
It made the system heavier, introduced messy entity labeling problems, and did not improve the actual user experience enough to justify keeping it. So I removed it.
That was another important lesson from building Tallei:
not every advanced feature belongs in the product just because it sounds intelligent.
Sometimes the better product decision is to remove complexity and focus on what actually helps users keep their thread across tools.
Why I think this matters
We are not another all-AI chat router interface✌️.
That means the moment your workflow becomes multi-tool, you start feeling the missing layer.
That missing layer is what I wanted Tallei to address.
Not by replacing the assistants, but by helping them feel connected, and not distrupting your flow.
I do not think the future of AI work is one assistant doing everything. I think a lot of real workflows will stay spread across multiple systems, each better at different moments. If that is true, then shared context becomes important infrastructure.
Open source matters here too
Tallei Github Repo
Tallei is also open source, which was important to me from the start.
If you are building a memory product — something that stores preferences, facts, notes, and document context — people should be able to inspect how it works. Open source helps make the architecture, trade-offs, and implementation more transparent.
It also makes it easier for others to understand that this is not just a vague AI promise. It is an actual system with real product decisions behind it.
Who this is for
Tallei is for people whose AI workflow already spans more than one tool.
That could be:
- founders moving between strategy, research, and execution
- developers using different assistants for architecture, debugging, and building
- writers switching between ideation, editing, and fact-checking
- researchers comparing outputs across models
- anyone tired of pasting the same context over and over again
If that sounds familiar, then you probably already understand the problem Tallei is trying to solve.
Final thought
I did not build Tallei because I thought the world needed one more AI product.
I built it because I personally felt the pain of context breaking between assistants, over and over again.
The core idea stayed simple the whole way through:
your context should survive the handoff within your AI tools
That means preferences should carry over.
Documents should stay useful.
Important decisions should not disappear.
And switching tools should not mean starting from zero.
That is what Tallei is built for.