1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
| import requests
from lxml import html
conn = requests.session()
headers = {'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; WOW64) '
'AppleWebKit/537.36 (KHTML, like Gecko) '
'Chrome/63.0.3239.26 '
'Safari/537.36 Core/1.63.5733.400 '
'QQBrowser/10.2.2019.400'}
# 验证码计算
def cal(sen):
number = sen.split(':')[1].split('等于')[0]
ans = 0
if '加' in sen:
ans = int(number.split('加')[0]) + int(number.split('加')[1])
elif '减' in sen:
ans = int(number.split('减')[0]) - int(number.split('减')[1])
elif '乘以' in sen:
ans = int(number.split('乘以')[0]) * int(number.split('乘以')[1])
elif '除以' in sen:
ans = int(number.split('除以')[0]) / int(number.split('除以')[1])
return int(ans)
# 中文期刊
def all_journal():
# 登录
url = 'http://muchong.com/bbs/logging.php?action=login'
postdata = {
'formhash': 'da8aadbd',
'username': '******',
'password': '******',
'cookietime': 31536000,
'refer': '',
'loginsubmit': '(unable to decode value)'
}
rep = conn.post(url, data=postdata, headers=headers)
# 验证
yanzheng = html.fromstring(rep.text)
question = yanzheng.xpath('//form[@name="input"]/div/text()')[0]
formhash = yanzheng.xpath('//input[@name="formhash"]/@value')[0]
post_sec_hash = yanzheng.xpath('//input[@name="post_sec_hash"]/@value')[0]
answer = cal(question)
# print(question, answer, formhash, post_sec_hash)
postdata = {
'formhash': formhash,
'post_sec_code': answer,
'post_sec_hash': post_sec_hash,
'username': '******',
'loginsubmit': '(unable to decode value)',
}
rep1 = conn.post(url, data=postdata, headers=headers)
# 期刊
# 第一页
url = 'http://muchong.com/bbs/journal_cn.php'
rep2 = conn.get(url, headers=headers)
qikan = html.fromstring(rep2.text)
head_name = qikan.xpath('//div[@class="wrapper"][8]/div[@class="forum_head"]//td/text()')
all_qikan = qikan.xpath('//div[@class="wrapper"][8]/div[@class="forum_body forum_body_journal"]//tbody')
for a in all_qikan[:]:
x = a.xpath('string(.)')
print(x.split())
# 第一页往后
for i in range(2, 23):
url = 'http://muchong.com/bbs/journal_cn.php?from=emuch&view=&classid=0&class_credit=0&page=' + str(i)
rep2 = conn.get(url, headers=headers)
qikan = html.fromstring(rep2.text)
head_name = qikan.xpath('//div[@class="wrapper"][6]/div[@class="forum_head"]//td/text()')
all_qikan = qikan.xpath('//div[@class="wrapper"][6]/div[@class="forum_body forum_body_journal"]//tbody')
for a in all_qikan[:]:
x = a.xpath('string(.)')
print(x.split())
def journal_name(name):
url = 'http://muchong.com/bbs/journal_cn.php'
name = name.encode("GBK")
postdata = {
'issn': '',
'tagname': '',
'name': name,
'ssubmit': '(unable to decode value)',
'accept-charset': "utf-8"
}
rep = conn.post(url, data=postdata, headers=headers)
qikan = html.fromstring(rep.text)
every_qikan = qikan.xpath('//div[@class="wrapper"][6]/div[@class="forum_body forum_body_journal"]//tbody')
for a in every_qikan[:]:
x = a.xpath('tr/th/a/@href')
url = 'http://muchong.com/bbs/'+x[0]
print(url)
detail(url)
def detail(url):
rep = conn.get(url, headers=headers)
_detail = html.fromstring(rep.text)
# 虫友提供资料
deta = _detail.xpath('//div[@class="wrapper"][4]/div[@class="forum_explan bg_global"][2]//tr')
for i in deta:
i1 = i.xpath('string(.)')
print(i1.split())
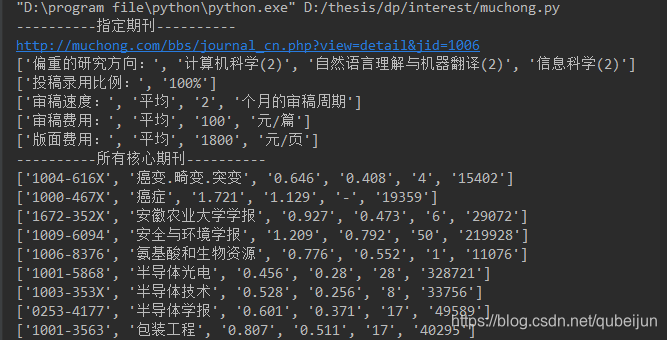
print('----------指定期刊----------')
journal_name('中文信息学报')
print('----------所有核心期刊----------')
all_journal()
|