


New UC San Diego research suggests the line between human and machine is increasingly drawn around social behavior as much as knowledge

- UC San Diego researchers ran a rigorous three-party Turing test and found that, with the right “persona” prompt, advanced AI can pass as human in live chats.
- GPT-4.5 was judged “human” 73% of the time; LLaMa-3.1-405B was 56%.
- Without persona prompting, performance dropped sharply.
- The results raise new questions about online trust, deception and what “humanlike” means.
A new University of California San Diego study unveils the first empirical evidence that a modern artificial intelligence system can pass the Turing test — a major scientific benchmark that asks whether a machine can imitate human conversation so convincingly that people can’t reliably tell it apart from a real person. In a series of experiments, people were often unable to tell the difference between humans and advanced large language models (LLMs).
The study published in the Proceedings of the National Academy of Sciences is the first to rigorously test LLMs with the method that British mathematician and “father of computer science” Alan Turing created in 1950. It is also the first time anyone has found that models were judged to be human as often as actual humans using the Turing framework.
“What we found is that if given the right prompts, advanced LLMs can exhibit the same tone, directness, humor and fallibility as humans,” said the study’s corresponding author Cameron Jones, who conducted the research while earning his doctorate in Cognitive Science from UC San Diego. “While we know LLMs can easily produce knowledge on nearly every topic, this test showed that it can also convincingly display social behavioral traits, which has major implications for how we think of AI.”
In the test, a participant chats simultaneously with two other parties — one is a human and the other is an LLM —and the human “interrogator” must decide which party is the human.
Across randomized, controlled, experiments with two independent participant groups — UC San Diego undergraduates and online participants — interrogators held brief, text-based conversations and then made their judgments. In the experiments participants chatted with four different LLMs — GPT-4.5 and LLaMa-3.1-405B as state-of-the-art models — and the researchers also included older baseline models for comparison. Those models included GPT-4o and ELIZA, a classic 1960s rules-based chatbot.
Across the four LLMs, GPT-4.5 was judged to be the human 73% of the time, meaning interrogators selected it as “human” significantly more often than they selected the real human participant. LLaMa-3.1-405B, given the same prompt, was judged human 56% of the time — statistically indistinguishable from the humans it was compared against.
Baseline systems performed far worse: ELIZA and GPT-4o were selected as human only about 23% and 21% of the time overall.
76 years after its inception, the Turing Test takes on new meaning
The study also reveals that scientists need to start thinking of the Turing Test differently, according to the authors.
“The Turing test started as a way to ask whether machines could rival human intelligence,” said study coauthor Ben Bergen, a professor of cognitive science at UC San Diego. “But now we know AI can answer many questions faster and more accurately than people can, so the real issue isn’t raw brainpower. Seeing that machines can pass the test — and seeing how they pass it — forces us to rethink what it measures. Increasingly, it’s measuring humanlikeness.”

Image created by AI (ChatGPT)
Alan Turing a closeup portrait from English money - pound. Credit: johan10/iStock.
Each LLM was given a “persona” prompt, asking it to adopt a specific human character and communication style. Bergen explained that the LLMs were not winning through shows of force of knowledge, they were winning because they made mistakes like a human would. “These traits aren’t the kinds of math and logic problem-solving intelligence that I think Turing was imagining.”
Prompts mattered — dramatically
Without explicit instructions, the models were far less likely to be mistaken for human: GPT-4.5 fell to a 36% win rate and LLaMa-3.1 to 38%, while baseline systems ELIZA (23%) and GPT-4o (21%) were chosen as human even less often.
The same systems that could pass as human when given detailed instructions on what kind of character they should play were unable to adopt such characteristics without that guidance — suggesting that while the models can behave in convincingly human ways, they often need humans to tell them how.
“They have the ability to appear human-like, but maybe not as much the ability to figure out what it would take to appear human-like,” Bergen said.
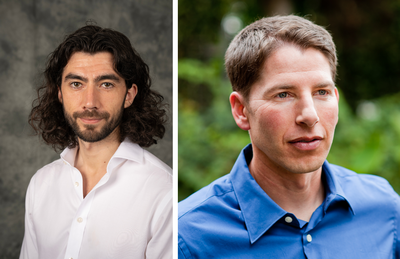
Cameron Jones earned his doctorate in Cognitive Science from UC San Diego in 2025 (left) and Ben Bergen (right) a professor of Cognitive Science at UC San Diego. Courtesy of Stony Brook University and UC San Diego.
Why it matters: trust, deception and the rise of “counterfeit people”
The results carry real-world implications for trust online — especially because the models that pass as human do so over the course of extended five or 15-minute conversations. “It’s relatively easy to prompt these models to be indistinguishable from humans,” said Jones, who is now an assistant professor of Psychology at Stony Brook University. “We need to be more alert; when you interact with strangers online people should be much less confident that they know they’re talking to a human rather than an LLM.”
He also points to darker risks. “The Turing test is a game about lying for the models,” Jones said. “One of the implications is that models seem to be really good at that.”
Bergen added that being unable to discern whether you’re interacting with a human or bot can have serious consequences.
“There are lots of people who would like to use bots to persuade people to share their social security numbers, and vote for their party, or buy their product,” he said.
The researchers note they hope the work sharpens public understanding of what these systems can now do — and what kinds of safeguards society may need.
A live, head-to-head test of human vs. machine
To run the study, the researchers built an online interface designed to feel like a familiar messaging app.
“For the interrogator, they have a split screen on their computer and they’re asking questions to both witnesses,” Jones said. “They know that one of those witnesses is a human and one of them is an AI.”
After five minutes — and in a separate replication study, 15 minutes—the interrogator had to decide which conversational partner was the real human.
To confirm the results held beyond a single population, the researchers ran the study with two groups: UC San Diego undergraduates recruited through the SONA system and a broader online sample recruited through Prolific, a platform that pays participants to complete research studies. Nearly 500 people participated across the experiments.
UC San Diego participants performed slightly better overall, possibly because they shared more “common ground” that could be used to probe one another, such as shared experiences and local campus details.
A version of the Turing test interface used in the study is available at turingtest.live.
Read the full study “Large Language Models Pass a Standard Three-Party Turing Test.”
Stay in the Know
Keep up with all the latest from UC San Diego. Subscribe to the newsletter today.