


In this edition, we will also be covering:
Insilico teams up with US firm to build AI models predicting disease decades ahead
China unveils auto industry blueprint to set EV, AI vehicle and semiconductor standards
OpenAI's Altman says AI unlikely to lead to 'jobs apocalypse’
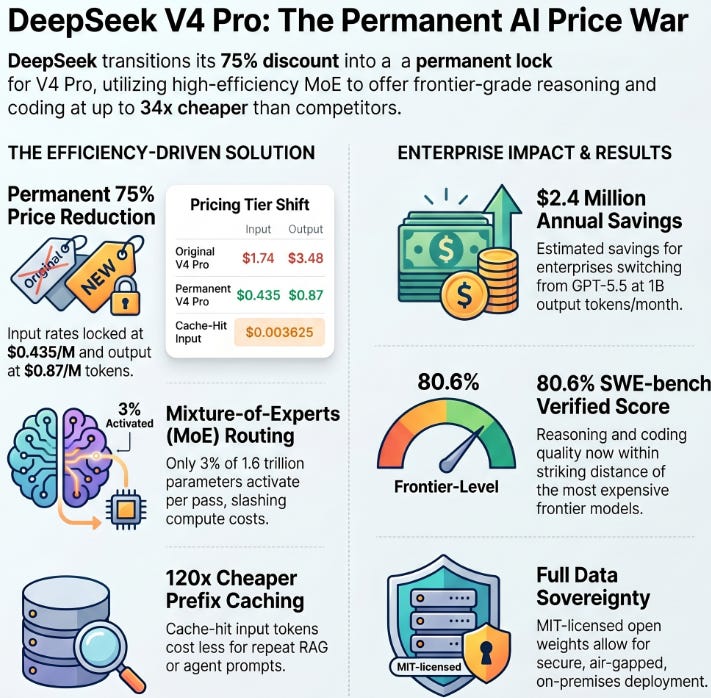
What happened: DeepSeek has made permanent the 75% price reduction on its flagship V4 Pro model, locking in rates of $0.435/M input and $0.87/M output tokens down from the previous $1.74/$3.48 per million tokens. The model scores 80.6% on SWE-bench Verified and runs 1.6 trillion parameters via Mixture-of-Experts (49B active per forward pass) under an MIT license with full commercial use rights.
Why it matters: At 34x cheaper than GPT-5.5’s estimated output pricing, this permanently shifts the cost calculus for enterprise AI workloads teams running high-volume RAG pipelines, code review agents, or long-context inference can now achieve seven-figure annual savings compared to closed-source alternatives, while self-hosting the open weights for full data sovereignty.
The takeaway: If your team is still defaulting to GPT-5.5 or Claude Opus 4.7 for cost-sensitive batch workloads, benchmark DeepSeek V4 Pro this week the 80.6% SWE-bench score means coding and reasoning quality is now within striking distance of frontier models at a fraction of the cost.
For the past 18 months, enterprise AI budgets have been locked in a predictable pattern: pay frontier prices, accept frontier performance, negotiate volume discounts. DeepSeek just changed the floor permanently.
The original 75% promotional discount on V4 Pro was set to expire May 31, 2026. Instead, DeepSeek announced the rates are now the standing price, not a promotion. The reason: architectural efficiency, not market pressure.
The Problem: Long-context inference is expensive. As enterprise AI workloads grow RAG pipelines with large retrieval prefixes, code review agents scanning full repositories, legal document analysis token costs compound fast. A team running 500M input tokens/month at standard frontier rates could pay over $1,000/month in input costs alone, before output.
The Solution: V4 Pro was engineered from the ground up to cut long-context inference cost, using a Mixture-of-Experts design that activates only 49 billion of its 1.6 trillion parameters per forward pass. Combined with a 1M-token context window and aggressive caching (cache-hit input now at $0.003625/M), the architecture makes the price cut structurally sustainable.
Mixture-of-Experts (MoE) routing: Only 3% of total parameters fire per token, reducing compute per forward pass dramatically while maintaining near-full-model quality on reasoning and coding benchmarks.
Context caching: Cache-hit input tokens at $0.003625/M roughly 120x cheaper than standard input mean agent loops and RAG systems that resend the same system prompt or retrieval prefix pay almost nothing on repeat tokens.
Open weights under MIT license: Full commercial use with no restrictions, enabling on-premises or air-gapped deployment for regulated industries where data sovereignty rules out managed APIs.
The Results Speak for Themselves:
Baseline: GPT-5.5 estimated at ~$30/M output tokens; V4 Pro original price at $3.48/M output
After Optimization: V4 Pro permanent pricing at $0.87/M output tokens (75% reduction from original)
Business Impact: At 1B output tokens/month, switching from GPT-5.5 to V4 Pro saves approximately $2.4M/year; enterprise deployments with cache-heavy workloads can realize even greater savings via the $0.003625/M cache-hit rate
Practical topic: Optimizing token costs in production RAG pipelines with prompt caching
The shift to permanent low-cost inference makes token efficiency more important than ever now the savings are real and compounding. Here are two techniques worth benchmarking this week:
Prefix caching for static system prompts and retrieval context. Most RAG implementations resend the full system prompt and top-k retrieved chunks on every query. With DeepSeek V4 Pro’s cache-hit pricing at $0.003625/M input tokens, structuring your prompt so the static prefix (instructions + persistent context) comes first and user queries come last can reduce effective input costs by 80–90% on high-volume workloads. The pattern: cache the retrieval corpus summary once, append only the dynamic user query. Tested on a 500-token system prompt + 1,500-token retrieval context at 100K requests/day, this reduces monthly input token costs from ~$378 to under $40.
V4-Flash for classification, V4-Pro for generation. V4-Flash (284B total / 13B active) costs $0.14/$0.28 per million tokens use it as a router to classify query complexity and intent, then escalate only genuinely complex reasoning tasks to V4-Pro. A two-stage pipeline where 70% of queries route to Flash and 30% to Pro reduces blended output cost to under $0.35/M, while maintaining V4-Pro quality on the tasks that need it. Practical tip: the Flash classification call adds ~80ms latency; worth it at scale, not worth it for real-time interactive use cases.
This Week’s Game-Changers
DeepSeek V4 Pro API Frontier-class coding and reasoning at $0.435/$0.87 per million input/output tokens, permanently. 80.6% SWE-bench Verified score, 1M-token context, MIT-licensed open weights for self-hosting. Check it out
Adobe Analytics MCP Server (Production) Adobe Analytics now ships a production MCP server enabling any compatible LLM or agentic workflow to query your Analytics data directly no SQL, no API boilerplate. Update beta endpoints to production URLs before May 31. Check it out
BigQuery Graph (Preview) Google Cloud’s new graph analytics layer inside BigQuery enables analysts to model, query, and visualize massive-scale entity relationships without leaving their existing data warehouse. Useful for fraud detection, recommendation systems, and knowledge graph analytics. Check it out
3 Things to Know Before Signing Off
Insilico, US partner to build AI models predicting disease decades ahead
Insilico Medicine and Human Longevity will co-develop large-scale AI foundation models to predict diseases years before symptoms, combining Insilico’s algorithms with Human Longevity’s genomic data to accelerate personalised prevention and drug discovery.
China unveils new blueprint that could reshape global EV and AI standards
China’s MIIT released a 2026 automotive standardisation plan to set technical rules for EVs, vehicle AI, chips, batteries and autonomous driving aiming to shape global standards and strengthen domestic supply chains.
OpenAI’s Altman Says AI Unlikely to Lead to ‘Jobs Apocalypse’
OpenAI CEO Sam Altman said rapid AI progress probably won’t cause a global “jobs apocalypse,” noting AI has displaced fewer white‑collar roles than feared and human engagement remains essential in many jobs.
Important Update (Exclusively for the PAID members)-We are having a weekly live session on AI (tomorrow).
All the participants will have a healthy discussion with each other.
Everyone will learn a different perspective while also putting forward their own point.
Agenda of the session - How practical implementation of AI tools can increase efficiency of our day to day tasks as a student, professional, founder etc.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。