


Today's AI models are falling victim to a dangerous vulnerability: data poisoning. But the data poisoning crisis isn't caused solely -- or even mostly -- by hackers or adversaries. It's self-inflicted. As enterprises race to deploy AI across workflows, they are quietly and quickly flooding their internal databases with AI-generated summaries, emails, code and reports. Data poisoning occurs when synthetic content is ingested back into the training pipelines used to build and fine-tune organizations' next generation of AI models.
For many organizations, the AI transformation they invested in is now actively cannibalizing the AI future they are counting on.
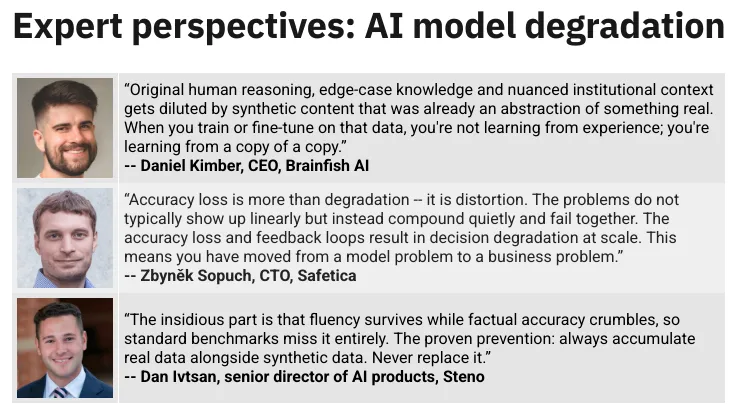
"What happens is this: the signal-to-noise ratio collapses," said Daniel Kimber, CEO of Brainfish AI, an Australia-founded tech startup focused on building AI agents. "Original human reasoning, edge-case knowledge and nuanced institutional context get diluted by synthetic content that was already an abstraction of something real. When you train or fine-tune on that data, you're not learning from experience; you're learning from a copy of a copy."
Related:Will the music stop for AI's funding dance?
The end result of data poisoning is a risk that many CIOs may already be aware of: Model degradation. However, reducing the problem to simply "model degradation" can cloak what's really at stake -- business outcomes. Model degradation can lead to decision degradation, which occurs when decisions -- made by either machines or humans -- rely on distorted analyses or outputs from AI.
"Accuracy loss is more than degradation -- it is distortion. The problems do not typically show up linearly but instead compound quietly and fail together," said Zbyněk Sopuch, CTO at Safetica, a data loss prevention and insider risk management provider. "The accuracy loss and feedback loops result in decision degradation at scale. This means you have moved from a model problem to a business problem."
Data poisoning can also lead to a surprising variety of legal, compliance and institutional knowledge woes. The data degradation it causes is irreversible, according to an AI model study published in Nature.com in 2024. Not only that, but it also flattens the "nuanced, rare institutional knowledge in the tails of your data distribution" in the process, according to Dan Ivtsan, senior director of AI products at Steno, a provider of tech-enabled court reporter and litigation support services.
"The insidious part is that fluency survives while factual accuracy crumbles, so standard benchmarks miss it entirely," he added.
Related:Red Hat CIO Marco Bill: Resource control is key for AI sovereignty
Beyond accuracy loss, organizations can face bias amplification due to factors such as the disappearance of minority-group data output and the homogenization of outputs, meaning a convergence of outputs toward a bland average.
"In legal AI, where I build products, that drift can mean hallucinated citations or incorrect medical timelines. That's real malpractice exposure," Ivtsan said. "The proven prevention: always accumulate real data alongside synthetic data. Never replace it."
Data poisoning lessens the value of the original data, explained Ryoji Morii, founder of Tokyo-based Insynergy.io, a company specializing in AI governance and AI decision architecture. "Data is being treated as a throwaway resource, and derived values are being used instead. This is contaminating the training data and making the raw data less relevant," Morii said.
You can blame the problem on corporate need for speed, human instinct to reach for what's easiest, or simply a misunderstanding of how AI training and fine-tuning actually works. Regardless of the reason or intent, the harm is undeniable.
"What is being described is 'data poisoning in the name of convenience.' It is not malicious, but it will result in long-term damage," Sopuch said.
Related:As Microsoft expands Copilot, CIOs face a new AI security gap
Assigning blame doesn't matter nearly as much as being able to recognize the danger now.
"In the early stages, you often will not catch it: the outputs look fine, the QA also passes," said Chetan Saundankar, CEO of India-based Coditation, a company that builds and deploys AI systems for enterprise clients. But this is the calm before the storm.
"Weeks or months later, the model begins to get things wrong in ways that are hard to spot because the answers still sound perfectly reasonable," he said. "A code tool starts suggesting patterns that work but have security holes. A summarization model starts dropping the qualifications and nuances that made the original documents useful, while still sounding authoritative."
The problems seep into everything important to running a successful and profitable organization. Small inaccuracies, like misjudging resource allocation or mislabeling usage patterns, can quickly snowball, explained Dirk Alshuth, chief marketing officer of Emma, a Luxembourg-based cloud management platform. Eventually, those errors increase costs or lead to performance reduction over time. "The feedback loop makes it worse because those same flawed outputs can get logged and reused, reinforcing the mistake," he added.
In cloud and infrastructure environments for example, small inaccuracies such as making slightly wrong recommendations from misjudging resource allocation or mislabeling usage patterns can quietly increase costs or reduce performance over time Alshuth said. This can have a potentially huge impact on the business.
Another issue he said he noticed is loss of adaptability. "AI trained on AI tends to struggle when something new or unexpected happens, because it hasn't seen real variability," he said.
"The best prevention is to keep your training data tied to real system behavior. Use live telemetry, logs and human-reviewed decisions as your source of truth, and treat AI-generated outputs as temporary, not foundational," Alshuth added.
CIOs need to be cognizant that the problem of data poisoning doesn't end at model degradation. Training on AI-generated content can lead to "model collapse," wherein AI systems eventually and completely fail. In effect, it reduces AI investments to spoilage loss -- the loss occurs when the projects are rendered useless beyond the point of repair, given the degradation of the model, data and the outputs.
"Model collapse refers to a degradation that occurs when models are trained repeatedly on outputs from other models. Over time, the system becomes more repetitive, less nuanced, and less representative of the real world," explained Oli Ostertag, president of growth platforms and AI at PAR Technology, a unified commerce platform provider for restaurants, convenience stores, and fuel retailers.
Even if organizations are deploying vendor AI solutions in their enterprise, the collapse may still be originating closer to home. "The conversation about AI data contamination tends to focus on foundation model training, [meaning] what OpenAI or Google trains on," Kimber said. "But the more immediate problem for most organizations is happening one layer down, in their own knowledge infrastructure. Every company is now, functionally, a model trainer."
The first step in correcting the data poisoning problem is stopping it from getting worse. Fortunately, there is a way to salvage performance as or after a model collapses, although it requires considerable effort. Prevention is always preferable, but if a collapse occurs the solution is to retrain on clean data to restore performance, Ivtsan said.
Collapse is avoidable if real data accumulates alongside synthetic data, rather than being replaced by it, according to a paper by Gerstgrasser et al. Even imperfect external verification can stabilize the trajectory, according to another paper by Yi et al.
In this context, "imperfect" external validation doesn't mean using verification sources or information that may be flawed or incorrect. It means using methods like spot checks, subject-matter expert review or experience-based human judgment, which are not thorough fact-checking in themselves, but are still likely to be highly accurate. At-scale, targeted verification beats both zero oversight and the impracticality of exhaustive fact-checking.
The better course of action, if possible, is to prevent it from occurring.
"The way to prevent it is to design for human–machine feedback loops. The strongest systems are iterative, human to AI, AI back to human, where outputs are continuously shaped, challenged and refined," explained Kaare Wesnaes, head of innovation at Ogilvy North America, the agency behind brand building for Fortune Global 500 companies worldwide.
In short, "the strongest systems aren't AI-only. They're human–machine loops," Wesnaes said.
The key idea is to remember that AI is only as good as its data, and to act accordingly.
"Companies need to protect the integrity of their data. That means prioritizing high-quality, human-generated inputs, clearly separating synthetic from real data, and continuously reintroducing fresh, real-world signals into their systems," Wesnaes said.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。