





When building PlanetScale, we knew that we would be using background jobs extensively for tasks like creating databases, branching, and deploying schema changes.
Early on, we decided we had two hard requirements for this system.
- If we lose all data in the queues at any time, we can recover without any loss in functionality.
- If a single job fails, it will be automatically re-run.
These requirements came about from our past experience with background job systems. We knew that it was "not if, but when" that we’d hit failure scenarios and need to recover from them.
Our background jobs perform critical actions for our users, such as rolling out schema changes to their production databases. This is an action that cannot fail, and if it does, we need to recover quickly.
Our stack
The PlanetScale UI (Next.js app) is backed by a Ruby on Rails API. All of our Rails background jobs are run on Sidekiq.
Much of what you’ll read here is Sidekiq specific (with code samples) but can be applied to most any background queueing system.
Scheduler jobs running on a cron
For each job we have, we set up another job whose responsibility is to schedule it to run.
This is the core design decision that allows us to be self-healing. If for any reason we lost a job, or even the entire queue, the scheduling jobs will re-queue anything that was missed.
We’ve put this decision to the test a couple of times already this year. We were able to dump our queues entirely without impacting our user experience.
Storing state in the database
When using a background job system, a common pattern is to let jobs only be queued by a user action.
For example: In our application, a user can create a new database. This action enqueues a background job to do all the setup.
What if something goes wrong with that job? What if Redis failed and we lost everything in our queues? These were scenarios that worried us.
The solution is storing the state in our PlanetScale database. When creating a database for a user, we also create a record in our databases table immediately. This record starts with a state set to pending.
This allows us to have a scheduled job that runs once a minute and checks if any databases are in a pending state. If they are, that triggers the creation job to get enqueued again:
class ScheduleDatabaseJobs < BaseJob
  sidekiq_options queue: "background"

  def perform
    Database.pending.find_each do |database|
      DatabaseCreationJob.perform_async(database.id)
    end
  end
end
As long as the scheduler job is running, we could dump our entire queue and still recover.
Disabling schedules with feature flags
We added the ability to stop our scheduled jobs from running at any time. This has come in useful during an incident where we’ve wanted control over a specific job type.
To do this, we added middleware that checks a feature flag for each job type. If the flag is enabled, we skip running the job:
# lib/sidekiq_middleware/scheduled_jobs_flipper.rb
module SidekiqMiddleware
  class ScheduledJobsFlipper
    def call(worker_class, job, queue, redis_pool)
      # return false/nil to stop the job from going to redis
      klass = worker_class.to_s
      if BaseJob::SCHEDULED_JOBS.key?(klass) && Flipper.enabled?("disable_#{klass.underscore.to_sym}")
        return false
      end

      yield
    end
  end
end
# initializers/sidekiq.rb
Sidekiq.configure_server do |config|
  config.client_middleware do |chain|
    chain.add(SidekiqMiddleware::ScheduledJobsFlipper)
  end
end
Bulk scheduling jobs
Scheduling jobs one-by-one works well when you only have a few thousand. Once our app grew, we noticed we were spending a lot of time sending individual Redis requests. Each request is very fast, but requests add up when run thousands of times.
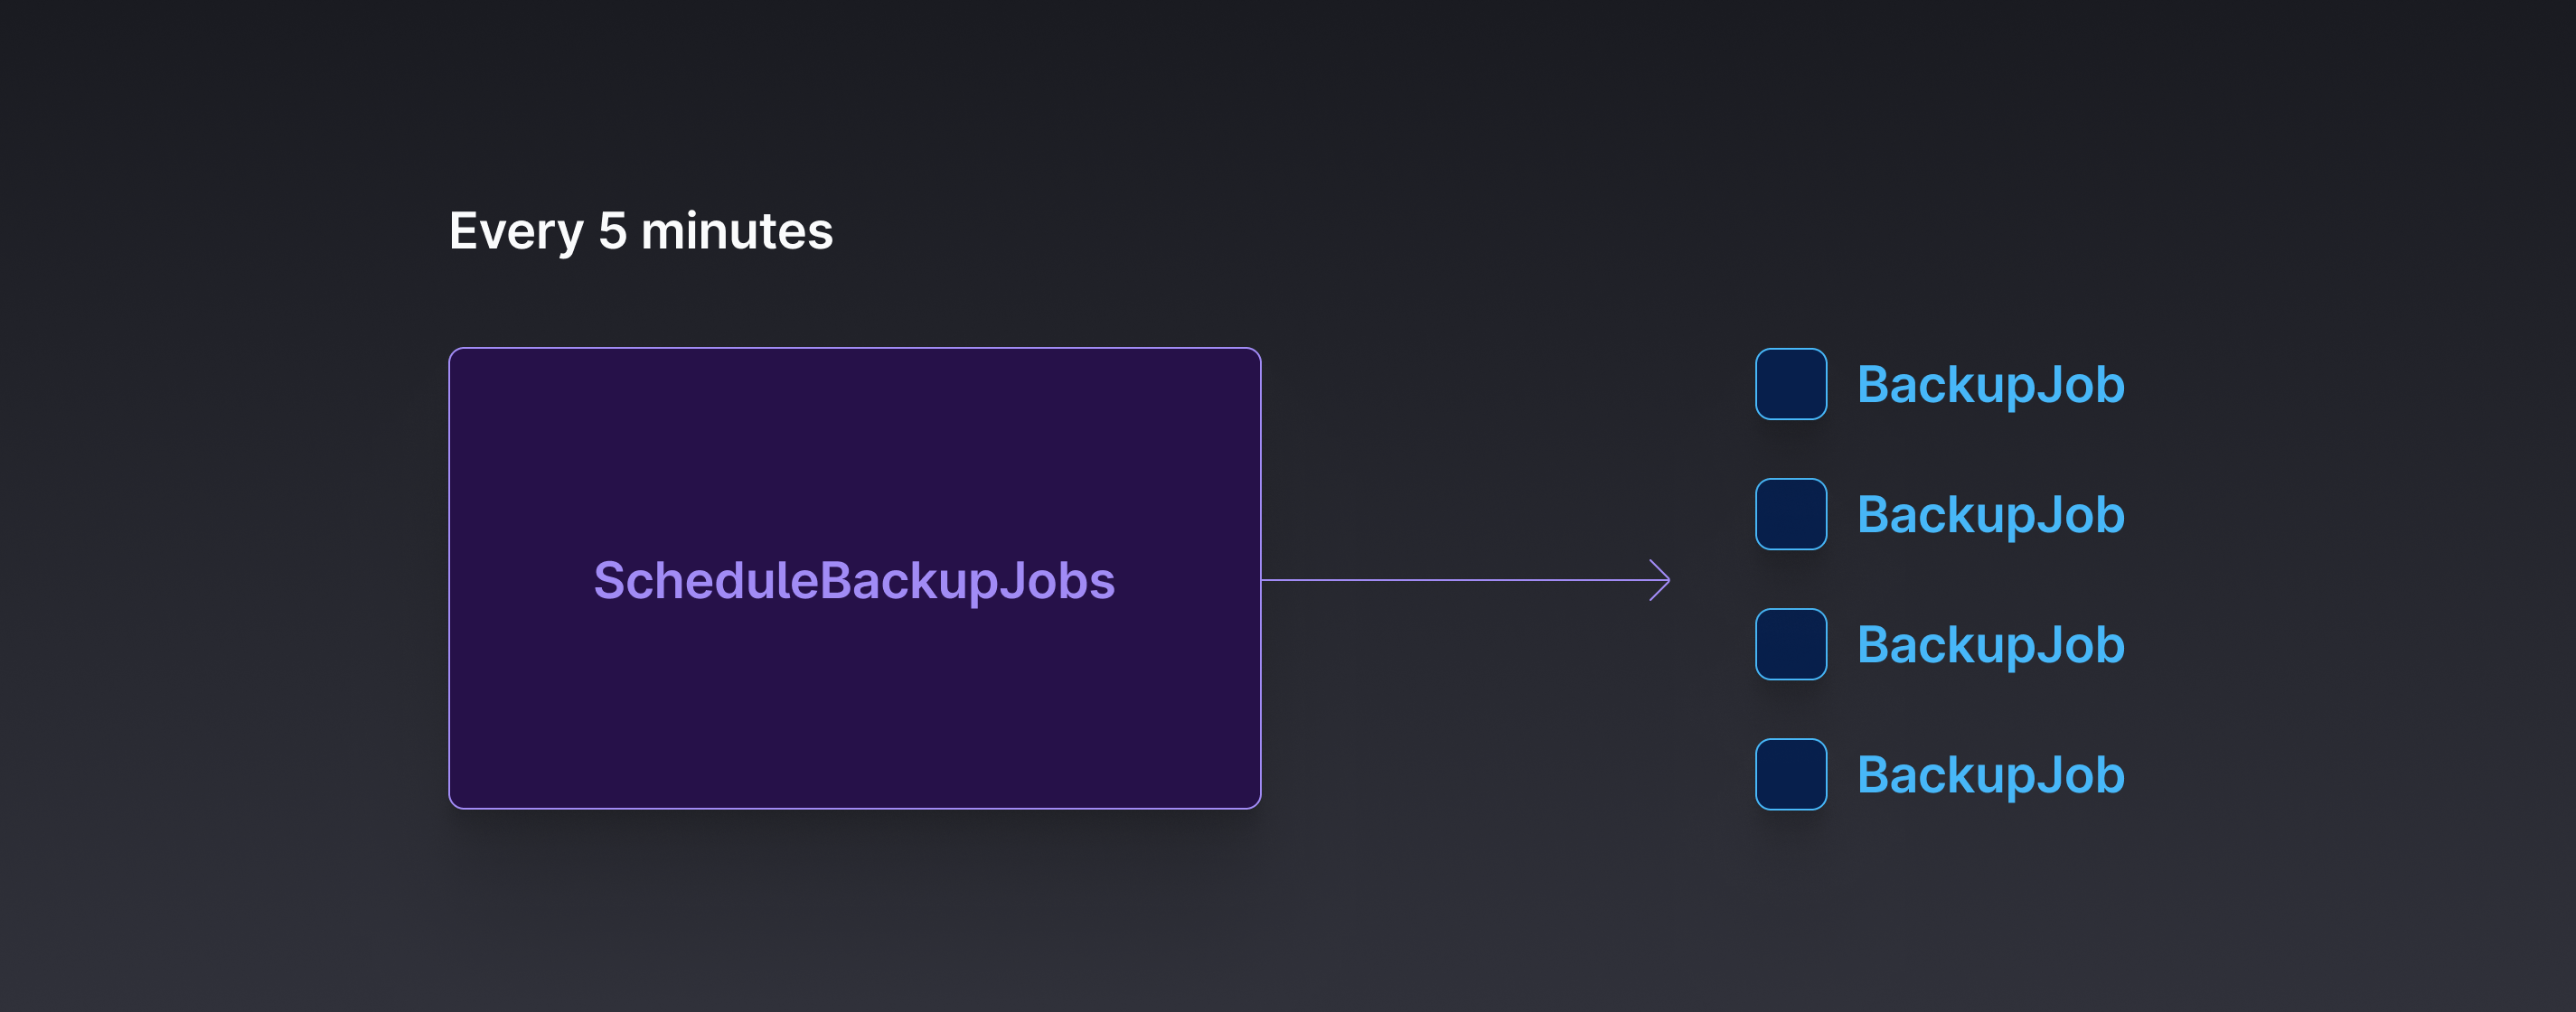
To improve this, we started bulk scheduling jobs:
# Job is set to run every 5 minutes
class ScheduleBackupJobs < BaseJob
  sidekiq_options queue: "background"

  def perform
    # Schedule backup jobs in batches of 1,000
    BackupPolicy.needs_to_run.in_batches do |backup_policies|
      BackupJob.perform_bulk(backup_policies.pluck(:id))
    end
  end
end
Adding jitter to job scheduling
We don’t want certain types of jobs all running at once because they may overwhelm an external API. In those cases, we spread them out over a time period using perform_with_jitter. Below is a custom method we added to our job classes to handle this:
# This will run sometime in the next 30 minutes
CleanUpJob.perform_with_jitter(id, max_wait: 30.minutes)
# app/jobs/application_job.rb
MAX_WAIT = 1.minute
def self.perform_with_jitter(*args, **options)
  max_wait = options[:max_wait] || MAX_WAIT
  min_wait = options[:min_wait] || 0.seconds
  random_wait = rand(min_wait...max_wait)
  set(wait: random_wait).perform_later(*args)
end
Handling uniqueness
With the way we schedule jobs, it’s possible for us to get multiple of the same job in our queues. We handle this in a few ways.
1. Exit quickly
We store state in our database and quickly exit a job if it no longer needs to be run:
def perform(id)
  user = user.find(id)
  return unless user.pending?
  # ...
end
2. Use database locks
We avoid race conditions, such as when multiple jobs are updating the same data at once:
backup.with_lock do
  backup.restore_from_backup!
end
3. Use sidekiq unique jobs
Sidekiq Enterprise includes the ability to have unique jobs. This will stop a duplicate job from ever being enqueued:
class CheckDeploymentStatusJob < BaseJob
  sidekiq_options queue: "urgent", retry: 5, unique_for: 1.minute, unique_until: :start
  #...
end