






The race to make large language models faster and cheaper to run has largely been fought at two levels: the model architecture and the hardware. But there is a third, often underappreciated frontier — the GPU kernel. A kernel is the low-level computational routine that actually executes a mathematical operation on the GPU. Writing a good one requires understanding not just the math, but the exact memory layout, instruction scheduling, and hardware quirks of the chip you are targeting. Most ML professionals never write kernels directly; they rely on libraries like FlashAttention or Triton to do it for them.
Meet FlashQLA: a QwenLM’s contribution to this layer. Released under the MIT License and built on the TileLang compiler framework, it is a high-performance linear attention kernel library specifically optimized for the Gated Delta Network (GDN) attention mechanism — the linear attention architecture that powers the Qwen3.5 and Qwen3.6 model families.
To understand what FlashQLA solves, it helps to understand what standard softmax attention costs. In a conventional Transformer, the attention mechanism has O(n²) complexity — meaning that doubling the sequence length quadruples the computation. This is the fundamental bottleneck that makes processing long documents, long code files, or long conversations expensive.
Linear attention replaces the softmax with a formulation that reduces this to O(n) complexity, making it scale much more favorably with sequence length. The Gated Delta Network (GDN) is one such linear attention mechanism, and it has been integrated into Qwen’s hybrid model architecture, where GDN layers alternate with standard full attention layers. This hybrid design attempts to get the best of both worlds: the expressiveness of full attention where it is most needed, and the efficiency of linear attention everywhere else.
GDN uses what is called a ‘gated’ formulation — it applies an exponentially decaying gate to control how much past context is carried forward. This gate is key to how FlashQLA achieves its performance gains.
Before FlashQLA, the standard implementation for GDN operations came from the Flash Linear Attention (FLA) library, which uses Triton kernels — Triton being OpenAI’s Python-based GPU programming language. While Triton makes kernel authoring more accessible, it comes with trade-offs: the kernels it produces are not always optimally scheduled for specific hardware, particularly on NVIDIA’s Hopper architecture (the H100 and H200 GPU generation).
The Hopper architecture introduced new features like warpgroup-level Tensor Core operations and asynchronous data pipelines that Triton cannot always exploit to their full potential. This is the gap FlashQLA is designed to fill.
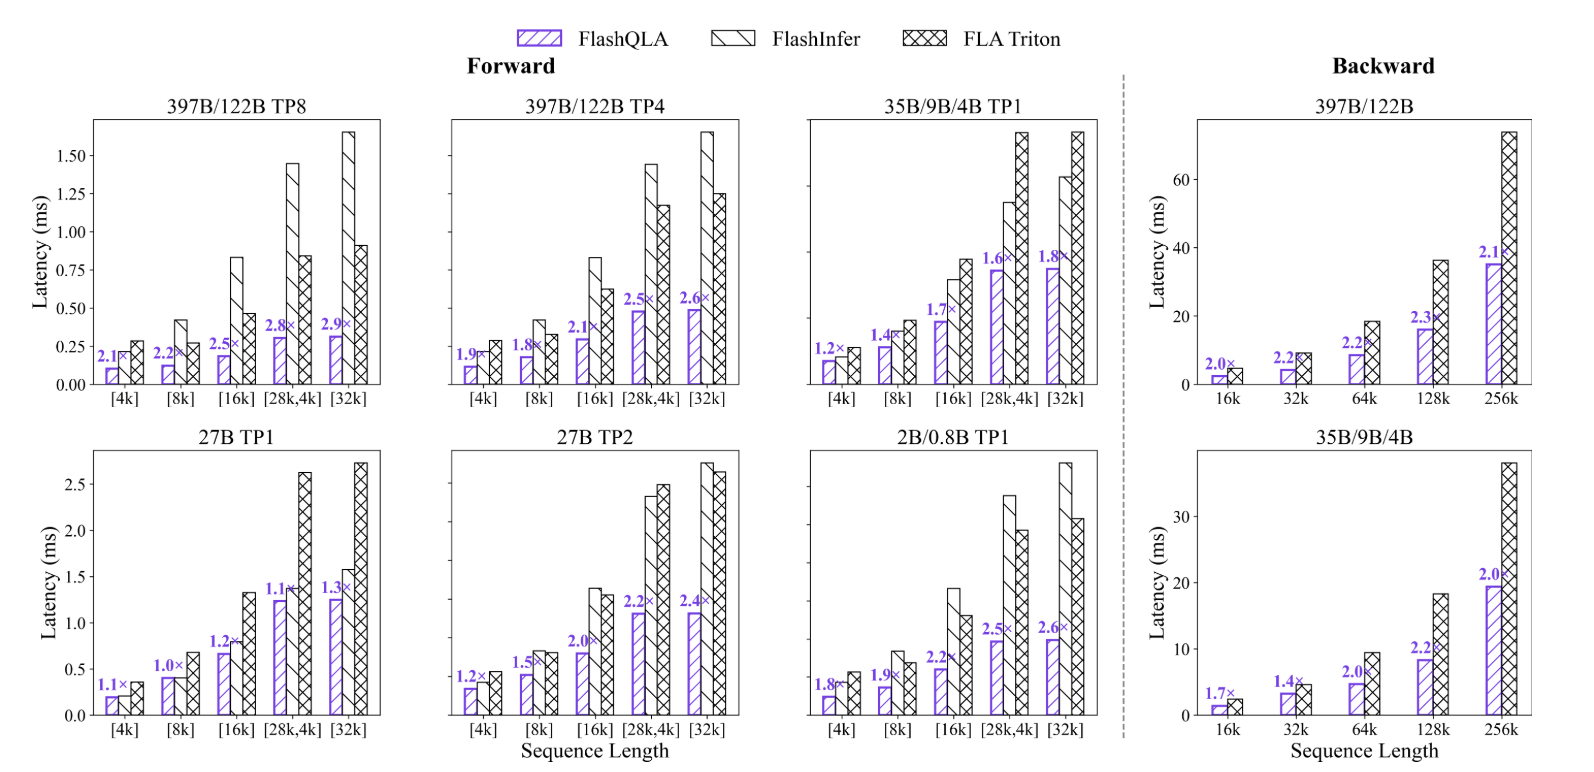
FlashQLA applies operator fusion and performance optimization to both the forward pass (used during inference and training) and the backward pass (used during training for gradient computation) of GDN Chunked Prefill. The result is a 2–3× speedup on forward passes and a 2× speedup on backward passes compared to the FLA Triton kernel across multiple scenarios on NVIDIA Hopper GPUs.
Three technical innovations drive these gains:
1. Gate-driven automatic intra-card context parallelism: Context parallelism (CP) refers to splitting a long sequence across multiple processing units so they can work on different parts simultaneously. FlashQLA exploits the exponential decay property of the GDN gate to make this split mathematically valid — because the gate’s decay means that tokens far apart in a sequence have diminishing influence on each other. This allows FlashQLA to automatically enable intra-card CP under tensor parallelism (TP), long-sequence, and small-head-count settings, improving GPU Streaming Multiprocessor (SM) utilization without requiring manual configuration.
2. Hardware-friendly algebraic reformulation: FlashQLA reformulates, to a certain extent, the mathematical computation of GDN Chunked Prefill’s forward and backward flows to reduce overhead on three types of GPU hardware units: Tensor Cores (which handle matrix multiplications), CUDA Cores (which handle scalar and vector operations), and the Special Function Unit (SFU, which handles operations like exponentials and square roots). Critically, this is done without sacrificing numerical precision — an important guarantee when the reformulation is being used for model training.
3. TileLang fused warp-specialized kernels: Rather than decomposing the computation into independent sequential kernels (too slow) or fusing everything into a single monolithic kernel (too rigid to optimize), FlashQLA takes a middle path. It uses TileLang to build several key fused kernels and manually implements warpgroup specialization — a technique that assigns different warpgroups (groups of 128 threads on Hopper) to specialized roles, such as one warpgroup moving data from global memory to shared memory while another simultaneously runs Tensor Core matrix multiplications. This overlap of data movement, Tensor Core computation, and CUDA Core computation is what allows FlashQLA to approach the theoretical peak throughput of the hardware.
FlashQLA was benchmarked against two baselines: the FLA Triton kernel (version 0.5.0, Triton 3.5.1) and FlashInfer (version 0.6.9), using TileLang 0.1.8, on NVIDIA H200 GPUs. The benchmarks used the head configurations from the Qwen3.5 and Qwen3.6 model families, with head dimensions hv ∈ 64, 48, 32, 24, 16, 8, corresponding to tensor parallelism settings from TP1 through TP8.
The forward (FWD) benchmarks measure single-kernel latency for different models and TP settings under varying batch lengths. The backward (BWD) benchmarks examine the relationship between total token count within a batch and latency during a single update step.
Check out the GitHub Repo and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 130k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。