










There is a quiet failure mode that lives at the center of every AI-assisted coding workflow. You ask Claude Code, Cursor, or Windsurf to modify a function. The agent does it confidently, cleanly, and incorrectly — because it had no idea that 47 other functions depended on the return type it just changed. Breaking changes ship. The test suite screams. And you spend the next two hours untangling what the model should have known before it touched a single line.
An Indian Computer Science student built GitNexus to fix that. The open-source project, now sitting at 28,000+ stars and 3,000+ forks on GitHub with 45 contributors, describes itself as ‘the nervous system for agent context.’ That description undersells what it actually does.
GitNexus is a code intelligence layer, not a documentation tool. It indexes an entire repository into a structured knowledge graph — mapping every function call, import, class inheritance, interface implementation, and execution flow — and then exposes that graph to AI agents through a Model Context Protocol (MCP) server. The agents stop guessing. They query.
To understand why this is significant, you need to understand what AI coding agents currently operate on. Most tools like Cursor, Claude Code, and Windsurf rely on either file-based context windows (they read the files nearby and hope for the best) or traditional Graph RAG approaches (they query a graph with a series of prompts, hoping to discover what matters). Neither approach gives an agent a structural map of the repository before it acts.
GitNexus pre-computes the entire dependency structure at index time. When an agent asks ‘what depends on this function?’, it gets a complete, confidence-scored answer in one query, instead of chaining 10 successive queries that each risk missing something.
Running npx gitnexus analyze from the root of a repository kicks off a multi-phase indexing pipeline that does the following:
First, it walks the file tree and maps folder and file relationships (the Structure phase). Then it parses every function, class, method, and interface using Tree-sitter ASTs (Abstract Syntax Trees). Tree-sitter is a high-performance, incremental parser originally developed at GitHub that produces concrete syntax trees for any supported language. GitNexus uses it to extract symbols with precision that regex or simple text search cannot match.
After parsing, GitNexus performs cross-file resolution: it resolves imports, function calls, class heritage, constructor inference, and self/this receiver types across the whole codebase. This is the step where it learns that UserController in src/controllers/user.ts calls into UserService, which authRouter imports, which handleLogin depends on.
Next comes clustering — GitNexus groups related symbols into functional communities using Leiden community detection on the call graph, assigning each cluster a cohesion score. Then it traces execution flows from entry points through full call chains to build what it calls ‘processes.’ Finally it indexes everything for hybrid search using BM25 (a keyword ranking algorithm), semantic vector embeddings, and RRF (Reciprocal Rank Fusion) to merge results. The graph is stored in LadybugDB, an embedded graph database with native vector support formerly known as KuzuDB.
This entire pipeline runs locally — no code leaves your machine.
A particularly useful flag for teams: gitnexus analyze --skills takes the Leiden community detection one step further. Instead of only grouping symbols internally, it generates a custom SKILL.md file for each detected functional area of your codebase under .claude/skills/generated/. Each skill file describes that module’s key files, entry points, execution flows, and cross-area connections — so an AI agent working in the authentication module gets targeted architectural context for that specific area, not a generic overview of the entire repo. Skills are regenerated on each --skills run to stay current.
Once indexed, GitNexus registers an MCP server that exposes seven tools and two guided prompts to your AI agent.
impact runs blast radius analysis. Given a target symbol, it returns every upstream caller grouped by depth with confidence scores — handleLogin [CALLS 90%], UserController [CALLS 85%] — so the agent knows what it risks breaking before it touches anything.context gives a 360-degree view of any symbol: its callers, its callees, every process it participates in, and which step of each process it occupies.query runs process-grouped hybrid search across the codebase, returning matching symbols alongside the execution flows they belong to.detect_changes performs git-diff impact analysis — it maps changed lines to affected processes and assigns a risk level before you commit.rename executes coordinated multi-file symbol renames using the graph for high-confidence edits and text search for the rest, with a dry-run mode to preview changes before applying them.cypher exposes raw Cypher graph queries for engineers who want to write custom traversals against the knowledge graph directly.list_repos handles the multi-repo case — GitNexus uses a global registry at ~/.gitnexus/ so one MCP server can serve multiple indexed repositories simultaneously.Beyond the tools, GitNexus also exposes two MCP prompts for guided workflows. detect_impact runs a pre-commit change analysis that surfaces scope, affected processes, and an overall risk level — think of it as a structured checklist before any significant edit. generate_map produces architecture documentation directly from the knowledge graph, complete with Mermaid diagrams, making it useful for onboarding engineers or documenting a codebase that has grown faster than its docs.
GitNexus supports Claude Code, Cursor, Codex, OpenCode, and Windsurf. Editor support varies by tier. Windsurf gets MCP only. Cursor, Codex, and OpenCode get MCP plus agent skills. Claude Code gets the full stack: MCP tools, agent skills (Exploring, Debugging, Impact Analysis, Refactoring), PreToolUse hooks that enrich every search with graph context before Claude acts, and PostToolUse hooks that auto-reindex after commits. For Claude Code users, GitNexus installs itself completely — hooks, skills, and an AGENTS.md / CLAUDE.md context file — in a single npx gitnexus analyze command.
One of the less obvious implications of this architecture is what it does for smaller models. Because GitNexus precomputes architectural clarity and delivers it in a single structured tool response, a model like GPT-4o-mini can navigate a large codebase without the reasoning chains required to reconstruct that structure from scratch. The tool does the heavy lifting; the model interprets a clean output rather than raw graph edges.
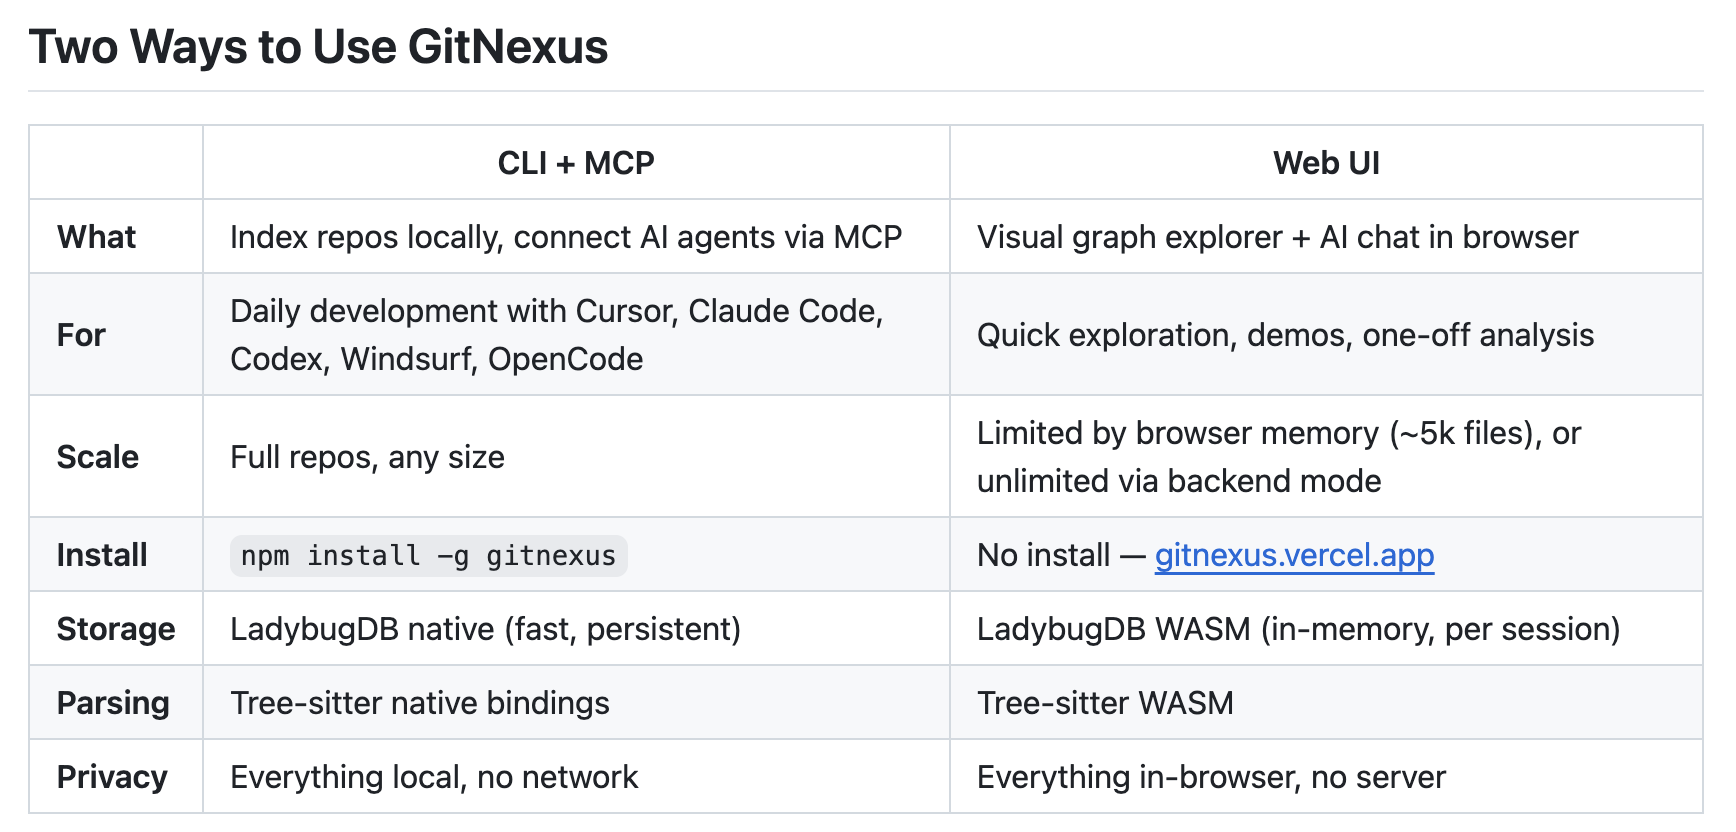
For dev teams that want to explore a repository visually without installing the CLI, GitNexus ships a fully client-side web interface at gitnexus.vercel.app. Drop in a GitHub repo or a ZIP file and get an interactive knowledge graph rendered with Sigma.js over WebGL, with a built-in Graph RAG agent for conversational code exploration. Everything runs in the browser via WebAssembly — Tree-sitter WASM, LadybugDB WASM, and in-browser embeddings via HuggingFace transformers.js. No server. No upload. No data leaving the browser.
For devs using both the CLI and the web UI, gitnexus serve provides a bridge mode: the web UI auto-detects the running local server and surfaces all your CLI-indexed repositories without requiring a re-upload or re-index. The agent tools — Cypher queries, search, code navigation — route through the local backend HTTP API automatically.
impact tool call.detect_changes for pre-commit risk analysis, rename for coordinated multi-file symbol renames, and generate_map for auto-generating Mermaid architecture diagrams from the knowledge graph.AGENTS.md / CLAUDE.md context files, all installed with a single npx gitnexus analyze command.Check out the Repo here. Also, feel free to follow us on Twitter and don’t forget to join our 130k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。