








Building a production-grade voice AI agent is one of the hardest engineering challenges in applied machine learning today. It is not just about transcription accuracy. You need a system that can hold context across a five-minute conversation, invoke external APIs mid-call without an awkward pause, gracefully recover when a caller corrects themselves, and do all of this reliably when the audio is degraded by background noise, a heavy accent, or a dropped word. Most current systems handle one or two of those requirements. xAI’s newly released grok-voice-think-fast-1.0 is making a serious claim to handle all of them — and the benchmark numbers back it up.
Available via the xAI API, grok-voice-think-fast-1.0 is the xAI’s new flagship voice model. It is purpose-built for complex, ambiguous, multi-step workflows across customer support, sales, and enterprise applications, and it is already deployed at scale powering Starlink’s live phone operations.
Before unpacking the benchmark results, it is worth understanding what kind of model grok-voice-think-fast-1.0 is. It is evaluated on the (Tau) τ-voice Bench as a full-duplex voice agent. The system processes incoming speech and generates responses simultaneously, rather than waiting for the speaker to stop before it begins thinking. This is how humans communicate in real conversations. It is also why handling interruptions is a genuinely hard technical problem: the model must decide in real time whether a mid-sentence utterance is a correction, a clarification, or just a filler word, and adjust its behavior accordingly.
The τ-voice Bench evaluates agents specifically under these realistic conditions: noise, accents, interruptions, and natural turn-taking, making it a more relevant measure for production deployments than traditional clean-audio ASR benchmarks.
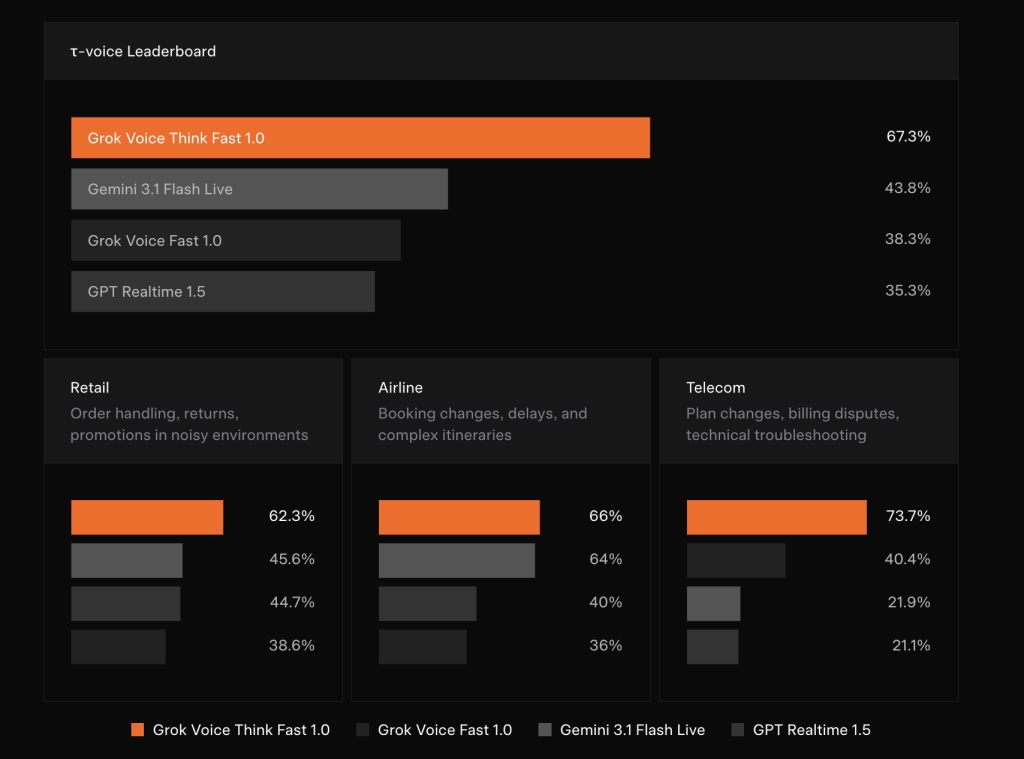
The benchmark results xAI published are striking in how large the gaps are. On the τ-voice Bench overall leaderboard, grok-voice-think-fast-1.0 scores 67.3%, compared to 43.8% for Gemini 3.1 Flash Live, 38.3% for Grok Voice Fast 1.0 (xAI’s own previous model), and 35.3% for GPT Realtime 1.5.
Breaking that down by vertical tells an even clearer story:
In Retail — covering order handling, returns, and promotions in noisy environments — grok-voice-think-fast-1.0 scores 62.3%, followed by Grok Voice Fast 1.0 at 45.6%, Gemini 3.1 Flash Live at 44.7%, and GPT Realtime 1.5 at 38.6%.
In Airline — booking changes, delays, and complex itineraries — the scores are 66% for Grok Voice Think Fast 1.0, 64% for Grok Voice Fast 1.0, 40% for Gemini 3.1 Flash Live, and 36% for GPT Realtime 1.5.
The most dramatic gap appears in Telecom: plan changes, billing disputes, and technical troubleshooting — where grok-voice-think-fast-1.0 achieves 73.7%, while Grok Voice Fast 1.0 scores 40.4%, Gemini 3.1 Flash Live 21.9%, and GPT Realtime 1.5 21.1%. A 33-percentage-point lead over the next competitor in a single vertical is not a marginal improvement. That is an architectural advantage.
One of the most technically significant design decisions in this model is how reasoning is handled. grok-voice-think-fast-1.0 performs reasoning in the background, thinking through challenging queries and workflows in real time with no impact on response latency. For AI teams, this is the difficult part to build: reasoning models traditionally increase response time because they generate intermediate ‘thinking’ tokens before producing an answer. Hiding that computation from the conversational latency budget, while still benefiting from it, requires careful architecture work.
The practical payoff is accuracy without sluggishness. xAI team demonstrates this with a representative edge case: when asked “Which months of the year are spelled with the letter X?”, grok-voice-think-fast-1.0 correctly responds that no month contains the letter X. On the other hand, the competing models confidently and incorrectly answered “February.” This class of error, where a model produces a plausible-sounding but wrong answer with high confidence, is particularly damaging in voice interfaces because users have no text output to cross-check.
A core workflow capability of grok-voice-think-fast-1.0 is structured data capture and read-back. The model can seamlessly collect email addresses, physical street addresses, phone numbers, full names, account numbers, and other structured data, even when information is spoken quickly or with a strong accent. It gracefully handles speech disfluencies and accepts natural corrections as a human would, then reads back the confirmed data to the user.
xAI illustrates this with a concrete example. A caller says: “Yep, it’s 1410, uh wait, 1450 Page Mill Street. Actually no sorry, that’s Page Mill Road.” The model processes the spoken corrections in real time, invokes a search_address tool with the corrected parameter "1450 Page Mill Rd", and reads back the normalized address for user confirmation. Data teams who has spent time building post-call cleanup pipelines to extract structured fields from messy transcripts, this native capture-and-read-back capability represents a meaningful reduction in downstream processing complexity.
The model has been battle-tested in the toughest real-world conditions: telephony audio, background noise, heavy accents, and frequent interruptions. It natively supports 25+ languages, making it ideal for global deployments across use cases including customer support, phone sales, appointment booking, and restaurant reservations.
The most compelling validation of grok-voice-think-fast-1.0 is not the benchmark alone but it’s live deployment. Grok Voice powers the full phone sales and customer support operation for Starlink at +1 (888) GO STARLINK. The numbers xAI discloses from this deployment are operationally significant: a 20% sales conversion rate (meaning one in five callers making a sales inquiry purchases Starlink service while on the phone with Grok), a 70% autonomous resolution rate for customer support inquiries with no human in the loop, and a single agent operating across 28 distinct tools spanning hundreds of support and sales workflows.
Check out the Documentation and Official Release. Also, feel free to follow us on Twitter and don’t forget to join our 130k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。