



Mistral AI has been quietly building one of the more practical coding agent ecosystems in the open-source/weights AI space, and they are shipping its most significant infrastructure upgrade yet. Mistral team announced remote agents in Vibe, its coding agent platform, alongside the public preview of Mistral Medium 3.5 — a new 128B dense model that now serves as the default model in both Vibe and Le Chat, Mistral’s consumer assistant.
If you haven’t used it yet, Mistral Vibe is a coding agent accessible through a CLI (command-line interface) that lets an AI model work through software tasks on your behalf — writing code, refactoring modules, generating tests, investigating CI failures, and more. Think of it as a junior developer that never gets tired and can operate across your codebase.
Until now, Vibe sessions ran locally, meaning the agent was tied to your laptop and your terminal. That changes today.
So, basically now coding sessions can work through long tasks while you’re away. Many can run in parallel, and you stop being the bottleneck on every step the agent takes.
This is the key behavioral shift. Instead of babysitting a coding session in your terminal, you kick off a task and let the cloud handle the rest. You can start cloud agents from the Mistral Vibe CLI or from Le Chat. While they run, you can inspect what the agent is doing, with file diffs, tool calls, progress states, and questions surfaced as you go.
One particularly useful feature for developers already mid-session: ongoing local CLI sessions can be teleported up to the cloud when you want to leave them running, with session history, task state, and approvals carrying across. So you don’t lose your place — you just move the work off your machine.
Each session runs in isolation. Each coding session runs in an isolated sandbox, including broad edits and installs. When the work is done, the agent can open a pull request on GitHub and notify you, so you review the result instead of every keystroke that produced it.
It’s also worth understanding the logic behind how Vibe connects to Le Chat. Mistral uses Workflows orchestrated in Mistral Studio to bring Mistral Vibe into Le Chat — originally built for their own in-house coding environment, then for enterprise customers, and now open to everyone. This means the remote coding agent in Le Chat is not a standalone feature — it’s built on top of Mistral’s own orchestration layer, which is useful context if you’re thinking about how to architect similar agentic systems yourself.
On the integration side, Vibe plugs into GitHub for code and pull requests, Linear and Jira for issues, Sentry for incidents, and apps like Slack or Teams for reporting.
None of this would be practically possible without a capable underlying AI model. This new released model is Mistral Medium 3.5, which Mistral team describes as its first flagship merged model.
It is a dense 128B model with a 256k context window, handling instruction-following, reasoning, and coding in a single set of weights. For context, a 256k context window means the model can process roughly 200,000 words in a single pass — long enough to reason across an entire large codebase.
The model is also multimodal. Mistral team trained the vision encoder from scratch to handle variable image sizes and aspect ratios — a notable architectural choice. Most vision-language models reuse pretrained encoders like CLIP, so building this component from scratch suggests Mistral prioritized flexibility in how the model handles real-world image inputs rather than defaulting to fixed-resolution assumptions.
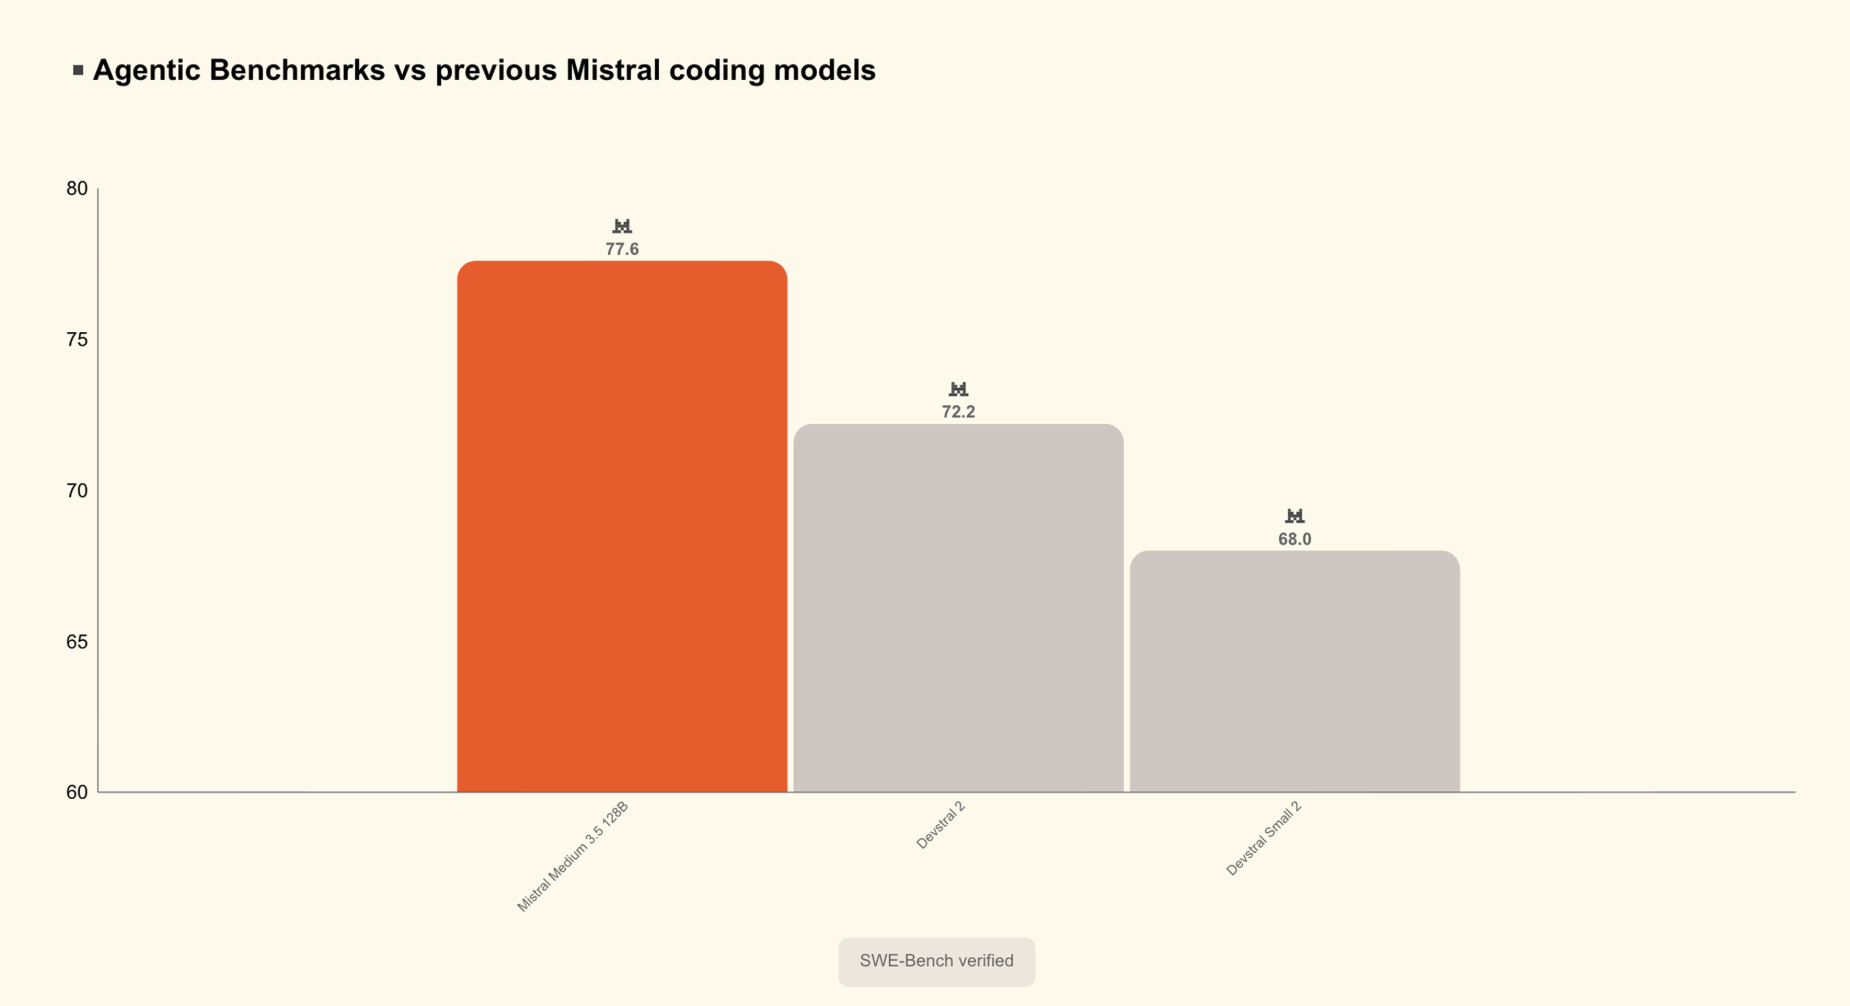
Mistral Medium 3.5 scores 77.6% on SWE-Bench Verified, ahead of Devstral 2 and models like Qwen3.5 397B A17B. SWE-Bench Verified is a standard benchmark that tests whether a model can resolve real-world GitHub issues from popular open-source repositories — it’s one of the most reliable proxies for practical software engineering ability. The model also scores 91.4 on τ³-Telecom and has strong agentic capabilities.
One particularly interesting design choice: reasoning effort is now configurable per request, so the same model can answer a quick chat reply or work through a complex agentic run. This is important for developers integrating the model via API — you can dial down compute for simple lookups and dial it up for multi-step reasoning tasks, without switching models.
The model was built for long-horizon tasks, calling multiple tools reliably, and producing structured output that downstream code can consume.
Beyond the coding agent upgrades, Mistral is also shipping Work mode in Le Chat — a new agentic mode for more general, multi-step tasks. Work mode is a powerful new agentic mode for complex tasks in Le Chat, powered by a new harness and Mistral Medium 3.5. The agent becomes the execution backend for the assistant itself, so Le Chat can read and write, use several tools at once, and work through multi-step projects until it completes what you’ve asked.
Practically, this means things like cross-tool workflows — catching up across email, messages, and calendar; preparing for a meeting with relevant context pulled from multiple sources; or triaging an inbox and creating Jira issues from team discussions.
In Work mode, connectors are on by default rather than chosen manually, which lets the agent reach into documents, mailboxes, calendars, and other systems for the rich context it needs to take correct action. This is a significant usability shift from typical chat assistants, where you manually select tools before each session.
Transparency is a built-in feature rather than an afterthought: every action the agent takes is visible — you see each tool call and the thinking rationale. Le Chat will ask for explicit approval — based on your permissions — before proceeding with sensitive tasks like sending a message, writing a document, or modifying data.
Here are the key takeaways:
Check out the Model Weights on HF and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 130k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。