惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

月光博客
月光博客
J
Java Code Geeks
F
Fortinet All Blogs
Blog — PlanetScale
Blog — PlanetScale
P
Proofpoint News Feed
U
Unit 42
B
Blog
宝玉的分享
宝玉的分享
腾讯CDC
Microsoft Azure Blog
酷 壳 – CoolShell
酷 壳 – CoolShell
Last Week in AI
Last Week in AI
博客园 - Franky
博客园 - 三生石上(FineUI控件)
人人都是产品经理
人人都是产品经理
Martin Fowler
Martin Fowler
博客园_首页
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
云风的 BLOG
云风的 BLOG
L
LangChain Blog
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
Y
Y Combinator Blog
The GitHub Blog
The GitHub Blog
博客园 - 叶小钗

MarkTechPost

A Coding Implementation of End-to-End Brain Decoding from MEG Signals Using NeuralSet and Deep Learning for Predicting Linguistic Features Meta Introduces Autodata: An Agentic Framework That Turns AI Models into Autonomous Data Scientists for High-Quality Training Data Creation A Coding Guide on LLM Post Training with TRL from Supervised Fine Tuning to DPO and GRPO Reasoning Qwen AI Releases Qwen-Scope: An Open-Source Sparse AutoEncoders (SAE) Suite That Turns LLM Internal Features into Practical Development Tools A Coding Deep Dive into Agentic UI, Generative UI, State Synchronization, and Interrupt-Driven Approval Flows Moonshot AI Open-Sources FlashKDA: CUTLASS Kernels for Kimi Delta Attention with Variable-Length Batching and H20 Benchmarks Microsoft Research’s World-R1 Uses Flow-GRPO and 3D-Aware Rewards to Inject Geometric Consistency Into Wan 2.1 Without Architectural Changes A Coding Implementation on Pyright Type Checking Covering Generics, Protocols, Strict Mode, Type Narrowing, and Modern Python Typing IBM Releases Two Granite Speech 4.1 2B Models: Autoregressive ASR with Translation and Non-Autoregressive Editing for Fast Inference Top 10 KV Cache Compression Techniques for LLM Inference: Reducing Memory Overhead Across Eviction, Quantization, and Low-Rank Methods Qwen Team Releases FlashQLA: a High-Performance Linear Attention Kernel Library That Achieves Up to 3× Speedup on NVIDIA Hopper GPUs Step by Step Guide to Build a Complete PII Detection and Redaction Pipeline with OpenAI Privacy Filter Meta FAIR Releases NeuralSet: A Python Package for Neuro-AI That Supports fMRI, M/EEG, Spikes, and HuggingFace Embeddings smol-audio: A Colab-Friendly Notebook Collection for Fine-Tuning Whisper, Parakeet, Voxtral, Granite Speech, and Audio Flamingo 3 A Coding Implementation on Document Parsing Benchmarking with LlamaIndex ParseBench Using Python, Hugging Face, and Evaluation Metrics Poolside AI Introduces Laguna XS.2 and M.1: Agentic Coding Models Reaching 68.2% and 72.5% on SWE-bench Verified How to Build Traceable and Evaluated LLM Workflows Using Promptflow, Prompty, and OpenAI OpenAI Releases Privacy Filter: A 1.5B-Parameter Open-Source PII Redaction Model with 50M Active Parameters Top 10 Physical AI Models Powering Real-World Robots in 2026 How to Build a Lightweight Vision-Language-Action-Inspired Embodied Agent with Latent World Modeling and Model Predictive Control Meet Talkie-1930: A 13B Open-Weight LLM Trained on Pre-1931 English Text for Historical Reasoning and Generalization Research Build a Reinforcement Learning Powered Agent that Learns to Retrieve Relevant Long-Term Memories for Accurate LLM Question Answering OpenMOSS Releases MOSS-Audio: An Open-Source Foundation Model for Speech, Sound, Music, and Time-Aware Audio Reasoning Meta AI Releases Sapiens2: A High-Resolution Human-Centric Vision Model for Pose, Segmentation, Normals, Pointmap, and Albedo The LoRA Assumption That Breaks in Production How to Build a Fully Searchable AI Knowledge Base with OpenKB, OpenRouter, and Llama How to Build Smarter Multilingual Text Wrapping with BudouX Through Parsing, HTML Rendering, Model Introspection, and Toy Training Top 7 Benchmarks That Actually Matter for Agentic Reasoning in Large Language Models RAG Without Vectors: How PageIndex Retrieves by Reasoning A Coding Tutorial on Datashader on Rendering Massive Datasets with High-Performance Python Visual Analytics
TinyFish AI Releases Full Web Infrastructure Platform for...
Asif Razzaq · 2026-04-15 · via MarkTechPost

AI agents struggle with tasks that require interacting with the live web — fetching a competitor’s pricing page, extracting structured data from a JavaScript-heavy dashboard, or automating a multi-step workflow on a real site. The tooling has been fragmented, requiring teams to stitch together separate providers for search, browser automation, and content retrieval.

TinyFish, a Palo Alto-based startup that previously shipped a standalone web agent, is launching what it describes as the complete infrastructure platform for AI agents operating on the live web. This launch introduces four products unified under a single API key and a single credit system: Web Agent, Web Search, Web Browser, and Web Fetch.

What TinyFish is Shipping

Here is what each product does:

  • Web Agent — Executes autonomous multi-step workflows on real websites. The agent navigates sites, fills forms, clicks through flows, and returns structured results without requiring manually scripted steps.
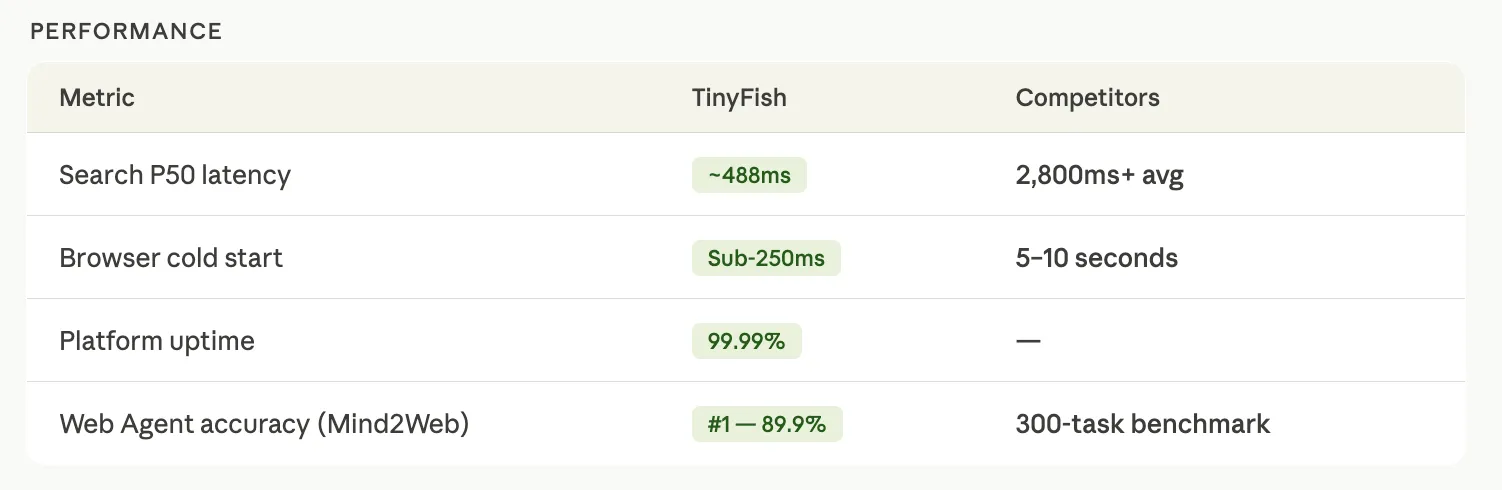
  • Web Search — Returns structured search results as clean JSON using a custom Chromium engine, with a P50 latency of approximately 488ms. Competitors in this space average over 2,800ms for the same operation.
  • Web Browser — Provides managed stealth Chrome sessions via the Chrome DevTools Protocol (CDP), with a sub-250ms cold start. Competitors typically take 5–10 seconds. The browser includes 28 anti-bot mechanisms built at the C++ level — not via JavaScript injection, which is the more common and more detectable approach.
  • Web Fetch — Converts any URL into clean Markdown, HTML, or JSON with full browser rendering. Unlike the native fetch tools built into many AI coding agents, TinyFish Fetch strips irrelevant markup — CSS, scripts, navigation, ads, footers — and returns only the content the agent needs.

The Token Problem in Agent Pipelines

One of the consistent performance problems in agent pipelines is context window pollution. When an AI agent uses a standard web fetch tool, it typically pulls the entire page — including thousands of tokens of navigation elements, ad code, and boilerplate markup — and puts all of it into the model’s context window before reaching the actual content.

TinyFish Fetch addresses this by rendering the page in a full browser and returning only the clean text content as Markdown or JSON. The company’s benchmarks show CLI-based operations using approximately 100 tokens per operation versus roughly 1,500 tokens when routing the same workflow over MCP — an 87% reduction per operation.

Beyond token count, there is an architectural difference worth understanding: MCP operations return output directly into the agent’s context window. The TinyFish CLI writes output to the filesystem, and the agent reads only what it needs. This keeps the context window clean across multi-step tasks and enables composability through native Unix pipes and redirects — something that is not possible with sequential MCP round-trips.

On complex multi-step tasks, TinyFish reports 2× higher task completion rates using CLI + Skills compared to MCP-based execution.

The CLI and Agent Skill System

TinyFish is shipping two developer-facing components alongside the API endpoints.

The CLI installs with a single command:

npm install -g @tiny-fish/cli

This gives terminal access to all four endpoints — Search, Fetch, Browser, and Agent — directly from the command line.

The Agent Skill is a markdown instruction file (SKILL.md) that teaches AI coding agents — including Claude Code, Cursor, Codex, OpenClaw, and OpenCode — how to use the CLI. Install it with:

npx skills add https://github.com/tinyfish-io/skills --skill tinyfish

Once installed, the agent learns when and how to call each TinyFish endpoint without manual SDK integration or configuration. A developer can ask their coding agent to “get competitor pricing from these five sites,” and the agent autonomously recognizes the TinyFish skill, calls the appropriate CLI commands, and writes structured output to the filesystem — without the developer writing integration code.

The company also notes that MCP remains supported. The positioning is that MCP is suited for discovery, while CLI + Skills is the recommended path for heavy-duty, multi-step web execution.

Why a Unified Stack?

TinyFish built Search, Fetch, Browser, and Agent entirely in-house. This is a meaningful distinction from some competitors. For example, Browserbase uses Exa to power its Search endpoint, meaning that layer is not proprietary. Firecrawl offers search, crawl, and an agent endpoint, but the agent endpoint has reliability issues on many tasks.

The infrastructure argument is not only about avoiding vendor dependencies. When every layer of the stack is owned by the same team, the system can optimize for a single outcome: whether the task completed. When TinyFish’s agent succeeds or fails using its own search and fetch, the company gets end-to-end signal at every step — what was searched, what was fetched, and exactly where failures occurred. Companies whose search or fetch layer runs on a third-party API do not have access to this signal.

There is also a practical cost that teams integrating multiple providers encounter. Search finds a page the fetch layer cannot render. Fetch returns content the agent cannot parse. Browser sessions drop context between steps. The result is custom glue code, retry logic, fallback handlers, and validation layers — engineering work that adds up. A unified stack removes the component boundaries where these failures occur.

The platform also maintains session consistency across steps: same IP, same fingerprint, same cookies throughout a workflow. Separate tools operating independently appear to a target site as multiple unrelated clients, which increases the likelihood of detection and session failure.
Key Metrics

Key Takeaways

  • TinyFish moves from a single web agent to a four-product platform — Web Agent, Web Search, Web Browser, and Web Fetch — all accessible under one API key and one credit system, eliminating the need to manage multiple providers.
  • The CLI + Agent Skill combination lets AI coding agents use the live web autonomously — install once and agents like Claude Code, Cursor, and Codex automatically know when and how to call each TinyFish endpoint, with no manual integration code.
  • CLI-based operations produce 87% fewer tokens per task than MCP, and write output directly to the filesystem instead of dumping it into the agent’s context window — keeping context clean across multi-step workflows.
  • Every layer of the stack — Search, Fetch, Browser, and Agent — is built in-house, giving end-to-end signals when a task succeeds or fails, a data feedback loop that cannot be replicated by assembling third-party APIs.
  • TinyFish maintains a single session identity across an entire workflow — same IP, fingerprint, and cookies — whereas separate tools appear to target sites as multiple unrelated clients, increasing detection risk and failure rates.

Getting Started

TinyFish offers 500 free steps with no credit card required at tinyfish.ai. The open-source cookbook and Skill files are available at github.com/tinyfish-io/tinyfish-cookbook, and CLI documentation is at docs.tinyfish.ai/cli.


Note: Thanks for the leadership at Tinyfish for supporting and providing details for this article.