




惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

J
Java Code Geeks
博客园 - 司徒正美
博客园 - 【当耐特】
爱范儿
爱范儿
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
IT之家
IT之家
人人都是产品经理
人人都是产品经理
雷峰网
雷峰网
酷 壳 – CoolShell
酷 壳 – CoolShell
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
大猫的无限游戏
大猫的无限游戏
月光博客
月光博客
宝玉的分享
宝玉的分享
V
V2EX
S
SegmentFault 最新的问题
V
Visual Studio Blog
阮一峰的网络日志
阮一峰的网络日志
Martin Fowler
Martin Fowler
Jina AI
Jina AI
让小产品的独立变现更简单 - ezindie.com
博客园_首页
L
LangChain Blog
D
Docker
腾讯CDC

MarkTechPost

A Coding Implementation of End-to-End Brain Decoding from MEG Signals Using NeuralSet and Deep Learning for Predicting Linguistic Features Meta Introduces Autodata: An Agentic Framework That Turns AI Models into Autonomous Data Scientists for High-Quality Training Data Creation A Coding Guide on LLM Post Training with TRL from Supervised Fine Tuning to DPO and GRPO Reasoning Qwen AI Releases Qwen-Scope: An Open-Source Sparse AutoEncoders (SAE) Suite That Turns LLM Internal Features into Practical Development Tools A Coding Deep Dive into Agentic UI, Generative UI, State Synchronization, and Interrupt-Driven Approval Flows Moonshot AI Open-Sources FlashKDA: CUTLASS Kernels for Kimi Delta Attention with Variable-Length Batching and H20 Benchmarks Microsoft Research’s World-R1 Uses Flow-GRPO and 3D-Aware Rewards to Inject Geometric Consistency Into Wan 2.1 Without Architectural Changes A Coding Implementation on Pyright Type Checking Covering Generics, Protocols, Strict Mode, Type Narrowing, and Modern Python Typing IBM Releases Two Granite Speech 4.1 2B Models: Autoregressive ASR with Translation and Non-Autoregressive Editing for Fast Inference Top 10 KV Cache Compression Techniques for LLM Inference: Reducing Memory Overhead Across Eviction, Quantization, and Low-Rank Methods Qwen Team Releases FlashQLA: a High-Performance Linear Attention Kernel Library That Achieves Up to 3× Speedup on NVIDIA Hopper GPUs Step by Step Guide to Build a Complete PII Detection and Redaction Pipeline with OpenAI Privacy Filter Meta FAIR Releases NeuralSet: A Python Package for Neuro-AI That Supports fMRI, M/EEG, Spikes, and HuggingFace Embeddings smol-audio: A Colab-Friendly Notebook Collection for Fine-Tuning Whisper, Parakeet, Voxtral, Granite Speech, and Audio Flamingo 3 A Coding Implementation on Document Parsing Benchmarking with LlamaIndex ParseBench Using Python, Hugging Face, and Evaluation Metrics Poolside AI Introduces Laguna XS.2 and M.1: Agentic Coding Models Reaching 68.2% and 72.5% on SWE-bench Verified How to Build Traceable and Evaluated LLM Workflows Using Promptflow, Prompty, and OpenAI OpenAI Releases Privacy Filter: A 1.5B-Parameter Open-Source PII Redaction Model with 50M Active Parameters Top 10 Physical AI Models Powering Real-World Robots in 2026 How to Build a Lightweight Vision-Language-Action-Inspired Embodied Agent with Latent World Modeling and Model Predictive Control Meet Talkie-1930: A 13B Open-Weight LLM Trained on Pre-1931 English Text for Historical Reasoning and Generalization Research Build a Reinforcement Learning Powered Agent that Learns to Retrieve Relevant Long-Term Memories for Accurate LLM Question Answering OpenMOSS Releases MOSS-Audio: An Open-Source Foundation Model for Speech, Sound, Music, and Time-Aware Audio Reasoning Meta AI Releases Sapiens2: A High-Resolution Human-Centric Vision Model for Pose, Segmentation, Normals, Pointmap, and Albedo The LoRA Assumption That Breaks in Production How to Build a Fully Searchable AI Knowledge Base with OpenKB, OpenRouter, and Llama How to Build Smarter Multilingual Text Wrapping with BudouX Through Parsing, HTML Rendering, Model Introspection, and Toy Training Top 7 Benchmarks That Actually Matter for Agentic Reasoning in Large Language Models RAG Without Vectors: How PageIndex Retrieves by Reasoning A Coding Tutorial on Datashader on Rendering Massive Datasets with High-Performance Python Visual Analytics
xAI Launches Standalone Grok Speech-to-Text and Text-to-S...
Michal Sutte · 2026-04-19 · via MarkTechPost

Elon Musk’s AI company xAI has launched two standalone audio APIs — a Speech-to-Text (STT) API and a Text-to-Speech (TTS) API — both built on the same infrastructure that powers Grok Voice on mobile apps, Tesla vehicles, and Starlink customer support. The release moves xAI squarely into the competitive speech API market currently occupied by ElevenLabs, Deepgram, and AssemblyAI.

What Is the Grok Speech-to-Text API?

Speech-to-Text is the technology that converts spoken audio into written text. For developers building meeting transcription tools, voice agents, call center analytics, or accessibility features, an STT API is a core building block. Rather than developing this from scratch, developers call an endpoint, send audio, and receive a structured transcript in return.

The Grok STT API is now generally available, offering transcription across 25 languages with both batch and streaming modes. The batch mode is designed for processing pre-recorded audio files, while streaming enables real-time transcription as audio is captured. Pricing is kept straightforward: Speech-to-Text is $0.10 per hour for batch and $0.20 per hour for streaming.

The API includes word-level timestamps, speaker diarization, and multichannel support, along with intelligent Inverse Text Normalization that correctly handles numbers, dates, currencies, and more. It also accepts 12 audio formats — nine container formats (WAV, MP3, OGG, Opus, FLAC, AAC, MP4, M4A, MKV) and three raw formats (PCM, µ-law, A-law), with a maximum file size of 500 MB per request.

Speaker diarization is the process of separating audio by individual speakers — answering the question ‘who said what.’ This is critical for multi-speaker recordings like meetings, interviews, or customer calls. Word-level timestamps assign precise start and end times to each word in the transcript, enabling use cases like subtitle generation, searchable recordings, and legal documentation. Inverse Text Normalization converts spoken forms like ‘one hundred sixty-seven thousand nine hundred eighty-three dollars and fifteen cents’ into readable structured output: “$167,983.15.”.

Benchmark Performance

xAI research team is making strong claims on accuracy. On phone call entity recognition — names, account numbers, dates — Grok STT claims a 5.0% error rate versus ElevenLabs at 12.0%, Deepgram at 13.5%, and AssemblyAI at 21.3%. That is a substantial margin if it holds in production. For video and podcast transcription, Grok and ElevenLabs tied at a 2.4% error rate, with Deepgram and AssemblyAI trailing at 3.0% and 3.2% respectively. xAI team also reports a 6.9% word error rate on general audio benchmarks.
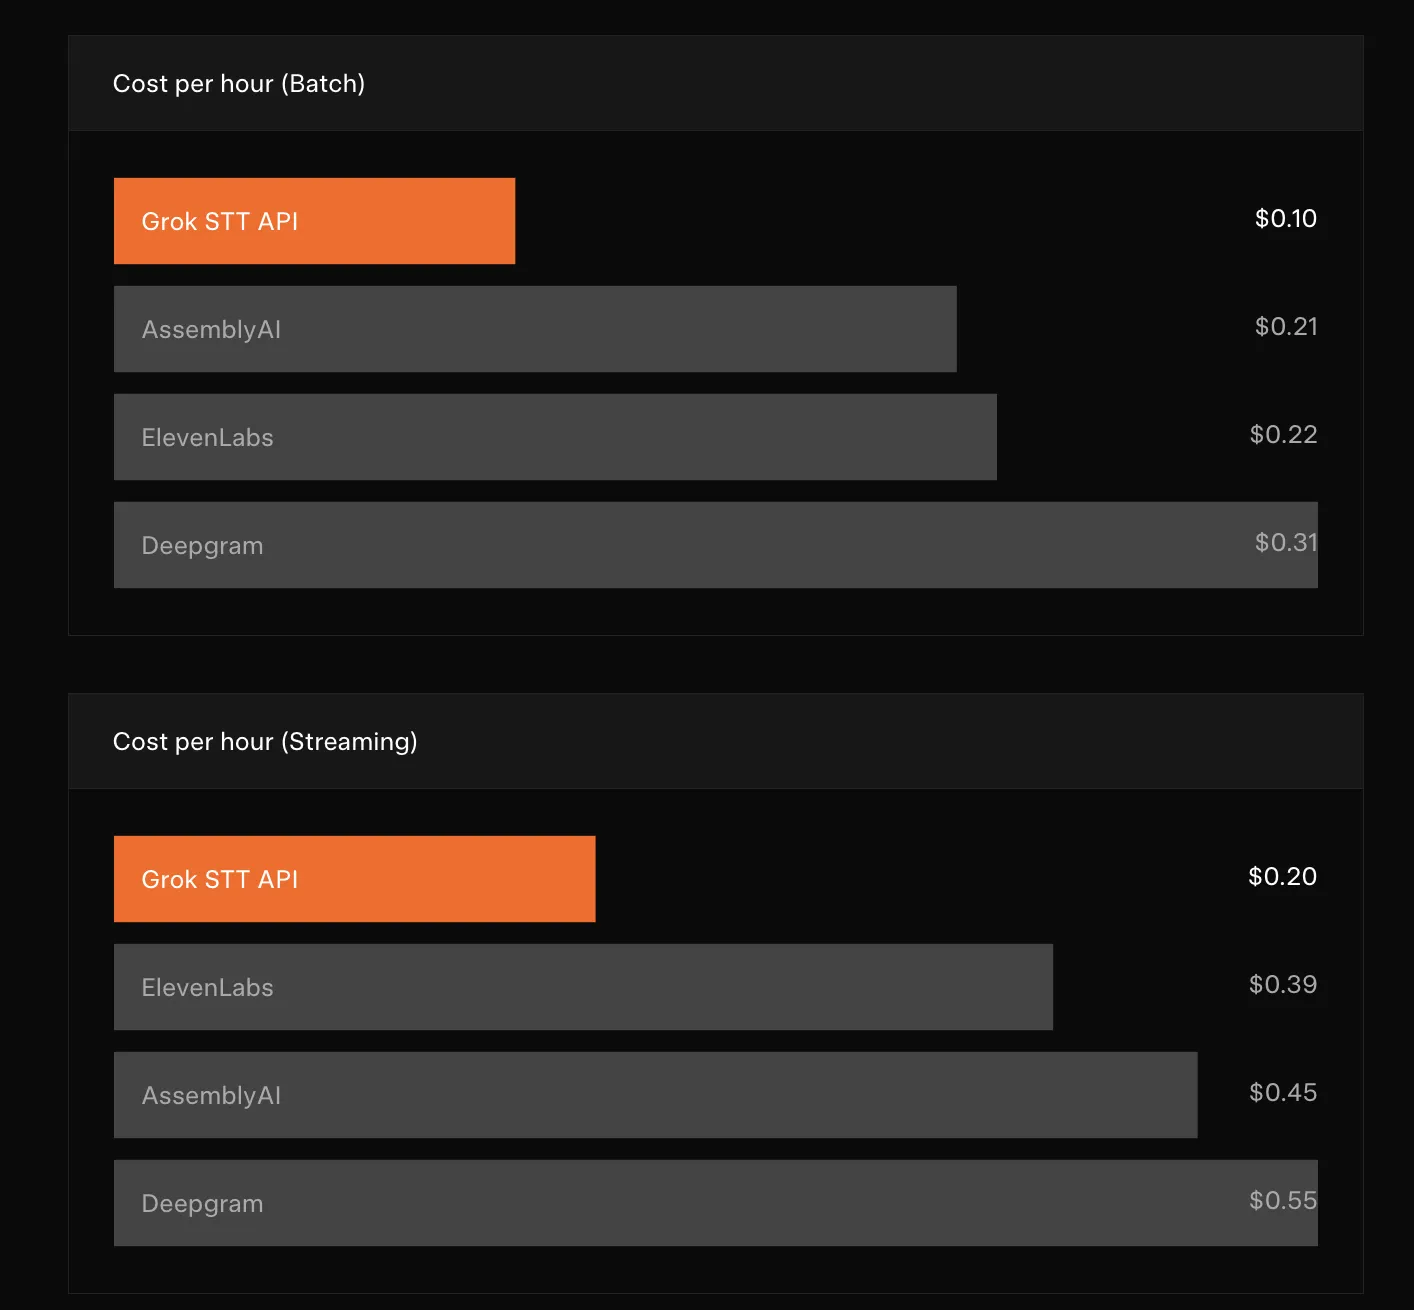
https://x.ai/news/grok-stt-and-tts-apis

What is the Grok Text-to-Speech API?

Text-to-Speech converts written text into spoken audio. Developers use TTS APIs to power voice assistants, read-aloud features, podcast generation, IVR (interactive voice response) systems, and accessibility tools.

The Grok TTS API delivers fast, natural speech synthesis with detailed control via speech tags, and is priced at $4.20 per 1 million characters. The API accepts up to 15,000 characters per REST request; for longer content, a WebSocket streaming endpoint is available that has no text length limit and begins returning audio before the full input is processed. The API supports 20 languages and five distinct voices: Ara, Eve, Leo, Rex, and Sal — with Eve set as the default.

Beyond voice selection, developers can inject inline and wrapping speech tags to control delivery. These include inline tags like [laugh], [sigh], and [breath], and wrapping tags like <whisper>text</whisper> and <emphasis>text</emphasis>, letting developers create engaging, lifelike delivery without complex markup. This expressiveness addresses one of the core limitations of traditional TTS systems, which often produce technically correct but emotionally flat output.

Key Takeaways

  • xAI has launched two standalone audio APIs — Grok Speech-to-Text (STT) and Text-to-Speech (TTS) — built on the same production stack already serving millions of users across Grok mobile apps, Tesla vehicles, and Starlink customer support.
  • The Grok STT API offers real-time and batch transcription across 25 languages with speaker diarization, word-level timestamps, Inverse Text Normalization, and support for 12 audio formats — priced at $0.10/hour for batch and $0.20/hour for streaming.
  • On phone call entity recognition benchmarks, Grok STT reports a 5.0% error rate, significantly outperforming ElevenLabs (12.0%), Deepgram (13.5%), and AssemblyAI (21.3%), with particularly strong performance in medical, legal, and financial use cases.
  • The Grok TTS API supports five expressive voices (Ara, Eve, Leo, Rex, Sal) across 20 languages, with inline and wrapping speech tags like [laugh], [sigh], and <whisper> giving developers fine-grained control over vocal delivery — priced at $4.20 per 1 million characters.

Check out the Technical details here. Also, feel free to follow us on Twitter and don’t forget to join our 130k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.