


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

B
Blog RSS Feed
量子位
Recent Announcements
T
The Blog of Author Tim Ferriss
美团技术团队
Cyber Security Advisories - MS-ISAC
Blog — PlanetScale
Blog — PlanetScale
H
Help Net Security
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
博客园 - Franky
让小产品的独立变现更简单 - ezindie.com
宝玉的分享
宝玉的分享
大猫的无限游戏
大猫的无限游戏
V
Visual Studio Blog
博客园 - 聂微东
aimingoo的专栏
aimingoo的专栏
Microsoft Security Blog
U
Unit 42
J
Java Code Geeks
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
IT之家
IT之家
Hugging Face - Blog
Hugging Face - Blog
腾讯CDC
L
LangChain Blog

MarkTechPost

A Coding Implementation of End-to-End Brain Decoding from MEG Signals Using NeuralSet and Deep Learning for Predicting Linguistic Features Meta Introduces Autodata: An Agentic Framework That Turns AI Models into Autonomous Data Scientists for High-Quality Training Data Creation A Coding Guide on LLM Post Training with TRL from Supervised Fine Tuning to DPO and GRPO Reasoning Qwen AI Releases Qwen-Scope: An Open-Source Sparse AutoEncoders (SAE) Suite That Turns LLM Internal Features into Practical Development Tools A Coding Deep Dive into Agentic UI, Generative UI, State Synchronization, and Interrupt-Driven Approval Flows Moonshot AI Open-Sources FlashKDA: CUTLASS Kernels for Kimi Delta Attention with Variable-Length Batching and H20 Benchmarks Microsoft Research’s World-R1 Uses Flow-GRPO and 3D-Aware Rewards to Inject Geometric Consistency Into Wan 2.1 Without Architectural Changes A Coding Implementation on Pyright Type Checking Covering Generics, Protocols, Strict Mode, Type Narrowing, and Modern Python Typing IBM Releases Two Granite Speech 4.1 2B Models: Autoregressive ASR with Translation and Non-Autoregressive Editing for Fast Inference Top 10 KV Cache Compression Techniques for LLM Inference: Reducing Memory Overhead Across Eviction, Quantization, and Low-Rank Methods Qwen Team Releases FlashQLA: a High-Performance Linear Attention Kernel Library That Achieves Up to 3× Speedup on NVIDIA Hopper GPUs Step by Step Guide to Build a Complete PII Detection and Redaction Pipeline with OpenAI Privacy Filter Meta FAIR Releases NeuralSet: A Python Package for Neuro-AI That Supports fMRI, M/EEG, Spikes, and HuggingFace Embeddings smol-audio: A Colab-Friendly Notebook Collection for Fine-Tuning Whisper, Parakeet, Voxtral, Granite Speech, and Audio Flamingo 3 A Coding Implementation on Document Parsing Benchmarking with LlamaIndex ParseBench Using Python, Hugging Face, and Evaluation Metrics Poolside AI Introduces Laguna XS.2 and M.1: Agentic Coding Models Reaching 68.2% and 72.5% on SWE-bench Verified How to Build Traceable and Evaluated LLM Workflows Using Promptflow, Prompty, and OpenAI OpenAI Releases Privacy Filter: A 1.5B-Parameter Open-Source PII Redaction Model with 50M Active Parameters Top 10 Physical AI Models Powering Real-World Robots in 2026 How to Build a Lightweight Vision-Language-Action-Inspired Embodied Agent with Latent World Modeling and Model Predictive Control Meet Talkie-1930: A 13B Open-Weight LLM Trained on Pre-1931 English Text for Historical Reasoning and Generalization Research Build a Reinforcement Learning Powered Agent that Learns to Retrieve Relevant Long-Term Memories for Accurate LLM Question Answering OpenMOSS Releases MOSS-Audio: An Open-Source Foundation Model for Speech, Sound, Music, and Time-Aware Audio Reasoning Meta AI Releases Sapiens2: A High-Resolution Human-Centric Vision Model for Pose, Segmentation, Normals, Pointmap, and Albedo The LoRA Assumption That Breaks in Production How to Build a Fully Searchable AI Knowledge Base with OpenKB, OpenRouter, and Llama How to Build Smarter Multilingual Text Wrapping with BudouX Through Parsing, HTML Rendering, Model Introspection, and Toy Training Top 7 Benchmarks That Actually Matter for Agentic Reasoning in Large Language Models RAG Without Vectors: How PageIndex Retrieves by Reasoning A Coding Tutorial on Datashader on Rendering Massive Datasets with High-Performance Python Visual Analytics
OpenAI Releases GPT-5.5, a Fully Retrained Agentic Model ...
Michal Sutte · 2026-04-24 · via MarkTechPost

OpenAI has released GPT-5.5, its most capable model to date and the first fully retrained base model since GPT-4.5. GPT-5.5 is designed to complete complex, multi-step computer tasks with minimal human direction. Think of it as the difference between an assistant who needs a checklist and one who understands the underlying goal and figures out the steps themselves. The release is rolling out today to Plus, Pro, Business, and Enterprise subscribers across ChatGPT and Codex.

What ‘Agentic’ Actually Means Here

An agentic model doesn’t just respond to a single prompt — it takes a sequence of actions, uses tools (like browsing the web, writing code, running scripts, or operating software), checks its own work, and keeps going until the task is finished. Prior models often stalled at handoff points, requiring the user to re-prompt or correct course. GPT-5.5 is built to reduce those interruptions.

OpenAI launched GPT-5.5 as a model targeted at agentic computer use — it writes and debugs code, browses the web, fills out spreadsheets, and keeps working through multi-step tasks without requiring a human to supervise every move.

The Four Domains Where Gains Are Concentrated

The gains are concentrated in four areas: agentic coding, computer use, knowledge work, and early scientific research — domains OpenAI describes as those ‘where progress depends on reasoning across context and taking action over time.’

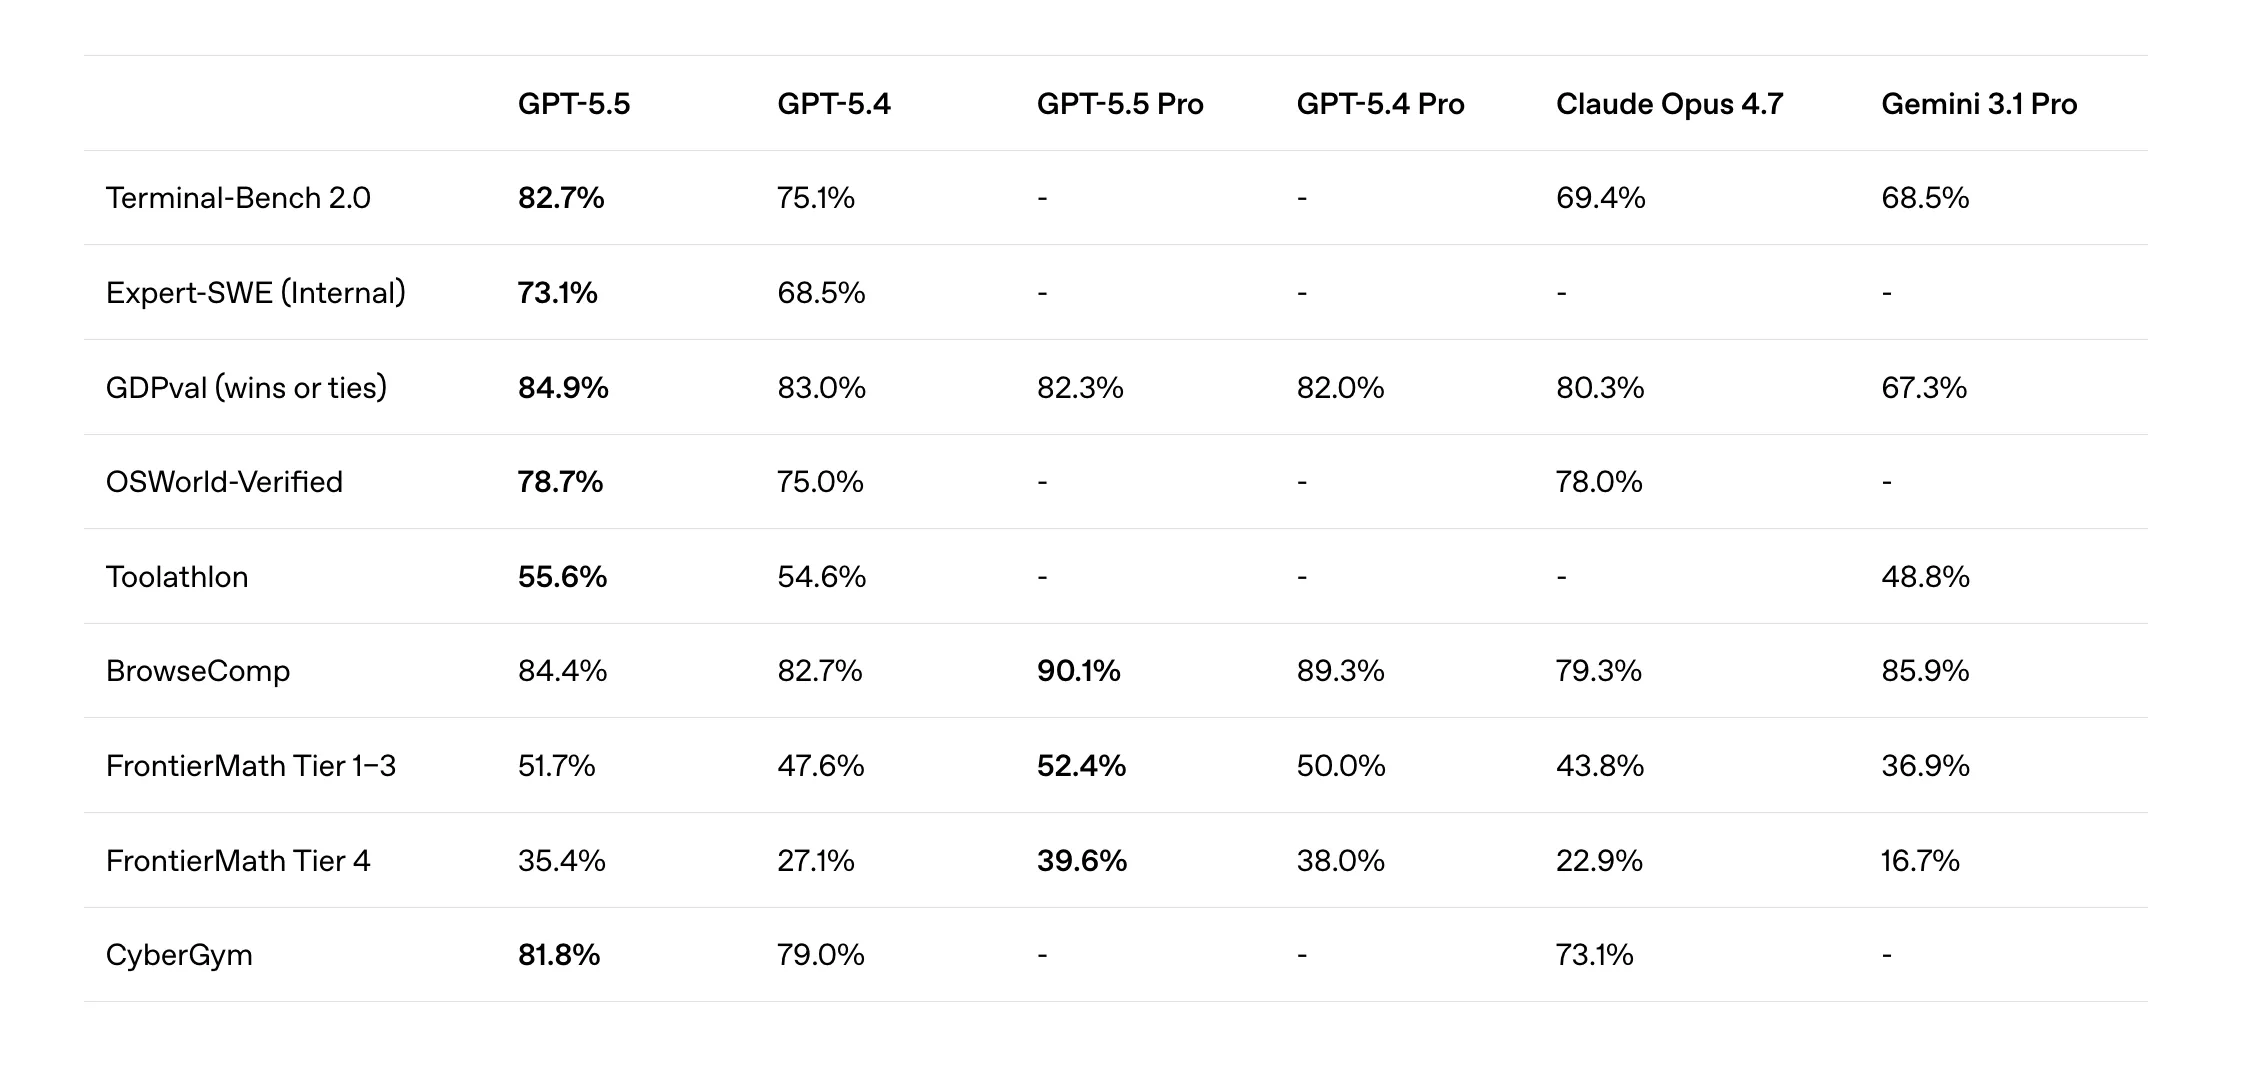
For software engineers, the most immediately relevant benchmark is SWE-Bench Pro, which evaluates real-world GitHub issue resolution across four programming languages. GPT-5.5 resolves 58.6% of tasks end-to-end in a single pass. Worth noting: Claude Opus 4.7 scores higher at 64.3% on this same benchmark, though OpenAI has noted that Anthropic reported signs of memorization on a subset of those problems, which may affect the comparison.

For long-horizon coding specifically, OpenAI also reports results on Expert-SWE, an internal benchmark measuring tasks with a median estimated human completion time of 20 hours. GPT-5.5 outperforms GPT-5.4 on Expert-SWE. This benchmark is significant because it reflects the kind of extended, multi-session engineering work — large refactors, feature builds, debugging deep in a codebase — that agentic tools are increasingly being asked to handle autonomously.

Developers who tested the system early said GPT-5.5 has a better understanding of the “shape” of a software system, and can better understand why something is failing, where the fix is needed, and what else in the codebase would be affected.
https://openai.com/index/introducing-gpt-5-5/

For ML engineers and data scientists who spend significant time in terminal environments orchestrating pipelines and debugging scripts, the Terminal-Bench 2.0 results are the most compelling signal. GPT-5.5 scores 82.7% on Terminal-Bench 2.0, which tests complex command-line workflows requiring planning, iteration, and tool coordination — beating Claude Opus 4.7 at 69.4% and Gemini 3.1 Pro at 68.5%. That is not a marginal lead.

For broader knowledge work, GPT-5.5 scores 84.9% on GDPval, which tests agents across 44 occupations of knowledge work. On OSWorld-Verified, a benchmark measuring whether a model can autonomously operate real computer environments, it reaches 78.7%.

GPT-5.5 also ships with a Pro variant built for higher-accuracy, harder tasks. On BrowseComp, which tests a model’s ability to track down hard-to-find information across the web, GPT-5.5 Pro scores 90.1%, ahead of Gemini 3.1 Pro at 85.9%. The model is also the top-ranked system on the Artificial Analysis Intelligence Index.
https://openai.com/index/introducing-gpt-5-5/

Speed and Token Efficiency

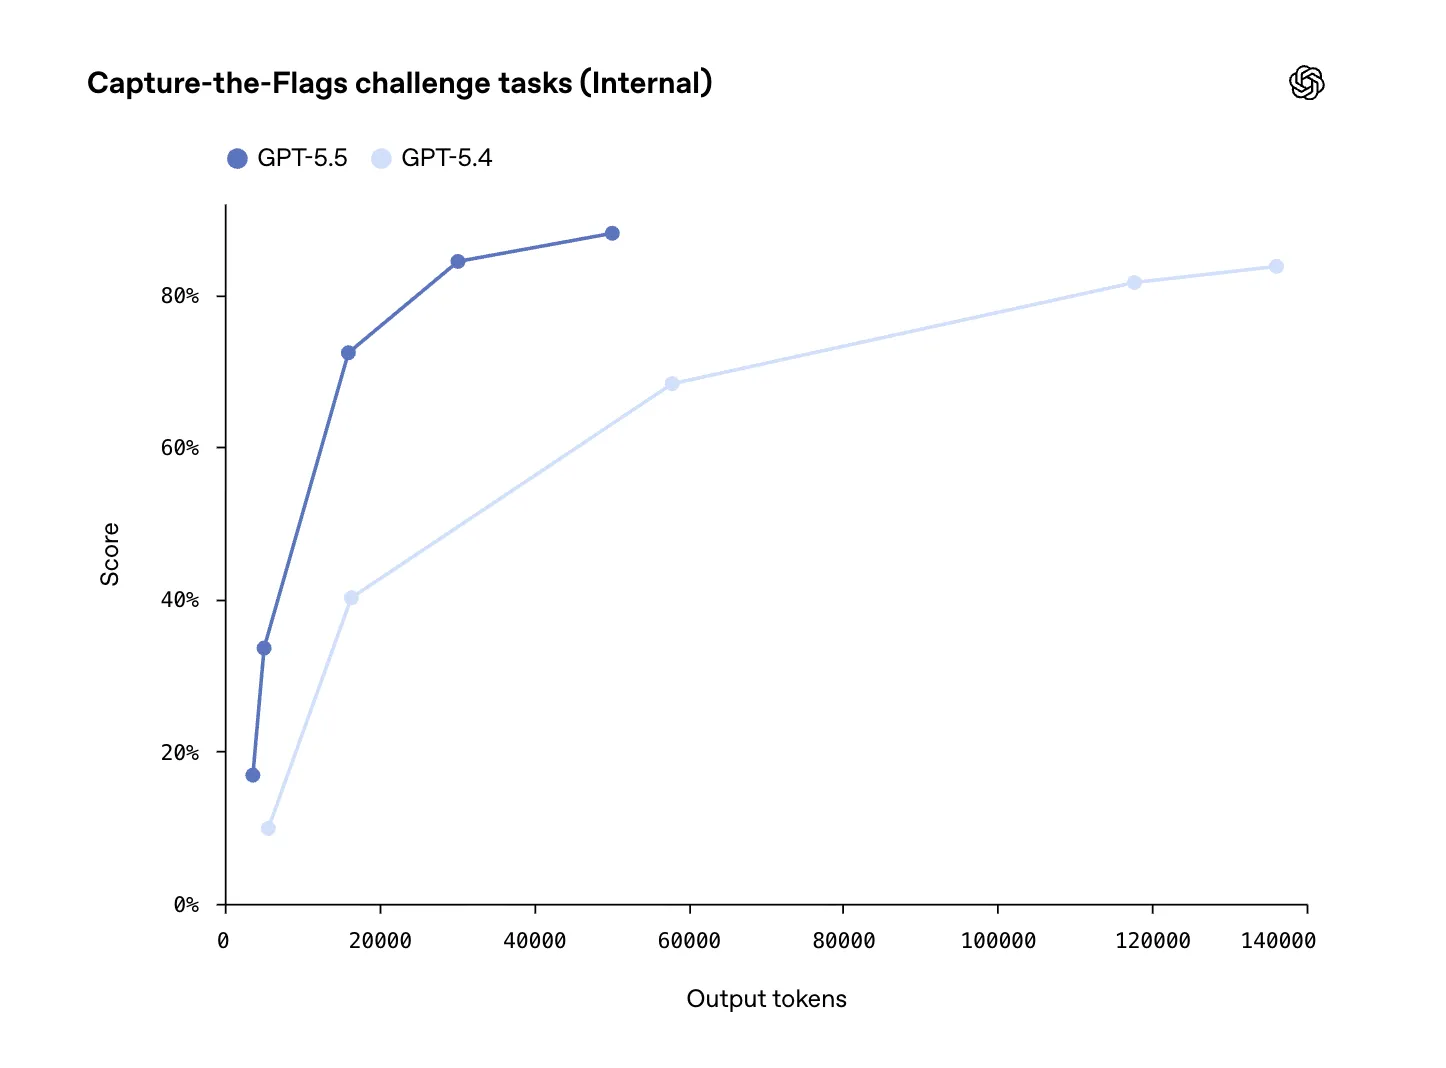
One concern with more capable models is that they tend to be slower or more expensive to run. OpenAI addressed this directly. GPT-5.5 matches GPT-5.4’s per-token latency in real-world serving while performing better across nearly every evaluation measured. It also uses significantly fewer tokens to complete the same Codex tasks — meaning shorter, more efficient runs even on complex agentic workflows.

On pricing, the standard GPT-5.5 API will be charged at $5 per million input tokens and $30 per million output tokens. For context, GPT-5.4 was priced at $2.50 per million input tokens and $15 per million output tokens — so the per-token price has doubled. OpenAI team argued that token efficiency gains offset the cost, since GPT-5.5 completes the same Codex tasks with fewer tokens, meaning cheaper runs overall even at the higher per-token rate. GPT-5.5 Pro, the higher-accuracy variant, is priced at $30 per million input tokens and $180 per million output tokens in the API.

For teams running Codex at scale, the net math is what matters: if GPT-5.5 completes a task in materially fewer tokens than GPT-5.4, the effective cost per completed workflow can still come out lower despite the higher rate.

Scale and Adoption

OpenAI has seen a surge in Codex usage, with about 4 million developers using the tool weekly. That scale matters for understanding the deployment context: GPT-5.5 is not a research preview but a production model being pushed to an active, large developer base immediately on launch.
Key Takeaways

  • GPT-5.5 is OpenAI’s first fully retrained base model since GPT-4.5, designed specifically for agentic workflows — it can understand complex goals, use tools, check its own work, and carry multi-step tasks through to completion with minimal human direction.
  • The biggest performance gains are in agentic coding, computer use, knowledge work, and early scientific research — GPT-5.5 scores 82.7% on Terminal-Bench 2.0, 84.9% on GDPval, and 78.7% on OSWorld-Verified, outperforming both Claude Opus 4.7 and Gemini 3.1 Pro on several key benchmarks.
  • GPT-5.5 matches GPT-5.4’s per-token latency while being more capable across nearly every benchmark — it also uses significantly fewer tokens to complete the same Codex tasks, meaning better results without a proportional increase in speed or cost per completed workflow.
  • API pricing increases to $5/M input tokens and $30/M output tokens (up from $2.50 and $15 for GPT-5.4), with GPT-5.5 Pro priced at $30/M input and $180/M output — OpenAI team argues token efficiency gains offset the higher per-token rate for most workloads.
  • GPT-5.5 is rolling out today to Plus, Pro, Business, and Enterprise users in ChatGPT and Codex, with approximately 4 million developers already using Codex weekly.

Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.