


Writing a research paper is brutal. Even after the experiments are done, a researcher still faces weeks of translating messy lab notes, scattered results tables, and half-formed ideas into a polished, logically coherent manuscript formatted precisely to a conference’s specifications. For many fresh researchers, that translation work is where papers go to die.
A team at Google Cloud AI Research propose ‘PaperOrchestra‘, a multi-agent system that autonomously converts unstructured pre-writing materials — a rough idea summary and raw experimental logs — into a submission-ready LaTeX manuscript, complete with a literature review, generated figures, and API-verified citations.
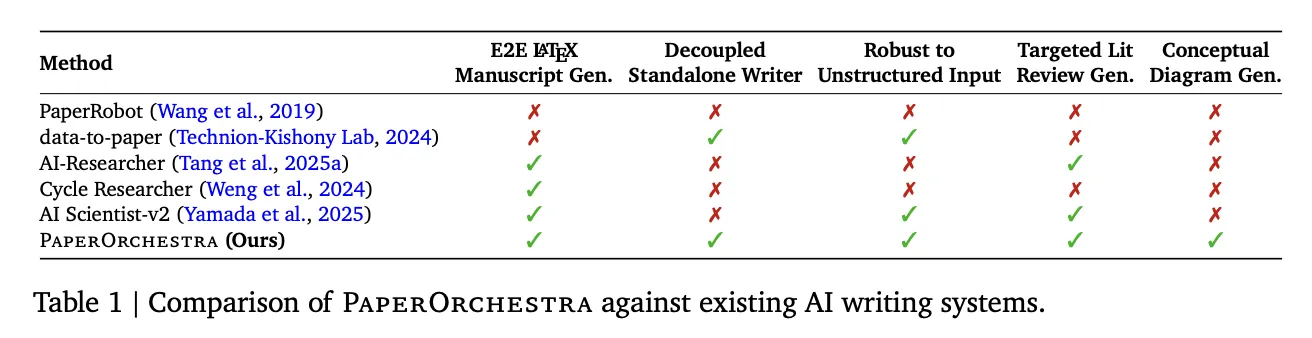
Earlier automated writing systems, like PaperRobot, could generate incremental text sequences but couldn’t handle the full complexity of a data-driven scientific narrative. More recent end-to-end autonomous research frameworks like AI Scientist-v1 (which introduced automated experimentation and drafting via code templates) and its successor AI Scientist-v2 (which increases autonomy using agentic tree-search) automate the entire research loop — but their writing modules are tightly coupled to their own internal experimental pipelines. You can’t just hand them your data and expect a paper. They’re not standalone writers.
Meanwhile, systems specialized in literature reviews, such as AutoSurvey2 and LiRA, produce comprehensive surveys but lack the contextual awareness to write a targeted Related Work section that clearly positions a specific new method against prior art. CycleResearcher requires a pre-existing structured BibTeX reference list as input — an artifact rarely available at the start of writing — and fails entirely on unstructured inputs.
The result is a gap: no existing tool could take unconstrained human-provided materials — the kind of thing a real researcher might actually have after finishing experiments — and produce a complete, rigorous manuscript on its own. PaperOrchestra is built specifically to fill that gap.
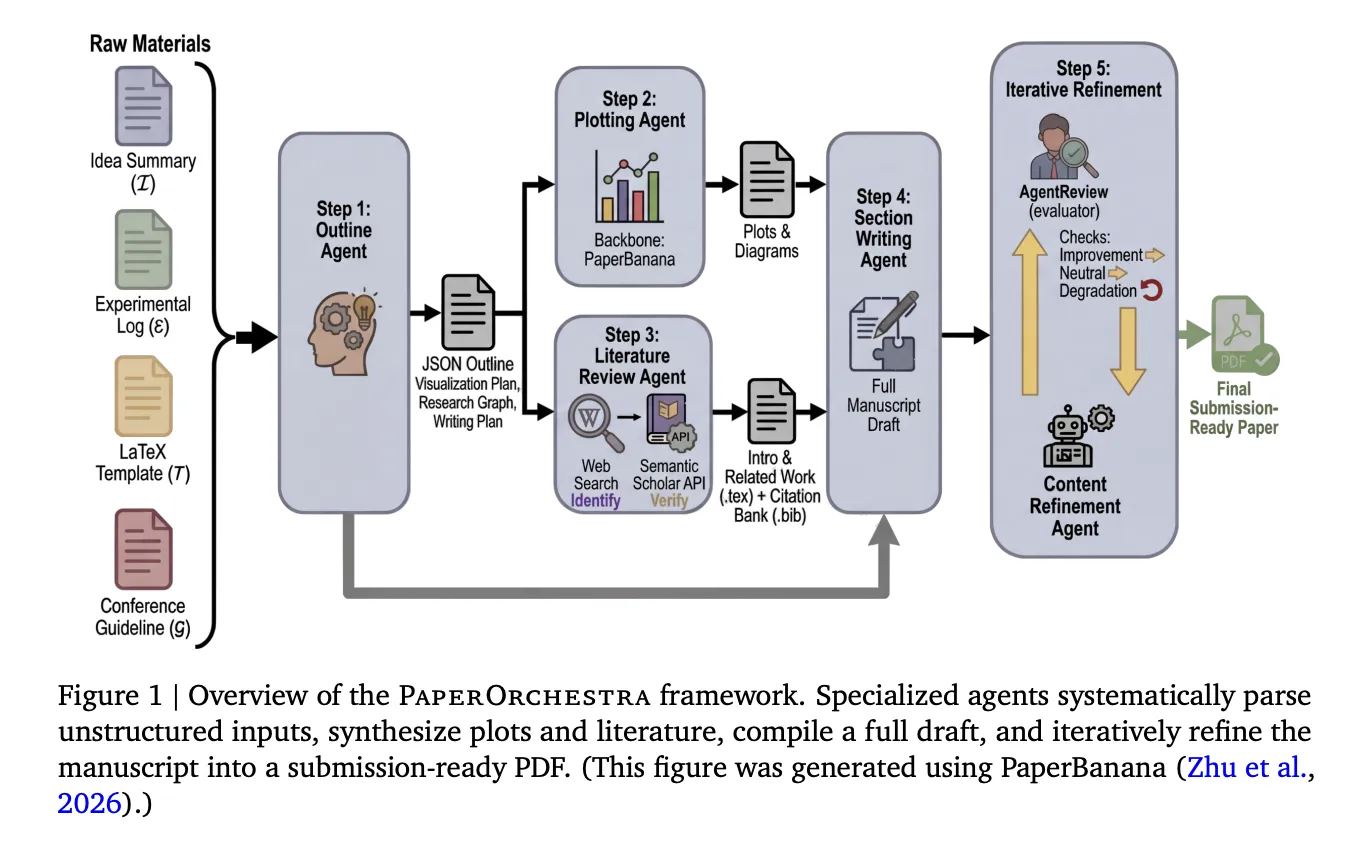
PaperOrchestra orchestrates five specialized agents that work in sequence, with two running in parallel:
Step 1 — Outline Agent: This agent reads the idea summary, experimental log, LaTeX conference template, and conference guidelines, then produces a structured JSON outline. This outline includes a visualization plan (specifying what plots and diagrams to generate), a targeted literature search strategy separating macro-level context for the Introduction from micro-level methodology clusters for the Related Work, and a section-level writing plan with citation hints for every dataset, optimizer, metric, and baseline method mentioned in the materials.
Steps 2 & 3 — Plotting Agent and Literature Review Agent (parallel): The Plotting Agent executes the visualization plan using PaperBanana, an academic illustration tool that uses a Vision-Language Model (VLM) critic to evaluate generated images against design objectives and iteratively revise them. Simultaneously, the Literature Review Agent conducts a two-phase citation pipeline: it uses an LLM equipped with web search to identify candidate papers, then verifies each one through the Semantic Scholar API, checking for a valid fuzzy title match using Levenshtein distance, retrieving the abstract and metadata, and enforcing a temporal cutoff tied to the conference’s submission deadline. Hallucinated or unverifiable references are discarded. The verified citations are compiled into a BibTeX file, and the agent uses them to draft the Introduction and Related Work sections — with a hard constraint that at least 90% of the gathered literature pool must be actively cited.
Step 4 — Section Writing Agent: This agent takes everything generated so far — the outline, the verified citations, the generated figures — and authors the remaining sections: abstract, methodology, experiments, and conclusion. It extracts numeric values directly from the experimental log to construct tables and integrates the generated figures into the LaTeX source.
Step 5 — Content Refinement Agent: Using AgentReview, a simulated peer-review system, this agent iteratively optimizes the manuscript. After each revision, the manuscript is accepted only if the overall AgentReview score increases, or ties with net non-negative sub-axis gains. Any overall score decrease triggers an immediate revert and halt. Ablation results show this step is critical: refined manuscripts dominate unrefined drafts with 79%–81% win rates in automated side-by-side comparisons, and deliver absolute acceptance rate gains of +19% on CVPR and +22% on ICLR in AgentReview simulations.
The full pipeline makes approximately 60–70 LLM API calls and completes in a mean of 39.6 minutes per paper — only about 4.5 minutes more than AI Scientist-v2’s 35.1 minutes, despite running significantly more LLM calls (40–45 for AI Scientist-v2 vs. 60–70 for PaperOrchestra).
The research team also introduce PaperWritingBench, described as the first standardized benchmark specifically for AI research paper writing. It contains 200 accepted papers from CVPR 2025 and ICLR 2025 (100 from each venue), selected to test adaptation to different conference formats — double-column for CVPR versus single-column for ICLR.
For each paper, an LLM was used to reverse-engineer two inputs from the published PDF: a Sparse Idea Summary (high-level conceptual description, no math or LaTeX) and a Dense Idea Summary (retaining formal definitions, loss functions, and LaTeX equations), alongside an Experimental Log derived by extracting all numeric data and converting figure insights into standalone factual observations. All materials were fully anonymized, stripping author names, titles, citations, and figure references.
This design isolates the writing task from any specific experimental pipeline, using real accepted papers as ground truth — and it reveals something important. For Overall Paper Quality, the Dense idea setting substantially outperforms Sparse (43%–56% win rates vs. 18%–24%), since more precise methodology descriptions enable more rigorous section writing. But for Literature Review Quality, the two settings are nearly equal (Sparse: 32%–40%, Dense: 28%–39%), meaning the Literature Review Agent can autonomously identify research gaps and relevant citations without relying on detail-heavy human inputs.
In automated side-by-side (SxS) evaluations using both Gemini-3.1-Pro and GPT-5 as judge models, PaperOrchestra dominated on literature review quality, achieving absolute win margins of 88%–99% over AI baselines. For overall paper quality, it outperformed AI Scientist-v2 by 39%–86% and the Single Agent by 52%–88% across all settings.
Human evaluation — conducted with 11 AI researchers across 180 paired manuscript comparisons — confirmed the automated results. PaperOrchestra achieved absolute win rate margins of 50%–68% over AI baselines in literature review quality, and 14%–38% in overall manuscript quality. It also achieved a 43% tie/win rate against the human-written ground truth in literature synthesis — a notable result for a fully automated system.
The citation coverage numbers tell a particularly clear story. AI baselines averaged only 9.75–14.18 citations per paper, inflating their F1 scores on the must-cite (P0) reference category while leaving “good-to-cite” (P1) recall near zero. PaperOrchestra generated an average of 45.73–47.98 citations, closely mirroring the ~59 citations found in human-written papers, and improved P1 Recall by 12.59%–13.75% over the strongest baselines.
Under the ScholarPeer evaluation framework, PaperOrchestra achieved simulated acceptance rates of 84% on CVPR and 81% on ICLR, compared to human-authored ground truth rates of 86% and 94% respectively. It outperformed the strongest autonomous baseline by absolute acceptance gains of 13% on CVPR and 9% on ICLR.
Notably, even when PaperOrchestra generates its own figures autonomously from scratch (PlotOn mode) rather than using human-authored figures (PlotOff mode), it achieves ties or wins in 51%–66% of side-by-side matchups — despite PlotOff having an inherent information advantage since human-authored figures often embed supplementary results not present in the raw experimental logs.
Check out the Paper and Project Page. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。