


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

量子位
博客园_首页
罗磊的独立博客
云风的 BLOG
云风的 BLOG
J
Java Code Geeks
Last Week in AI
Last Week in AI
D
DataBreaches.Net
Jina AI
Jina AI
博客园 - Franky
大猫的无限游戏
大猫的无限游戏
Apple Machine Learning Research
V
V2EX
D
Docker
MongoDB | Blog
MongoDB | Blog
B
Blog RSS Feed
让小产品的独立变现更简单 - ezindie.com
宝玉的分享
宝玉的分享
Engineering at Meta
Engineering at Meta
The Cloudflare Blog
博客园 - 三生石上(FineUI控件)
有赞技术团队
有赞技术团队
人人都是产品经理
人人都是产品经理
H
Help Net Security
T
The Blog of Author Tim Ferriss

MarkTechPost

A Coding Implementation of End-to-End Brain Decoding from MEG Signals Using NeuralSet and Deep Learning for Predicting Linguistic Features Meta Introduces Autodata: An Agentic Framework That Turns AI Models into Autonomous Data Scientists for High-Quality Training Data Creation A Coding Guide on LLM Post Training with TRL from Supervised Fine Tuning to DPO and GRPO Reasoning Qwen AI Releases Qwen-Scope: An Open-Source Sparse AutoEncoders (SAE) Suite That Turns LLM Internal Features into Practical Development Tools A Coding Deep Dive into Agentic UI, Generative UI, State Synchronization, and Interrupt-Driven Approval Flows Moonshot AI Open-Sources FlashKDA: CUTLASS Kernels for Kimi Delta Attention with Variable-Length Batching and H20 Benchmarks Microsoft Research’s World-R1 Uses Flow-GRPO and 3D-Aware Rewards to Inject Geometric Consistency Into Wan 2.1 Without Architectural Changes A Coding Implementation on Pyright Type Checking Covering Generics, Protocols, Strict Mode, Type Narrowing, and Modern Python Typing IBM Releases Two Granite Speech 4.1 2B Models: Autoregressive ASR with Translation and Non-Autoregressive Editing for Fast Inference Top 10 KV Cache Compression Techniques for LLM Inference: Reducing Memory Overhead Across Eviction, Quantization, and Low-Rank Methods Qwen Team Releases FlashQLA: a High-Performance Linear Attention Kernel Library That Achieves Up to 3× Speedup on NVIDIA Hopper GPUs Step by Step Guide to Build a Complete PII Detection and Redaction Pipeline with OpenAI Privacy Filter Meta FAIR Releases NeuralSet: A Python Package for Neuro-AI That Supports fMRI, M/EEG, Spikes, and HuggingFace Embeddings smol-audio: A Colab-Friendly Notebook Collection for Fine-Tuning Whisper, Parakeet, Voxtral, Granite Speech, and Audio Flamingo 3 A Coding Implementation on Document Parsing Benchmarking with LlamaIndex ParseBench Using Python, Hugging Face, and Evaluation Metrics Poolside AI Introduces Laguna XS.2 and M.1: Agentic Coding Models Reaching 68.2% and 72.5% on SWE-bench Verified How to Build Traceable and Evaluated LLM Workflows Using Promptflow, Prompty, and OpenAI OpenAI Releases Privacy Filter: A 1.5B-Parameter Open-Source PII Redaction Model with 50M Active Parameters Top 10 Physical AI Models Powering Real-World Robots in 2026 How to Build a Lightweight Vision-Language-Action-Inspired Embodied Agent with Latent World Modeling and Model Predictive Control Meet Talkie-1930: A 13B Open-Weight LLM Trained on Pre-1931 English Text for Historical Reasoning and Generalization Research Build a Reinforcement Learning Powered Agent that Learns to Retrieve Relevant Long-Term Memories for Accurate LLM Question Answering OpenMOSS Releases MOSS-Audio: An Open-Source Foundation Model for Speech, Sound, Music, and Time-Aware Audio Reasoning Meta AI Releases Sapiens2: A High-Resolution Human-Centric Vision Model for Pose, Segmentation, Normals, Pointmap, and Albedo The LoRA Assumption That Breaks in Production How to Build a Fully Searchable AI Knowledge Base with OpenKB, OpenRouter, and Llama How to Build Smarter Multilingual Text Wrapping with BudouX Through Parsing, HTML Rendering, Model Introspection, and Toy Training Top 7 Benchmarks That Actually Matter for Agentic Reasoning in Large Language Models RAG Without Vectors: How PageIndex Retrieves by Reasoning A Coding Tutorial on Datashader on Rendering Massive Datasets with High-Performance Python Visual Analytics
Google AI Releases Auto-Diagnose: An Large Language Model...
Asif Razzaq · 2026-04-18 · via MarkTechPost

If you have ever stared at thousands of lines of integration test logs wondering which of the sixteen log files actually contains your bug, you are not alone — and Google now has data to prove it.

A team of Google researchers introduced Auto-Diagnose, an LLM-powered tool that automatically reads the failure logs from a broken integration test, finds the root cause, and posts a concise diagnosis directly into the code review where the failure showed up. On a manual evaluation of 71 real-world failures spanning 39 distinct teams, the tool correctly identified the root cause 90.14% of the time. It has run on 52,635 distinct failing tests across 224,782 executions on 91,130 code changes authored by 22,962 distinct developers, with a ‘Not helpful’ rate of just 5.8% on the feedback received.
https://arxiv.org/pdf/2604.12108

The problem: integration tests are a debugging tax

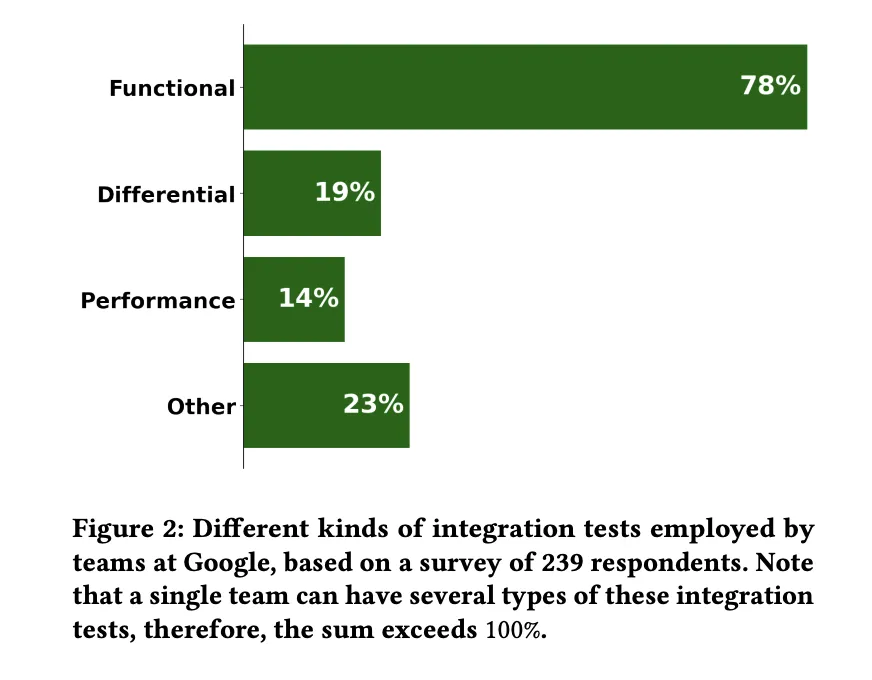
Integration tests verify that multiple components of a distributed system actually communicate to each other correctly. The tests Auto-Diagnose targets are hermetic functional integration tests: tests where an entire system under test (SUT) — typically a graph of communicating servers — is brought up inside an isolated environment by a test driver, and exercised against business logic. A separate Google survey of 239 respondents found that 78% of integration tests at Google are functional, which is what motivated the scope.

Diagnosing integration test failures showed up as one of the top five complaints in EngSat, a Google-wide survey of 6,059 developers. A follow-up survey of 116 developers found that 38.4% of integration test failures take more than an hour to diagnose, and 8.9% take more than a day — versus 2.7% and 0% for unit tests.

The root cause is structural. Test driver logs usually surface only a generic symptom (a timeout, an assertion). The actual error lives somewhere inside one of the SUT component logs, often buried under recoverable warnings and ERROR-level lines that are not actually the cause.

https://arxiv.org/pdf/2604.12108

How Auto-Diagnose works

When an integration test fails, a pub/sub event triggers Auto-Diagnose. The system collects all test driver and SUT component logs at level INFO and above — across data centers, processes, and threads — then joins and sorts them by timestamp into a single log stream. That stream is dropped into a prompt template along with component metadata.

The model is Gemini 2.5 Flash, called with temperature = 0.1 (for near-deterministic, debuggable outputs) and topp = 0.8. Gemini was not fine-tuned on Google’s integration test data; this is pure prompt engineering on a general-purpose model.

The prompt itself is the most instructive part of this research. It walks the model through an explicit step-by-step protocol: scan log sections, read component context, locate the failure, summarize errors, and only then attempt a conclusion. Critically, it includes hard negative constraints — for example: if the logs do not contain lines from the component that failed, do not draw any conclusion.

The model’s response is post-processed into a markdown finding with ==Conclusion==, ==Investigation Steps==, and ==Most Relevant Log Lines== sections, then posted as a comment in Critique, Google’s internal code review system. Each cited log line is rendered as a clickable link.

Numbers from production

Auto-Diagnose averages 110,617 input tokens and 5,962 output tokens per execution, and posts findings with a p50 latency of 56 seconds and p90 of 346 seconds — fast enough that developers see the diagnosis before they have switched contexts.

Critique exposes three feedback buttons on a finding: Please fix (used by reviewers), Helpful, and Not helpful (both used by authors). Across 517 total feedback reports from 437 distinct developers, 436 (84.3%) were “Please fix” from 370 reviewers — by far the dominant interaction, and a sign that reviewers are actively asking authors to act on the diagnoses. Among dev-side feedback, the helpfulness ratio (H / (H + N)) is 62.96%, and the “Not helpful” rate (N / (PF + H + N)) is 5.8% — well under Google’s 10% threshold for keeping a tool live. Across 370 tools that post findings to Critique, Auto-Diagnose ranks #14 in helpfulness, putting it in the top 3.78%.

The manual evaluation also surfaced a useful side effect. Of the seven cases where Auto-Diagnose failed, four were because test driver logs were not properly saved on crash, and three were because SUT component logs were not saved when the component crashed — both real infrastructure bugs, reported back to the relevant teams. In production, around 20 ‘more information is needed‘ diagnoses have similarly helped surface infrastructure issues.

Key Takeaways

  • Auto-Diagnose hit 90.14% root-cause accuracy on a manual evaluation of 71 real-world integration test failures spanning 39 teams at Google, addressing a problem 6,059 developers ranked among their top five complaints in the EngSat survey.
  • The system runs on Gemini 2.5 Flash with no fine-tuning — just prompt engineering. A pub/sub trigger collects logs across data centers and processes, joins them by timestamp, and sends them to the model at temperature 0.1 and topp 0.8.
  • The prompt is engineered to refuse rather than guess. Hard negative constraints force the model to respond with “more information is needed” when evidence is missing — a deliberate trade-off that prevents hallucinated root causes and even helped surface real infrastructure bugs in Google’s logging pipeline.
  • In production since May 2025, Auto-Diagnose has run on 52,635 distinct failing tests across 224,782 executions on 91,130 code changes from 22,962 developers, posting findings in a p50 of 56 seconds — fast enough that engineers see the diagnosis before switching contexts.

Check out the Pre-Print Paper here. Also, feel free to follow us on Twitter and don’t forget to join our 130k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us