





Training frontier AI models is, at its core, a coordination problem. Thousands of chips must communicate with each other continuously, synchronizing every gradient update across the network. When one chip fails or even slows down, the entire training run can stall. As models scale toward hundreds of billions of parameters, that fragility becomes increasingly untenable. Google DeepMind is now proposing a different model entirely.
Google DeepMind researchers introduced Decoupled DiLoCo (Distributed Low-Communication), a distributed training architecture that decouples compute into asynchronous, fault-isolated ‘islands,’ enabling large language model pre-training across geographically distant data centers without requiring the tight synchronization that makes conventional approaches brittle at scale.
To understand why Decoupled DiLoCo is important, it helps to understand how distributed training typically works. Standard Data-Parallel training replicates a model across many accelerators (GPUs or TPUs), each processing a different mini-batch of data. After each forward and backward pass, gradients must be averaged across every device — a process called AllReduce — before the next training step can begin. This blocking synchronization step means every device must wait for the slowest one. Across thousands of chips spanning multiple data centers, that bottleneck is not just inconvenient; it makes global-scale training effectively impractical.
Bandwidth is another hard constraint. Conventional Data-Parallel training requires approximately 198 Gbps of inter-datacenter bandwidth across eight data centers — far beyond what standard wide-area networking (WAN) can support between geographically distributed facilities.
Decoupled DiLoCo builds on two prior systems from Google. The first is Pathways, which introduced a distributed AI system based on asynchronous data flow, allowing different compute resources to work at their own pace without blocking on one another. The second is DiLoCo, which dramatically reduced the inter-datacenter bandwidth required for distributed training by having each worker perform many local gradient steps before communicating with peers — dramatically reducing how much data needs to flow between data centers.
Decoupled DiLoCo brings both ideas together. Built on top of Pathways, training is divided across separate clusters of accelerators called learner units — the ‘islands’ of compute. Each learner unit trains semi-independently, performing many local steps, before sharing a compressed gradient signal with an outer optimizer that aggregates updates across all learner units. Because this outer synchronization step is asynchronous, a chip failure or slow learner unit in one island does not block the others from continuing to train.
The bandwidth savings are dramatic. Decoupled DiLoCo reduces required inter-datacenter bandwidth from 198 Gbps to just 0.84 Gbps across eight data centers — multiple orders of magnitude lower — making it compatible with standard internet-scale connectivity between datacenter facilities rather than requiring custom high-speed network infrastructure.
One of the most technically significant properties of Decoupled DiLoCo is its fault tolerance. The research team used chaos engineering, a method that deliberately introduces artificial hardware failures into a running system to test its robustness during training runs. The system continued training after the loss of entire learner units, and then seamlessly reintegrated those units when they came back online. This behavior is what the research team describes as ‘self-healing’.
In simulations involving 1.2 million chips under high failure rates, Decoupled DiLoCo maintained a goodput (the fraction of time the system is performing useful training) of 88%, compared to just 27% for standard Data-Parallel methods. Goodput is the practical metric that matters here: a training run with high nominal compute but low goodput wastes significant resources.
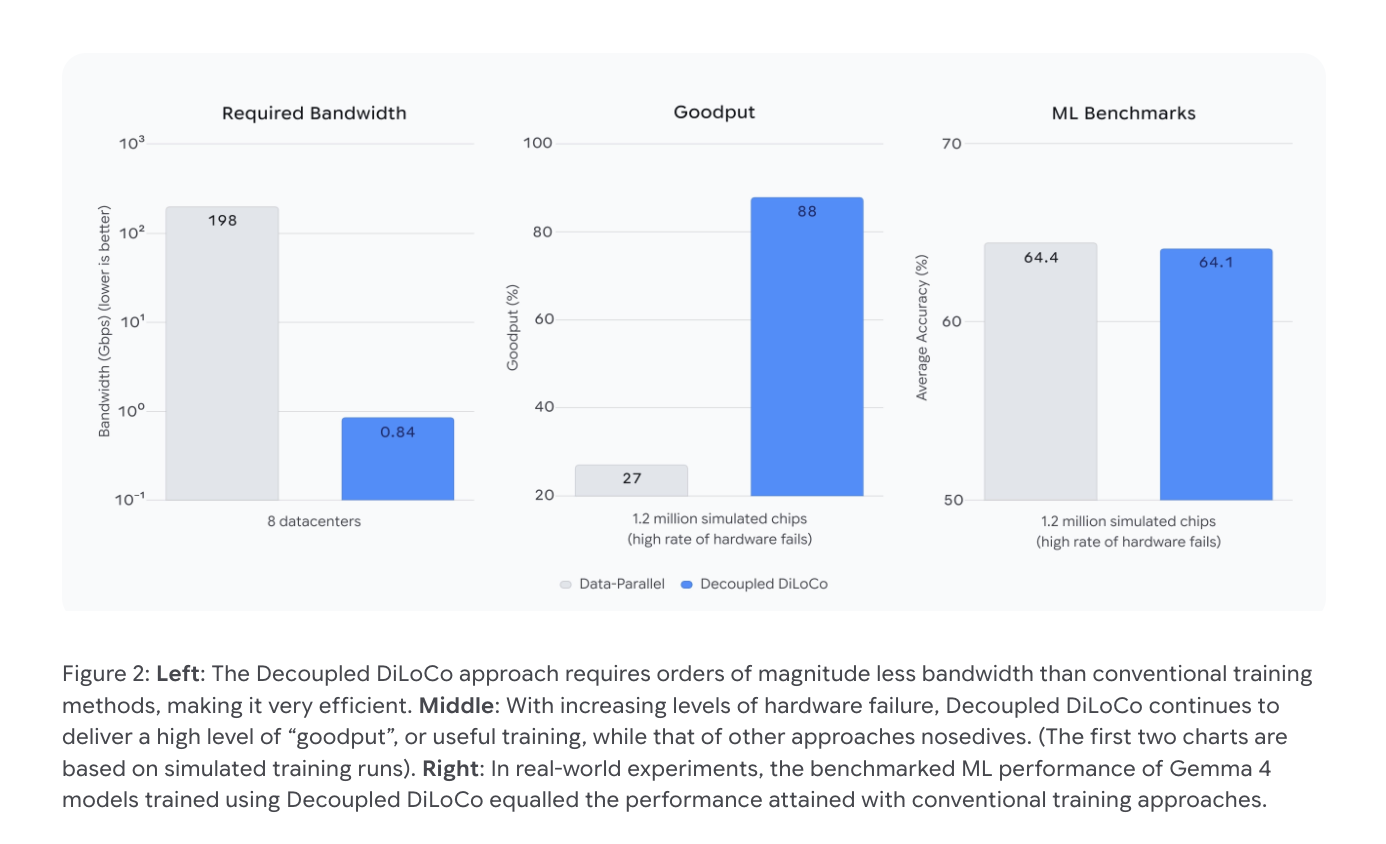
Critically, these resilience gains come with minimal degradation in model quality. In real-world experiments using Gemma 4 models, Decoupled DiLoCo achieved an average ML benchmark accuracy of 64.1%, compared to 64.4% for the conventional baseline — a difference well within the noise of typical evaluation variance.
The research team validated Decoupled DiLoCo at production scale by successfully training a 12 billion parameter model across four separate U.S. regions using just 2–5 Gbps of wide-area networking, a bandwidth level achievable with existing commercial internet infrastructure between data center facilities. The system accomplished this more than 20 times faster than conventional synchronization methods. The key reason: rather than forcing compute to pause and wait for communication to complete, Decoupled DiLoCo incorporates required communication into longer periods of computation, eliminating the “blocking” bottlenecks that make conventional distributed training slow at global scale.
An underappreciated implication of the architecture is its support for heterogeneous hardware. Because learner units operate asynchronously, they do not need to run on identical hardware at the same clock speed. The research team demonstrated training runs that mixed TPU v6e and TPU v5p chips — different hardware generations with different performance characteristics — in a single training job, without degrading ML performance relative to homogeneous runs.
This has two practical consequences worth noting. First, it extends the useful life of existing hardware, allowing older accelerators to continue contributing meaningfully to large-scale training. Second, because new hardware generations do not arrive everywhere at once, being able to train across generations can alleviate the recurring logistical and capacity bottlenecks that arise during hardware transition periods — a real operational challenge at organizations running large training infrastructure.
Check out the Paper and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 130k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。