





Most AI agents today have a fundamental amnesia problem. Deploy one to browse the web, resolve GitHub issues, or navigate a shopping platform, and it approaches every single task as if it has never seen anything like it before. No matter how many times it has stumbled on the same type of problem, it repeats the same mistakes. Valuable lessons evaporate the moment a task ends.
A team of researchers from Google Cloud AI, the University of Illinois Urbana-Champaign and Yale University introduces ReasoningBank, a memory framework that doesn’t just record what an agent did — it distills why something worked or failed into reusable, generalizable reasoning strategies.
To understand why ReasoningBank is important, you need to understand what existing agent memory actually does. Two popular approaches are trajectory memory (used in a system called Synapse) and workflow memory (used in Agent Workflow Memory, or AWM). Trajectory memory stores raw action logs — every click, scroll, and typed query an agent executed. Workflow memory goes a step further and extracts reusable step-by-step procedures from successful runs only.
Both have critical blind spots. Raw trajectories are noisy and too long to be directly useful for new tasks. Workflow memory only mines successful attempts, which means the rich learning signal buried in every failure — and agents fail a lot — gets completely discarded.
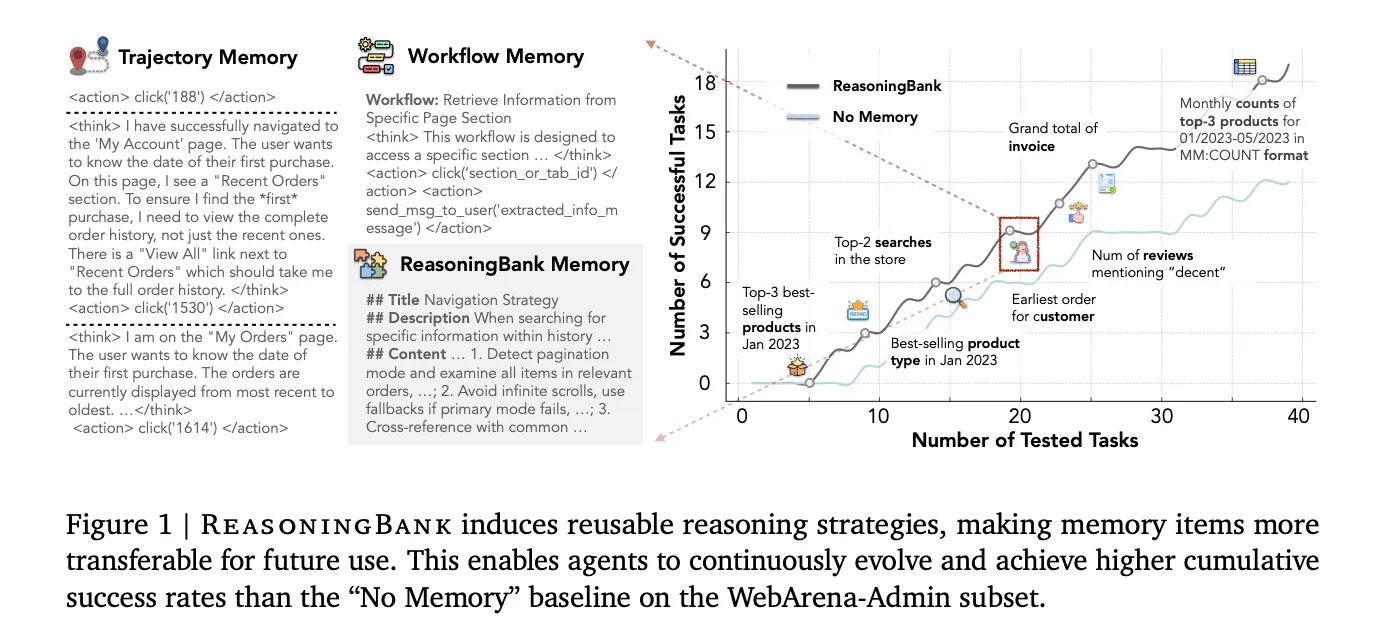
ReasoningBank operates as a closed-loop memory process with three stages that run around every completed task: memory retrieval, memory extraction, and memory consolidation.
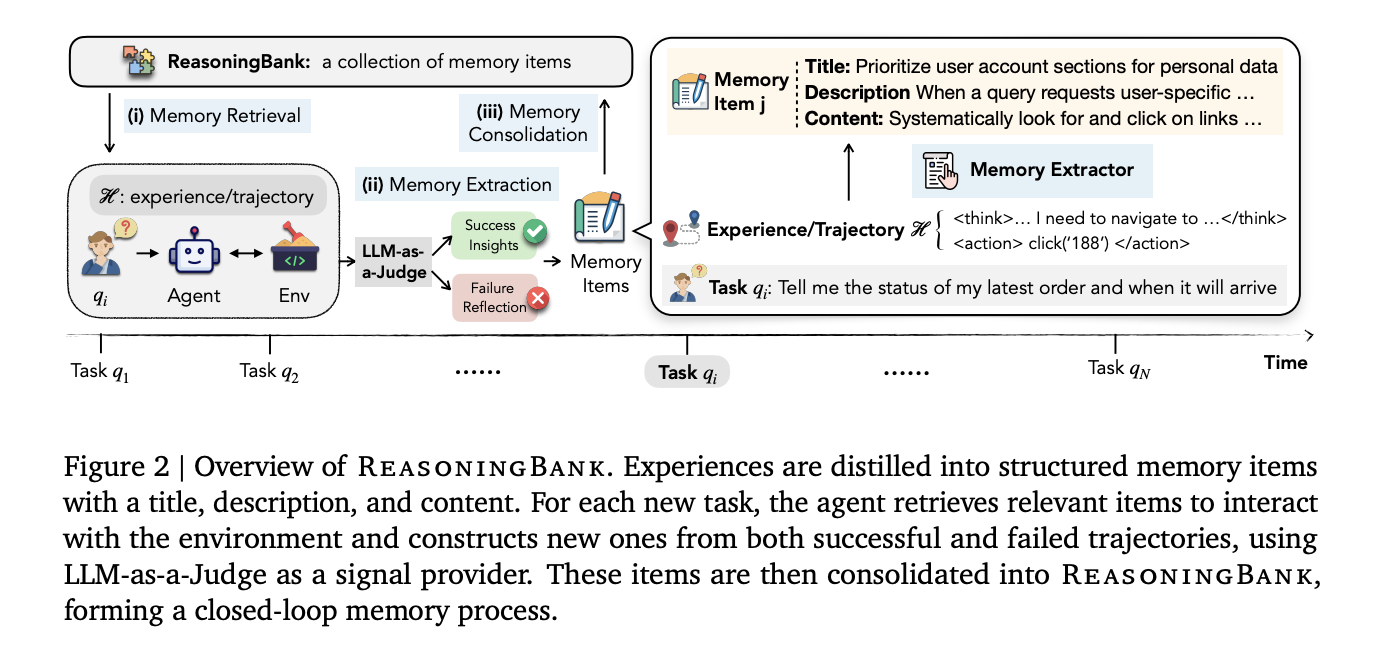
Before an agent starts a new task, it queries ReasoningBank using embedding-based similarity search to retrieve the top-k most relevant memory items. Those items get injected directly into the agent’s system prompt as additional context. Importantly, the default is k=1, a single retrieved memory item per task. Ablation experiments show that retrieving more memories actually hurts performance: success rate drops from 49.7% at k=1 to 44.4% at k=4. The quality and relevance of retrieved memory matter far more than quantity.
Once the task is finished, a Memory Extractor — powered by the same backbone LLM as the agent — analyzes the trajectory and distills it into structured memory items. Each item has three components: a title (a concise strategy name), a description (a one-sentence summary), and content (1–3 sentences of distilled reasoning steps or operational insights). Crucially, the extractor treats successful and failed trajectories differently: successes contribute validated strategies, while failures supply counterfactual pitfalls and preventative lessons.
To decide whether a trajectory was successful or not — without access to ground-truth labels at test time — the system uses an LLM-as-a-Judge, which outputs a binary “Success” or “Failure” verdict given the user query, the trajectory, and the final page state. The judge doesn’t need to be perfect; ablation experiments show ReasoningBank remains robust even when judge accuracy drops to around 70%.
New memory items are then appended directly to the ReasoningBank store, maintained as JSON with pre-computed embeddings for fast cosine similarity search, completing the loop.
The research team goes further and introduces memory-aware test-time scaling (MaTTS), which links ReasoningBank with test-time compute scaling — a technique that has already proven powerful in math reasoning and coding tasks.
The insight is simple but important: scaling at test time generates multiple trajectories for the same task. Instead of just picking the best answer and discarding the rest, MaTTS uses the full set of trajectories as rich contrastive signals for memory extraction.
MaTTS comes in two ways. Parallel scaling generates k independent trajectories for the same query, then uses self-contrast — comparing what went right and wrong across all trajectories — to extract higher-quality, more reliable memory items. Sequential scaling iteratively refines a single trajectory using self-refinement, capturing intermediate corrections and insights as memory signals.
The result is a positive feedback loop: better memory guides the agent toward more promising rollouts, and richer rollouts forge even stronger memory. The paper notes that at k=5, parallel scaling (55.1% SR) edges out sequential scaling (54.5% SR) on WebArena-Shopping — sequential gains saturate quickly once the model reaches a decisive success or failure, while parallel scaling keeps providing diverse rollouts that the agent can contrast and learn from.
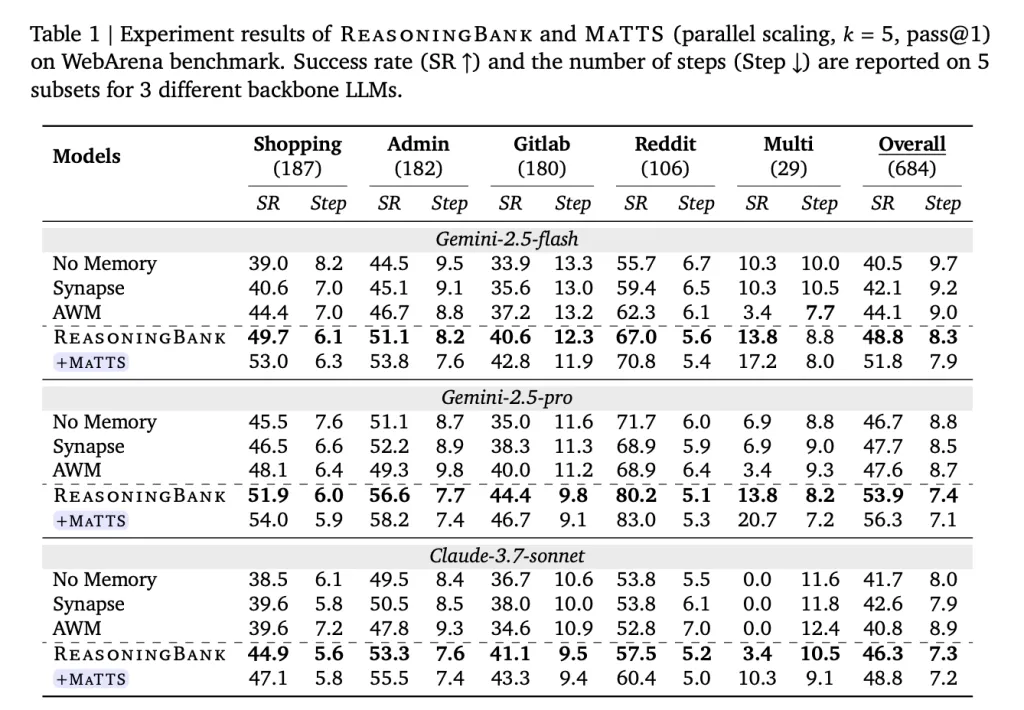
Tested on WebArena (a web navigation benchmark spanning shopping, admin, GitLab, and Reddit tasks), Mind2Web (which tests generalization across cross-task, cross-website, and cross-domain settings), and SWE-Bench-Verified (a repository-level software engineering benchmark with 500 verified instances), ReasoningBank consistently outperforms all baselines across all three datasets and all tested backbone models.
On WebArena with Gemini-2.5-Flash, ReasoningBank improved overall success rate by +8.3 percentage points over the memory-free baseline (40.5% → 48.8%), while reducing average interaction steps by up to 1.4 compared to no-memory and up to 1.6 compared to other memory baselines. The efficiency gains are sharpest on successful trajectories — on the Shopping subset, for example, ReasoningBank cut 2.1 steps from successful task completions (a 26.9% relative reduction). The agent reaches solutions faster because it knows the right path, not simply because it gives up on failed attempts sooner.
On Mind2Web, ReasoningBank delivers consistent gains across cross-task, cross-website, and cross-domain evaluation splits, with the most pronounced improvements in the cross-domain setting — where the highest degree of strategy transfer is required and where competing methods like AWM actually degrade relative to the no-memory baseline.
On SWE-Bench-Verified, results vary meaningfully by backbone model. With Gemini-2.5-Pro, ReasoningBank achieves a 57.4% resolve rate versus 54.0% for the no-memory baseline, saving 1.3 steps per task. With Gemini-2.5-Flash, the step savings are more dramatic — 2.8 fewer steps per task (30.3 → 27.5) alongside a resolve rate improvement from 34.2% to 38.8%.
Adding MaTTS (parallel scaling, k=5) pushes results further. ReasoningBank with MaTTS reaches 56.3% overall SR on WebArena with Gemini-2.5-Pro — compared to 46.7% for the no-memory baseline — while also reducing average steps from 8.8 to 7.1 per task.
One of the most striking findings is that ReasoningBank’s memory doesn’t stay static — it evolves. In a documented case study, the agent’s initial memory items for a “User-Specific Information Navigation” strategy resemble simple procedural checklists: “actively look for and click on ‘Next Page,’ ‘Page X,’ or ‘Load More’ links.” As the agent accumulates experience, those same memory items mature into adaptive self-reflections, then into systematic pre-task checks, and eventually into compositional strategies like “regularly cross-reference the current view with the task requirements; if current data doesn’t align with expectations, reassess available options such as search filters and alternative sections.” The research team describe this as emergent behavior resembling the learning dynamics of reinforcement learning — happening entirely at test time, without any model weight updates.
Check out the Paper, Repo and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 130k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。