


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

N
Netflix TechBlog - Medium
J
Java Code Geeks
爱范儿
爱范儿
雷峰网
雷峰网
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
Cyber Security Advisories - MS-ISAC
博客园 - 三生石上(FineUI控件)
H
Hackread – Cybersecurity News, Data Breaches, AI and More
B
Blog RSS Feed
Google DeepMind News
Jina AI
Jina AI
The GitHub Blog
The GitHub Blog
I
InfoQ
月光博客
月光博客
博客园 - 聂微东
博客园 - Franky
The Cloudflare Blog
阮一峰的网络日志
阮一峰的网络日志
博客园_首页
G
Google Developers Blog
Blog — PlanetScale
Blog — PlanetScale
L
LangChain Blog
罗磊的独立博客
Apple Machine Learning Research

MarkTechPost

A Coding Implementation of End-to-End Brain Decoding from MEG Signals Using NeuralSet and Deep Learning for Predicting Linguistic Features Meta Introduces Autodata: An Agentic Framework That Turns AI Models into Autonomous Data Scientists for High-Quality Training Data Creation A Coding Guide on LLM Post Training with TRL from Supervised Fine Tuning to DPO and GRPO Reasoning Qwen AI Releases Qwen-Scope: An Open-Source Sparse AutoEncoders (SAE) Suite That Turns LLM Internal Features into Practical Development Tools A Coding Deep Dive into Agentic UI, Generative UI, State Synchronization, and Interrupt-Driven Approval Flows Moonshot AI Open-Sources FlashKDA: CUTLASS Kernels for Kimi Delta Attention with Variable-Length Batching and H20 Benchmarks Microsoft Research’s World-R1 Uses Flow-GRPO and 3D-Aware Rewards to Inject Geometric Consistency Into Wan 2.1 Without Architectural Changes A Coding Implementation on Pyright Type Checking Covering Generics, Protocols, Strict Mode, Type Narrowing, and Modern Python Typing IBM Releases Two Granite Speech 4.1 2B Models: Autoregressive ASR with Translation and Non-Autoregressive Editing for Fast Inference Top 10 KV Cache Compression Techniques for LLM Inference: Reducing Memory Overhead Across Eviction, Quantization, and Low-Rank Methods Qwen Team Releases FlashQLA: a High-Performance Linear Attention Kernel Library That Achieves Up to 3× Speedup on NVIDIA Hopper GPUs Step by Step Guide to Build a Complete PII Detection and Redaction Pipeline with OpenAI Privacy Filter Meta FAIR Releases NeuralSet: A Python Package for Neuro-AI That Supports fMRI, M/EEG, Spikes, and HuggingFace Embeddings smol-audio: A Colab-Friendly Notebook Collection for Fine-Tuning Whisper, Parakeet, Voxtral, Granite Speech, and Audio Flamingo 3 A Coding Implementation on Document Parsing Benchmarking with LlamaIndex ParseBench Using Python, Hugging Face, and Evaluation Metrics Poolside AI Introduces Laguna XS.2 and M.1: Agentic Coding Models Reaching 68.2% and 72.5% on SWE-bench Verified How to Build Traceable and Evaluated LLM Workflows Using Promptflow, Prompty, and OpenAI OpenAI Releases Privacy Filter: A 1.5B-Parameter Open-Source PII Redaction Model with 50M Active Parameters Top 10 Physical AI Models Powering Real-World Robots in 2026 How to Build a Lightweight Vision-Language-Action-Inspired Embodied Agent with Latent World Modeling and Model Predictive Control Meet Talkie-1930: A 13B Open-Weight LLM Trained on Pre-1931 English Text for Historical Reasoning and Generalization Research Build a Reinforcement Learning Powered Agent that Learns to Retrieve Relevant Long-Term Memories for Accurate LLM Question Answering OpenMOSS Releases MOSS-Audio: An Open-Source Foundation Model for Speech, Sound, Music, and Time-Aware Audio Reasoning Meta AI Releases Sapiens2: A High-Resolution Human-Centric Vision Model for Pose, Segmentation, Normals, Pointmap, and Albedo The LoRA Assumption That Breaks in Production How to Build a Fully Searchable AI Knowledge Base with OpenKB, OpenRouter, and Llama How to Build Smarter Multilingual Text Wrapping with BudouX Through Parsing, HTML Rendering, Model Introspection, and Toy Training Top 7 Benchmarks That Actually Matter for Agentic Reasoning in Large Language Models RAG Without Vectors: How PageIndex Retrieves by Reasoning A Coding Tutorial on Datashader on Rendering Massive Datasets with High-Performance Python Visual Analytics
Qwen Team Open-Sources Qwen3.6-35B-A3B: A Sparse MoE Visi...
Asif Razzaq · 2026-04-17 · via MarkTechPost

The open-source AI landscape has a new entry worth paying attention to. The Qwen team at Alibaba has released Qwen3.6-35B-A3B, the first open-weight model from the Qwen3.6 generation, and it is making a compelling argument that parameter efficiency matters far more than raw model size. With 35 billion total parameters but only 3 billion activated during inference, this model delivers agentic coding performance competitive with dense models that are ten times its active size.

What is a Sparse MoE Model, and Why Does it Matter Here?

A Mixture of Experts (MoE) model does not run all of its parameters on every forward pass. Instead, the model routes each input token through a small subset of specialized sub-networks called ‘experts.’ The rest of the parameters sit idle. This means you can have an enormous total parameter count while keeping inference compute — and therefore inference cost and latency — proportional only to the active parameter count.

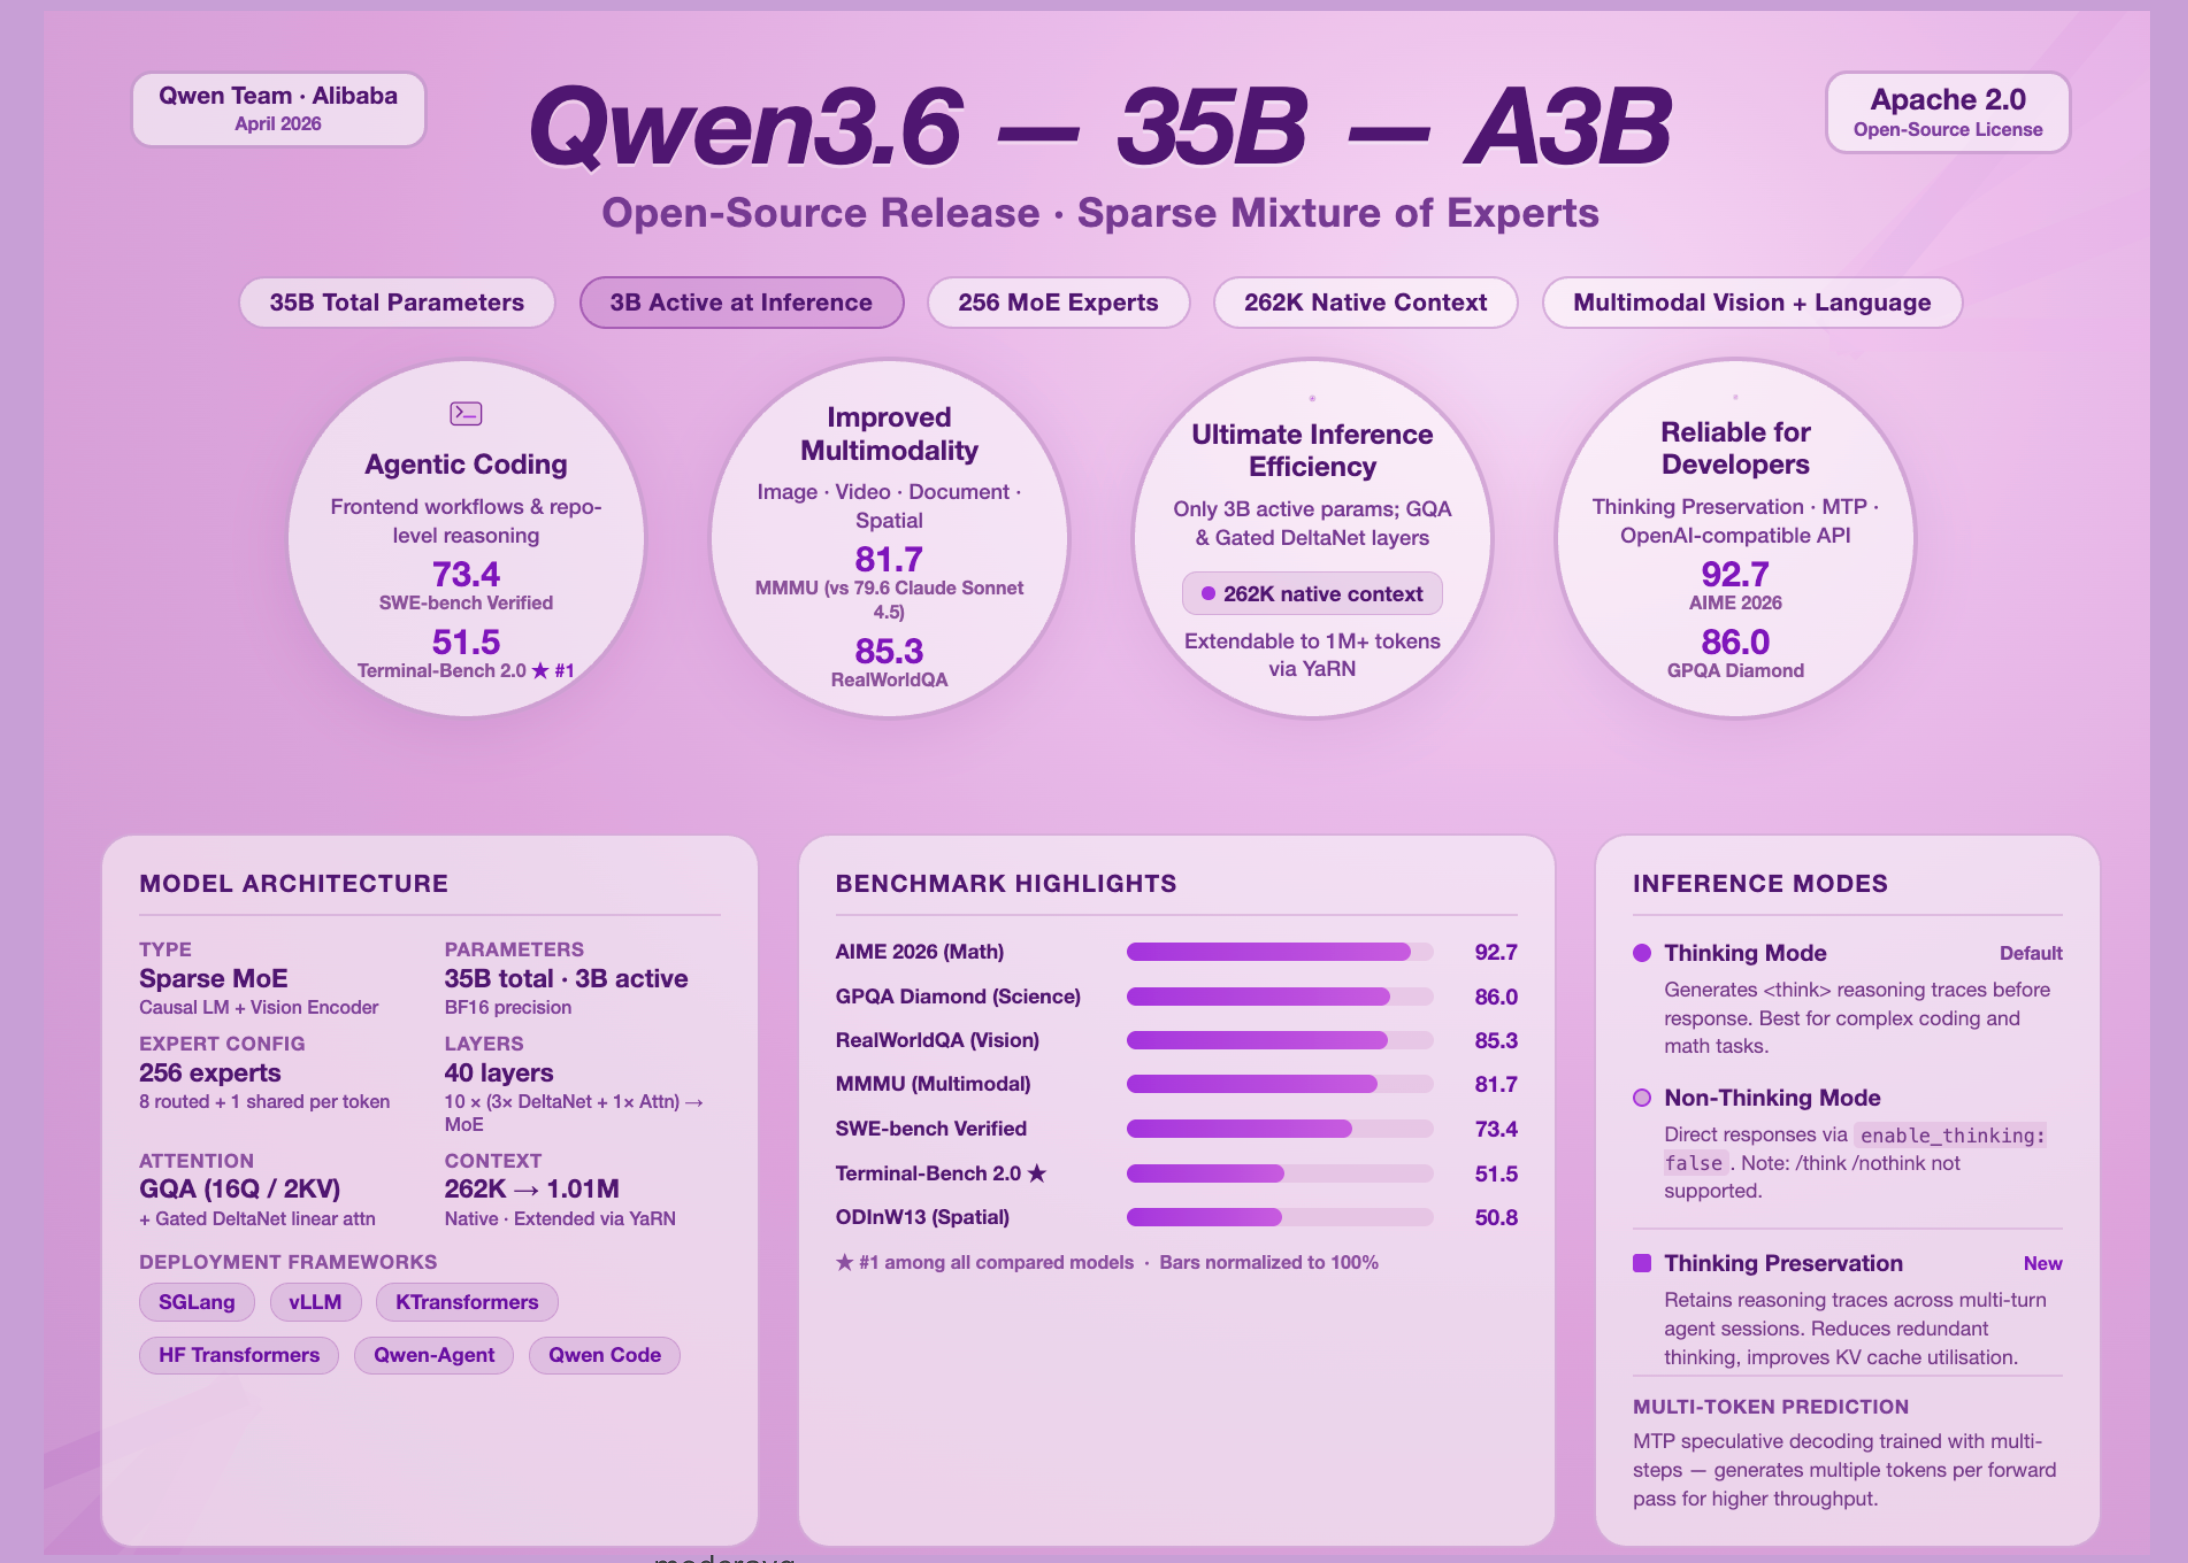
Qwen3.6-35B-A3B is a Causal Language Model with Vision Encoder, trained through both pre-training and post-training stages, with 35 billion total parameters and 3 billion activated. Its MoE layer contains 256 experts in total, with 8 routed experts and 1 shared expert activated per token.

The architecture introduces an unusual hidden layout worth understanding: the model uses a pattern of 10 blocks, each consisting of 3 instances of (Gated DeltaNet → MoE) followed by 1 instance of (Gated Attention → MoE). Across 40 total layers, the Gated DeltaNet sublayers handle linear attention — a computationally cheaper alternative to standard self-attention — while the Gated Attention sublayers use Grouped Query Attention (GQA), with 16 attention heads for Q and only 2 for KV, significantly reducing KV-cache memory pressure during inference. The model supports a native context length of 262,144 tokens, extensible up to 1,010,000 tokens using YaRN (Yet another RoPE extensioN) scaling.

Agentic Coding is Where This Model Gets Serious

On SWE-bench Verified — the canonical benchmark for real-world GitHub issue resolution — Qwen3.6-35B-A3B scores 73.4, compared to 70.0 for Qwen3.5-35B-A3B and 52.0 for Gemma4-31B. On Terminal-Bench 2.0, which evaluates an agent completing tasks inside a real terminal environment with a three-hour timeout, Qwen3.6-35B-A3B scores 51.5 — the highest among all compared models, including Qwen3.5-27B (41.6), Gemma4-31B (42.9), and Qwen3.5-35B-A3B (40.5).

Frontend code generation shows the sharpest improvement. On QwenWebBench, an internal bilingual front-end code generation benchmark covering seven categories including Web Design, Web Apps, Games, SVG, Data Visualization, Animation, and 3D, Qwen3.6-35B-A3B achieves a score of 1397 — well ahead of Qwen3.5-27B (1068) and Qwen3.5-35B-A3B (978).

On STEM and reasoning benchmarks, the numbers are equally striking. Qwen3.6-35B-A3B scores 92.7 on AIME 2026 (the full AIME I & II), and 86.0 on GPQA Diamond — a graduate-level scientific reasoning benchmark — both competitive with much larger models.

Multimodal Vision Performance

Qwen3.6-35B-A3B is not a text-only model. It ships with a vision encoder and handles image, document, video, and spatial reasoning tasks natively.

On MMMU (Massive Multi-discipline Multimodal Understanding), a benchmark that tests university-level reasoning across images, Qwen3.6-35B-A3B scores 81.7, outperforming Claude-Sonnet-4.5 (79.6) and Gemma4-31B (80.4). On RealWorldQA, which tests visual understanding in real-world photographic contexts, the model achieves 85.3, ahead of Qwen3.5-27B (83.7) and significantly above Claude-Sonnet-4.5 (70.3) and Gemma 4-31B (72.3).

Spatial intelligence is another area of measurable gain. On ODInW13, an object detection benchmark, Qwen3.6-35B-A3B scores 50.8, up from 42.6 for Qwen3.5-35B-A3B. For video understanding, it achieves 83.7 on VideoMMMU, outperforming Claude-Sonnet-4.5 (77.6) and Gemma4-31B (81.6).
https://qwen.ai/blog?id=qwen3.6-35b-a3b

Thinking Mode, Non-Thinking Mode, and a Key Behavioral Change

One of the more practically useful design decisions in Qwen3.6 is explicit control over the model’s reasoning behavior. Qwen3.6 models operate in thinking mode by default, generating reasoning content enclosed within <think> tags before producing the final response. Developers who need faster, direct responses can disable this via an API parameter — setting "enable_thinking": False in the chat template kwargs. However, AI professionals migrating from Qwen3 should note an important behavioral change: Qwen3.6 does not officially support the soft switch of Qwen3, i.e., /think and /nothink. Mode switching must be done through the API parameter rather than inline prompt tokens.

The more novel addition is a feature called Thinking Preservation. By default, only the thinking blocks generated for the latest user message are retained; Qwen3.6 has been additionally trained to preserve and leverage thinking traces from historical messages, which can be enabled by setting the preserve_thinking option. This capability is particularly beneficial for agent scenarios, where maintaining full reasoning context can enhance decision consistency, reduce redundant reasoning, and improve KV cache utilization in both thinking and non-thinking modes.

Key Takeaways

  • Qwen3.6-35B-A3B is a sparse Mixture of Experts model with 35 billion total parameters but only 3 billion activated at inference time, making it significantly cheaper to run than its total parameter count suggests — without sacrificing performance on complex tasks.
  • The model’s agentic coding capabilities are its strongest suit, with a score of 51.5 on Terminal-Bench 2.0 (the highest among all compared models), 73.4 on SWE-bench Verified, and a dominant 1,397 on QwenWebBench covering frontend code generation across seven categories including Web Apps, Games, and Data Visualization.
  • Qwen3.6-35B-A3B is a natively multimodal model, supporting image, video, and document understanding out of the box, with scores of 81.7 on MMMU, 85.3 on RealWorldQA, and 83.7 on VideoMMMU — outperforming Claude-Sonnet-4.5 and Gemma4-31B on each of these.
  • The model introduces a new Thinking Preservation feature that allows reasoning traces from prior conversation turns to be retained and reused across multi-step agent workflows, reducing redundant reasoning and improving KV cache efficiency in both thinking and non-thinking modes.
  • Released under Apache 2.0, the model is fully open for commercial use and is compatible with the major open-source inference frameworks — SGLang, vLLM, KTransformers, and Hugging Face Transformers — with KTransformers specifically enabling CPU-GPU heterogeneous deployment for resource-constrained environments.

Check out the Technical details and Model WeightsAlso, feel free to follow us on Twitter and don’t forget to join our 130k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us