









Poolside AI released the first two models in its Laguna family: Laguna M.1 and Laguna XS.2. Alongside these, the company is releasing pool — a lightweight terminal-based coding agent and a dual Agent Client Protocol (ACP) client-server — the same environment Poolside uses internally for agent RL training and evaluation, now available as a research preview.
Both Laguna M.1 and Laguna XS.2 are Mixture-of-Experts (MoE) models. Instead of activating all parameters for every token, MoE models route each token through only a subset of specialized sub-networks called ‘experts.’ This means a large total parameter count and the capability headroom that comes with it while only paying the compute cost of a much smaller “activated” parameter count at inference time.
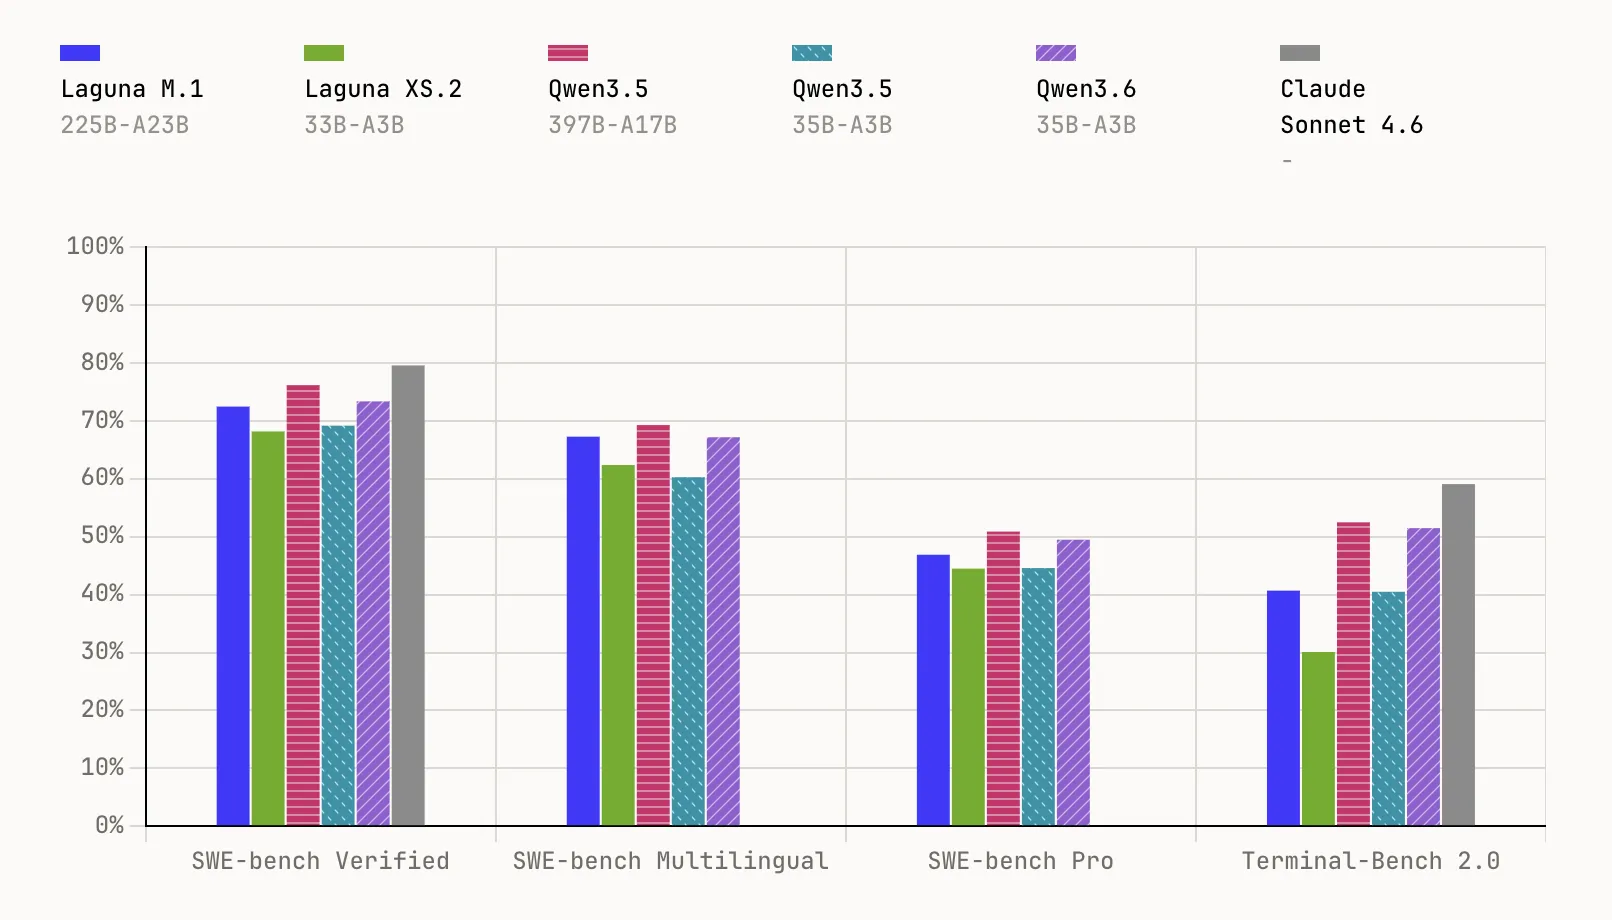
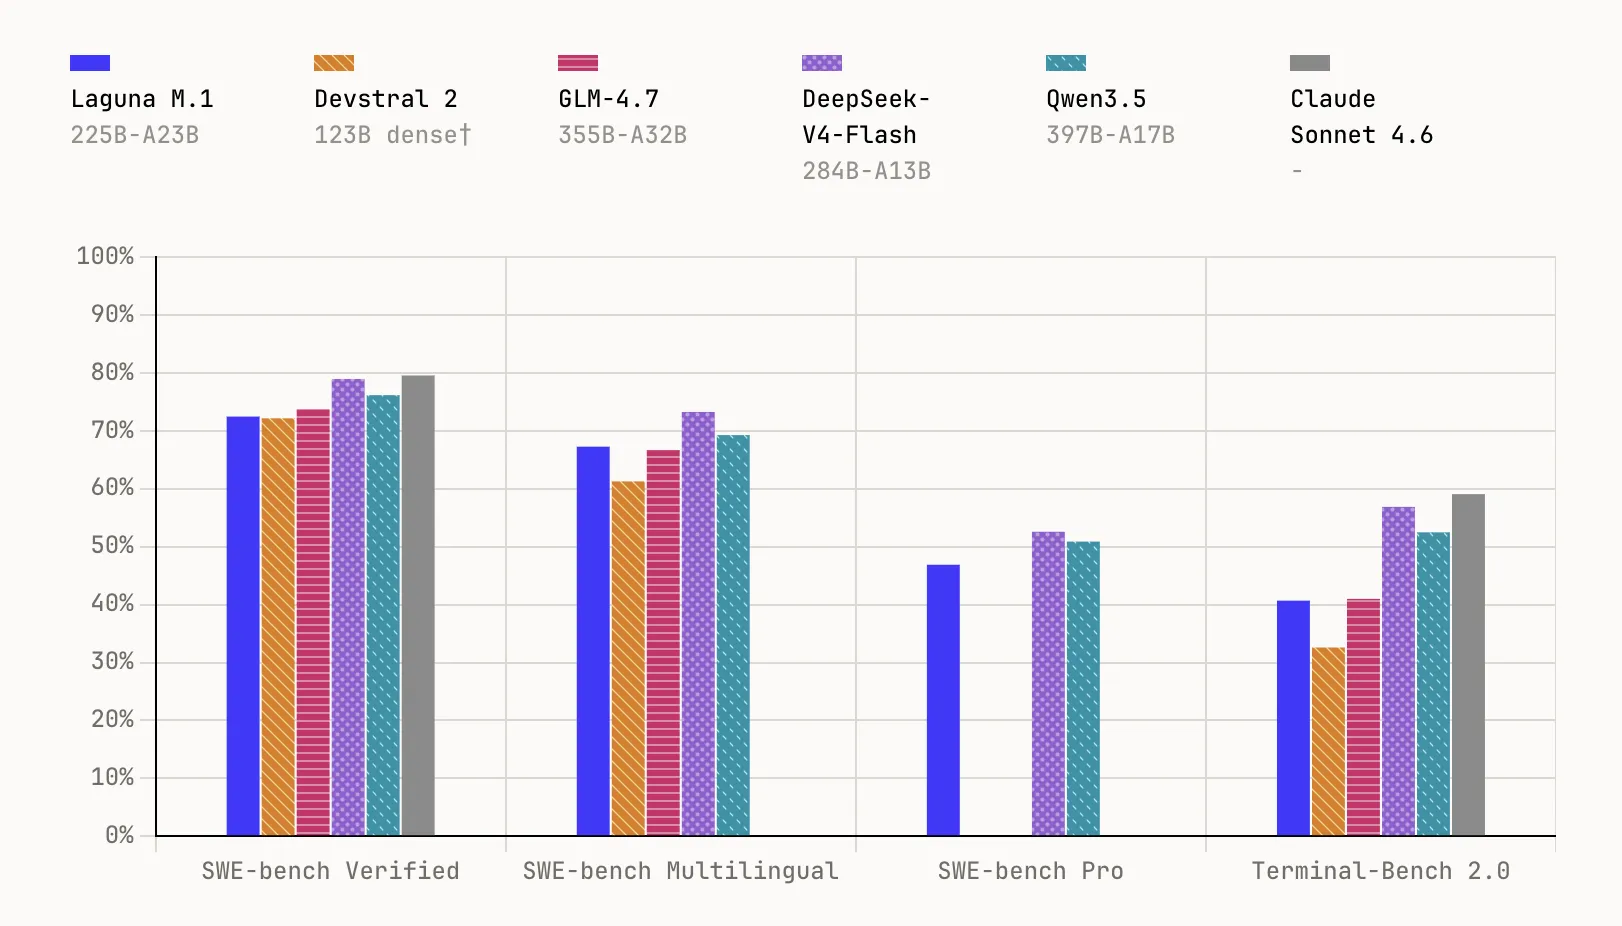
Laguna M.1 is a 225B total parameter MoE model with 23B activated parameters, trained from scratch on 30T tokens using 6,144 interconnected NVIDIA Hopper GPUs. It completed pre-training at the end of last year and serves as the foundation for the entire Laguna family. On benchmarks, it reaches 72.5% on SWE-bench Verified, 67.3% on SWE-bench Multilingual, 46.9% on SWE-bench Pro, and 40.7% on Terminal-Bench 2.0.
Laguna XS.2 is the second-generation MoE and Poolside’s first open-weight model, built on everything learned since training M.1. At 33B total parameters with 3B activated per token, it is designed for agentic coding and long-horizon work on a local machine — compact enough to run on a Mac with 36 GB of RAM via Ollama. It scores 68.2% on SWE-bench Verified, 62.4% on SWE-bench Multilingual, 44.5% on SWE-bench Pro, and 30.1% on Terminal-Bench 2.0. Poolside will also release Laguna XS.2-base soon for practitioners who want to fine-tune.
XS.2 uses sigmoid gating with per-layer rotary scales, enabling a mixed Sliding Window Attention (SWA) and global attention layout in a 3:1 ratio across 40 total layers — 30 SWA layers and 10 global attention layers. Sliding Window Attention limits each token’s attention to a local window of 512 tokens rather than the full sequence, dramatically cutting KV cache memory. The global attention layers at a 1-in-4 ratio preserve long-range dependencies without paying the full cost everywhere. The model also quantizes the KV cache to FP8, further reducing memory per token.
Under the hood, XS.2 uses 256 experts with 1 shared expert, supports a context window of 131,072 tokens, and features native reasoning support — interleaved thinking between tool calls with per-request control over enabling or disabling thinking.
Poolside team trains all its models from scratch using its own data pipeline, its own training codebase (Titan), and its own agent RL infrastructure. Three areas saw particular investment for Laguna.
AutoMixer: Optimizing the Data Mix Automatically. Data curation and the mix that goes into training is extremely impactful on final model performance. Rather than relying on manual heuristics, Poolside developed an automixing framework that trains a swarm of approximately 60 proxy models, each on a different data mix, and measures performance across key capability groups — code, math, STEM, and common sense. Surrogate regressors are then fit to approximate how changes in dataset proportions affect downstream evaluations, giving a learned mapping from data mix to performance that can be directly optimized. The approach is inspired by prior work including Olmix, MDE, and RegMix, adapted to Poolside’s setting with richer data groupings.
On the data side, both Laguna models were trained on more than 30T tokens. Poolside’s diversity-preserving data curation approach — which retains portions of mid- and lower-quality buckets alongside top-quality data to avoid STEM bias — yields approximately 2× more unique tokens compared to precision-focused pipelines, with the gain persisting at longer training horizons. A separate deduplication analysis also confirmed that global deduplication disproportionately removes high-quality data, informing how the team tuned its pipeline. Synthetic data contributes about 13% of the final training mix in Laguna XS.2, with the Laguna series using approximately 4.4T+ synthetic tokens in total.
Muon Optimizer. Rather than AdamW — the most common optimizer in large model training — Poolside used a distributed implementation of the Muon optimizer through all training stages of both models. In initial pre-training ablations, the research team achieved the same training loss as an AdamW baseline in approximately 15% fewer steps, with large absolute evaluation uplifts on the final model, and achieved learning rate transfer across model scales. An additional benefit: Muon requires only one state per parameter rather than two, reducing memory requirements for both training and checkpointing. During pre-training of Laguna M.1, the overhead from the optimizer was less than 1% of the training step time.
Poolside also runs periodic hash checks on model weights across training replicas to catch silent data corruption (SDC) from defective GPUs — specifically errors in arithmetic logic and pipeline registers, which unlike DRAM and SRAM are not covered by ECC protection.
Async On-Policy Agent RL. This is arguably the most complex piece of the Laguna training stack. Poolside built a fully asynchronous online RL system where actor processes pull tasks from a dataset, spin up sandboxed containers, and run the production agent binary against each task using the freshly deployed model. The resulting trajectories are scored, filtered, and written to Iceberg tables, while the trainer continuously consumes those records and produces the next checkpoint — inference and training running asynchronously in parallel, with throughput tuned to balance off-policy staleness.
Check out the Model Weights and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 130k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。