
惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

Y
Y Combinator Blog
有赞技术团队
有赞技术团队
J
Java Code Geeks
H
Hackread – Cybersecurity News, Data Breaches, AI and More
美团技术团队
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
Hugging Face - Blog
Hugging Face - Blog
人人都是产品经理
人人都是产品经理
酷 壳 – CoolShell
酷 壳 – CoolShell
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
C
Check Point Blog
博客园 - 【当耐特】
The GitHub Blog
The GitHub Blog
Recent Announcements
The Cloudflare Blog
Microsoft Azure Blog
腾讯CDC
Vercel News
Vercel News
IT之家
IT之家
MyScale Blog
MyScale Blog
博客园_首页
Martin Fowler
Martin Fowler
WordPress大学
WordPress大学
罗磊的独立博客

Hugging Face - Blog

Waypoint-1.5: Higher-Fidelity Interactive Worlds for Everyday GPUs ALTK‑Evolve: On‑the‑Job Learning for AI Agents Safetensors is Joining the PyTorch Foundation Holo3: Breaking the Computer Use Frontier Any Custom Frontend with Gradio's Backend A New Framework for Evaluating Voice Agents (EVA) Bringing Robotics AI to Embedded Platforms: Dataset Recording, VLA Fine‑Tuning, and On‑Device Optimizations One-Shot Any Web App with Gradio's gr.HTML CUGA on Hugging Face: Democratizing Configurable AI Agents New in llama.cpp: Model Management Building Deep Research: How we Achieved State of the Art OVHcloud on Hugging Face Inference Providers 🔥 20x Faster TRL Fine-tuning with RapidFire AI Building for an Open Future - our new partnership with Google Cloud Aligning to What? Rethinking Agent Generalization in MiniMax M2 Building a Healthcare Robot from Simulation to Deployment with NVIDIA Isaac Sentence Transformers is joining Hugging Face! Unlock the power of images with AI Sheets Supercharge your OCR Pipelines with Open Models Google Cloud C4 Brings a 70% TCO improvement on GPT OSS with Intel and Hugging Face Get your VLM running in 3 simple steps on Intel CPUs Nemotron-Personas-India: Synthesized Data for Sovereign AI Introducing RTEB: A New Standard for Retrieval Evaluation Accelerating Qwen3-8B Agent on Intel® Core™ Ultra with Depth-Pruned Draft Models VibeGame: Exploring Vibe Coding Games Nemotron-Personas-Japan: ソブリン AI のための合成データセット Swift Transformers Reaches 1.0 – and Looks to the Future Smol2Operator: Post-Training GUI Agents for Computer Use SyGra: The One-Stop Framework for Building Data for LLMs and SLMs Gaia2 and ARE: Empowering the community to study agents
StarCoder2 and The Stack v2
Leandro von Werra, Loubna Ben Allal, Anton Lozhkov, Nouamane Taz · 2024-02-28 · via Hugging Face - Blog

Back to Articles

This article is also available in Chinese 简体中文.
StarCoder2

BigCode is releasing StarCoder2, the next generation of transparently trained open code LLMs. All StarCoder2 variants were trained on The Stack v2, a new large and high-quality code dataset. We release all models, datasets, and the processing as well as the training code. Check out the paper for details.

What is StarCoder2?

StarCoder2 is a family of open LLMs for code and comes in 3 different sizes with 3B, 7B and 15B parameters. The flagship StarCoder2-15B model is trained on over 4 trillion tokens and 600+ programming languages from The Stack v2. All models use Grouped Query Attention, a context window of 16,384 tokens with a sliding window attention of 4,096 tokens, and were trained using the Fill-in-the-Middle objective.

StarCoder2 offers three model sizes: a 3 billion-parameter model trained by ServiceNow, a 7 billion-parameter model trained by Hugging Face, and a 15 billion-parameter model trained by NVIDIA using NVIDIA NeMo on NVIDIA accelerated infrastructure:

  • StarCoder2-3B was trained on 17 programming languages from The Stack v2 on 3+ trillion tokens.
  • StarCoder2-7B was trained on 17 programming languages from The Stack v2 on 3.5+ trillion tokens.
  • StarCoder2-15B was trained on 600+ programming languages from The Stack v2 on 4+ trillion tokens.

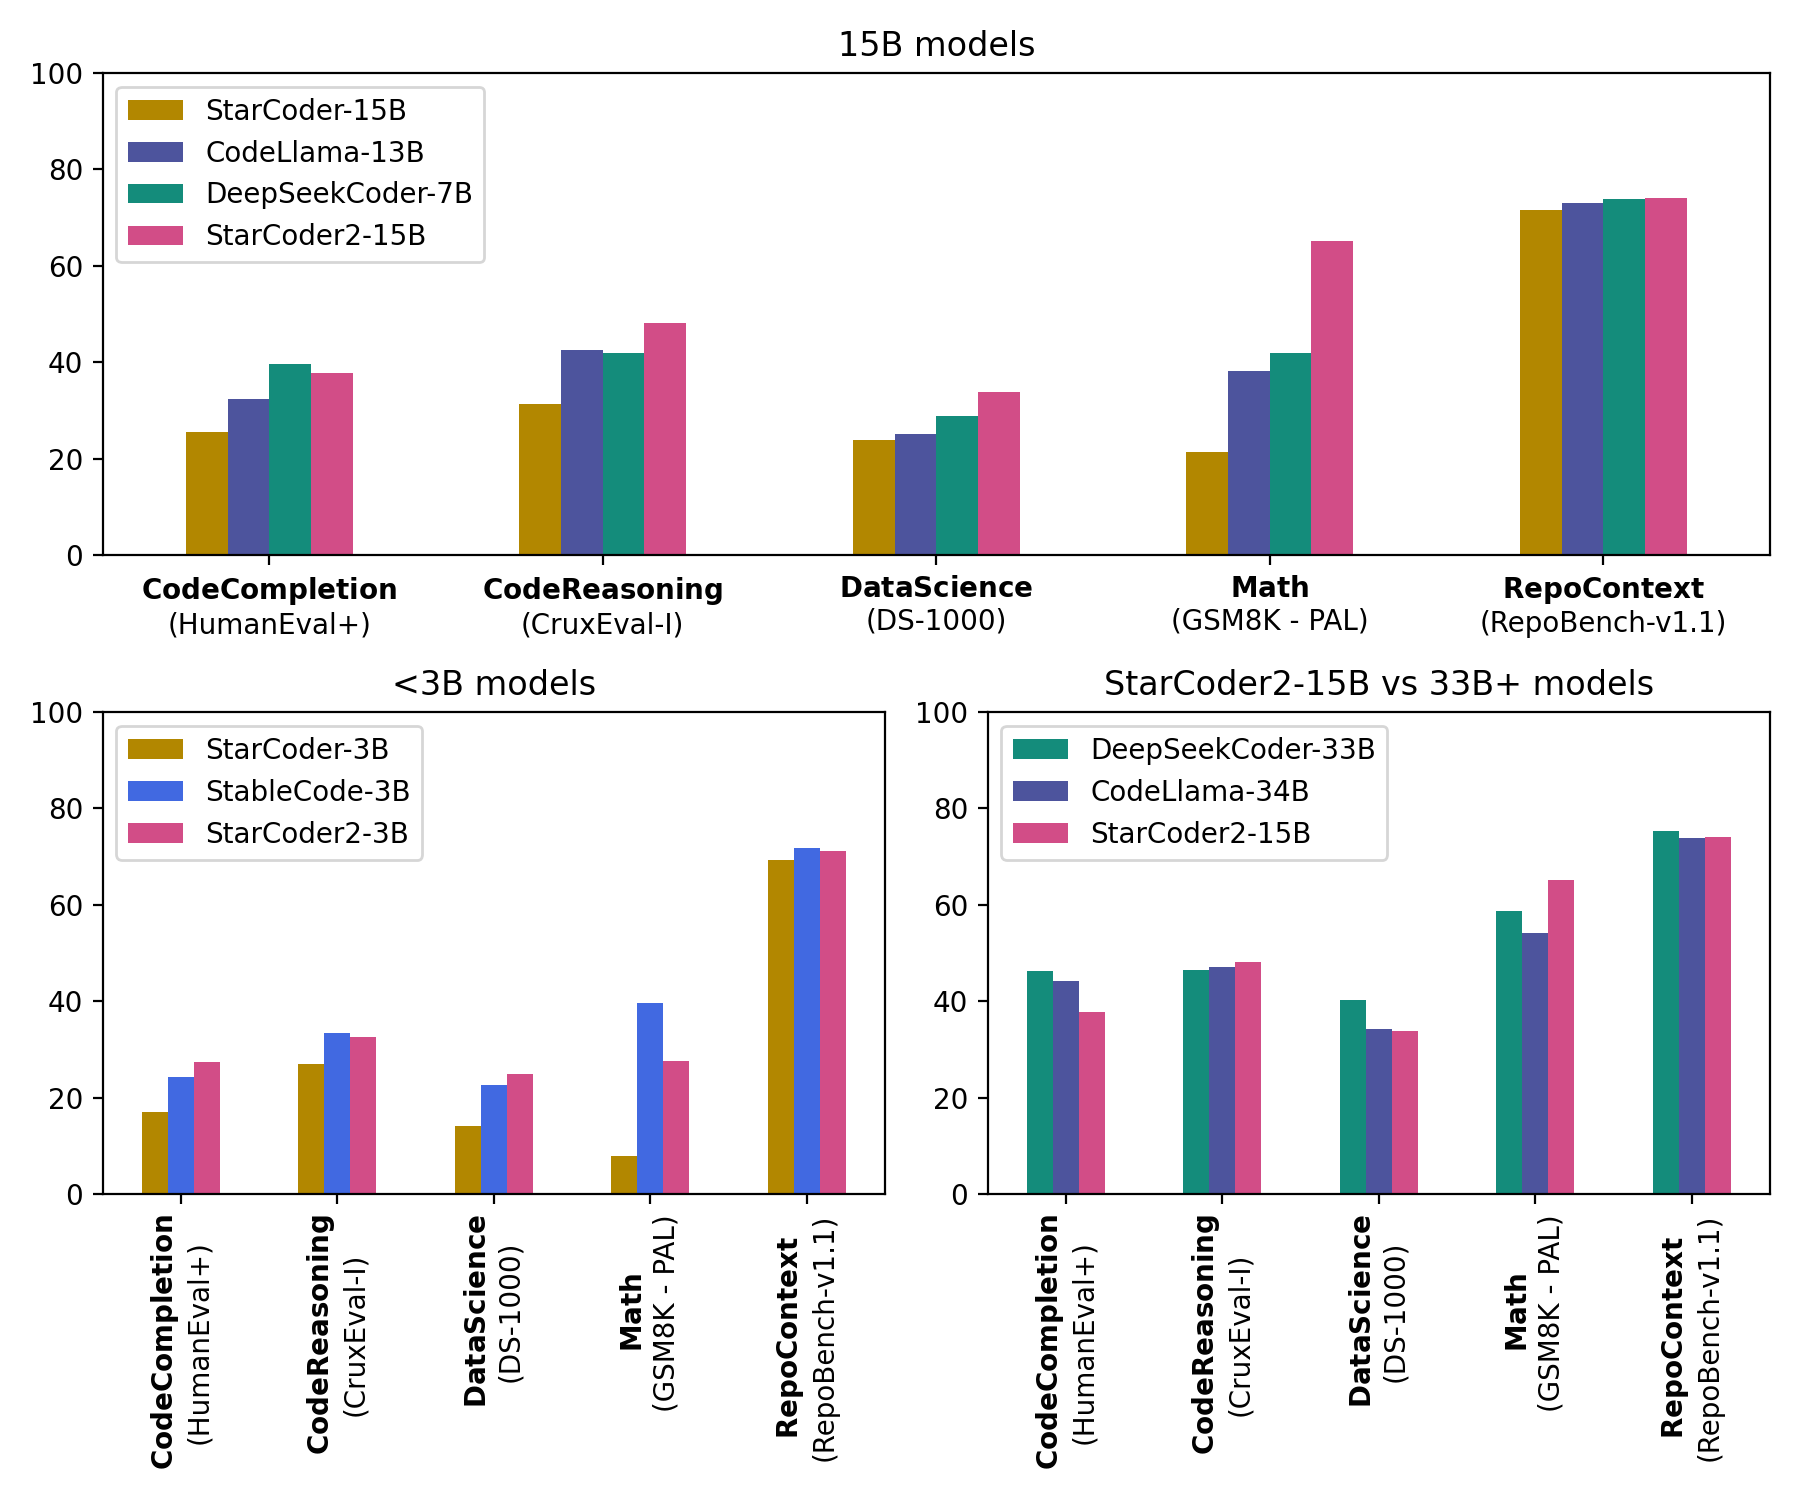
StarCoder2-15B is the best in its size class and matches 33B+ models on many evaluations. StarCoder2-3B matches the performance of StarCoder1-15B:
StarCoder2 Evaluation

What is The Stack v2?

The Stack v2

The Stack v2 is the largest open code dataset suitable for LLM pretraining. The Stack v2 is larger than The Stack v1, follows an improved language and license detection procedure, and better filtering heuristics. In addition, the training dataset is grouped by repositories, allowing to train models with repository context.

This dataset is derived from the Software Heritage archive, the largest public archive of software source code and accompanying development history. Software Heritage, launched by Inria in partnership with UNESCO, is an open, non-profit initiative to collect, preserve, and share the source code of all publicly available software. We are grateful to Software Heritage for providing access to this invaluable resource. For more details, visit the Software Heritage website.

The Stack v2 can be accessed through the Hugging Face Hub.

About BigCode

BigCode is an open scientific collaboration led jointly by Hugging Face and ServiceNow that works on the responsible development of large language models for code.

Links

Models

Data & Governance

Others

You can find all the resources and links at huggingface.co/bigcode!