



This article is also available in Chinese 简体中文.
We aim to give a clear overview of the pros and cons of each quantization scheme supported in transformers to help you decide which one you should go for.
Currently, quantizing models are used for two main purposes:
So far, two integration efforts have been made and are natively supported in transformers : bitsandbytes and auto-gptq. Note that some additional quantization schemes are also supported in the 🤗 optimum library, but this is out of scope for this blogpost.
To learn more about each of the supported schemes, please have a look at one of the resources shared below. Please also have a look at the appropriate sections of the documentation.
Note also that the details shared below are only valid for PyTorch models, this is currently out of scope for Tensorflow and Flax/JAX models.
In this section, we will go over the pros and cons of bitsandbytes and gptq quantization. Note that these are based on the feedback from the community and they can evolve over time as some of these features are in the roadmap of the respective libraries.
easy: bitsandbytes still remains the easiest way to quantize any model as it does not require calibrating the quantized model with input data (also called zero-shot quantization). It is possible to quantize any model out of the box as long as it contains torch.nn.Linear modules. Whenever a new architecture is added in transformers, as long as they can be loaded with accelerate’s device_map=”auto”, users can benefit from bitsandbytes quantization straight out of the box with minimal performance degradation. Quantization is performed on model load, no need to run any post-processing or preparation step.
cross-modality interoperability: As the only condition to quantize a model is to contain a torch.nn.Linear layer, quantization works out of the box for any modality, making it possible to load models such as Whisper, ViT, Blip2, etc. in 8-bit or 4-bit out of the box.
0 performance degradation when merging adapters: (Read more about adapters and PEFT in this blogpost if you are not familiar with it). If you train adapters on top of the quantized base model, the adapters can be merged on top of of the base model for deployment, with no inference performance degradation. You can also merge the adapters on top of the dequantized model ! This is not supported for GPTQ.
fast for text generation: GPTQ quantized models are fast compared to bitsandbytes quantized models for text generation. We will address the speed comparison in an appropriate section.
n-bit support: The GPTQ algorithm makes it possible to quantize models up to 2 bits! However, this might come with severe quality degradation. The recommended number of bits is 4, which seems to be a great tradeoff for GPTQ at this time.
easily-serializable: GPTQ models support serialization for any number of bits. Loading models from TheBloke namespace: https://huggingface.co/TheBloke (look for those that end with the -GPTQ suffix) is supported out of the box, as long as you have the required packages installed. Bitsandbytes supports 8-bit serialization but does not support 4-bit serialization as of today.
AMD support: The integration should work out of the box for AMD GPUs!
slower than GPTQ for text generation: bitsandbytes 4-bit models are slow compared to GPTQ when using generate.
4-bit weights are not serializable: Currently, 4-bit models cannot be serialized. This is a frequent community request, and we believe it should be addressed very soon by the bitsandbytes maintainers as it's in their roadmap!
calibration dataset: The need of a calibration dataset might discourage some users to go for GPTQ. Furthermore, it can take several hours to quantize the model (e.g. 4 GPU hours for a 175B scale model according to the paper - section 2)
works only for language models (for now): As of today, the API for quantizing a model with auto-GPTQ has been designed to support only language models. It should be possible to quantize non-text (or multimodal) models using the GPTQ algorithm, but the process has not been elaborated in the original paper or in the auto-gptq repository. If the community is excited about this topic this might be considered in the future.
We decided to provide an extensive benchmark for both inference and fine-tuning adapters using bitsandbytes and auto-gptq on different hardware. The inference benchmark should give users an idea of the speed difference they might get between the different approaches we propose for inference, and the adapter fine-tuning benchmark should give a clear idea to users when it comes to deciding which approach to use when fine-tuning adapters on top of bitsandbytes and GPTQ base models.
We will use the following setup:
bnb_4bit_compute_dtype=torch.float16. Make sure to use bitsandbytes>=0.41.1 for fast 4-bit kernels. auto-gptq>=0.4.0 to use ex-llama kernels.This benchmark measures only the prefill step, which corresponds to the forward pass during training. It was run on a single NVIDIA A100-SXM4-80GB GPU with a prompt length of 512. The model we used was meta-llama/Llama-2-13b-hf.
with batch size = 1:
| quantization | act_order | bits | group_size | kernel | Load time (s) | Per-token latency (ms) | Throughput (tok/s) | Peak memory (MB) |
|---|---|---|---|---|---|---|---|---|
| fp16 | None | None | None | None | 26.0 | 36.958 | 27.058 | 29152.98 |
| gptq | False | 4 | 128 | exllama | 36.2 | 33.711 | 29.663 | 10484.34 |
| bitsandbytes | None | 4 | None | None | 37.64 | 52.00 | 19.23 | 11018.36 |
with batch size = 16:
| quantization | act_order | bits | group_size | kernel | Load time (s) | Per-token latency (ms) | Throughput (tok/s) | Peak memory (MB) |
|---|---|---|---|---|---|---|---|---|
| fp16 | None | None | None | None | 26.0 | 69.94 | 228.76 | 53986.51 |
| gptq | False | 4 | 128 | exllama | 36.2 | 95.41 | 167.68 | 34777.04 |
| bitsandbytes | None | 4 | None | None | 37.64 | 113.98 | 140.38 | 35532.37 |
From the benchmark, we can see that bitsandbyes and GPTQ are equivalent, with GPTQ being slightly faster for large batch size. Check this link to have more details on these benchmarks.
The following benchmarks measure the generation speed of the model during inference. The benchmarking script can be found here for reproducibility.
Let's test use_cache to better understand the impact of caching the hidden state during the generation.
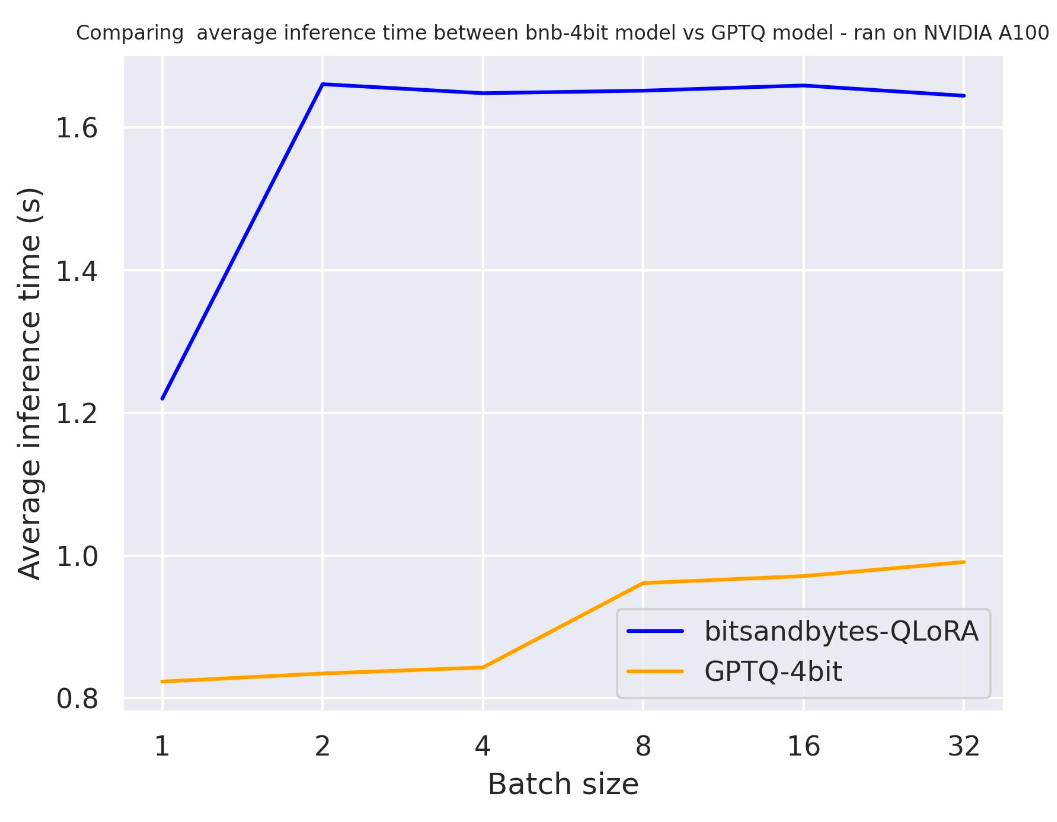
The benchmark was run on an A100 with a prompt length of 30 and we generated exactly 30 tokens. The model we used was meta-llama/Llama-2-7b-hf.
with use_cache=True
with use_cache=False
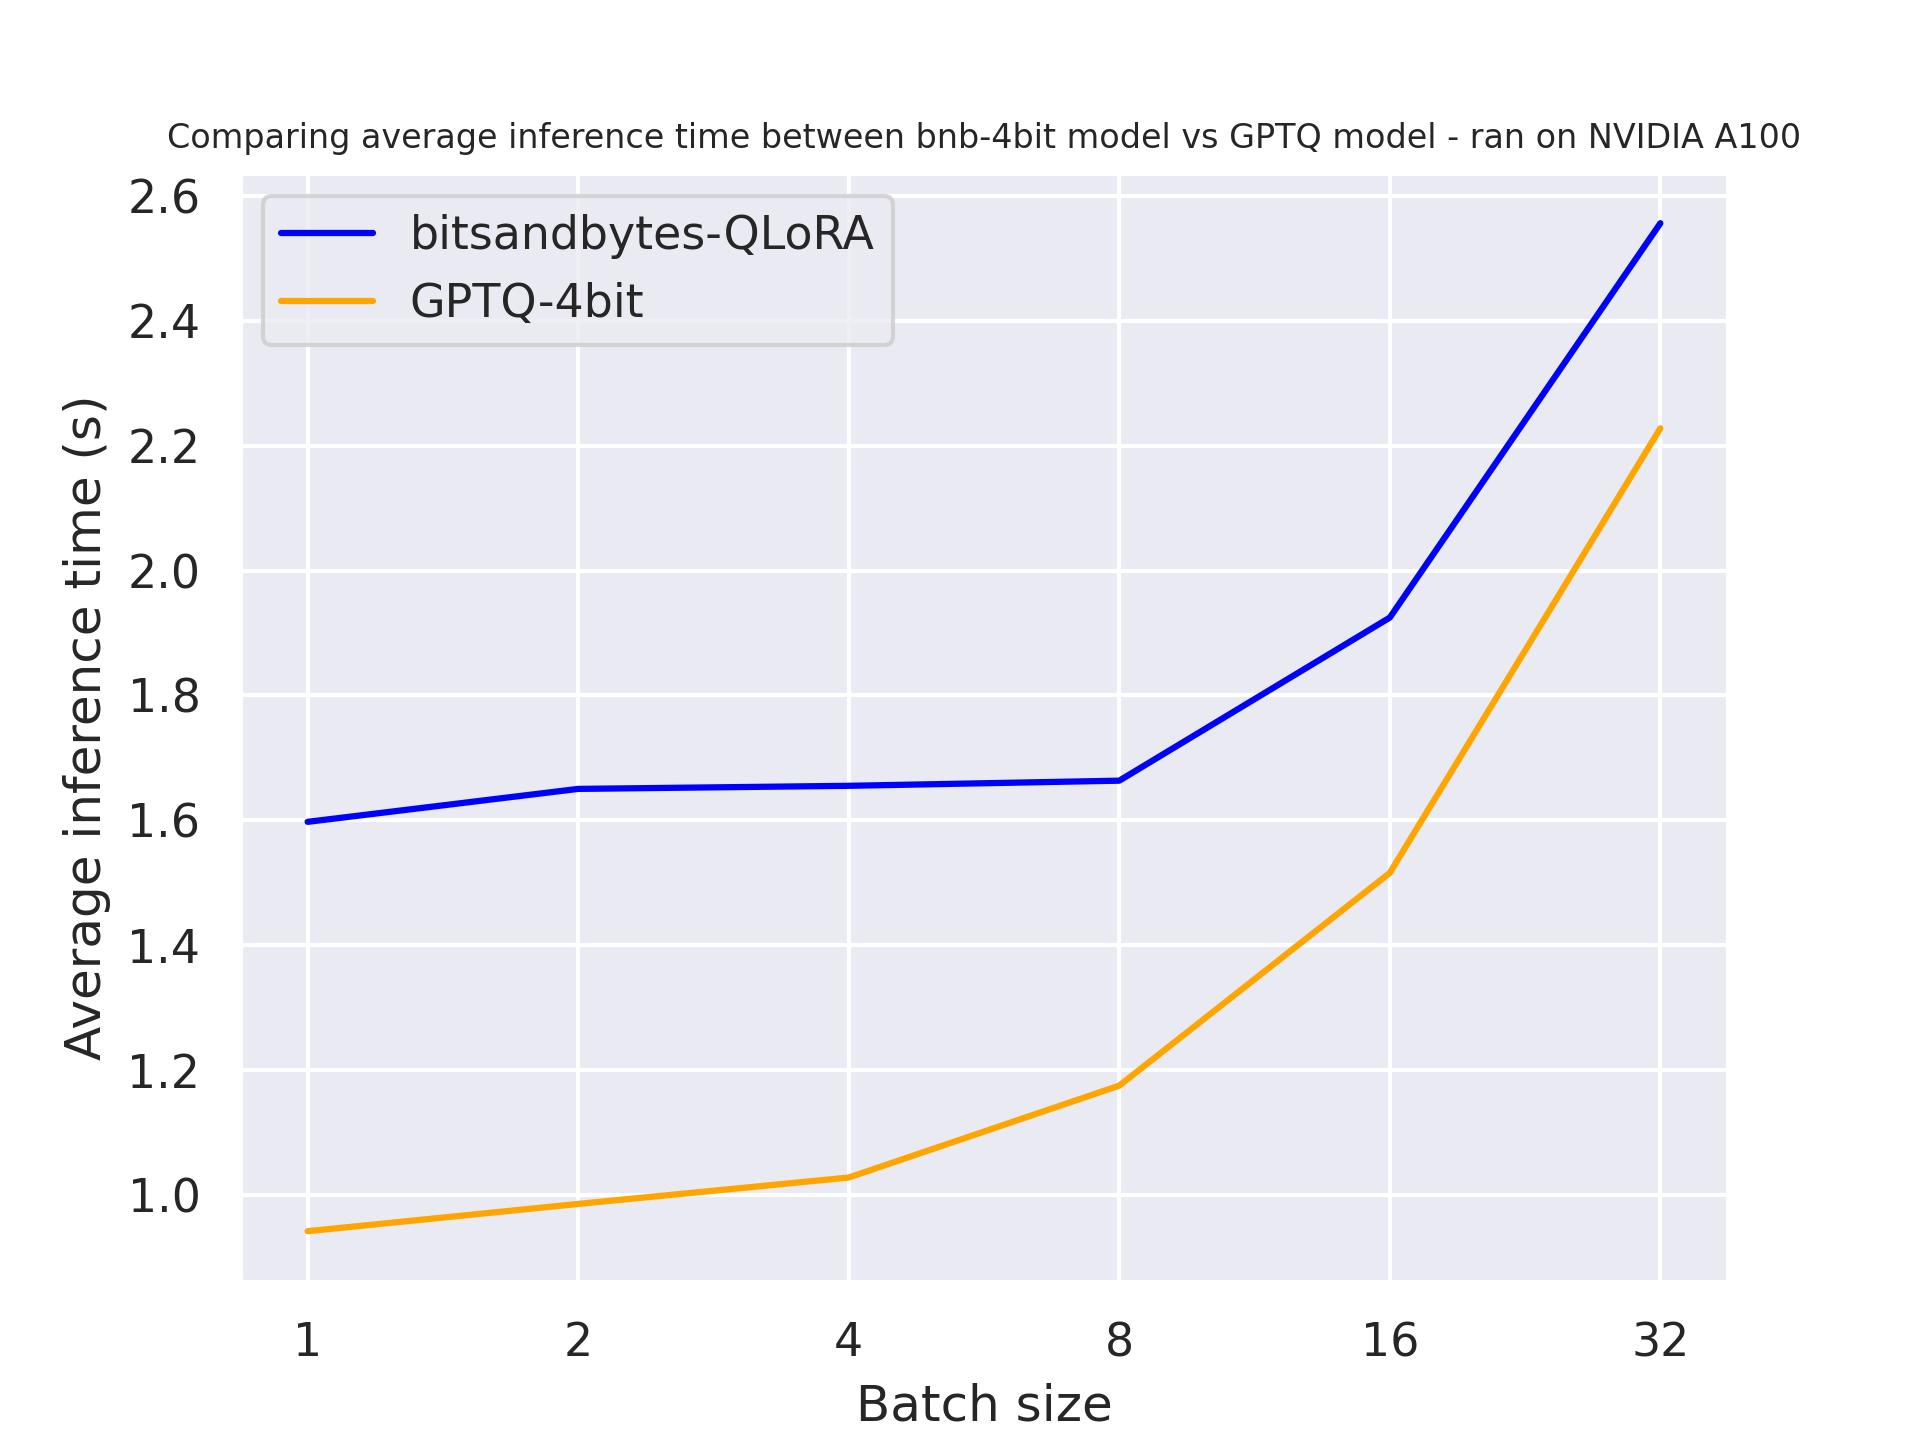
From the two benchmarks, we conclude that generation is faster when we use attention caching, as expected. Moreover, GPTQ is, in general, faster than bitsandbytes. For example, with batch_size=4 and use_cache=True, it is twice as fast! Therefore let’s use use_cache for the next benchmarks. Note that use_cache will consume more memory.
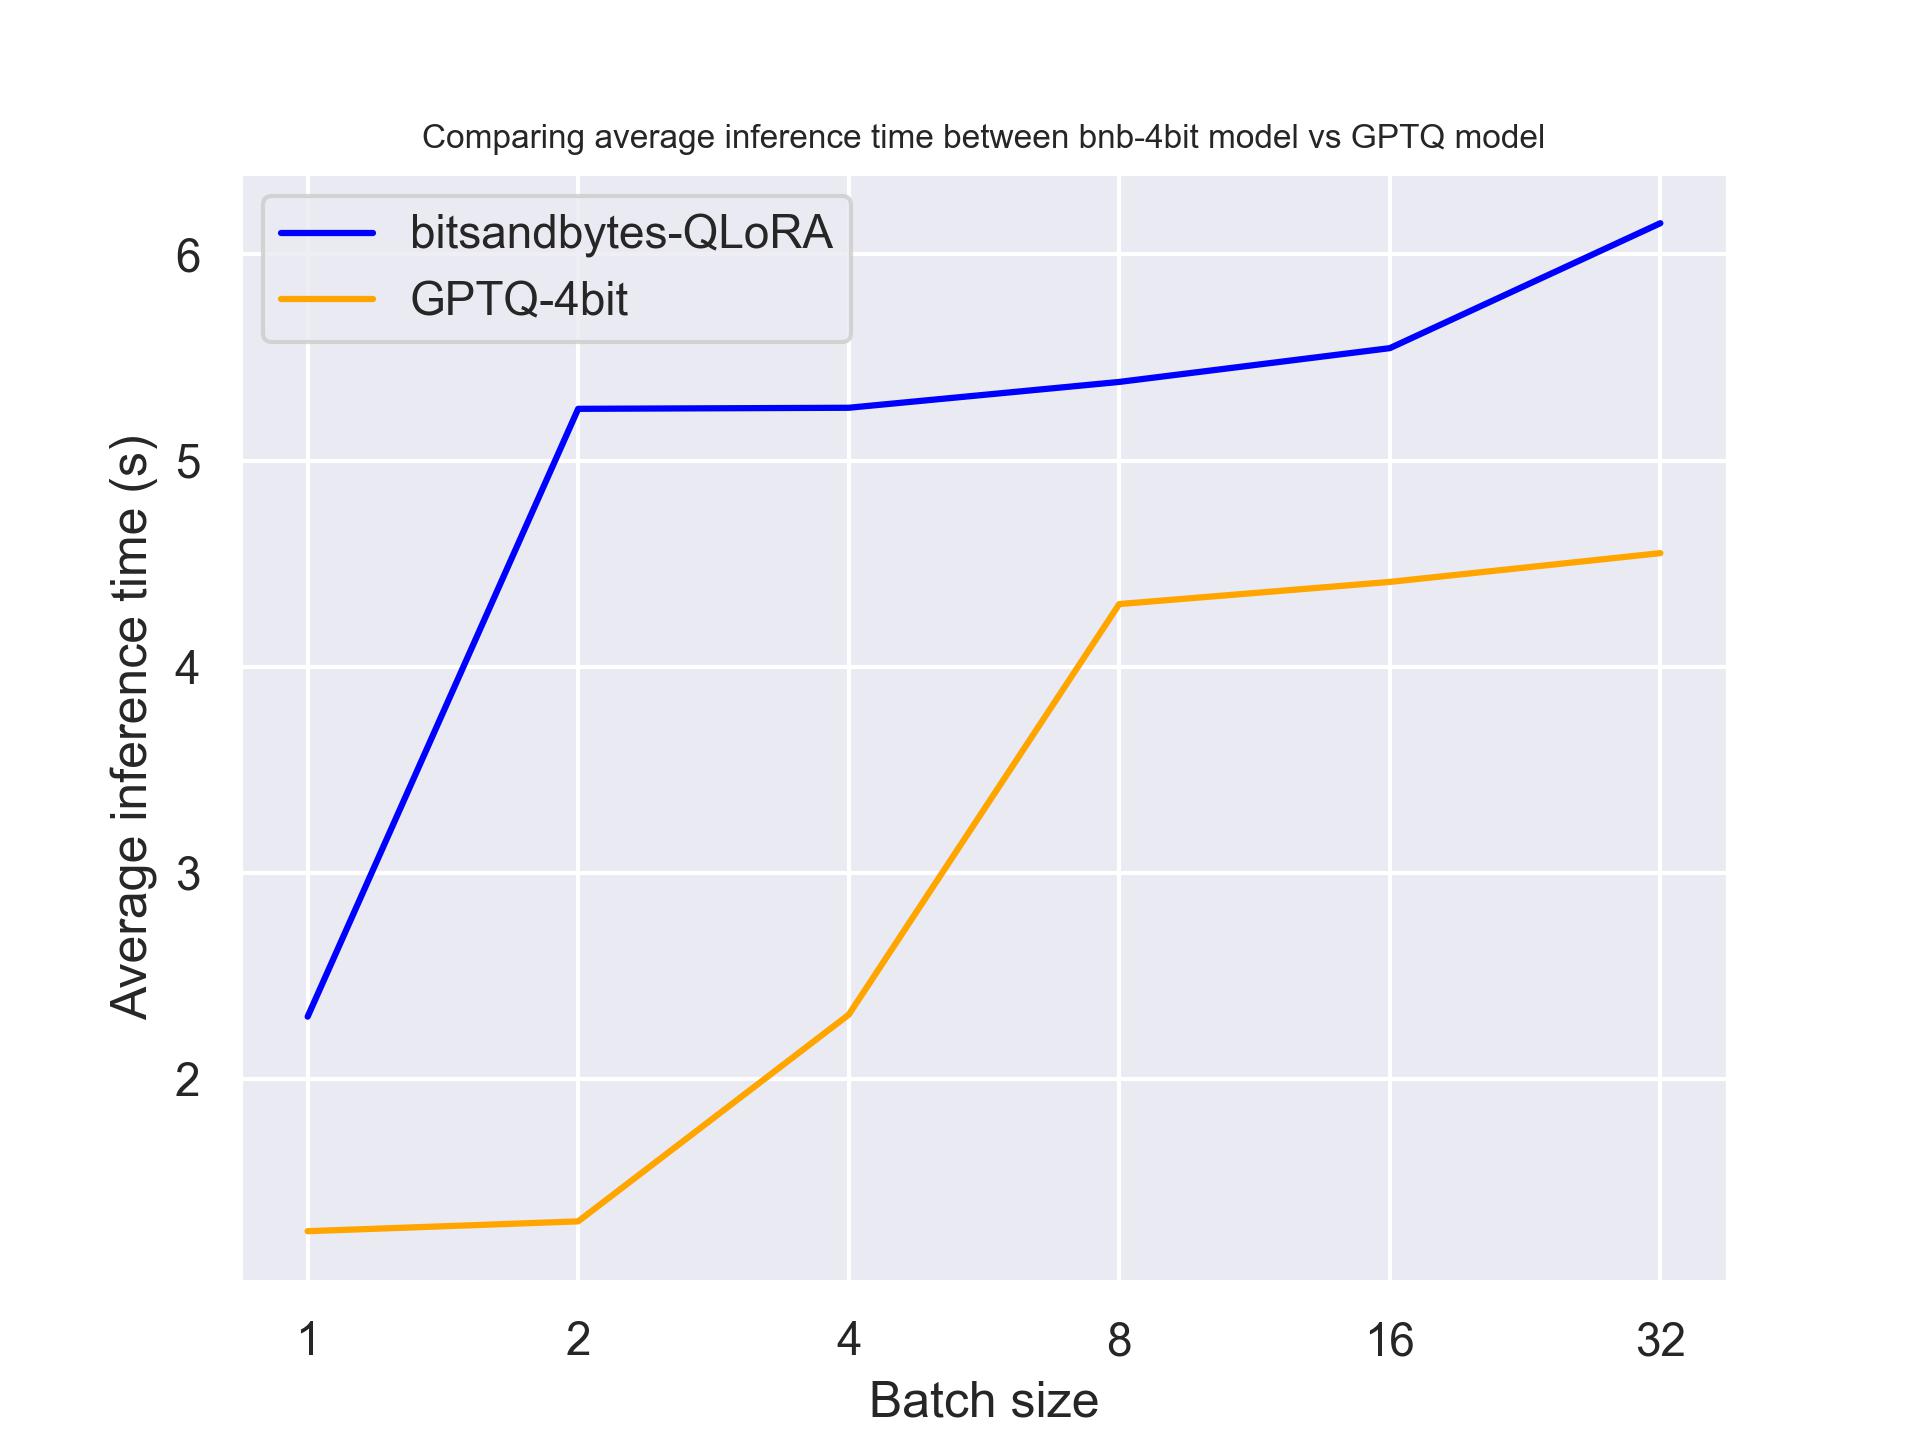
In the following benchmark, we will try different hardware to see the impact on the quantized model. We used a prompt length of 30 and we generated exactly 30 tokens. The model we used was meta-llama/Llama-2-7b-hf.
with a NVIDIA A100:
with a NVIDIA T4:
with a Titan RTX:
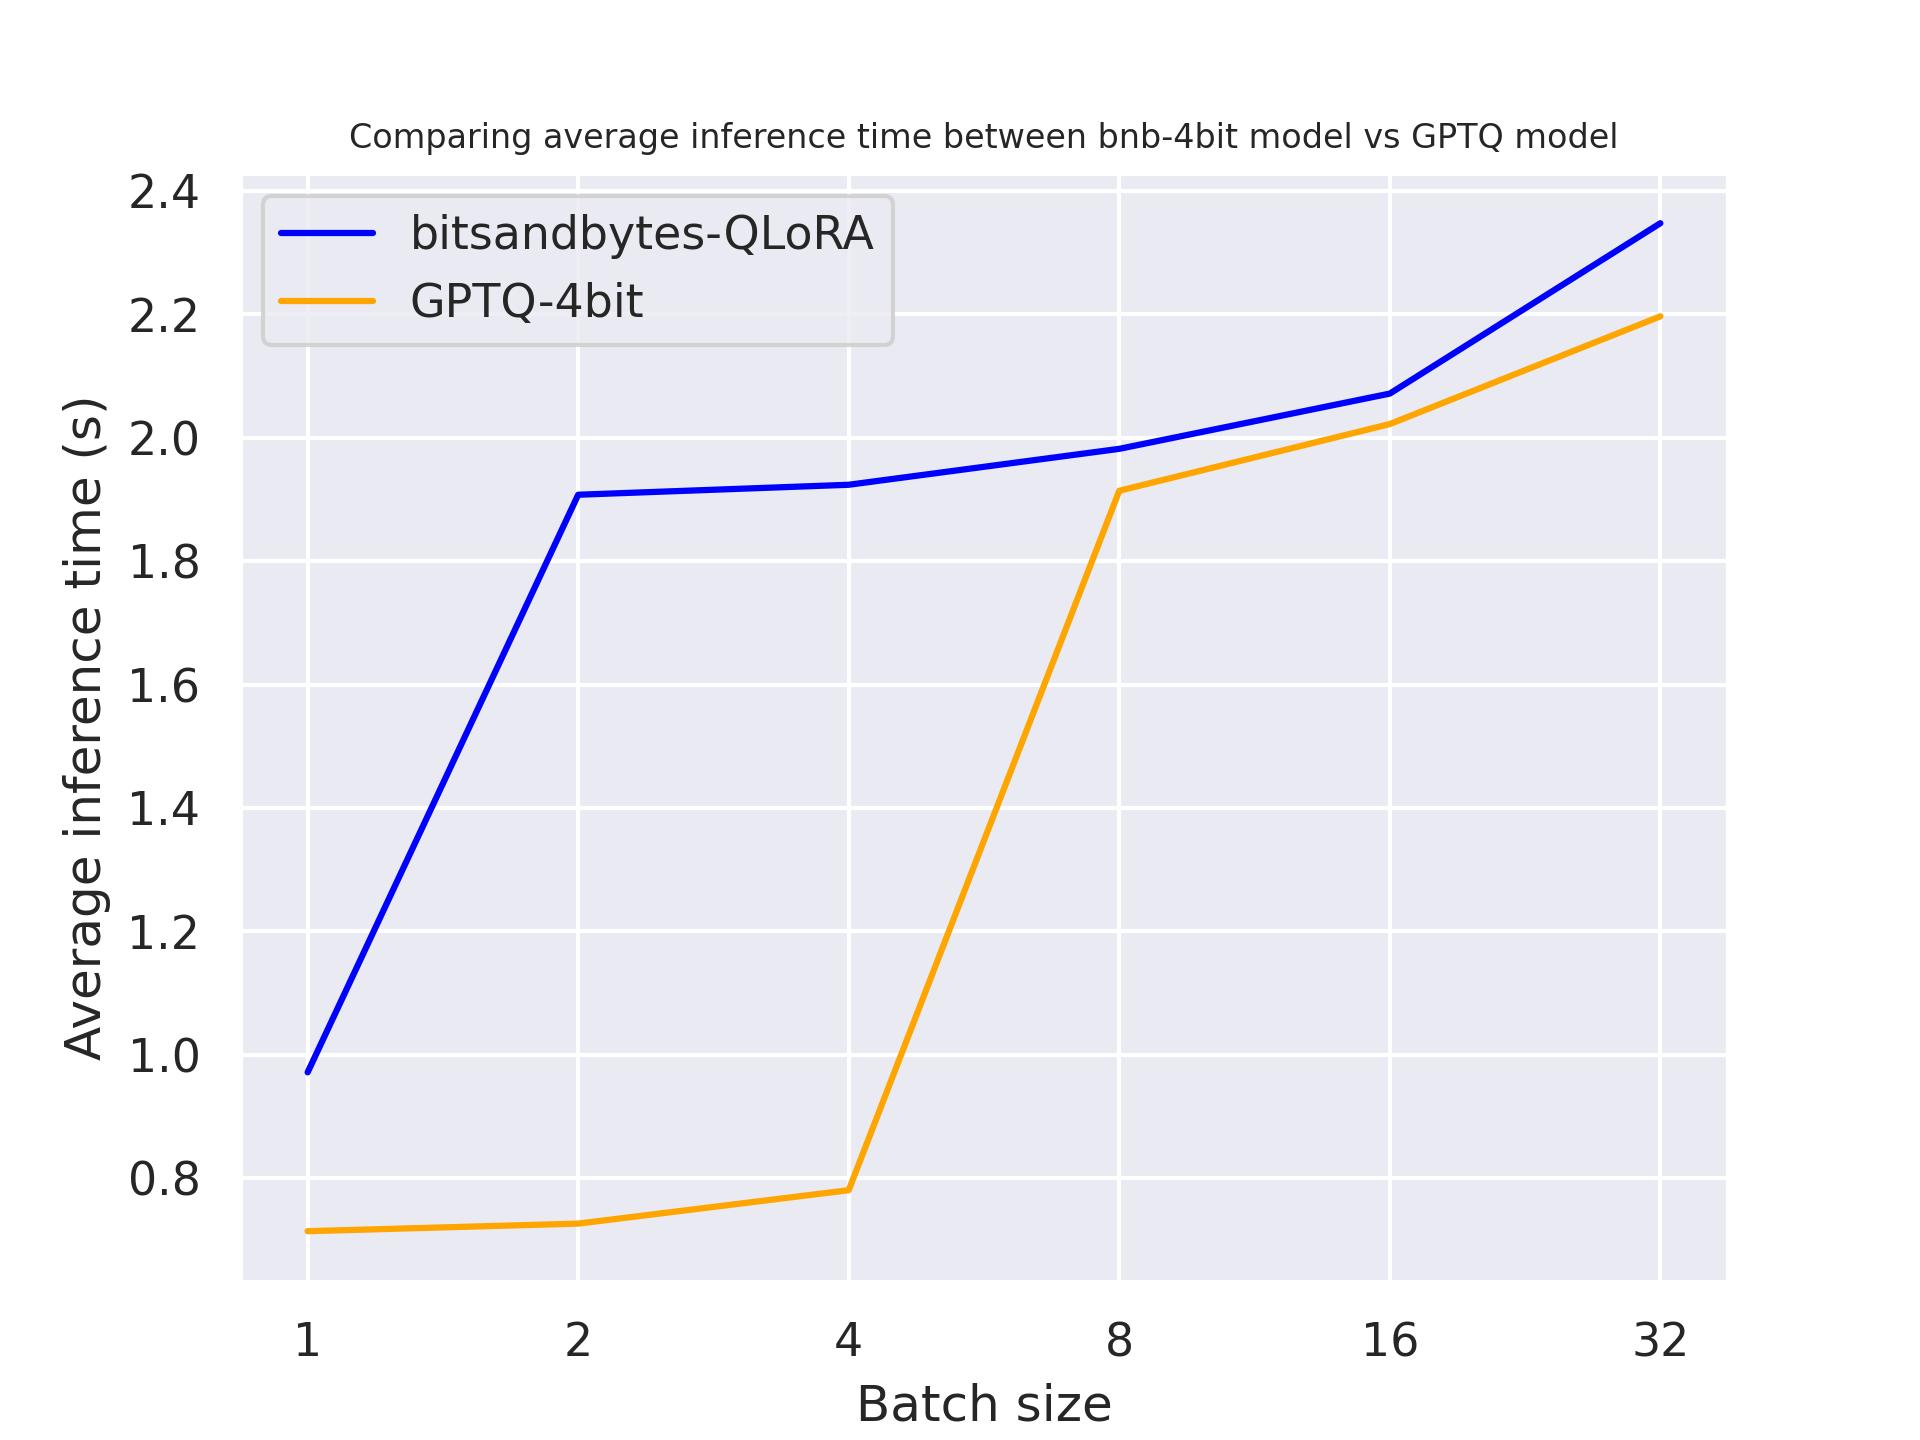
From the benchmark above, we can conclude that GPTQ is faster than bitsandbytes for those three GPUs.
In the following benchmark, we will try different generation lengths to see their impact on the quantized model. It was run on a A100 and we used a prompt length of 30, and varied the number of generated tokens. The model we used was meta-llama/Llama-2-7b-hf.
with 30 tokens generated:
with 512 tokens generated:
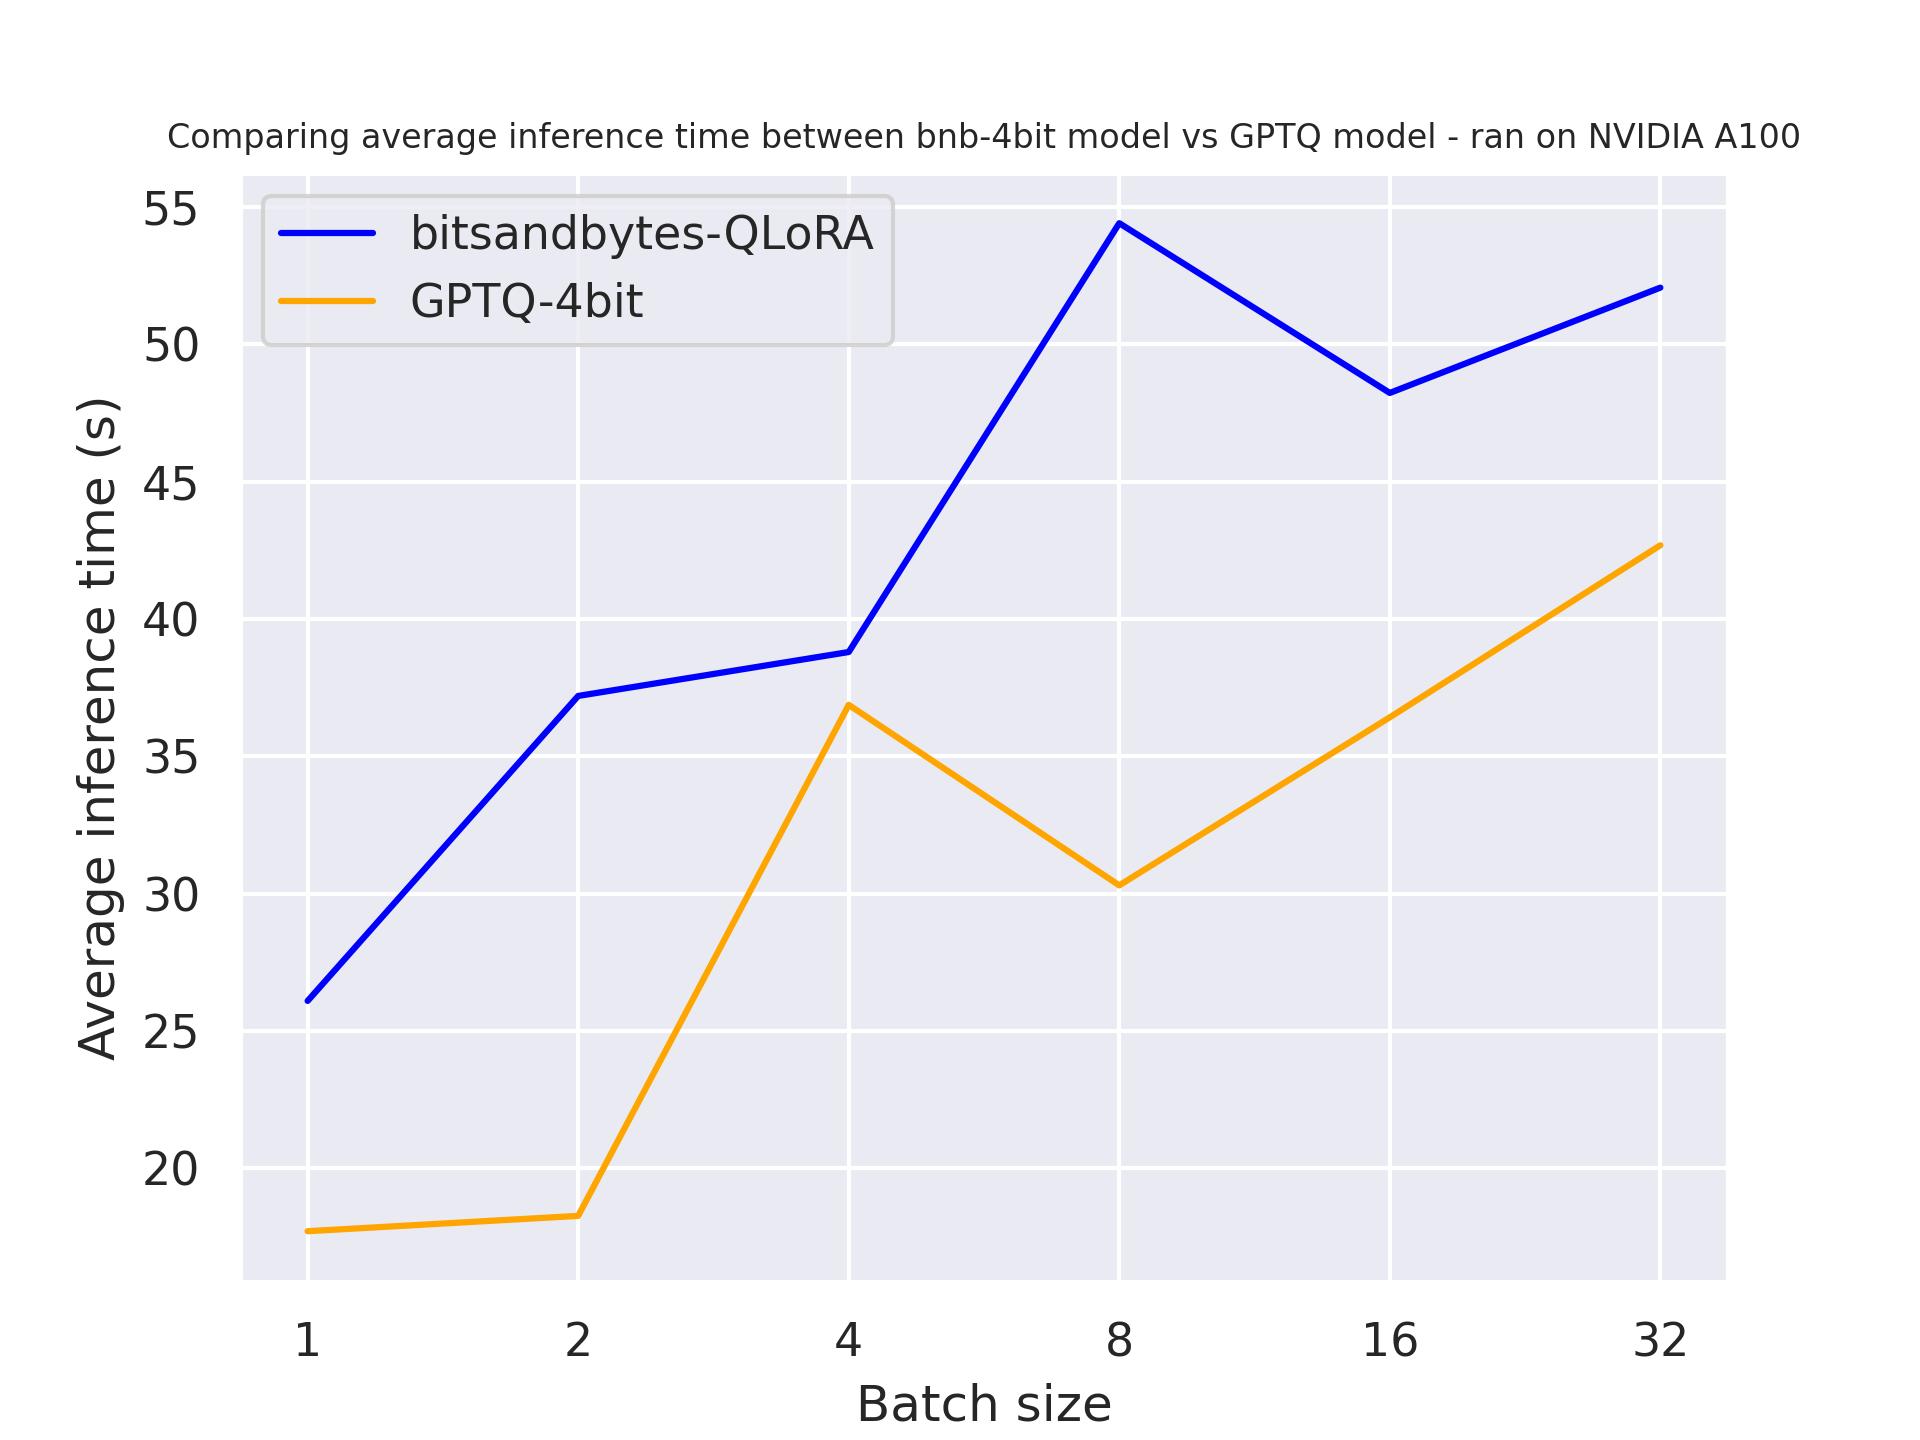
From the benchmark above, we can conclude that GPTQ is faster than bitsandbytes independently of the generation length.
It is not possible to perform pure training on a quantized model. However, you can fine-tune quantized models by leveraging parameter efficient fine tuning methods (PEFT) and train adapters on top of them. The fine-tuning method will rely on a recent method called "Low Rank Adapters" (LoRA): instead of fine-tuning the entire model you just have to fine-tune these adapters and load them properly inside the model. Let's compare the fine-tuning speed!
The benchmark was run on a NVIDIA A100 GPU and we used meta-llama/Llama-2-7b-hf model from the Hub. Note that for GPTQ model, we had to disable the exllama kernels as exllama is not supported for fine-tuning.
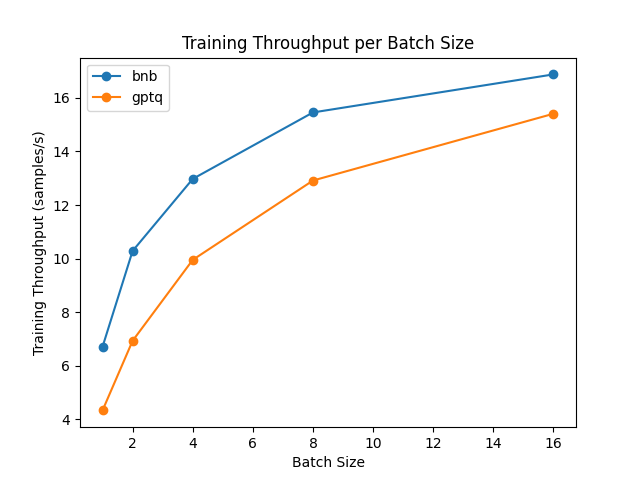
From the result, we conclude that bitsandbytes is faster than GPTQ for fine-tuning.
Quantization is great for reducing memory consumption. However, it does come with performance degradation. Let's compare the performance using the Open-LLM leaderboard !
with 7b model:
| model_id | Average | ARC | Hellaswag | MMLU | TruthfulQA |
|---|---|---|---|---|---|
| meta-llama/llama-2-7b-hf | 54.32 | 53.07 | 78.59 | 46.87 | 38.76 |
| meta-llama/llama-2-7b-hf-bnb-4bit | 53.4 | 53.07 | 77.74 | 43.8 | 38.98 |
| TheBloke/Llama-2-7B-GPTQ | 53.23 | 52.05 | 77.59 | 43.99 | 39.32 |
with 13b model:
| model_id | Average | ARC | Hellaswag | MMLU | TruthfulQA |
|---|---|---|---|---|---|
| meta-llama/llama-2-13b-hf | 58.66 | 59.39 | 82.13 | 55.74 | 37.38 |
| TheBloke/Llama-2-13B-GPTQ (revision = 'gptq-4bit-128g-actorder_True') | 58.03 | 59.13 | 81.48 | 54.45 | 37.07 |
| TheBloke/Llama-2-13B-GPTQ | 57.56 | 57.25 | 81.66 | 54.81 | 36.56 |
| meta-llama/llama-2-13b-hf-bnb-4bit | 56.9 | 58.11 | 80.97 | 54.34 | 34.17 |
From the results above, we conclude that there is less degradation in bigger models. More interestingly, the degradation is minimal!
In this blogpost, we compared bitsandbytes and GPTQ quantization across multiple setups. We saw that bitsandbytes is better suited for fine-tuning while GPTQ is better for generation. From this observation, one way to get better merged models would be to:
We hope that this overview will make it easier for everyone to use LLMs in their applications and usecases, and we are looking forward to seeing what you will build with it!
We would like to thank Ilyas, Clémentine and Felix for their help on the benchmarking.
Finally, we would like to thank Pedro Cuenca for his help with the writing of this blogpost.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。