


This article is also available in Chinese 简体中文.
In recent times, the AI community has witnessed a remarkable surge in the development of larger and more performant language models, such as Falcon 40B, LLaMa-2 70B, Falcon 40B, MPT 30B, and in the imaging domain with models like SD2.1 and SDXL. These advancements have undoubtedly pushed the boundaries of what AI can achieve, enabling highly versatile and state-of-the-art image generation and language understanding capabilities. However, as we marvel at the power and complexity of these models, it is essential to recognize a growing need to make AI models smaller, efficient, and more accessible, particularly by open-sourcing them.
At Segmind, we have been working on how to make generative AI models faster and cheaper. Last year, we have open-sourced our accelerated SD-WebUI library called voltaML, which is a AITemplate/TensorRT based inference acceleration library that has delivered between 4-6X increase in the inference speed. To continue towards the goal of making generative models faster, smaller and cheaper, we are open-sourcing the weights and training code of our compressed SD models; SD-Small and SD-Tiny. The pretrained checkpoints are available on Huggingface 🤗
Our new compressed models have been trained on Knowledge-Distillation (KD) techniques and the work has been largely based on this paper. The authors describe a Block-removal Knowledge-Distillation method where some of the UNet layers are removed and the student model weights are trained. Using the KD methods described in the paper, we were able to train two compressed models using the 🧨 diffusers library; Small and Tiny, that have 35% and 55% fewer parameters, respectively than the base model while achieving comparable image fidelity as the base model. We have open-sourced our distillation code in this repo and pretrained checkpoints on Huggingface 🤗.
Knowledge-Distillation training a neural network is similar to a teacher guiding a student step-by-step. A large teacher model is pre-trained on a large amount of data and then a smaller model is trained on a smaller dataset, to imitate the outputs of the larger model along with classical training on the dataset.
In this particular type of knowledge distillation, the student model is trained to do the normal diffusion task of recovering an image from pure noise, but at the same time, the model is made to match the output of the larger teacher model. The matching of outputs happens at every block of the U-nets, hence the model quality is mostly preserved. So, using the previous analogy, we can say that during this kind of distillation, the student will not only try to learn from the Questions and Answers but also from the Teacher’s answers, as well as the step by step method of getting to the answer. We have 3 components in the loss function to achieve this, firstly the traditional loss between latents of the target image and latents of the generated image. Secondly, the loss between latents of the image generated by the teacher and latents of image generated by the student. And lastly, and the most important component, is the feature level loss, which is the loss between the outputs of each of the blocks of the teacher and the student.
Combining all of this makes up the Knowledge-Distillation training. Below is an architecture of the Block Removed UNet used in the KD as described in the paper.
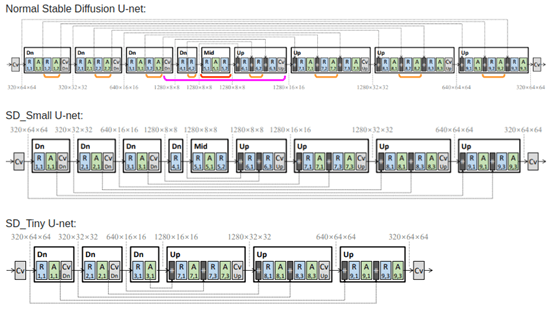
Image taken from the paper “On Architectural Compression of Text-to-Image Diffusion Models” by Shinkook. et. al
We have taken Realistic-Vision 4.0 as our base teacher model and have trained on the LAION Art Aesthetic dataset with image scores above 7.5, because of their high quality image descriptions. Unlike the paper, we have chosen to train the two models on 1M images for 100K steps for the Small and 125K steps for the Tiny mode respectively. The code for the distillation training can be found here.
The Model can be used using the DiffusionPipeline from 🧨 diffusers
from diffusers import DiffusionPipeline
import torch

pipeline = DiffusionPipeline.from_pretrained("segmind/small-sd", torch_dtype=torch.float16)
prompt = "Portrait of a pretty girl"
negative_prompt = "(deformed iris, deformed pupils, semi-realistic, cgi, 3d, render, sketch, cartoon, drawing, anime:1.4), text, close up, cropped, out of frame, worst quality, low quality, jpeg artifacts, ugly, duplicate, morbid, mutilated, extra fingers, mutated hands, poorly drawn hands, poorly drawn face, mutation, deformed, blurry, dehydrated, bad anatomy, bad proportions, extra limbs, cloned face, disfigured, gross proportions, malformed limbs, missing arms, missing legs, extra arms, extra legs, fused fingers, too many fingers, long neck"
image = pipeline(prompt, negative_prompt = negative_prompt).images[0]
image.save("my_image.png")
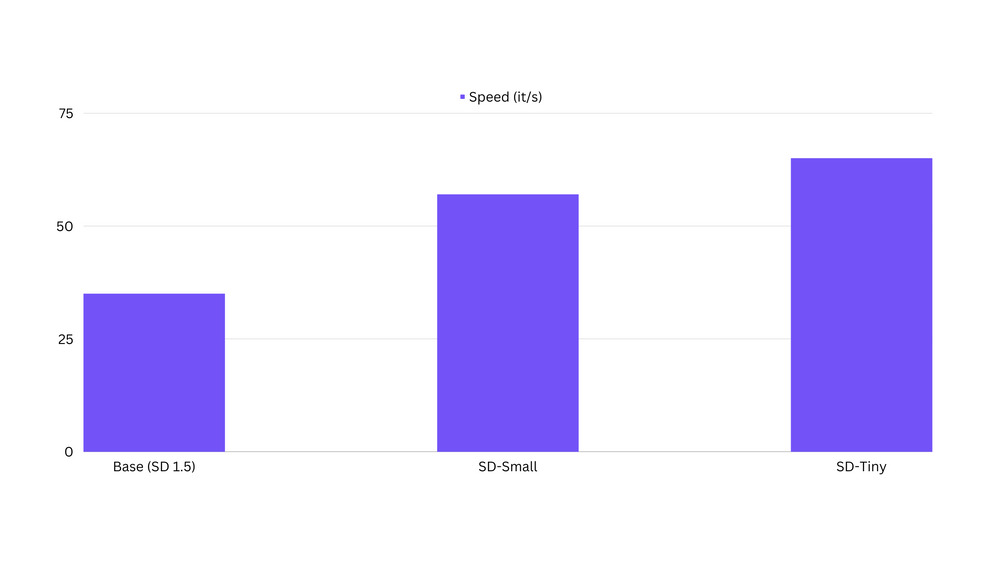
We have observed that distilled models are up to 100% faster than the original base models. The Benchmarking code can be found here.
The distilled models are in early phase and the outputs may not be at a production quality yet. These models may not be the best general models. They are best used as fine-tuned or LoRA trained on specific concepts/styles. Distilled models are not very good at composibility or multiconcepts yet.
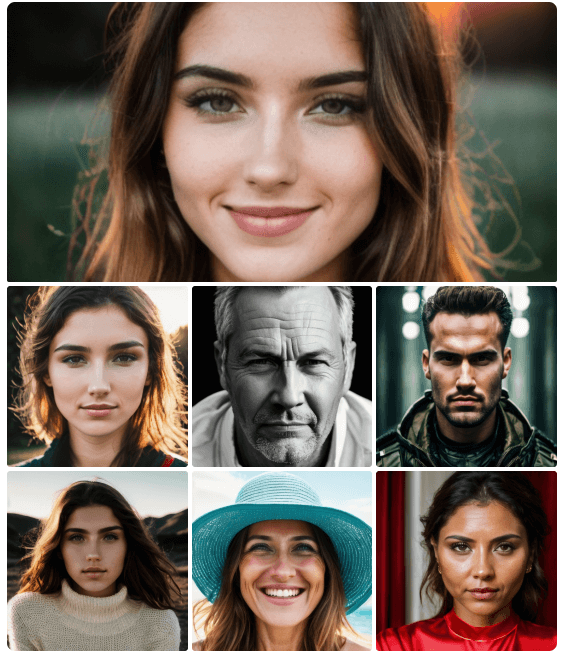
We have fine-tuned our sd-tiny model on portrait images generated with the Realistic Vision v4.0 model. Below are the fine tuning parameters used.
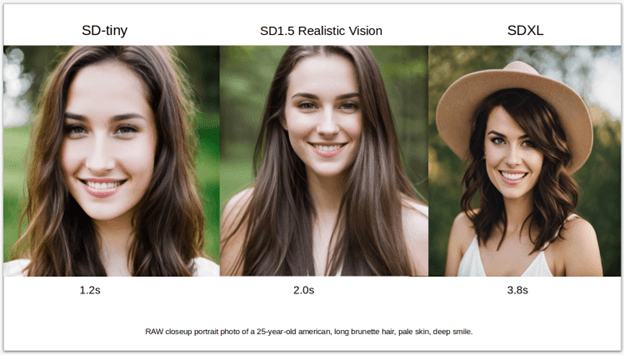
We were able to produce image quality close to the images produced by the original model, with almost 40% fewer parameters and the sample results below speak for themselves:
The code for fine-tuning the base models can be found here.
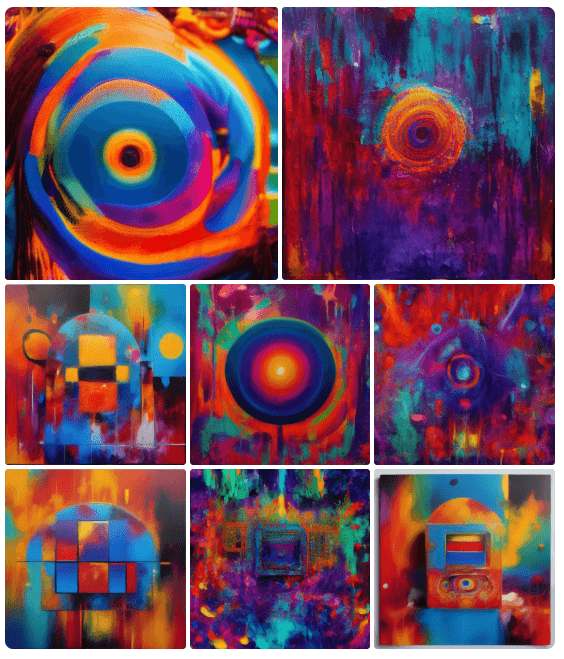
One of the advantages of LoRA training on a distilled model is faster training. Below are some of the images of the first LoRA we trained on the distilled model on some abstract concepts. The code for the LoRA training can be found here.
We invite the open-source community to help us improve and achieve wider adoption of these distilled SD models. Users can join our Discord server, where we will be announcing the latest updates to these models, releasing more checkpoints and some exciting new LoRAs. And if you like our work, please give us a star on our Github.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。