


We’re thrilled to announce the release of Snorkel Flow 2023.R4, a continuation of our commitment to creating a robust AI data development platform that empowers enterprises to accelerate custom AI data breakthroughs by 100x. This release introduces new features and enhancements designed to streamline processes and boost performance for even the most challenging scenarios.
Before we delve into the details, here’s a quick tl;dr of what is included in this latest release:
Working with PDF data often involves annotating entire documents, not just individual tokens—especially when dealing with large files or sparse entities.
Using Snorkel Flow 2023.R4, users can now quickly and effortlessly sample specific documents at the document level using document IDs. This new feature simplifies the data annotation process, allowing for a more targeted approach rather than sampling annotation data by spans.
Whether you’re handling large PDFs or just focused on individual unique structures (e.g. tables, diagrams, etc.) these improvements enhance your overall experience and efficiency.
Our new unified prompting interface enables users to construct more freeform prompts, giving you the flexibility and control needed to programmatically operate on your data. Now, you can prompt foundation models for multi-label classification, and batch processes by selecting the batch size, and run the prompt on a subset before scaling to your entire dataset.
This will not only enhance efficiency across all your Snorkel Flow applications but also provide a safer, more controlled environment for testing and iteration.
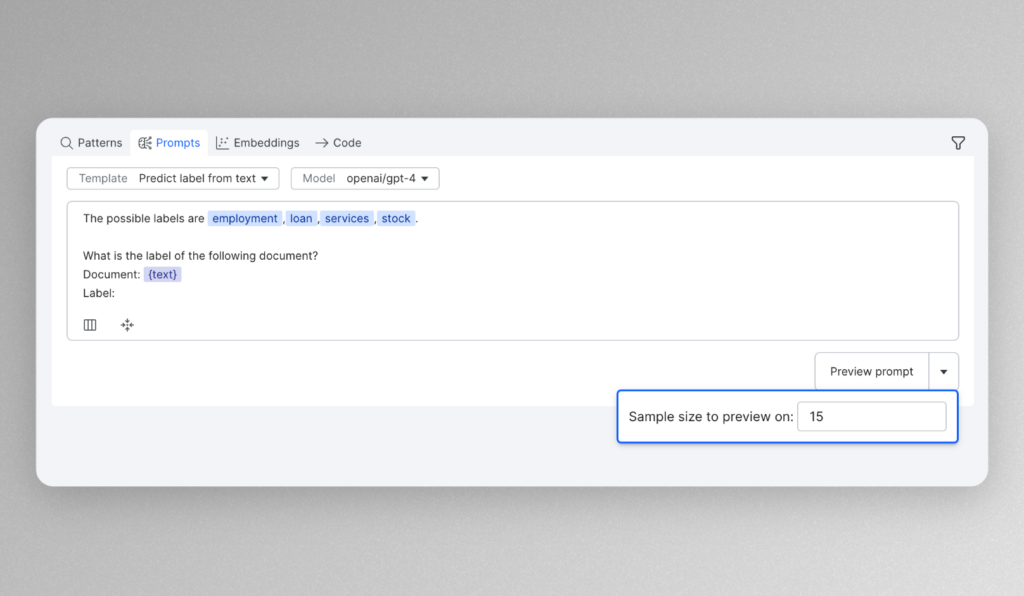
Additionally, we’ve implemented an all-new RAG integration (Alpha) into the prompting workflow. RAG is becoming a market standard for enhancing prompting workflows to improve the accuracy of generative AI outputs. If you want to see this functionality in action, sign up for a demo.
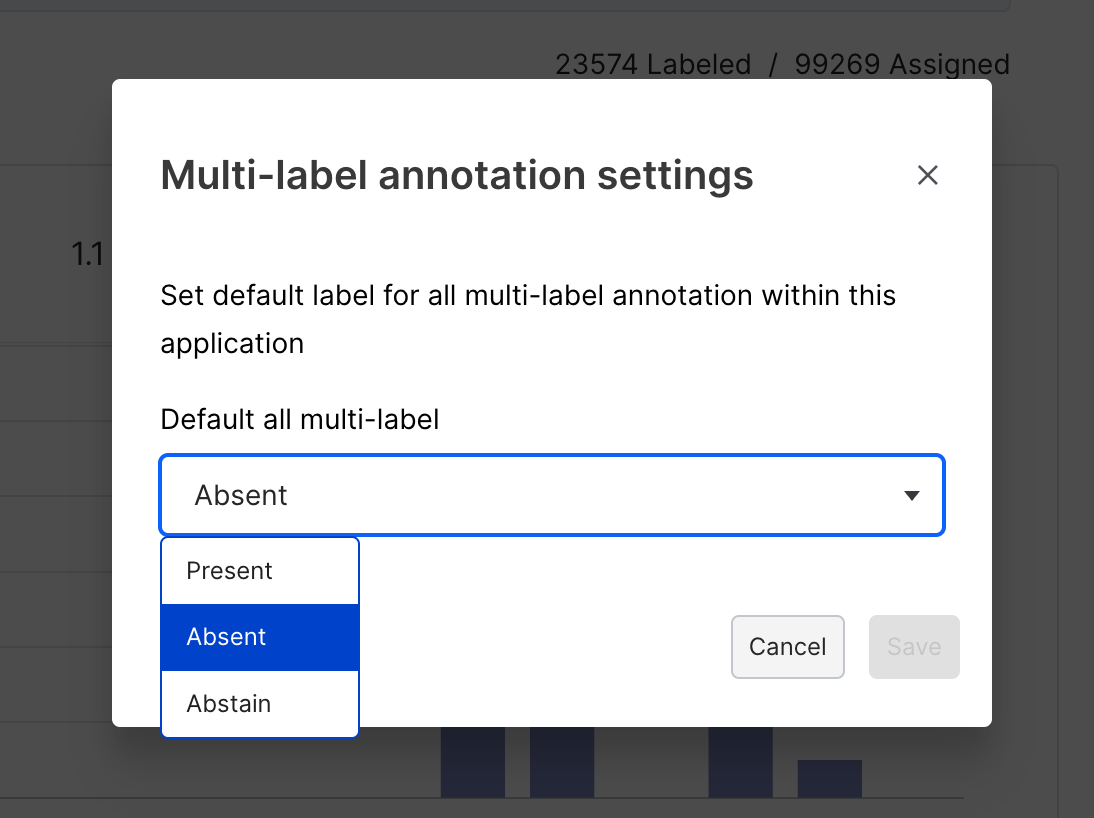
Consistent labels are vital for any AI/ML project; without them, model performance suffers. This is especially important when multiple teams work on the same data.
Without a shared understanding of what each label means, team members might misinterpret the data, causing errors in the dataset and any insights derived from it. To prevent this, 2023.R4 will have the option for users to configure multi-label annotation defaults to match individual team preferences.
Snorkel Flow is purposefully engineered to seamlessly integrate into an enterprise’s existing MLOps workflow. We continually work to make it as fast and as easy as possible for our customers to deploy what they’ve built in Snorkel Flow into production.
As of the 2023.R4 release, we’re thrilled to expand our existing Databricks support to incorporate the Databricks MLflow Model Registry. Using this new native integration enables users to deploy their machine learning models directly to the Databricks MLflow Model Registry, streamlining the deployment process and enhancing efficiency.
In this release, we’ve dedicated considerable effort to simplifying and streamlining the critical initial phases of AI development.
Our SDK now boasts improved documentation for both built-in and custom operators, complemented by an intuitive interface for easy retrieval of node data and metadata. These enhancements are designed to make the onboarding process as smooth and efficient as possible while reducing the effort needed to wrangle large amounts of data.
In the 2023.R4 release, we’ve implemented numerous enhancements to bolster the overall performance and stability of the platform. These improvements are designed to benefit a diverse range of deployments and infrastructures. Notably, Snorkel Flow Studio and datasets now load in half the time, making the experience significantly faster. The Studio data viewer has been upgraded for a more instantaneous interaction. Additionally, we’ve expanded our sequence tagging support from 10 to 25 classes, broadening the scope and capabilities of our platform to meet your complex needs.
And that wraps up the 2023.R4 Snorkel Flow release. Until the next one!
Follow Snorkel AI on LinkedIn, Twitter, and YouTube to be the first to see new posts and videos!
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。