






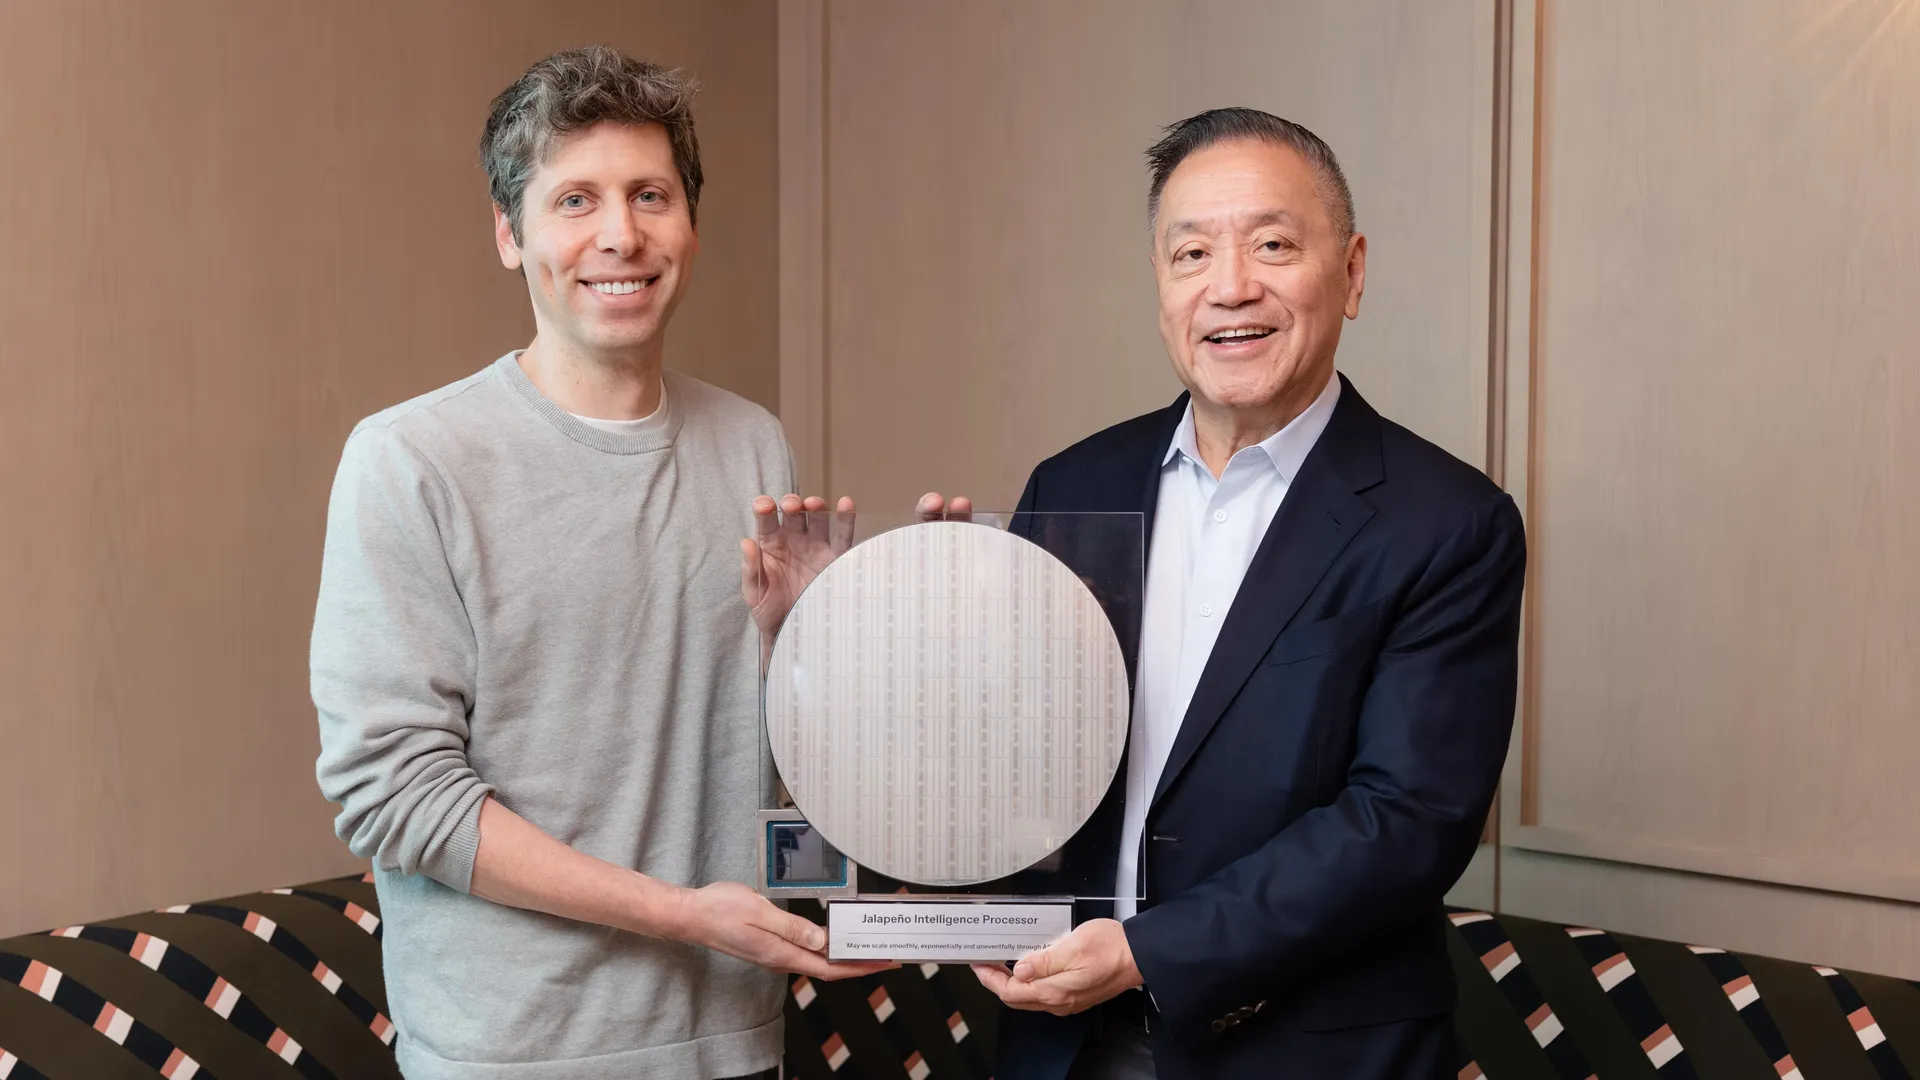
OpenAI and Broadcom have introduced Jalapeño, a custom-built inference processor designed specifically for modern large language models and future agentic AI workloads, which is designed to deliver performance per watt they claim is higher than today's leading-edge hardware. OpenAI considers its hardware project a strategic one and envisions Jalapeño to be the first generation of its inference hardware.
Not another AI accelerator
OpenAI stresses that Jalapeño is a purpose-built inference ASIC and not a repurposed training accelerator or a general-purpose AI processor. OpenAI says the architecture of Jalapeño was designed based on its understanding of LLM behavior and is meant to address practical bottlenecks that matter for inference at scale, including costly data movement, balance between compute and memory resources, networking efficiency, and overall behavior. OpenAI also states that the design of the processor is meant to wed high throughput with low latency (which is why it uses a huge compute chiplet and HBM memory and not cheaper types of DRAM like many other inference accelerators), which will be particularly handy for reasoning and agentic workloads.
In addition, OpenAI and Broadcom claim the processor is built to deliver higher effective utilization than conventional AI accelerators and deliver performance that is close to the theoretical maximum, which means very high efficiency both in terms of costs and in terms of power. Meanwhile, the companies did not disclose performance targets for their Jalapeño ASIC, so these claims should be taken with a grain of salt.
Engineering samples are already operating in the lab at target clock speed and power (though Broadcom and OpenAI do not disclose details about this, either), and OpenAI says it is running machine learning workloads, such as GPT-5.3-Codex-Spark.
The two companies also claim that early internal testing indicates that Jalapeño's performance-per-watt is substantially better than 'current state-of-the-art hardware,' although no hard numbers, benchmarks, memory configuration, or other details are disclosed, so again, we will have to take the claims with a grain of salt. In addition, one must bear in mind that while Jalapeño can purportedly beat existing AMD's Instinct MI350-series and Nvidia's Blackwell-based accelerators, it remains to be seen how competitive it will be against AMD's Instinct MI400-series and Nvidia's Rubin-based offerings.
"Jalapeño was designed from the ground up for LLM inference using detailed insights from our close collaboration with OpenAI researchers," said Richard Ho, who leads OpenAI's hardware program. "We optimized the architecture around the kernels, memory movement, networking, and serving patterns that matter most for frontier AI models. Based on early testing, Jalapeño will efficiently execute our most important workloads close to the hardware’s theoretical limits."
A massive chip with six HBM modules
While Broadcom and OpenAI did not disclose specifications of Jalapeño, they did show its wafer and packaging, so we can do a brief analysis. The package appears to contain one large compute chiplet surrounded by six HBM modules and another chiplet that likely packs input/output interfaces and is surrounded by two structural dummy dies.
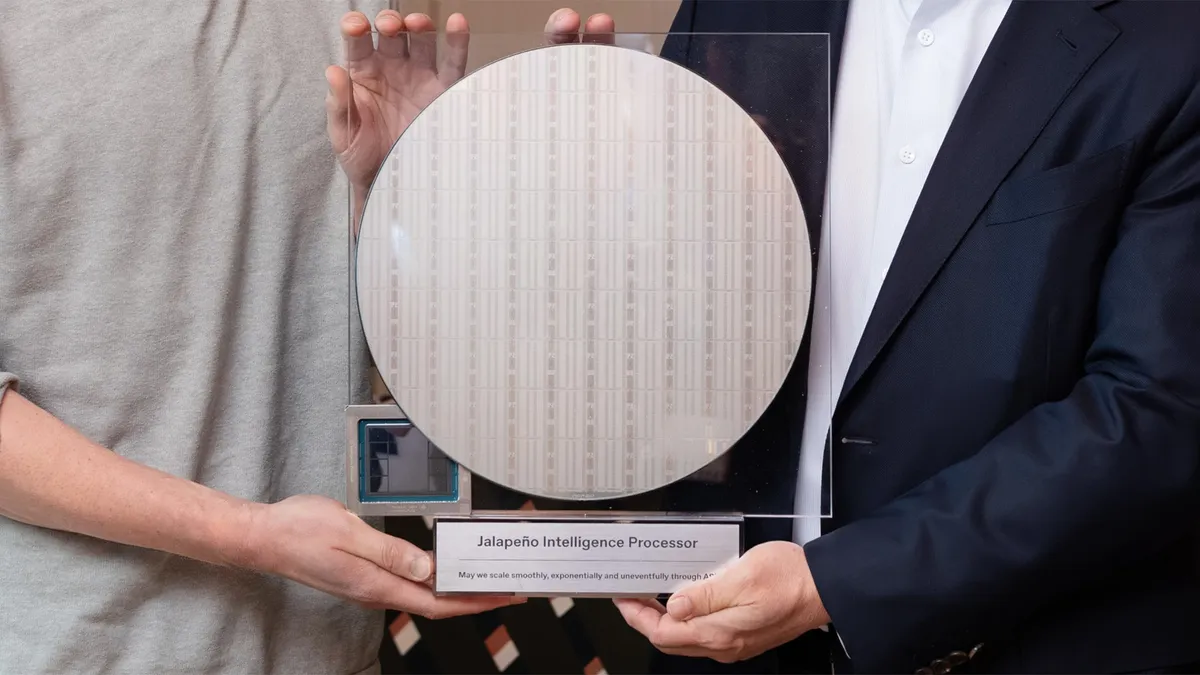
The wafer image does look like a Broadcom-style systolic-array-heavy accelerator, in the sense that it shows a very regular, repeated, columnar floorplan with what looks like replicated compute regions and fixed infrastructure macros. Yet, keep in mind that we are speculating, and the image is not clean enough to say that this is definitely Broadcom's standard TPU-like systolic array template with some perks from OpenAI,
From the image alone, it is impossible to tell whether Jalapeño uses a true 2D systolic array, a set of 1D/2D matrix engines, a collection of vector or tensor tiles, or some other inference datapath. All we can say is that the die has a highly repetitive floorplan consistent with several kinds of tiled AI accelerator architectures.
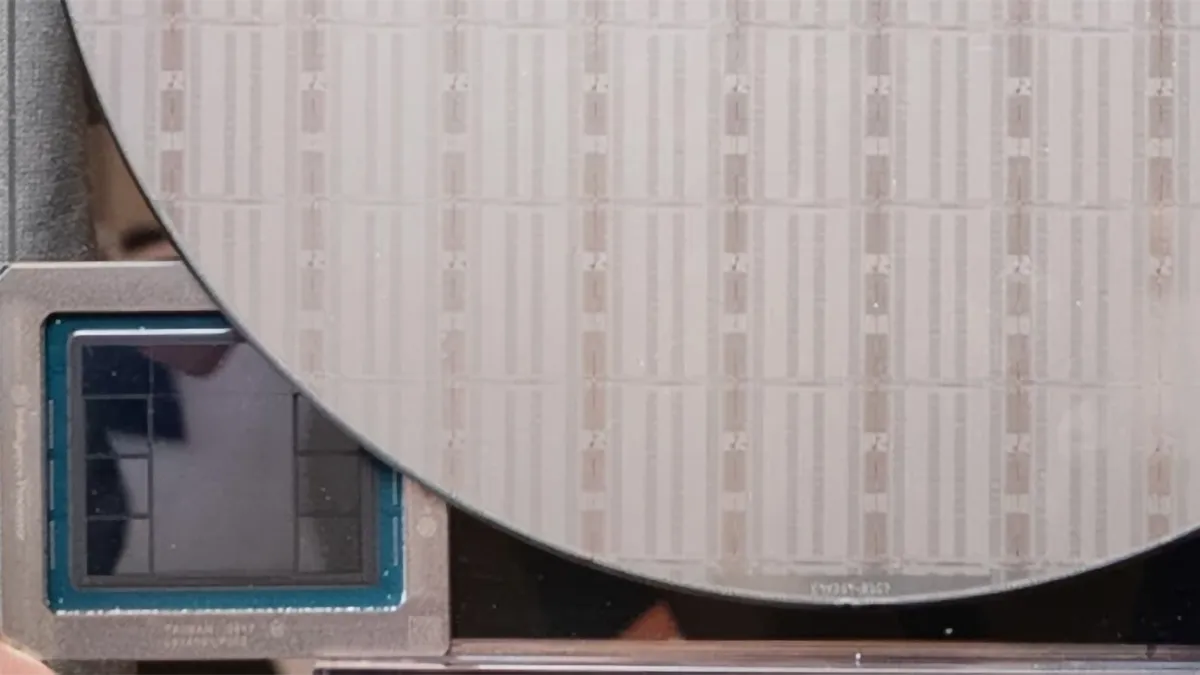
What we can tell from the image is the approximate die size of Jalapeño's compute chiplet based on the size of HBM3/4 packages (10.975 mm × 10.975 mm) that surround it. From what we can tell, the chiplet measures 25.46 mm (width) × 33 mm (height), which means that its die size is around 840 mm2, which is very close to the reticle size of EUV lithography systems (858 mm2). Given that the quality of the shot is poor, the die size we estimate cannot be 100% accurate, but we suspect it is close enough.
The die size of Jalapeño's compute chiplet implies that it packs quite a lot of compute oomph, though, of course, we cannot make performance estimates based on this metric. Yet, it is safe to say that Jalapeño's compute die is considerably bigger than compute dies of other inference accelerators on the market and more resembles processors for AI training. Speaking of processors for AI training, we increasingly see multi-chiplet designs for these workloads as companies like AMD and Nvidia want to pack as much performance as possible. Meanwhile, the fact that OpenAI and Broadcom chose to go with a large compute chiplet possibly indicates that they wanted to reduce latencies by as much as possible.
Designed in nine months
The companies say the chip reached tape-out in just nine months and is slated for deployment beginning in late 2026, which represents an extremely fast turnaround time in ASIC design. It is unclear whether Broadcom and OpenAI extensively used artificial intelligence to define and then develop Jalapeño, though the companies admitted that they used OpenAI's models to speed up parts of the chip's design and optimization work. Typically, it takes 1.5 – 2 years to design an ASIC from scratch, so AI can shrink the development cycle. Another means to accelerate the design cycle is Broadcom's extensive reuse of its logic across different custom designs to deliver new chips faster than other companies.
It is noteworthy that, according to the announcement, Jalapeño is designed to support not only OpenAI's own workloads but also present and future LLMs across the industry, which potentially lets OpenAI sell its hardware to third parties, assuming that it can get enough supply from Broadcom and TSMC. Meanwhile, the chief executive of Broadcom indicates that Jalapeño will be deployed at gigawatt-scale data centers with Microsoft and other partners starting this year, though it is unclear whether the processor will be used exclusively for OpenAI workloads or will be available for other tenants as well.
"Our collaboration with OpenAI represents a fundamental commitment to scaling the physical infrastructure required for the next decade of AI," said Hock Tan, President and CEO, Broadcom. "This is just the beginning of a multi-generation roadmap. By co-developing our industry-leading silicon directly with OpenAI, we are enabling the deployment of gigawatt-scale data centers with Microsoft and other partners beginning in 2026."

Follow Tom's Hardware on Google News, or add us as a preferred source, to get our latest news, analysis, & reviews in your feeds.