Google’s Gemma 4 comes touted as the latest evolution of Google’s multi-modal model offerings. Gemma 4 not only offers reasoning and tool use, but vision and audio functionality, and it’s available in a range of model sizes that target servers and local devices.
What’s striking about Gemma 4 is that even at the higher end of its size range, it’s still decently performant on personal hardware. Google claims this is due to innovations in the architecture of the model, but the proof is in the trying. Gemma 4 is quite responsive.
To that end, I took Gemma 4 for a spin on my own hardware to see how it fared for its advertised tasks.
Gemma 4 model sizes
Gemma 4 comes in four basic sizes or “densities”:
- E2B: 2.3 billion effective parameters, 5.1 billion total, 128K max context window.
- E4B: 4.5 billion efffective parameters, 8 billion total, 128K max context window.
- 31B: 31 billion parameters (the “dense” version), 256K max context window. (You will probably not use this one on your own machine — it’s 62GB!)
- 26B A4B: A “mixture of experts” model with 4 billion “activated” parameters and 26 billion total parameters, 256K max context window.
Each of these model sizes is available in a slew of community-created editions, thanks to Gemma 4’s Apache 2 licensing. For instance, the 26B A4B model comes in a community edition with more compact quantizations (4-bit, 6-bit, etc.), which I used as one of the model mixes for this article.
The models I used:
- google/gemma-4-26b-a4b: 18GB model size, 4-bit quantization.
- lmstudio-community/gemma-4-E4B-it-GGUF: 6.3GB model size, 4-bit quantization.
- unsloth/gemma-4-E4B-it-GGUF: A popular alternate mix of the same model, available in multiple quantizations. I used the 4.84GB size with 4-bit quantization.
Test system and prompts
I ran each model using my now-standard test bed: LM Studio 0.4.10 on an AMD Ryzen 5 3600 6-core CPU (32GB RAM) and an Nvidia GeForce RTX 5060 (8GB VRAM).
For each model I ran a set of prompts:
- A vision-functionality prompt: “Create a caption for the attached image of no more than three sentences.” Another version of the prompt added: “… with no editorialization.” (The attached image is shown in one of the screenshots below.)
- Prompts intended to provoke web-search tool use and produce either detailed or simplified responses: “What is the copyright status of Franz Kafka’s works? Explain in detail” and “What did William Gibson think of Blade Runner?”
- A prompt for code generation and problem solving: “Python’s
piptool has a functionScriptMaker(accessed withfrom pip._vendor.distlib.scripts import ScriptMaker). On Microsoft Windows this is used to create an .exe stub launcher for a Python package’s entry points when it’s installed withpip. However, the icon created for this stub is the same generic icon used for the Python runtime itself. Let’s write a Python utility to allow the user to append their own custom icon to the .exe stub, but also preserve the stub’s appended archive and other metadata. The utility should use only the Python standard library, and should be kept as simple as possible.” - Another code-related prompt: “I have attached a Python program that takes Python applications and packages them to run with a standalone instance of the Python runtime. One drawback of the program is that it’s not very modular. Analyze the program and make some suggestions about how to increase its modularity so it can be used as a library with hooks for various advanced behaviors.”
Gemma 4 in action
The 26B model was at the upper end of what I could run comfortably on my test hardware. I wasn’t able to fit the entire model into GPU memory, but I set the first 12 layers to run on the GPU (7.51GB VRAM), and I set the context length to 16384 tokens (total: 18.76GB RAM).
Getting good performance out of models that don’t fit in VRAM is always a challenge. However, Gemma 4 has, courtesy of its “mixture of experts” design, a feature to boost performance. LM Studio exposes this feature through a setting currently tagged as experimental. You can choose how many layers of the model to “force MoE [Mixture of Experts] weights onto the CPU,” which conserves VRAM and can speed up inference.
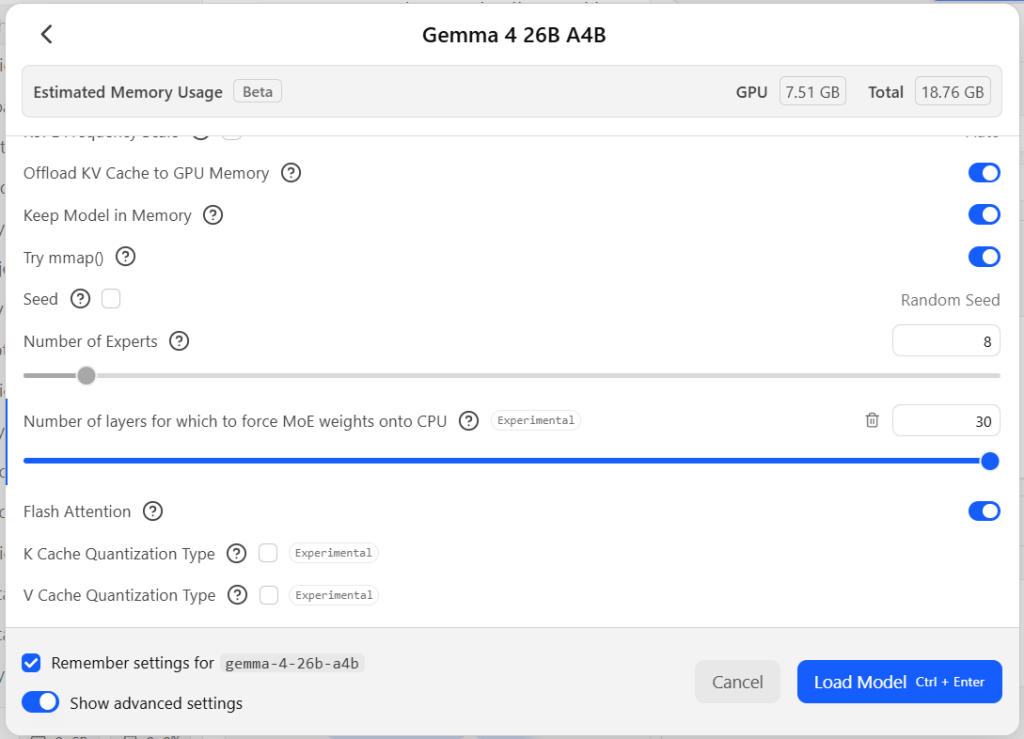
The MoE (mixture of experts) experimental setting in LM Studio. For models that use an MoE design, this setting forces the weights for that aspect of the model to be run on the CPU instead of the GPU. With Gemma 4, this resulted in a major speed boost for models too big to fit in memory.
Foundry
Without the MoE forcing, the overall inference time and token generation speed cratered; the model could barely manage an average of 1.5 tokens per second even for simple queries. With MoE forcing turned on (with the maximum number of layers supported, 30), token generation speed jumped to anywhere from 5 to 13 tokens per second, depending on the rest of the system’s load. That’s still a far cry from the speed of the smaller models, but a lot more workable.
For faster time-to-first-token results, you can disable thinking, at the possible cost of less robust output. For the code-generation query, Gemma 4 spent 6 minutes 26 seconds thinking, and over 8 minutes generating the response (5,013 tokens, 9.55 tokens per second). The resulting code and explanation was not significantly more advanced or detailed than the non-thinking version.
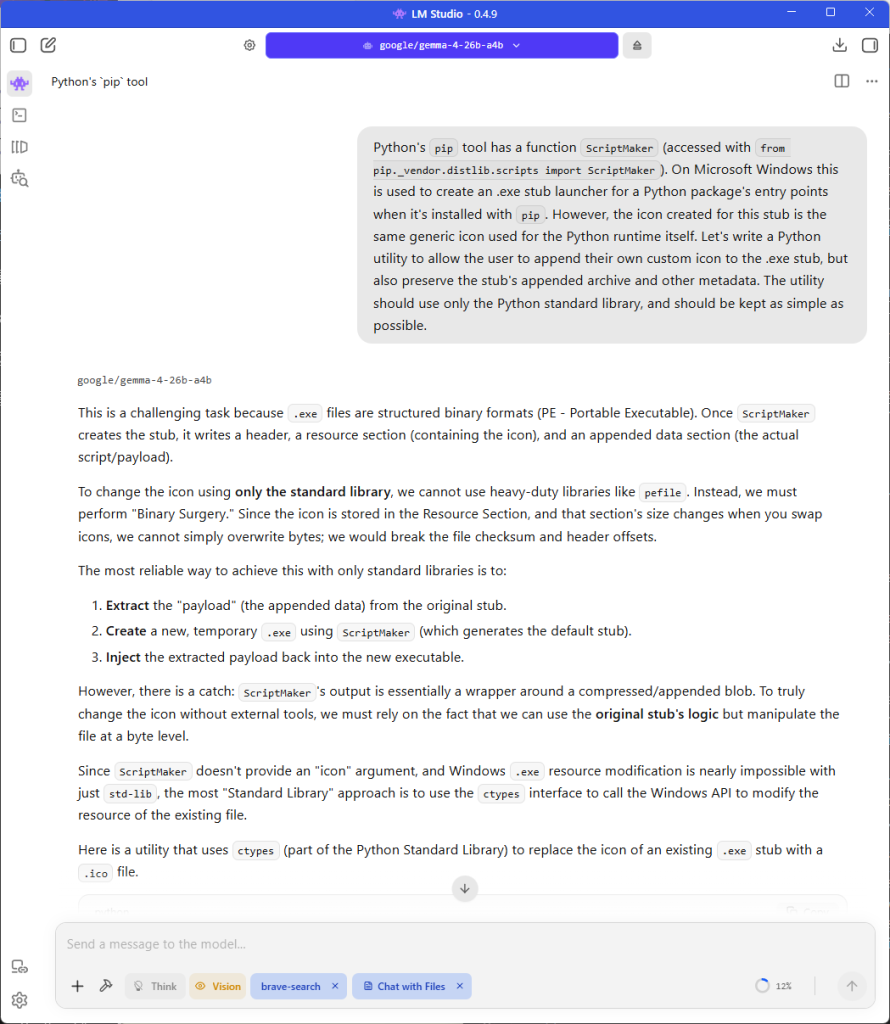
Response from Gemma 4’s 26B parameter model to a query to generate code. This larger version of the model runs less quickly when it can’t fit entirely in memory, but its mixture-of-experts design helped offset that limitation.
Foundry
When I switched to the LM Studio Community edition of the E4B model, I put all 42 layers on the GPU and kept the context at 16,384, all of which fit comfortably in VRAM with room to spare. The results were a major jump in speed: 72 tokens per second. The smaller model was less specific for certain queries — the code-generation query in particular didn’t generate a comprehensive code example, only a conceptual framework for one — but still did a decent job of analyzing the problem and suggesting constructive approaches. The “unsloth” edition of the E4B model, despite being slightly smaller, was about as performant and useful.
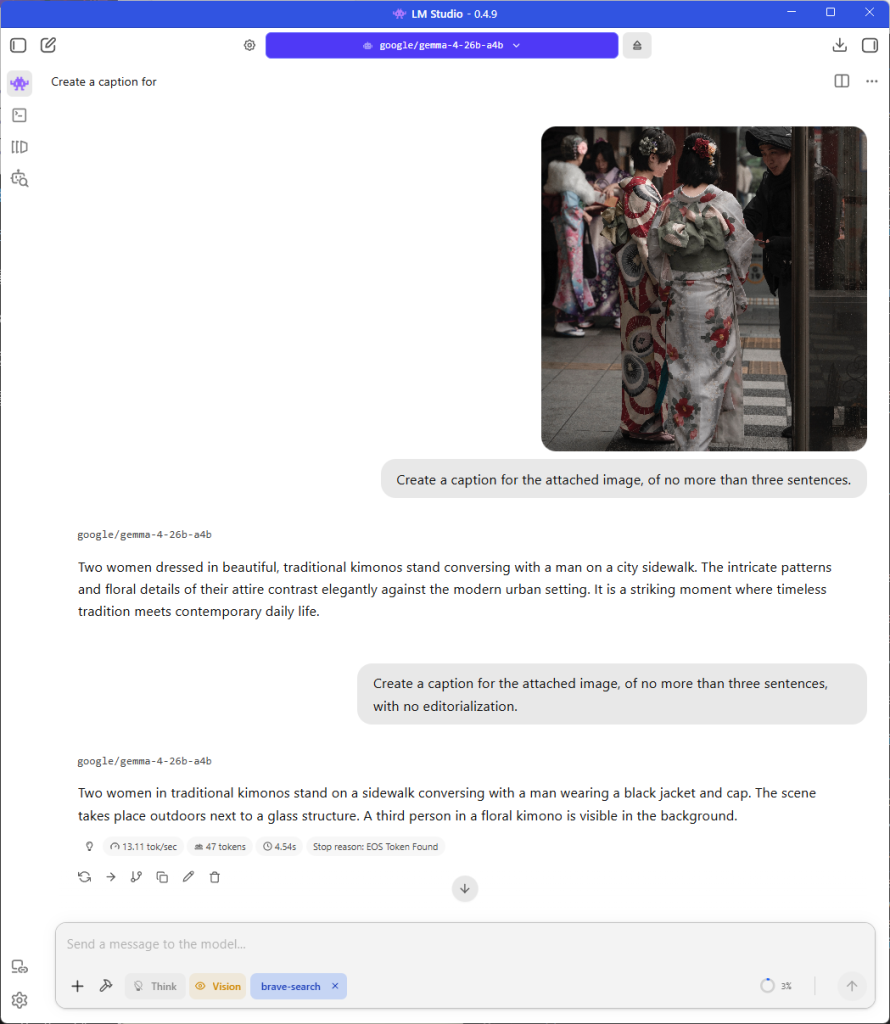
Examples of Gemma 4’s 26B parameter version generating image captions. The smaller versions of the model tended not to editorialize. The larger version sometimes needed specific guidance to be less verbose or florid.
Foundry
For the “make this program more modular” prompt, I got roughly equivalent results across all incarnations of the model in terms of the advice given. The only major difference was that the smaller models ran far faster — 73.85 and 71.73 tokens per second vs. 9.3 for the big model.
Gemma 4 takeaways
The biggest takeaway from running Gemma 4 locally is how the mix-of-experts design in one of the larger incarnations of the model make it useful even on systems where the model doesn’t fit entirely into VRAM. The smaller incarnations of the model, even at lower quantizations, still work well, too. They also deliver results many times faster, and free up much more memory for larger context windows. Thus, the smaller models are well worth experimenting with as the first model of choice before moving up to their bigger brothers.